GPT-6 Astra, Looped Transformers, and Hidden Reasoning
GPT-6 Astra、循环 Transformer 与隐藏推理
6,412 个英文词 · 24 个原文块 · 24 张保存图片
总结
文章从 Astra 的使用体验与评测出发,梳理循环 Transformer、动态计算深度和隐藏推理之间的关系。核心机制是反复使用同一组权重来增加计算深度;它能节省部分权重存储空间,但计算、缓存和训练仍有开销。MoR、隐空间推理和 SMELT 展示了不同的取舍,是否划算,要结合具体任务和计算预算判断。
结合补充核验,有两点需要注意:架构传闻不能证明 Astra 的真实实现,推理文字变短也不能单独解释可监控性变化。原文另有两处数字口径问题:Nanbeige 的总参数并非 3B;图 18 的 41k 与 8k 对应 Sol 约少用 80% 的 token。原文与译文保留作者说法,修正放在“判断”中。
- 循环 Transformer
- 权重共享
- 推理时计算
- KV 缓存
- 思维链可监控性
英文原文 01
293 词 · 1 张图A lot has happened in the last few weeks. I am sure that OpenAI’s GPT-6 Astra is top of mind for everyone right now. In particular, thoughts on its performance, the looped transformer/recurrent depth aspects, and rumors that Astra is “hiding” its reasoning trace (i.e., chain of thought).
So, in this article, I want to start with some brief impressions of Astra and some thoughts on where all this is headed. Then, I will discuss, in detail, what “looped transformers” are, and how (or rather, if) this relates to hiding chains of thought.
Lastly, after covering the basics of the looped transformer, I wanted to highlight some new insights from recent research papers on the topic.
1. GPT-6 Astra impressions
First things first. Before getting into the architecture rumors and related research literature, let me briefly summarize some GPT-6 Astra observations and tidbits.
Last week, OpenAI’s new GPT-6 Astra was released with a big fanfare. I used it over the past couple of days, and it’s an exceptionally good model, likely the best I’ve used as of this writing. But what, exactly, has it improved, and how?
1.1 Astra benchmarks
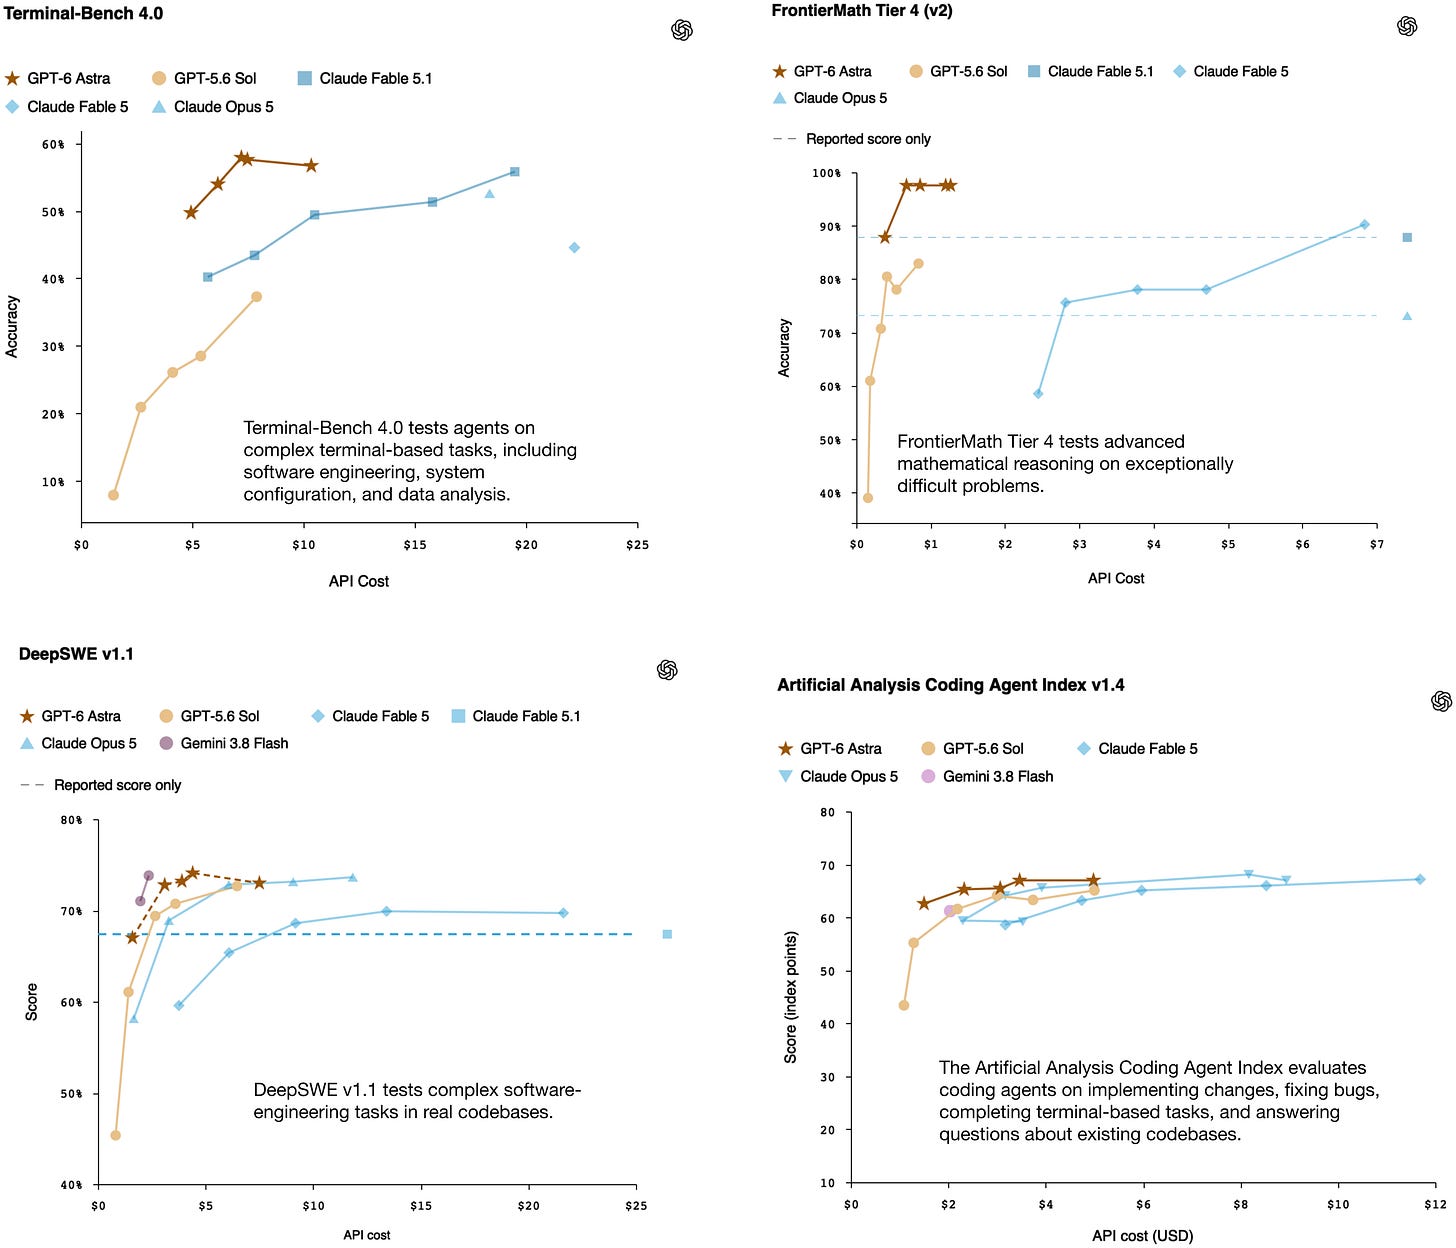
Astra is the best model I’ve used so far, and it’s disproportionately good at 3D rendering and animation tasks (relative to other models). With that, I mean that while it leapfrogs its GPT-5.6 predecessor in practically all categories (writing, math, coding, and more), it especially does so when it comes to graphical demos.
We can see this also reflected in the benchmarks. For instance, GPT-6 Astra is really good at math and coding, as shown below.
中文译文 01
459 字过去几周发生了很多事。我相信,OpenAI 的 GPT-6 Astra 现在一定是大家最关心的话题。尤其是它的表现、循环 Transformer/递归深度方面的设计,以及 Astra 正在“隐藏”其推理轨迹(也就是思维链)的传闻。
因此,在这篇文章中,我想先谈谈对 Astra 的简要印象,以及这些变化可能带来的影响。随后,我会详细讨论什么是“循环 Transformer”,以及它与隐藏思维链有何关系——更准确地说,两者究竟是否有关。
最后,在介绍循环 Transformer 的基础知识之后,我还想重点分享近期几篇相关研究论文带来的新认识。
1. 对 GPT-6 Astra 的印象
先从最基本的事情说起。在讨论架构传闻和相关研究之前,我先简要总结一些关于 GPT-6 Astra 的观察和信息。
上周,OpenAI 高调发布了新的 GPT-6 Astra。我在过去几天里使用了它,这个模型非常出色,可能是截至写作时我用过的最好的模型。不过,它具体提升了什么,又是如何提升的?
1.1 Astra 的基准评测
Astra 是我迄今用过的最好的模型,而且相对于其他模型,它在 3D 渲染和动画任务上的表现尤其突出。我的意思是,虽然它在几乎所有类别——写作、数学、编程等——都超越了上一代 GPT-5.6,但在图形演示方面的进步尤其明显。
基准评测也体现了这一点。例如,如下图所示,GPT-6 Astra 非常擅长数学和编程。
上下游
本块首次出现的来源与延伸
核查发布方报告的评测与计算机操作能力;发布方报告的成绩不等于独立复现的结果。
已核对官方发布页比较 expert-choice、token-choice、不同缓存方案与训练预算。
已读路由与实验区别思维链监控、动作监控和完整轨迹监控,核对可监控性下降是否仅与推理链长度有关。
已读可监控性章节理解测试集合、运行框架和指数口径;网页会更新,原图保留其历史版本。
已核对方法页本块新增 4 项
判断
对本块内容的判断
本块交代作者将讨论的范围,还没有给出证明架构或隐藏推理的证据。阅读时应分别跟踪使用体验、架构研究和可监控性,避免把它们合成同一个结论。 “用过最好的模型”是作者的个人使用评价;图中的具体测试结果是另一类证据。一个图形演示或若干任务得分,不能直接代表所有使用场景。
核验与延伸:GPT-6 Astra 官方发布说明 ↗ · Mixture-of-Recursions · NeurIPS 2025 ↗ · GPT-6 Astra 系统卡 · §9 Monitorability ↗ · Artificial Analysis 评测方法 ↗
解释
本块首次出现的知识点
块、堆栈与执行次数:分清“存了多少”和“算了几次”
一个 Transformer 块通常包含注意力、前馈网络、归一化与残差连接;多个块按顺序构成堆栈。一次块执行,就是让输入经过一个 Transformer 块,完成一次计算。22 个独立块循环两遍,只需存储 22 组主体权重,但块总共执行 44 次。
两处 θ 相同,表示权重共享;输入 h₀ 与 h₁ 不同,第二遍不会因为权重相同就必然得到相同结果。共享权重与新增独立层的表达能力也不能简单等同。
思维链、忠实性、可监控性:三个问题
思维链是模型生成的中间文本;忠实性关注这段文本是否反映实际影响答案的因素;可监控性关注监控器能否借这些信息发现目标行为。文本很长,不保证忠实;文本较短,也不能仅凭长度判定完全不可监控。
监控器看见的范围也很关键:只看思维链、只看动作,或看完整轨迹,可能得到不同结果。把用户界面是否展示推理、开发者能否监控、内部状态能否解释分别讨论,可以避免把不同“隐藏”混在一起。忠实性研究 ↗ · 系统卡 ↗
如何读本文的评测图
先读坐标轴及单位,再看任务、模型、版本与推理强度。Accuracy 是准确率,Validation Loss 是验证损失(一般越低越好);Pass@1 表示单次尝试的通过率。指数是特定任务集合的聚合,不代表每种现实任务。
“多 80%”以原数作分母;“少 80%”以被减少的数作分母。对图 18,41k÷8k≈5.125;反向减少比例则约为 80.5%。图 22 的长度图纵轴从约 420 开始,视觉柱高差会被放大;应读 token 数值,而非直接比较柱子面积。
参数、FLOPs、延迟和 token:四种不同的衡量指标
参数量决定要保存多少可学习数值;FLOPs 近似衡量做了多少浮点运算;延迟是人实际等待的时间;token 用量是输入输出长度。API 账单又受服务商定价影响。循环可能让生成每个 token 的计算开销更大,却让模型用更少 token 完成任务,最终总成本需要一起计算。
训练还包括反向传播及优化器更新。循环共享的同一参数会接收来自多个执行位置的梯度,不能只算一次反向传播。训练与推理阶段能节省多少开销,也应分别验证。
本块新增 4 项
英文原文 02
292 词 · 1 张图One of the highlights (not shown in the figure) is that Astra also achieves 99.9% on the ARC-AGI-3 benchmark (GPT-5.6 Sol only 7.8%), which measures a mix of solving logic puzzles and generalization. However, the math, coding, and computer use benchmarks are more interesting because they are closer to real-world use.
Coming back to the Artificial Analysis Coding Agent Index v1.4 (lower right in the previous figure), which blends several agentic coding tasks, GPT-6 Astra is clearly at the frontier, but it doesn’t pull ahead by leaps and bounds. This can also be seen in the general Artificial Analysis Intelligence Index shown below, which blends different types of tasks, not just coding tasks.
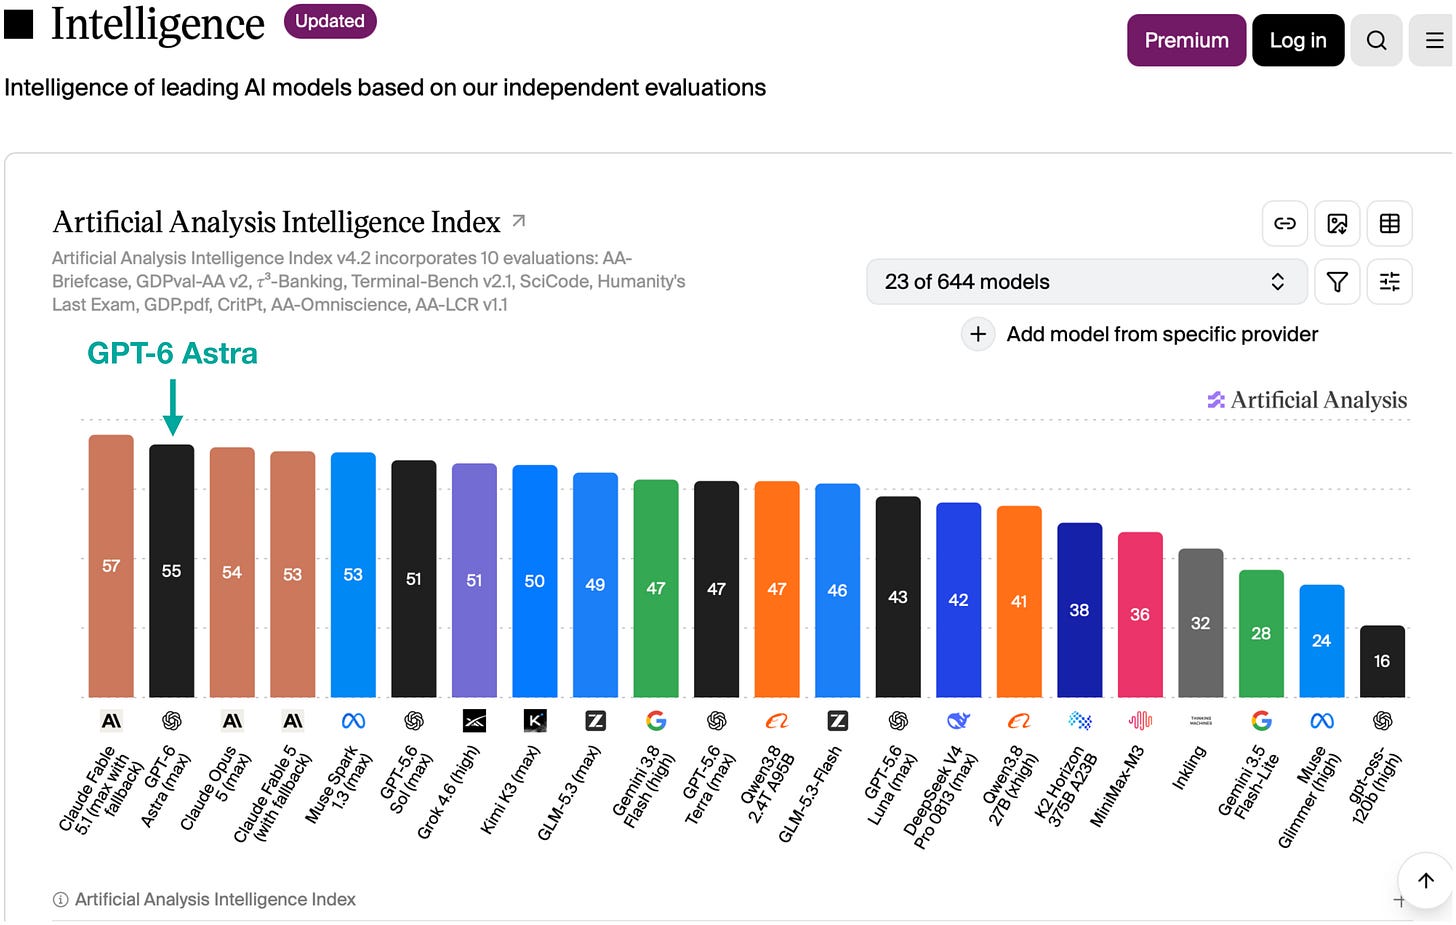
Now, the big advantage of Artificial Analysis benchmarks is that they are independent and thus may be a bit more trustworthy than self-evaluated benchmarks by model developers.
The harness setup depends on the benchmark. For example, GDPval-AA and AA-Briefcase use their open-source, minimal Stirrup harness across the different LLMs they compare. In the Intelligence Index v4.2 shown above, Terminal-Bench v2.1 uses Terminus 2, and τ³-Banking uses the τ-Bench harness. The separate Coding Agent Index also compares different coding-agent harnesses.
For evaluations that use a shared harness, this makes it more of an apples-to-apples comparison. At the same time, during model training, models are typically developed with one primary harness in mind (and fine-tuned less on other harnesses). Plus, the primary harness is often developed to suit and amplify a model’s strengths.
So, some of the agentic evaluations might underestimate how well Astra performs in its primary harness. How much this affects its Intelligence Index score would need to be tested by comparing Astra across harnesses on the same tasks.
中文译文 02
460 字另一个亮点是,Astra 在 ARC-AGI-3 基准上也达到了 99.9%(图中未展示;GPT-5.6 Sol 只有 7.8%)。这个基准综合考查逻辑谜题求解和泛化能力。不过,数学、编程和计算机操作基准更值得关注,因为它们更贴近现实中的实际用途。 [1]
再看上一张图右下角的 Artificial Analysis Coding Agent Index v1.4。该指数综合了多种编程智能体任务,GPT-6 Astra 显然处于领先水平,但没有大幅甩开其他模型。下方的通用 Artificial Analysis Intelligence Index 也反映了这一点;这个指数综合了不同类型的任务,而不只是编程任务。 [1] [2]
Artificial Analysis 基准的一大优势是独立性,因此,它们或许比模型开发者自己进行的评测更值得信赖一些。
评测运行框架(harness)的配置取决于具体基准。例如,GDPval-AA 和 AA-Briefcase 使用其开源、精简的 Stirrup 框架比较不同的大语言模型。在上图的 Intelligence Index v4.2 中,Terminal-Bench v2.1 使用 Terminus 2,τ³-Banking 使用 τ-Bench 框架。独立的 Coding Agent Index 还会比较不同的编程智能体框架。 [1] [2]
在使用同一框架的评测中,不同模型可以在更接近的条件下进行比较。不过,在模型训练期间,开发者通常会主要针对一种框架来开发模型,而对其他框架做的微调较少。此外,主要框架本身往往也是为了适应并放大模型优势而设计的。
因此,某些智能体评测可能低估了 Astra 在其主要框架中的表现。要知道这对 Intelligence Index 得分的影响有多大,需要让 Astra 在不同框架中执行相同任务,再进行比较。
上下游
本块首次出现的来源与延伸
保留原文提供的资源地址,供查看对应材料和上下文。
原文链接;未将未核验内容当作新证据保留原文提供的资源地址,供查看对应材料和上下文。
原文链接;未将未核验内容当作新证据保留原文提供的资源地址,供查看对应材料和上下文。
原文链接;未将未核验内容当作新证据展示不同运行框架如何影响同一个模型的实际表现。
已读项目说明本块新增 4 项 · 另有 2 项已在前文介绍
判断
对本块内容的判断
99.9% 是特定基准下的结果,不能读成所有任务的准确率。独立评测减少了发布方自评这一层利益关联,但仍要检查任务、版本、预算与实施方法。 作者把“框架可能低估模型”写成待检验的可能性,这个限定是恰当的。要分离模型与框架的贡献,应让多个模型在多个框架上执行同一任务集。
图中 token、价格、准确率与指数版本不能互相替代
图 1 的横轴是 API 价格,图 17 是输出 token;两者都不能直接当作底层 FLOPs。图 2 标为指数 v4.2,图 18 标为 v4.3,且 Luna 与 Sol 使用不同推理强度。相近任务表现的比较有参考价值,但要严谨计算效率收益,仍需同一任务集和明确的匹配条件;没有重叠准确率区间的曲线不能直接据此判断准确率相同时能节省多少 token。评测方法 ↗ · 定位原文 ↑
核验与延伸:ARC-AGI-3 benchmark ↗ · Artificial Analysis Coding Agent Index v1.4 ↗ · Artificial Analysis Intelligence Index ↗ · Artificial Analysis 评测方法 ↗
解释
本块首次出现的知识点
运行框架与模型的区别
模型负责根据输入决定输出;运行框架(harness)负责调用工具、执行动作、组织上下文和检查结果。同一个模型放入不同框架,可能因为工具接口、记忆方式、提示或验证流程不同,而表现不同。
比较模型时,要说明框架是否保持一致;比较完整产品时,则可以测量模型与框架的整体效果。这两种比较回答的问题不同。
本块新增 1 项 · 另有 1 项已在前文介绍
英文原文 03
280 词As a side note, as a colleague recently suggested to me (as also recommended by the Claude Code lead), it’s maybe not a bad idea to delete (/archive) some of your existing AGENTS.md contents and SKILL.md files, as newer LLMs have become more efficient at understanding the prompt and solving the problem at hand. The extra hand-holding could unnecessarily constrain newer models and lead to worse solutions.
Of course, I am not suggesting never using SKILL.md files again, but for some workflows, because they can improve efficiency upon reuse, since the model doesn’t have to rediscover them. But what I am suggesting is that some workflows don’t need describing, and “old” descriptions may no longer be ideal, and the LLM may be able to come up with better solutions. So, it’s perhaps time to update or regenerate said instruction files.
1.2 Computer use capabilities
GPT-6 Astra seems to be exceptionally strong in image and rendering tasks. When these tasks involve interacting with graphical user interfaces, they also demonstrate computer-use capabilities, meaning the model operates software on your local computer through the Codex/ChatGPT app.
Computer use is where the model really shines compared to others, and anything graphic-related also makes for interesting and intuitive demos on social media platforms. There are tons of examples of impressive demos out there, from modeling rendering New York City in blender to virtual open house tours.
To pick one example, below is a comparison where I had GPT-6 Astra Medium and High redraw a picture of me in a browser version of MS Paint using the mouse on my computer (not Extra High and Max, because I didn’t want to waste all my tokens :)).
中文译文 03
464 字顺便一提,一位同事最近向我提出了一个建议,Claude Code 的负责人也推荐过类似做法:删除或归档一部分现有的 AGENTS.md 内容和 SKILL.md 文件,或许不是坏事。因为较新的大语言模型已经更善于理解提示并解决手头的问题,额外的手把手引导可能会不必要地限制新模型,反而得到更差的方案。
当然,我并不是建议从此不再使用 SKILL.md 文件。在某些工作流中,这些文件能在重复使用时提高效率,因为模型不必再次摸索同样的流程。我想说的是,有些工作流无须提前写成指令,已有的描述也可能不再适用,模型也许能够自己找出更好的解决办法。所以,或许是时候更新或重新生成这些指令文件了。
1.2 计算机操作能力
GPT-6 Astra 在图像和渲染任务上似乎格外强。当这些任务涉及与图形用户界面交互时,它们也展示了计算机操作能力:模型通过 Codex/ChatGPT 应用,操作你本地计算机上的软件。
与其他模型相比,计算机操作正是这个模型特别出色的地方。图形相关的内容也很适合在社交平台上做有趣而直观的演示。从在 Blender 中建模和渲染纽约市,到虚拟看房导览,已经有大量令人印象深刻的例子。 [1] [2]
举一个例子:下面的比较中,我让 GPT-6 Astra 的 Medium 和 High 推理强度版本,使用我电脑上的鼠标,在浏览器版 MS Paint 中重画一张我的照片。我没有使用 Extra High 和 Max,因为不想把所有 token 都消耗掉 :))。 [1]
上下游
本块首次出现的来源与延伸
保留原文提供的资源地址,供查看对应材料和上下文。
原文链接;未将未核验内容当作新证据保留原文提供的资源地址,供查看对应材料和上下文。
原文链接;未将未核验内容当作新证据保留原文提供的资源地址,供查看对应材料和上下文。
原文链接;未将未核验内容当作新证据本块新增 3 项 · 另有 2 项已在前文介绍
判断
对本块内容的判断
这是作者对指令文件维护的经验判断,本块没有提供删除前后的受控比较。是否精简应通过实际任务验证;文章中的建议本身不是对当前项目发出的操作指令。 演示有助于理解工具使用,但不提供失败率、重复次数或代表性任务覆盖。所供文件未包含这段视频,因此不能凭占位比较 Medium 与 High 的实际差异。
核验与延伸:rendering New York City in blender ↗ · virtual open house tours ↗ · browser version of MS Paint ↗ · Stirrup · 评测与智能体运行框架 ↗
解释
本块首次出现的知识点
指令文件是什么
这类文件把项目约定和重复工作流程提供给智能体。它们可能减少重复摸索,也可能包含过时或过度具体的要求。评价效果时,应比较实际任务的成功率、耗时与错误,而不是只比较指令长短。
本块新增 1 项 · 另有 1 项已在前文介绍
英文原文 04
272 词[Embedded video / 嵌入视频]
This highlights not only the model’s artistic capabilities but, more importantly, its ability to use tools on one’s computer (in this case, Paint; you can see the model using the interface via the mouse cursor).
This is not the first model that, inside a harness, is capable of general computer use. For example, I successfully used GPT models for some UI tasks (e.g., expense-related tasks in Excel) and so on since earlier this year. However, computer use is a relatively new capability, enabled by the harness, and usually feels not quite as mature yet. This makes sense. LLMs are text models, so naturally the lower-hanging fruit is writing and coding and using APIs and CLIs.
At the same time, there are many tools and software that don’t expose CLIs (yet), and instead of waiting until someone designs that interface, why not improve models to use graphical user interfaces (and, as mentioned before, this makes for pretty and impressive demos, anyway)? This is somewhat analogous to the emerging humanoid robot developments. Sure, humanoid robots are not the most efficient robots, for example, at the assembly line, where special-purpose machines exist. But they are versatile.
So, I expect the upcoming months (or years) also to be an era of computer use refinement on both the LLM and the agent harness layer. I.e., in addition to the current capabilities, and expanding their math and coding capabilities, models will be trained with an increasing amount of computer use in mind. And this will also make LLMs more accessible for everyday computer tasks outside the tech world (”Hey ChatGPT, please do my tax return” :))
中文译文 04
459 字[嵌入视频]
这不仅展示了模型的绘画能力,更重要的是展示了它使用计算机工具的能力——这里使用的是 Paint,你可以看到模型通过鼠标光标操作界面。
这并不是第一个能够借助运行框架完成各类电脑操作的模型。例如,从今年早些时候开始,我就已经成功让 GPT 模型完成过一些界面任务,比如 Excel 中与费用相关的任务。不过,借助框架操作电脑仍是一项较新的能力,实际体验通常还不够成熟。这也很合理:大语言模型本来就是文本模型,因此更容易先取得进展的方向自然是写作、编程,以及使用 API 和命令行接口。
与此同时,很多工具和软件还没有提供命令行接口。与其等待别人为它们设计接口,为什么不提升模型使用图形界面的能力呢?而且,正如前面所说,这也很容易做出漂亮、令人印象深刻的演示。这与当前兴起的人形机器人发展有些相似:在有专用机器的流水线上,人形机器人当然不是效率最高的机器人,但它们具有通用性。
因此,我预计,未来几个月乃至几年里,大语言模型和智能体运行框架都会持续改进计算机操作能力。也就是说,在增强现有能力,以及继续发展数学和编程能力的同时,模型训练会越来越重视计算机操作。这也会让科技圈以外的人更容易把大语言模型用于日常电脑任务,比如:“嘿 ChatGPT,帮我报税吧” :))。
上下游
本块首次出现的来源与延伸
本块相关内容已在前文介绍
判断
对本块内容的判断
演示有助于理解工具使用,但不提供失败率、重复次数或代表性任务覆盖。所供文件未包含这段视频,因此不能凭占位比较 Medium 与 High 的实际差异。 没有命令行接口,确实能说明图形界面操作的价值;它并不意味着图形操作在有 API 的场景里也更快或更稳定。通用性与单项效率需要分别评价。 对未来计算机操作发展的判断属于预测;Mac 采购数量来自报道,训练环境的解释则是机制说明。三者的证据层级不同,不应将流程上的合理解释当成采购事实的独立证明。
解释
本块首次出现的知识点
计算机操作训练:模型、运行框架、环境与奖励
模型决定下一步动作,运行框架执行动作、截屏、管理上下文,环境则是被操作的软件或系统。验证器检查目标是否达到,并产生训练反馈。图 3 是这种循环的概念示意,并不是任何公司的硬件采购清单。
RLVR 指奖励可以通过可检查的结果给出,例如测试是否通过。它不意味着所有任务都只用二元奖励,也不保证验证器没有漏洞。真实训练如何组织,仍需具体训练报告支持。框架示例 ↗
本块新增 1 项 · 另有 2 项已在前文介绍
英文原文 05
282 词 · 1 张图1.3 Computer use training
The computer usage trend is also consistent with the recent reporting that OpenAI purchased tens of thousands of Mac Minis and Mac Studios for Reinforcement Learning. So, here the Macs are not used to literally train the models (it’s better to use GPUs for that) but rather to expose macOS during the model training for the model to learn to use said operating system and the tools therein.
So, how does computer-use training on said Macs work? In short, the Macs (or their macOS operating system, to be precise) serve as an environment that the model can interact with during training.
The basic workflow looks like this:
Prompt the model by giving it a task, such as “open an app xyz and do abc”.
Provide it with screenshots of the macOS interface (this is usually done by the harness).
The LLM then predicts mouse/keyboard actions (click, key presses, scrolling, and so on).
Execute those actions on the Mac (again, this is done by the harness).
Feed new screenshots of the updated environment after performing the actions in the previous step.
Repeat steps 2-5 until the task succeeds or fails.
Use success/failure signals and verifiers (or graders) as training feedback, including reinforcement learning during post-training; this is analogous to regular Reinforcement Learning with Verifiable Rewards (RLVR).
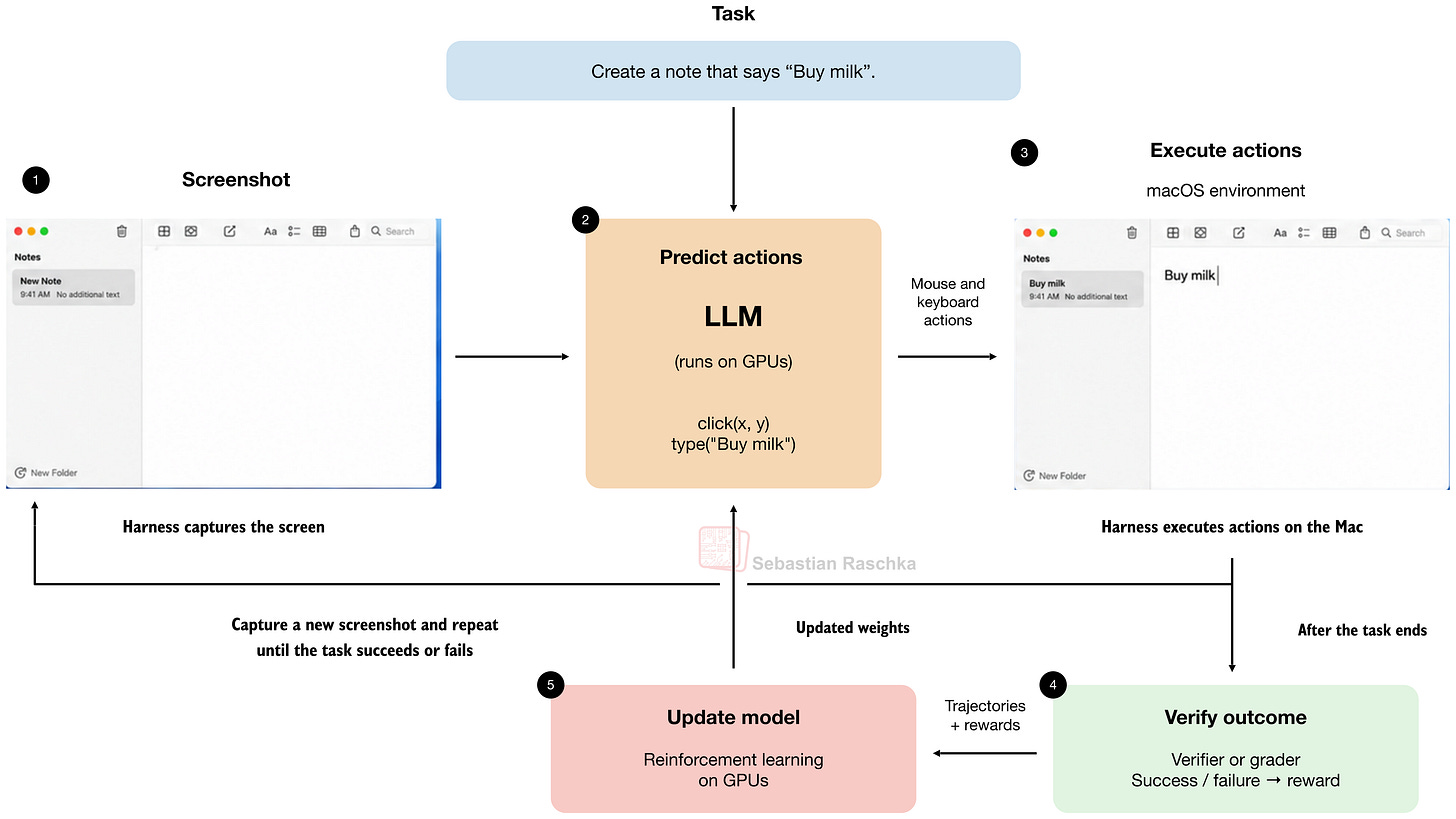
Again, the Mac is mostly the environment here and not the machine for running or updating the model during training. The model likely sits on NVIDIA GPUs and is fed via API to said Mac. By the way, NVIDIA’s CEO mentioned that GPT-6 Astra was being trained on ~100,000 Grace Blackwell GPUs.
中文译文 05
459 字1.3 计算机操作训练
计算机操作这一趋势,也与最近的报道相符:OpenAI 为强化学习购买了数万台 Mac Mini 和 Mac Studio。这里的 Mac 并不是直接用来训练模型的计算设备——做这件事,GPU 更合适。它们的作用是,在训练过程中提供 macOS 环境,让模型学习使用这个操作系统及其中的工具。 [1]
那么,利用这些 Mac 进行计算机操作训练是怎么回事?简单说,Mac——更准确地说,是它们运行的 macOS——就是模型在训练中练习操作的环境。
基本流程如下:
给模型一个任务提示,例如“打开某个 xyz 应用并完成 abc 操作”。
向模型提供 macOS 界面的截图,这通常由运行框架完成。
随后,大语言模型预测应当执行的鼠标或键盘动作,例如点击、按键、滚动等。
在 Mac 上执行这些动作,同样由运行框架完成。
执行上一步动作后,把更新后的环境截图重新输入模型。
重复步骤 2—5,直到任务成功或失败。
把任务成功或失败的信号,以及验证器或评分器给出的结果,用作训练反馈,包括后训练阶段强化学习所需的反馈。这与通常所说的可验证奖励强化学习(RLVR)类似。
再次强调,Mac 在这里主要充当环境,而不是训练期间运行模型或更新模型参数的设备。模型很可能运行在 NVIDIA GPU 上,并通过 API 与 Mac 交互。顺便一提,NVIDIA 的首席执行官曾提到,GPT-6 Astra 使用大约 100,000 张 Grace Blackwell GPU 进行训练。 [1]
上下游
本块首次出现的来源与延伸
保留原文提供的资源地址,供查看对应材料和上下文。
原文链接;未将未核验内容当作新证据保留原文提供的资源地址,供查看对应材料和上下文。
原文链接;未将未核验内容当作新证据本块新增 2 项 · 另有 2 项已在前文介绍
判断
对本块内容的判断
对未来计算机操作发展的判断属于预测;Mac 采购数量来自报道,训练环境的解释则是机制说明。三者的证据层级不同,不应将流程上的合理解释当成采购事实的独立证明。 流程图清楚区分了被操作的 Mac 与负责模型计算的设备,但它不验证具体 GPU 数量。成功或失败是奖励信号的例子,实际训练还可能使用更细的过程评分与约束。
核验与延伸:recent reporting ↗ · NVIDIA’s CEO mentioned ↗ · GPT-6 Astra 官方发布说明 ↗ · Stirrup · 评测与智能体运行框架 ↗
解释
本块首次出现的知识点
本块相关内容已在前文介绍
英文原文 06
244 词 · 1 张图1.4 GPT-6 Astra is still a reasoning model
The focus on computer-use training discussed in the previous section is not a fundamental paradigm shift in the training pipeline. GPT-6 Astra (and likely any LLM in the foreseeable future) is still a reasoning model. This means the LLM is trained with reinforcement learning with verifiable rewards (RLVR) and produces intermediate reasoning traces (chains of thought)
But I will discuss the reasoning model aspects of GPT-6 Astra (especially regarding hiding chains of thought) a bit later in this article.
2. Looped transformers
That being said, about two days before the official model, the news magazine The Information published an articlereporting that, according to some inside information, Astra is using a concept called “recurrent depth” or “looped transformers.”
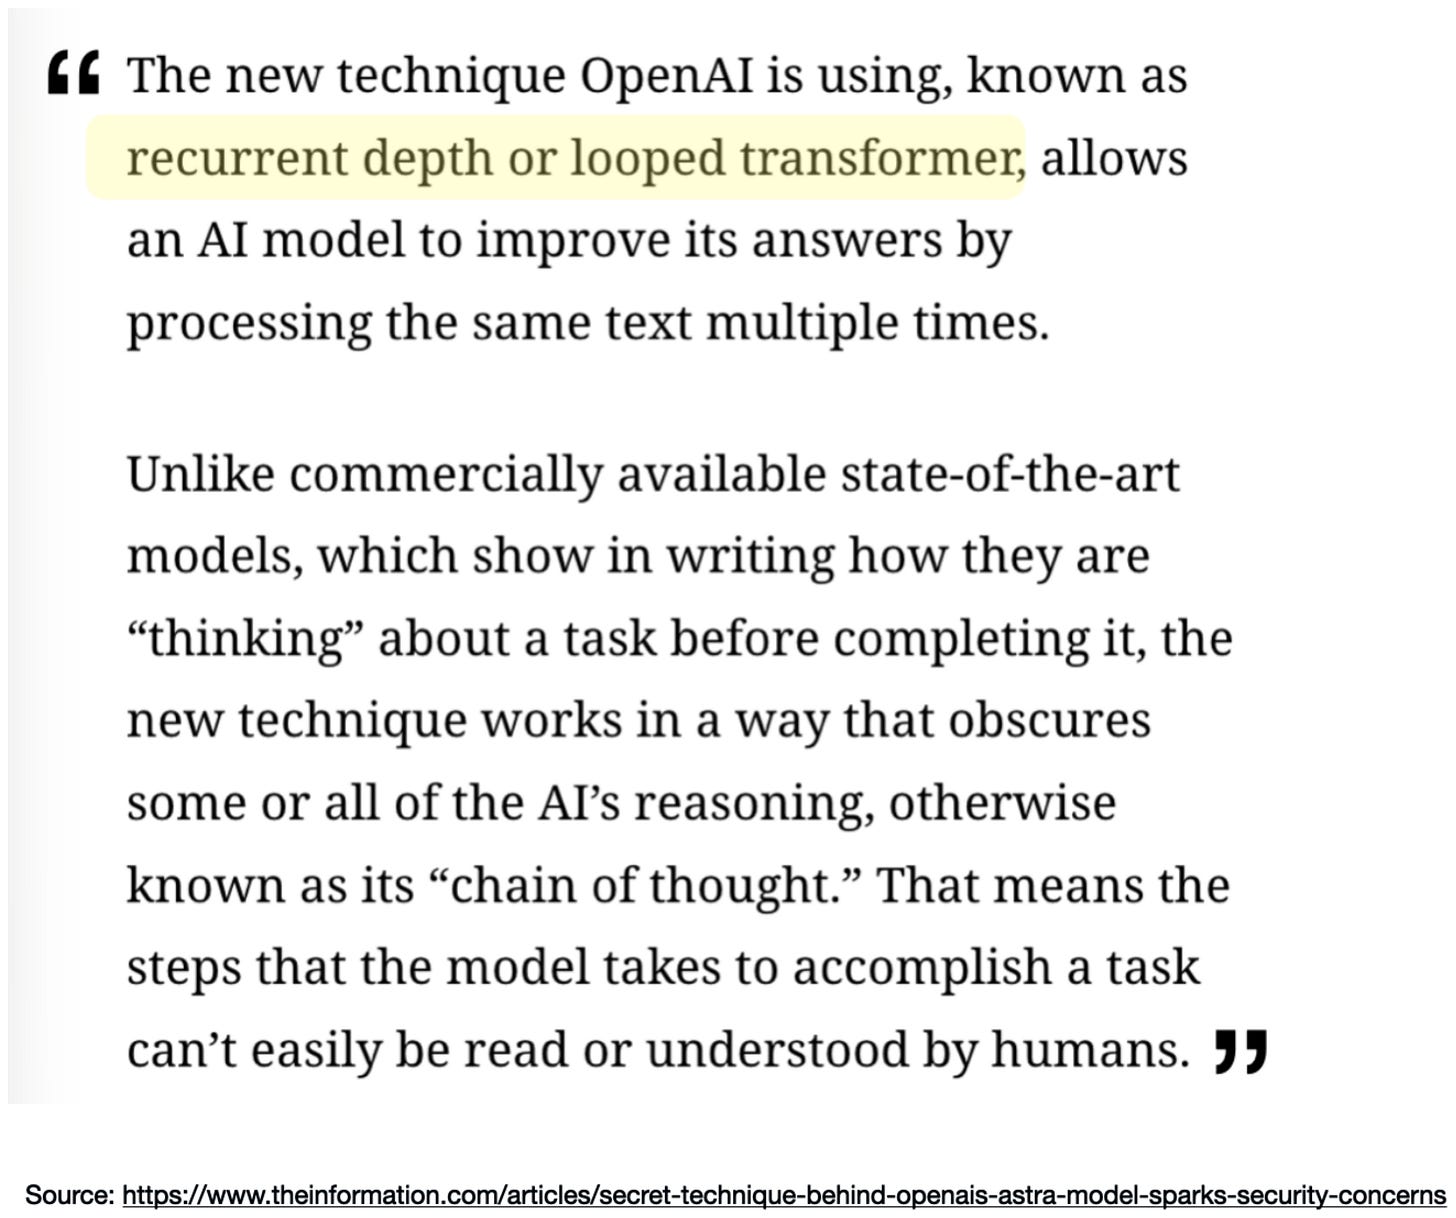
Since LLM architectures are within my area of expertise and my passion, I created a short lecture video explaining the general looped transformer mechanism and addressing the comment about hidden reasoning chains, which you can find below.
[Embedded video / 嵌入视频]
In the following subsections, I’ll first explain what looped transformers are, and I’ll revisit the comment about the hidden chains of thought later in this article.
(The looped transformer explanation may seem a bit long, but I really think that it helps with establishing a foundational understanding of the technique, which is then useful to judging the claim that it obscures the reasoning traces or chains of thought.)
中文译文 06
391 字1.4 GPT-6 Astra 仍然是推理模型
上一节所说的计算机操作训练重点,并不意味着训练流程出现了根本性的范式转变。GPT-6 Astra 仍然是推理模型;在可预见的未来,其他大语言模型很可能也都如此。这意味着,模型通过可验证奖励强化学习(RLVR)训练,并生成中间推理轨迹,也就是思维链。
不过,关于 GPT-6 Astra 作为推理模型的这些方面,尤其是思维链是否被隐藏,我会在本文后面进一步讨论。
2. 循环 Transformer
话虽如此,在模型正式发布前大约两天,新闻杂志 The Information 发表了一篇文章。报道援引内部消息称,Astra 使用了一种称为“递归深度”或“循环 Transformer”的概念。 [1]
大语言模型架构既是我的专业领域,也是我热爱的方向,因此我制作了一段简短的讲解视频,介绍一般的循环 Transformer 机制,并回应有关隐藏推理链的说法。视频就在下方。
[嵌入视频]
接下来的几个小节,我会先解释什么是循环 Transformer,再在文章后面回到隐藏思维链的话题。
循环 Transformer 的说明也许显得有些长,但我确实认为,先建立对这项技术的基础理解很有帮助,这样才更容易判断它是否会让推理轨迹或思维链变得不透明。
上下游
本块首次出现的来源与延伸
付费正文未独立读到,不能据此裁定记者是否误解。
仅核对可见页面与所供摘录深度方向的参数复用和逐位置动态停止,比近期模型发布更早。
已核对论文解释固定两遍、从零训练与独立 KV 缓存;结果属于该实验设置。
已核对架构与缓存取舍本块新增 3 项 · 另有 2 项已在前文介绍
判断
对本块内容的判断
Astra 的训练与行为应依据官方材料核查;“可预见未来的所有模型”是更广的作者预测。报道截图说明争论的来源,并不足以独立确认循环结构;本地视频占位也不作为证据。 区分块、堆栈和块的执行次数能避免把执行次数误当参数数量。这里的定义可以支持后续结构说明,但“架构调整很小”本身不能决定性能贡献的大小。
核验与延伸:The Information · 原始报道入口 ↗ · GPT-6 Astra 官方发布说明 ↗ · GPT-6 Astra 系统卡 · §9 Monitorability ↗ · Universal Transformers · 2018 / ICLR 2019 ↗
解释
本块首次出现的知识点
读懂原图中的嵌入、RoPE、RMSNorm、前馈模块和 GQA
嵌入把 token 编号映射为向量;输出层把最终向量映射为词表分数。前馈模块对每个位置做非线性变换;残差连接让输入与变换结果相加;RMSNorm 通过均方根归一化控制数值尺度。RoPE 用旋转方式编码相对位置信息。GQA 让多个查询头共享较少的键和值头,以减少 KV 存储。
图 5 的 48 个查询头与 8 个 KV 头表示每组 6 个查询头共享一组键和值;隐藏维度、头维度和词表大小是不同的量,不能混为模型参数总数。对应配置 ↗
本块新增 1 项 · 另有 2 项已在前文介绍
英文原文 07
265 词 · 1 张图2.1 Reusing transformer blocks
So, what’s a looped transformer?
A Looped Transformer is essentially an architectural tweak, with the main idea being to pass the intermediate representations through the same transformer blocks multiple times (instead of just once). Compared to just adding more blocks, the “trick” here is that the weights stay the same across these passes.
Definitions & Jargon
Throughout this article, I’ll use the following terms:
A transformer block is a unit containing attention, a feedforward module, normalization, and shortcut connections. These blocks are often called “transformer layers” in papers.
A stack is a sequence of transformer blocks.
A block application means running an input through a transformer block once.
The looped transformer is nothing new, and the basic idea already appeared in the Universal Transformers paper from 2018. But before discussing Universal Transformer, let’s start with a simpler example, Nanbeige4.2-3B, a recent open-weight LLM that came out in July and that I covered on Substack Notes and in my LLM Architecture Gallery earlier this summer.
The Nanbeige architecture, shown below, essentially looks like a regular transformer. However, notice that it has an extra (orange) arrow looping back to the beginning of the transformer stack.
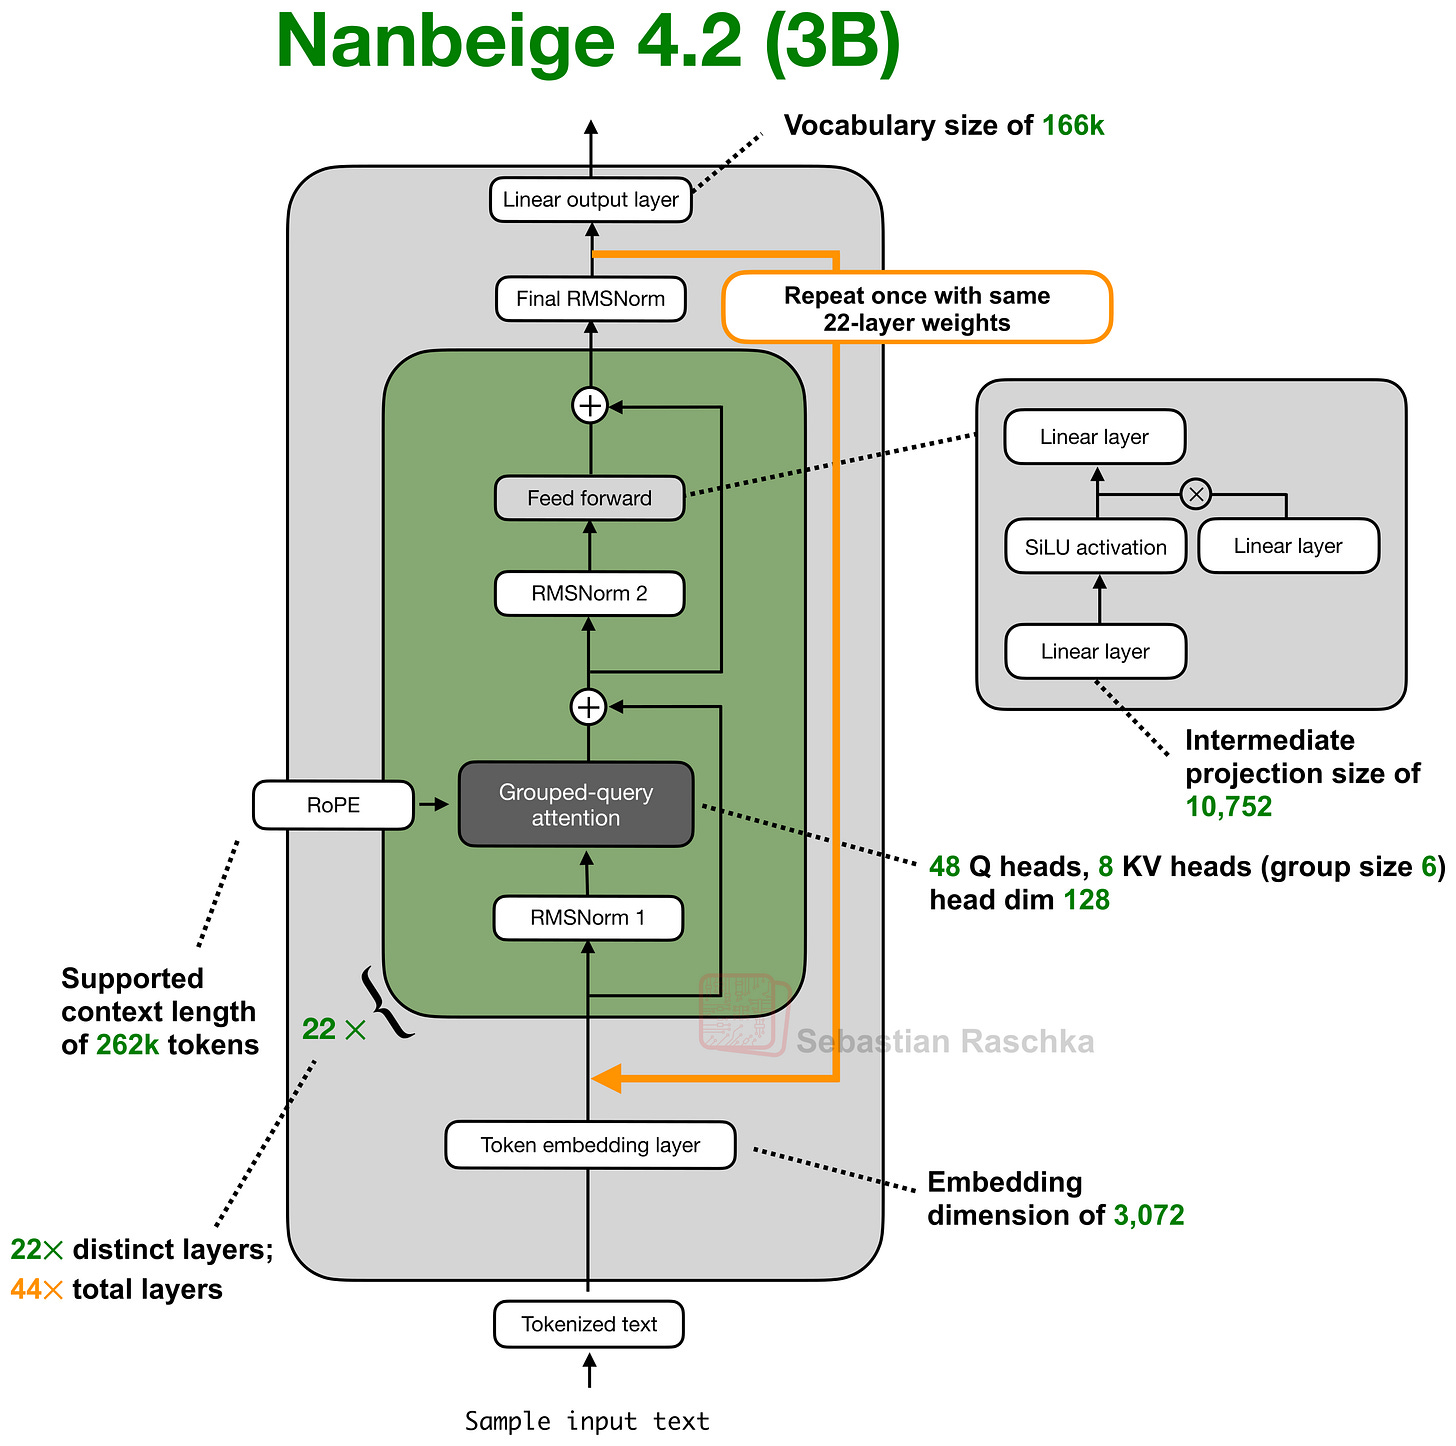
Let’s walk through this from the bottom up. First, as in any other transformer-based LLM, the input text is tokenized and converted into embedding vectors. These vectors then pass through 22 transformer blocks, and each of these 22 blocks has its own weights.
中文译文 07
433 字2.1 复用 Transformer 块
那么,什么是循环 Transformer?
循环 Transformer 本质上是一种架构调整。它的主要想法,是让中间表示多次通过同一组 Transformer 块,而不是只通过一次。与直接增加更多块相比,它的“诀窍”在于:每一轮计算都使用同一组权重。
定义与术语
在本文中,我会使用以下术语:
Transformer 块(transformer block)是包含注意力、前馈模块、归一化和跳跃连接(残差连接)的一个单元。在论文中,这些块也经常被称为“Transformer 层”。
堆栈(stack)是按顺序排列的一组 Transformer 块。
一次块执行(block application),指让输入经过某个 Transformer 块,完成一次计算。
循环 Transformer 并不是什么全新的东西,它的基本思想在 2018 年的 Universal Transformers 论文中就已经出现。不过,在讨论 Universal Transformer 之前,我们先看一个更简单的例子:Nanbeige4.2-3B。这是今年 7 月发布的一款开放权重的大语言模型,我在今年夏天早些时候的 Substack Notes 和 LLM Architecture Gallery 中都介绍过它。 [1] [2] [3] [4]
下图中的 Nanbeige 架构,看起来基本上就是一个常规的 Transformer。不过,请注意那根额外的橙色箭头:它会绕回 Transformer 堆栈的起点。
我们从下往上走一遍流程。首先,与其他基于 Transformer 的大语言模型一样,输入文本被分词,并转换为嵌入向量。随后,这些向量通过 22 个 Transformer 块,每个块都有自己的一组权重。
上下游
本块首次出现的来源与延伸
保留原文提供的资源地址,供查看对应材料和上下文。
原文链接;未将未核验内容当作新证据22 层、2 遍、隐藏维度 3072、词表 166144;用于复核嵌入参数量。
已核对公开配置3B 是非嵌入参数的标称规模,模型卡总参数约 4B。
已核对参数口径本块新增 3 项 · 另有 2 项已在前文介绍
判断
对本块内容的判断
区分块、堆栈和块的执行次数能避免把执行次数误当参数数量。这里的定义可以支持后续结构说明,但“架构调整很小”本身不能决定性能贡献的大小。 22 个独立块与两轮循环可以对照官方配置。此处得到的是计算路径更深,而不是新增一套权重,也不是自动证明能力与 44 个独立块完全相同。
核验与延伸:Universal Transformers · 2018 / ICLR 2019 ↗ · Nanbeige4.2-3B 技术报告 · §2.1 ↗ · LLM Architecture Gallery ↗ · Nanbeige4.2-3B · 官方配置 ↗
解释
本块首次出现的知识点
本块相关内容已在前文介绍
英文原文 08
247 词 · 1 张图However, the looping transformer aspect here is that after the first pass, the hidden states are fed back through the same 22 blocks. So, block 1 is applied again, followed by block 2, and so on up to block 22.
If we were to unroll this computation, we would have 44 transformer block applications. However, compared to a conventional transformer with 44 distinct blocks, the second stack of 22 block applications reuses the weights from the first stack. For example, block application 23 uses the weights of block 1, block application 24 uses the weights of block 2, and so on.
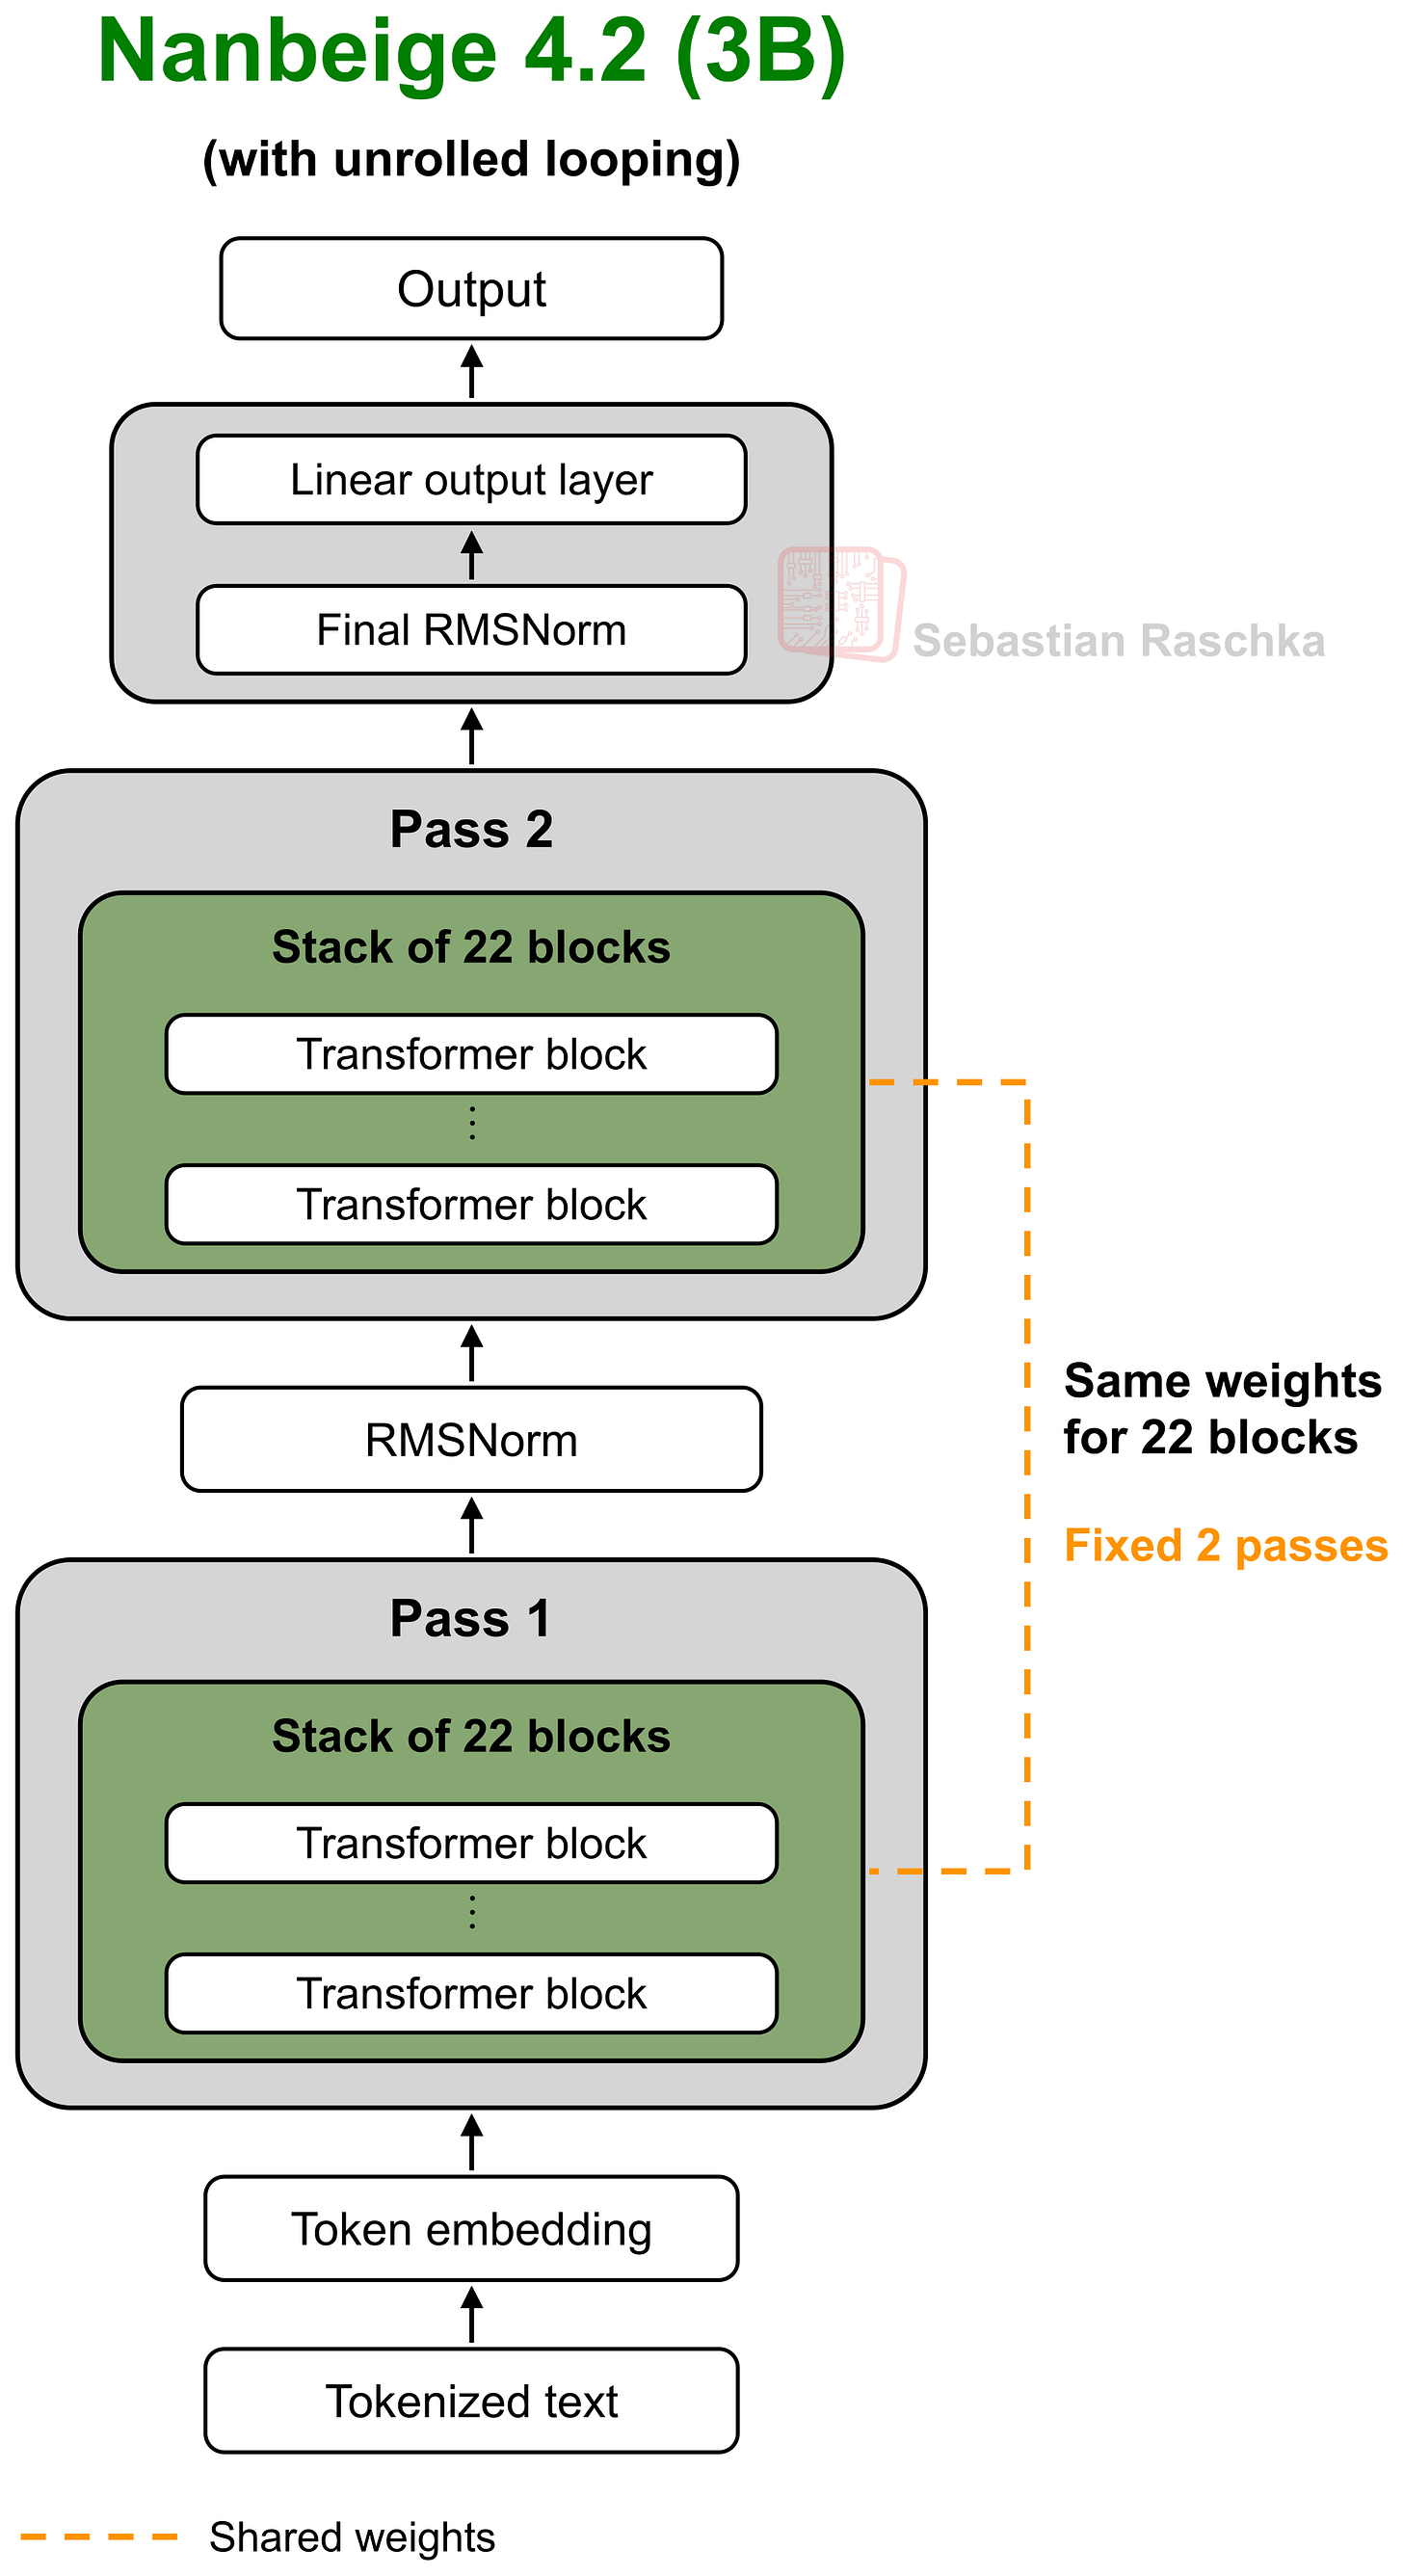
So, the whole idea here is that we increase the effective depth from 22 to 44 block applications without adding another set of transformer weights.
By the way, why 2 rounds, not 3, 4, or more? There are not many details in the Nanbeige paper, but they say that this was essentially the most efficient setup. Increasing the loops from 2 to 3 can increase modeling performance, but the extra computational cost wasn’t worth it.
2.2 Looping costs
So, why would we do this looping in general? This is essentially an alternative to just making the model bigger by adding more transformer blocks.
So, for instance, a model that uses 22 transformer blocks twice has roughly half as many (transformer-block) parameters compared to a model with 44 conventional blocks.
中文译文 08
392 字循环 Transformer 的特别之处在于:完成第一遍计算后,隐藏状态会被重新送入同一组 22 个块。因此,块 1 会再运行一次,然后是块 2,依次进行,直到块 22。
如果把整个计算过程展开,Transformer 块总共会执行 44 次。不过,与包含 44 个独立块的常规 Transformer 相比,后 22 次执行复用了前 22 次所用的权重。例如,第 23 次执行使用块 1 的权重,第 24 次使用块 2 的权重,以此类推。
因此,整个想法就是:在不额外增加一套 Transformer 权重的情况下,把块的执行次数从 22 次增加到 44 次,从而增加有效计算深度。
顺便问一句,为什么是两轮,而不是三轮、四轮或者更多轮?Nanbeige 论文并没有给出很多细节,但作者表示,这基本上是效率最高的配置。把循环次数从 2 增加到 3,能够提高模型表现,但性能收益不足以抵消额外的计算开销。
2.2 循环的成本
那么,为什么总体上要采用这种循环设计?它提供了另一种增加计算深度的方式,不必只靠增加 Transformer 块来扩大模型。
例如,将 22 个 Transformer 块使用两次的模型,与包含 44 个常规块的模型相比,Transformer 块部分的参数量大约只有一半。
上下游
本块首次出现的来源与延伸
本块相关内容已在前文介绍
判断
对本块内容的判断
22 个独立块与两轮循环可以对照官方配置。此处得到的是计算路径更深,而不是新增一套权重,也不是自动证明能力与 44 个独立块完全相同。 展开后共执行 44 次 Transformer 块,这样统计计算量是正确的。两遍优于更多遍,是 Nanbeige 在其训练条件下作出的取舍,不能当作所有循环模型的最优轮数。 本块需要特别区分非嵌入参数、总参数以及反向传播经过的执行次数。原文数字保持不变,具体口径修正在下方列出。
核验与延伸:Nanbeige4.2-3B 技术报告 · §2.1 ↗ · Nanbeige4.2-3B · 官方配置 ↗ · Nanbeige4.2-3B · 模型卡与权重 ↗ · Universal Transformers · 2018 / ICLR 2019 ↗
解释
本块首次出现的知识点
本块相关内容已在前文介绍
英文原文 09
268 词 · 2 张图This then reduces the memory needed to store the weights. As a side note, note that the embedding and output layers, which are usually large and make up a substantial portion of the total, are separate from this comparison. (In the case of Nanbeige 4.2 3B, the embedding and output layers make up ~25% of the total 3B parameters; with weight sharing between those two, we could reduce that to 12.5%.)
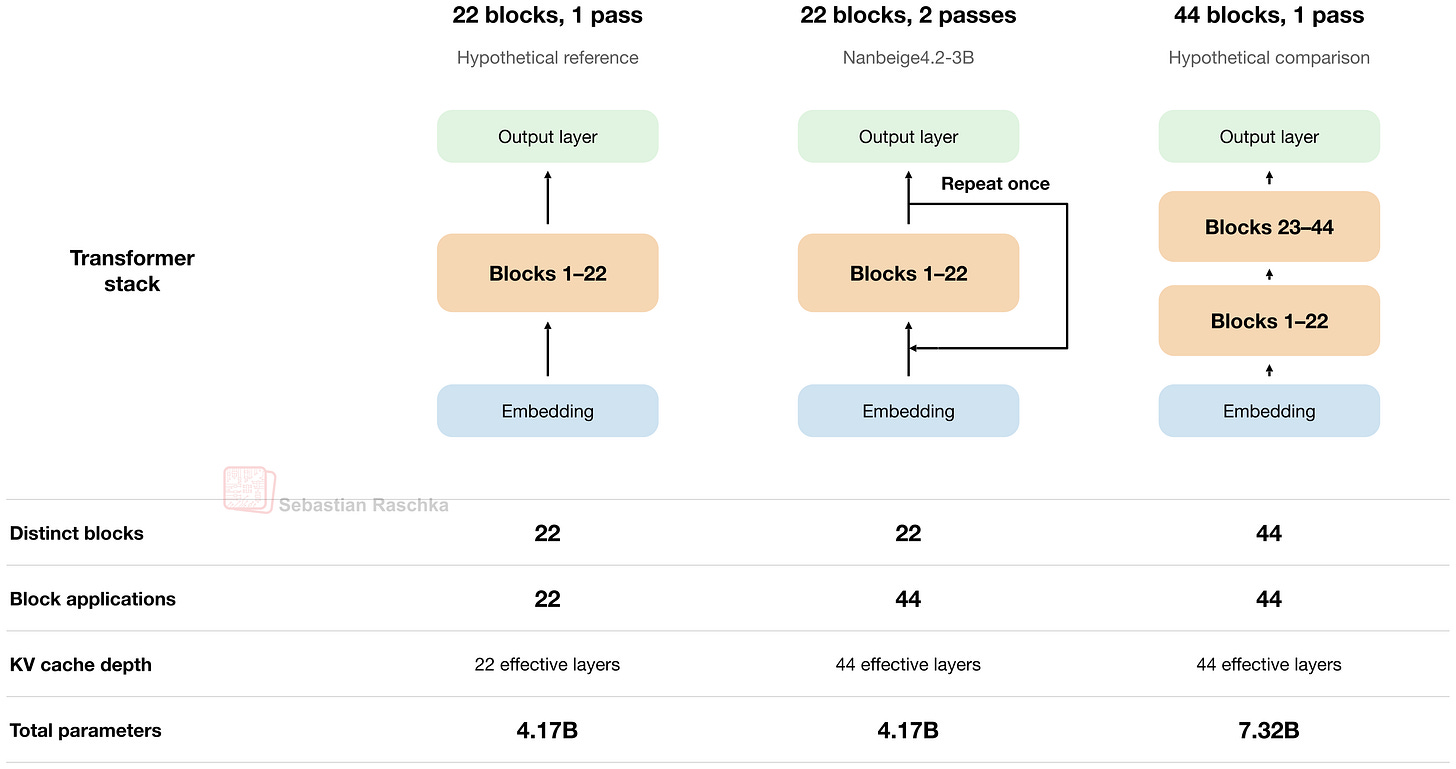
Of course, reusing the same blocks in a loop still requires computation. More precisely, we pass the intermediate inputs through 44 block applications during the forward pass. And, during training, gradients flow backward through both repetitions of the shared stack. So, compared to using the 22 blocks only once, this adds substantial work. Actually, it’s similarly expensive as having 44 distinct blocks (except the optimizer has fewer distinct parameters to update; backprop still runs through all 44 block applications).
There is also the KV cache, which stores the attention keys and values of previous tokens for reuse in conventional and looped transformers in each next-token generation step. By the way, I have a standalone article on KV caching here if useful:
Understanding and Coding the KV Cache in LLMs from Scratch
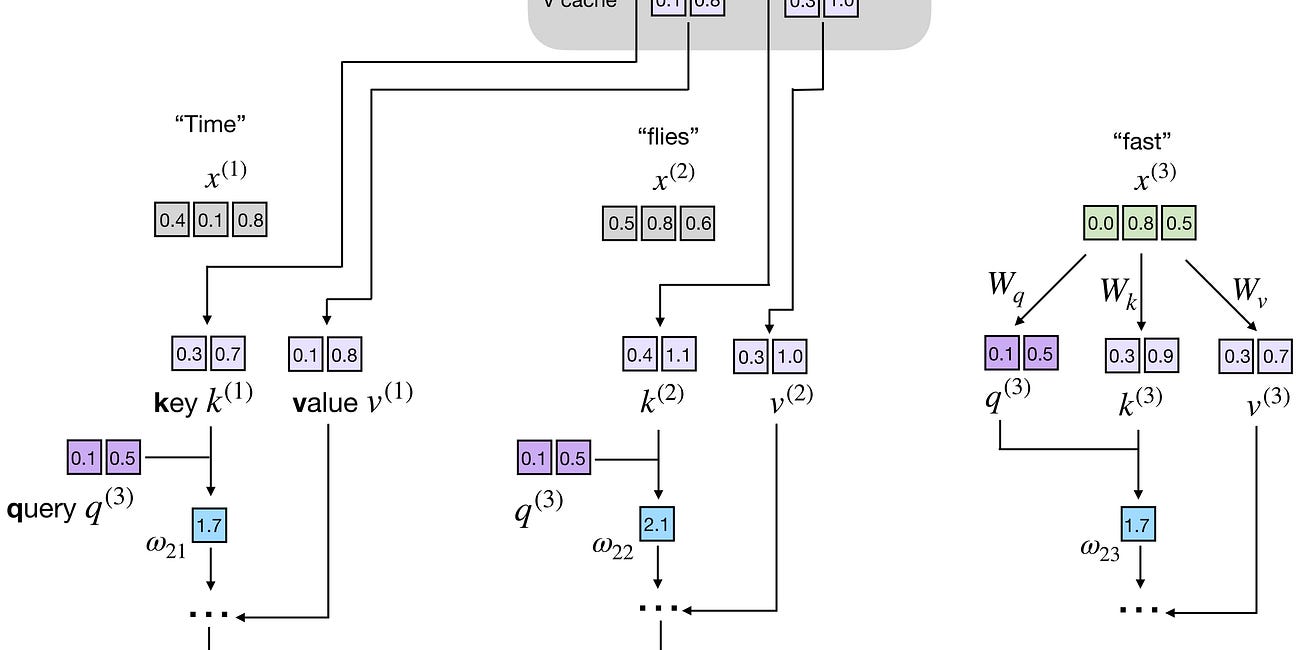
KV caches are one of the most critical techniques for efficient inference in LLMs in production. KV caches are an important component for compute-efficient LLM inference in production. This article explains how they work conceptually and in code with a from-scratch, human-readable implementation.
中文译文 09
433 字这样就能减少存储权重所需的内存。顺便提醒一下,嵌入层和输出层通常都很大,在总参数中占有相当大的比例,但不包含在这里的比较中。以 Nanbeige 4.2 3B 为例,嵌入层和输出层约占总计 3B 参数的 25%;如果让这两层共享权重,可以把这一比例降到 12.5%。
当然,在循环中复用同一组块仍然需要计算。具体来说,在前向传播中,Transformer 块总共要执行 44 次;训练时,梯度也要沿着共享堆栈的两遍计算过程反向传播。因此,与让 22 个块只运行一遍相比,循环会大幅增加计算量。实际上,它的计算开销与使用 44 个独立块相近,只是优化器需要更新的独立参数更少;反向传播仍然要经过全部 44 次执行。
此外还有 KV 缓存:它保存之前 token 的注意力键和值,让常规 Transformer 和循环 Transformer 都能在后续每一步生成下一个 token 时复用它们。如果你需要,我还有一篇专门介绍 KV 缓存的文章:
从零理解并编写大语言模型的 KV 缓存
KV 缓存是生产环境中提高大语言模型推理效率最关键的技术之一,也是降低推理计算开销的重要组成部分。本文从概念和代码两方面解释其工作原理,并提供从零编写、便于阅读理解的实现。
上下游
本块首次出现的来源与延伸
供复习键、值、查询和缓存使用;未把链接内未核验的实现细节作为本页结论。
本地原文提供教程卡片本块新增 1 项 · 另有 3 项已在前文介绍
判断
对本块内容的判断
本块需要特别区分非嵌入参数、总参数以及反向传播经过的执行次数。原文数字保持不变,具体口径修正在下方列出。 共享权重后,同一块在第二遍看到的隐藏状态仍可能不同,因此 K、V 不会自动相同。教程卡片是延伸阅读,不能把“存一份权重”推导为“只需一份缓存”。
3B 非嵌入参数与约 4.17B 总参数被混用了
原文第 2.2 节说嵌入和输出层约占“总计 3B”的 25%,但图 7 列出的总参数是 4.17B,模型卡的 3B 也指非嵌入参数。按官方词表与隐藏维度计算,每张嵌入矩阵为 166144 × 3072 ≈ 0.5104B,两张合计约 1.0208B,占 4.17B 的约 24.5%。共享这两张矩阵约节省原总参数的 12.2%;不同分母下的比例不能混用。配置 ↗ · 模型卡 ↗ · 定位原文 ↑
权重复用与 KV 缓存共享确实是两件事
重复计算时输入隐藏状态会变化,因而同一块可产生不同的键和值。Nanbeige 报告明确比较了跨轮共享 KV 的方案,并在权衡模型表现后选择了独立缓存。原文对这点解释清楚;工程上还应把权重、缓存、激活、优化器状态与实际延迟分别计量。报告 §2.1 ↗ · 定位原文 ↑
核验与延伸:Nanbeige4.2-3B · 官方配置 ↗ · Nanbeige4.2-3B · 模型卡与权重 ↗ · Nanbeige4.2-3B 技术报告 · §2.1 ↗ · 作者的 KV 缓存实现教程 ↗
解释
本块首次出现的知识点
KV 缓存:生成下一个 token 时复用历史注意力信息
查询 Q 表示当前关注什么,键 K 用来与查询匹配,值 V 携带待聚合的信息。生成新 token 时,过去位置的 K、V 可以缓存下来,避免反复重新计算整段历史。新位置的查询会与历史键匹配,再汇总对应的值。
前面的 2 代表 K 和 V,实际字节数还要乘数据类型的字节数。重复两遍但不共享 KV 时,缓存层数按两遍执行分别计算;权重只存一套,不意味着缓存也能只存一套。缓存取舍 ↗ · 进一步阅读 ↗
本块新增 1 项 · 另有 2 项已在前文介绍
英文原文 10
272 词But back to the topic. Even though there is weight-sharing in looped transformers, the intermediate states that enter a block are different on the second pass. Consequently, in KV caching, the resulting keys and values are also different between these two transformer stacks (just like in the no-looping case). So, there are no KV cache-related savings either.
To make this more concrete, for example, consider block applications 1 and 23, which both use block 1 in the looped transformer setup. But each application still needs its own KV cache entries. So, since we have to keep separate caches for both passes, the repeated stack of 22 blocks has the same KV cache requirements as a conventional transformer with 44 distinct blocks.
Interestingly, the Nanbeige researchers reported in the paper that they tried sharing the KV cache between passes. This, of course, halved the KV cache size, but the model performed worse than the version with separate caches (which is the version they released).
Just to complete the Nanbeige discussion before moving on and looking at some other looped transformer designs, their technical report also discusses two other choices or trade-offs.
Training the looped architecture from scratch worked better than converting an already pre-trained transformer through upcycling.
And two passes gave their preferred trade-off, as mentioned in the previous section. More passes brought only small additional gains while slowing training and making optimization less stable.
So, the number of passes is another architectural choice we have to make. As mentioned before, in Nanbeige, this is fixed at two. But we can also make it depend on the token, as we will see next.
中文译文 10
439 字回到我们的主题。循环 Transformer 虽然共享权重,但到了第二遍计算,输入某个块的中间状态已经发生了变化。因此,这两轮 Transformer 堆栈计算产生的键和值也不同,就像不采用循环时一样。所以,这里并没有节省与 KV 缓存相关的空间。
举一个更具体的例子:在循环 Transformer 中,第 1 次和第 23 次块执行都使用块 1,但每次执行仍然需要各自的 KV 缓存条目。由于必须为两遍计算分别保留缓存,这个重复使用的 22 块堆栈,其 KV 缓存需求与包含 44 个不同块的常规 Transformer 相同。
有意思的是,Nanbeige 的研究人员在论文中表示,他们尝试过让不同轮次共享 KV 缓存。这样当然能把 KV 缓存大小减半,但模型表现不如采用独立缓存的版本;后者才是他们最终发布的版本。
在介绍其他循环 Transformer 设计之前,先把 Nanbeige 的另外两项设计取舍说完。它的技术报告还提到了以下两点。 [1]
从零训练循环架构,比通过 upcycling 将已经预训练好的 Transformer 改造成循环架构,效果更好。
如上一节所述,两遍计算是他们更倾向采用的折中方案。更多遍计算只带来少量额外收益,却会降低训练速度,并使优化更不稳定。
因此,循环次数也是设计模型架构时需要确定的参数。前面说过,Nanbeige 将其固定为两遍。但也可以让次数取决于具体 token,接下来我们就会看到这种做法。
上下游
本块首次出现的来源与延伸
本块相关内容已在前文介绍
判断
对本块内容的判断
共享权重后,同一块在第二遍看到的隐藏状态仍可能不同,因此 K、V 不会自动相同。教程卡片是延伸阅读,不能把“存一份权重”推导为“只需一份缓存”。 这一块同时涉及缓存方案、训练起点和循环轮数,都是具体实验取舍。原文把它们与模型最终发布方案联系起来,解释基本成立,但相关性能代价仍需结合对应实验条件理解。 让不同 token 使用不同计算量,是在模型表现和计算成本之间进行权衡的方法。模型并不是事先知道哪个 token 最难;它依赖训练得到的信号来决定计算路径。
核验与延伸:Nanbeige4.2-3B 技术报告 · §2.1 ↗ · 作者的 KV 缓存实现教程 ↗ · Nanbeige4.2-3B · 模型卡与权重 ↗ · Universal Transformers · 2018 / ICLR 2019 ↗
解释
本块首次出现的知识点
自适应停止与路由:每个 token 应当算多久
固定循环为每个位置使用相同轮数。自适应停止则根据隐藏表示,逐步累计停止概率,并设置最大轮数作为上限。MoR 的 expert-choice 在每轮筛选继续计算的 token;token-choice 在开始时为 token 选定深度。这里的“专家”可以对应计算路径,不必是一组不同权重。
token 的表示包含上下文,因此同一个词在不同句子里可以被分配不同的计算量。实现中还要处理负载均衡、缓存和批处理;算法设计中少算一轮,不等于硬件必然按比例加速。UT ↗ · MoR ↗
本块新增 1 项 · 另有 2 项已在前文介绍
英文原文 11
306 词 · 1 张图2.3 Universal Transformers and flexible loop counts
Now, let’s come back to Universal Transformers. In Nanbeige, we apply a stack of 22 transformer blocks twice. In the Universal Transformer paper from 2018, we repeatedly apply the same transformer block instead of repeating a stack of transformer blocks. The main idea is similar, though.
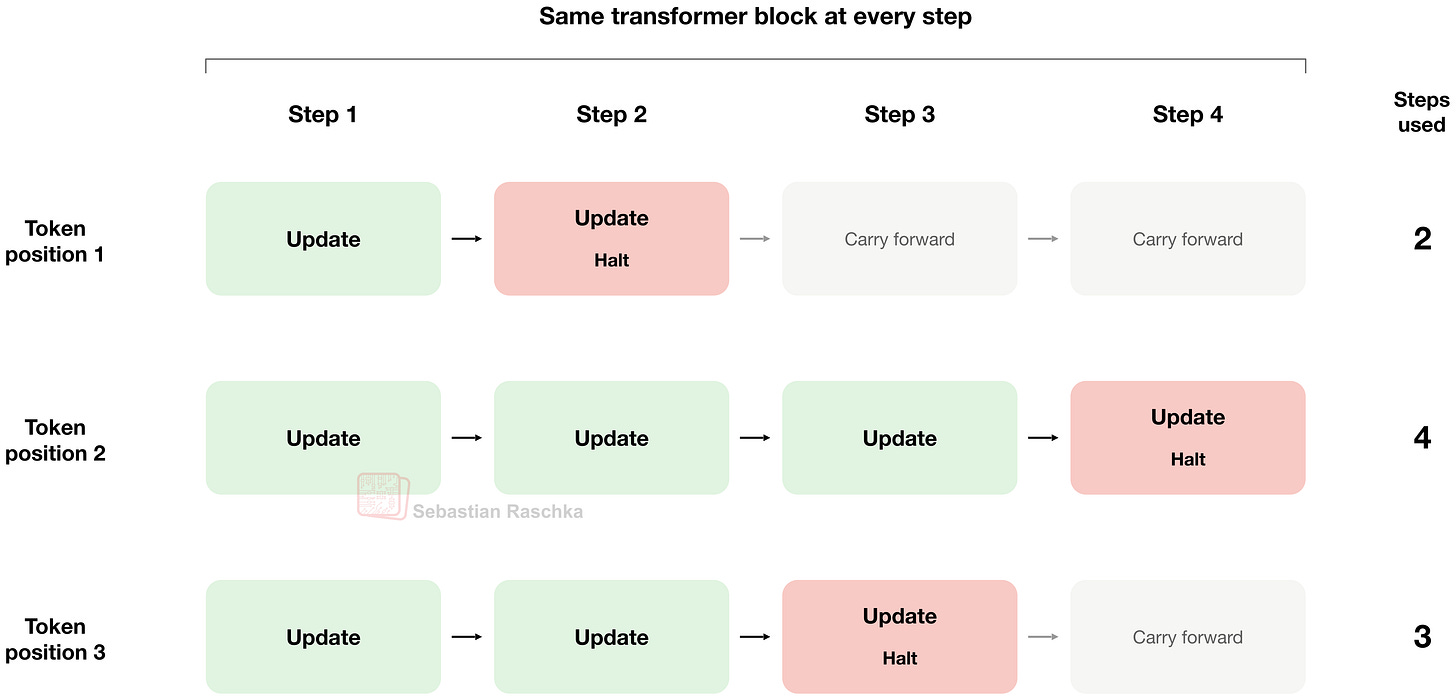
Also, the number of steps can be fixed, but the paper also explores adaptive halting. For example, a token at a particular position may only go through one or two loops. Another may go through three or four loops, and so on. This gives the model flexibility to allocate the compute to those tokens that benefit from extra computation.
How is the looping number decided? Here, the model uses a small, trained function that outputs a so-called halting probability for each position at each step. It adds up these probabilities over these successive loops and then stops looping at a given position once the sum exceeds a threshold value. In addition, a maximum loop count also limits the computation just in case.
Another example of a looped transformer is ByteDance’s Ouro, which I also covered in my LLM Architecture Gallery. For instance, Ouro-Thinking 2.6B applies the same stack of 48 transformer blocks four times. That’s 192 block applications while storing weights for 48 distinct blocks. Basically, that’s a more extreme case than Nanbeige. Additionally, a learned exit gate assigns probabilities to the different exits, and a threshold on the cumulative probability determines which pass supplies the output. So, it’s also borrowing the adaptive halting idea from Universal Transformer, which Nanbeige didn’t use. (However, there is a practical caveat here. The released Hugging Face implementation computes all configured passes before selecting an output, so it seems like the number of loops is effectively hard-coded to 4).
中文译文 11
482 字2.3 Universal Transformers 与灵活的循环次数
现在回到 Universal Transformers。Nanbeige 会把由 22 个 Transformer 块组成的堆栈运行两遍;2018 年的 Universal Transformer 论文则反复运行同一个 Transformer 块,而不是反复运行整个块堆栈。不过,两者的基本思想相似。 [1]
计算步数可以固定,但论文也研究了自适应停止。例如,某个位置的 token 可能只经过一两次循环,另一个则可能经过三四次。这样,模型就能灵活地把算力分配给那些能从额外计算中获益的 token。
循环次数是如何决定的?模型使用一个经过训练的小型函数,在每一步为每个位置输出所谓的停止概率。模型在连续的循环中累加这些概率;一旦某个位置的累计值超过阈值,就停止该位置的循环。此外,还会设置最大循环次数,作为对计算量的额外限制。
循环 Transformer 的另一个例子是字节跳动的 Ouro,我在 LLM Architecture Gallery 中也介绍过它。例如,Ouro-Thinking 2.6B 将同一个由 48 个 Transformer 块组成的堆栈运行四遍:只存储 48 个独立块的权重,但块的总执行次数达到 192 次。它基本上是比 Nanbeige 更极端的例子。此外,一个通过训练得到的退出门控机制会为不同的退出位置分配概率,再根据累计概率阈值决定采用哪一遍计算的输出。因此,它也借鉴了 Universal Transformer 的自适应停止思想,而 Nanbeige 并未采用这一点。不过,实际实现有一点需要注意:已发布的 Hugging Face 实现会先算完所有配置好的轮次,再选择输出,所以实际循环次数似乎被固定为 4 次。 [1] [2] [3]
上下游
本块首次出现的来源与延伸
用于比较多次循环与通过训练决定何时退出的设计,不将论文中的退出选择等同于实现已节省算力。
文中给出的研究入口需要分开检查是否选择早期输出,以及是否真的提前停止后续计算。
已定位代码,未运行模型本块新增 2 项 · 另有 3 项已在前文介绍
判断
对本块内容的判断
让不同 token 使用不同计算量,是在模型表现和计算成本之间进行权衡的方法。模型并不是事先知道哪个 token 最难;它依赖训练得到的信号来决定计算路径。 需要区分“选择哪一轮的输出”和“停止执行后续轮次”。如果实现先算完全部轮次,早期输出被选中也不意味着实际省去了同等计算。
选中早期输出,并不等于实际少算了后续轮次
原文指出 Ouro 已发布实现会先完成配置的全部轮次,再选择输出。这正是重要的区分:统计上的“退出位置”与实际执行次数可能不同。类似地,KL 分布变化变小只表明输出分布稳定,不保证答案已经正确;实际节省的时间还取决于批处理和执行器是否跳过计算。实现入口 ↗ · 停止机制 ↗ · 定位原文 ↑
核验与延伸:Universal Transformers · 2018 / ICLR 2019 ↗ · Ouro · Looped Language Models ↗ · LLM Architecture Gallery ↗ · Ouro-2.6B-Thinking · 官方实现 ↗
解释
本块首次出现的知识点
本块相关内容已在前文介绍
英文原文 12
200 词 · 1 张图2.4 Routing flexible loop counts
Another approach is Mixture-of-Recursions, a paper from 2025 that is essentially a more sophisticated version of the Universal Transformer discussed earlier. Similar to the Universal Transformer, individual tokens pass the transformer blocks one or more times as illustrated in the figure below. However, the innovation is how this looping number is determined on a per-token basis.
In the following figure from the paper, the looped (repeated) stack is called a recursion block here. This contains several transformer blocks, and it sits between separate first and last transformer blocks (labeled Layer 0 and Layer L-1).
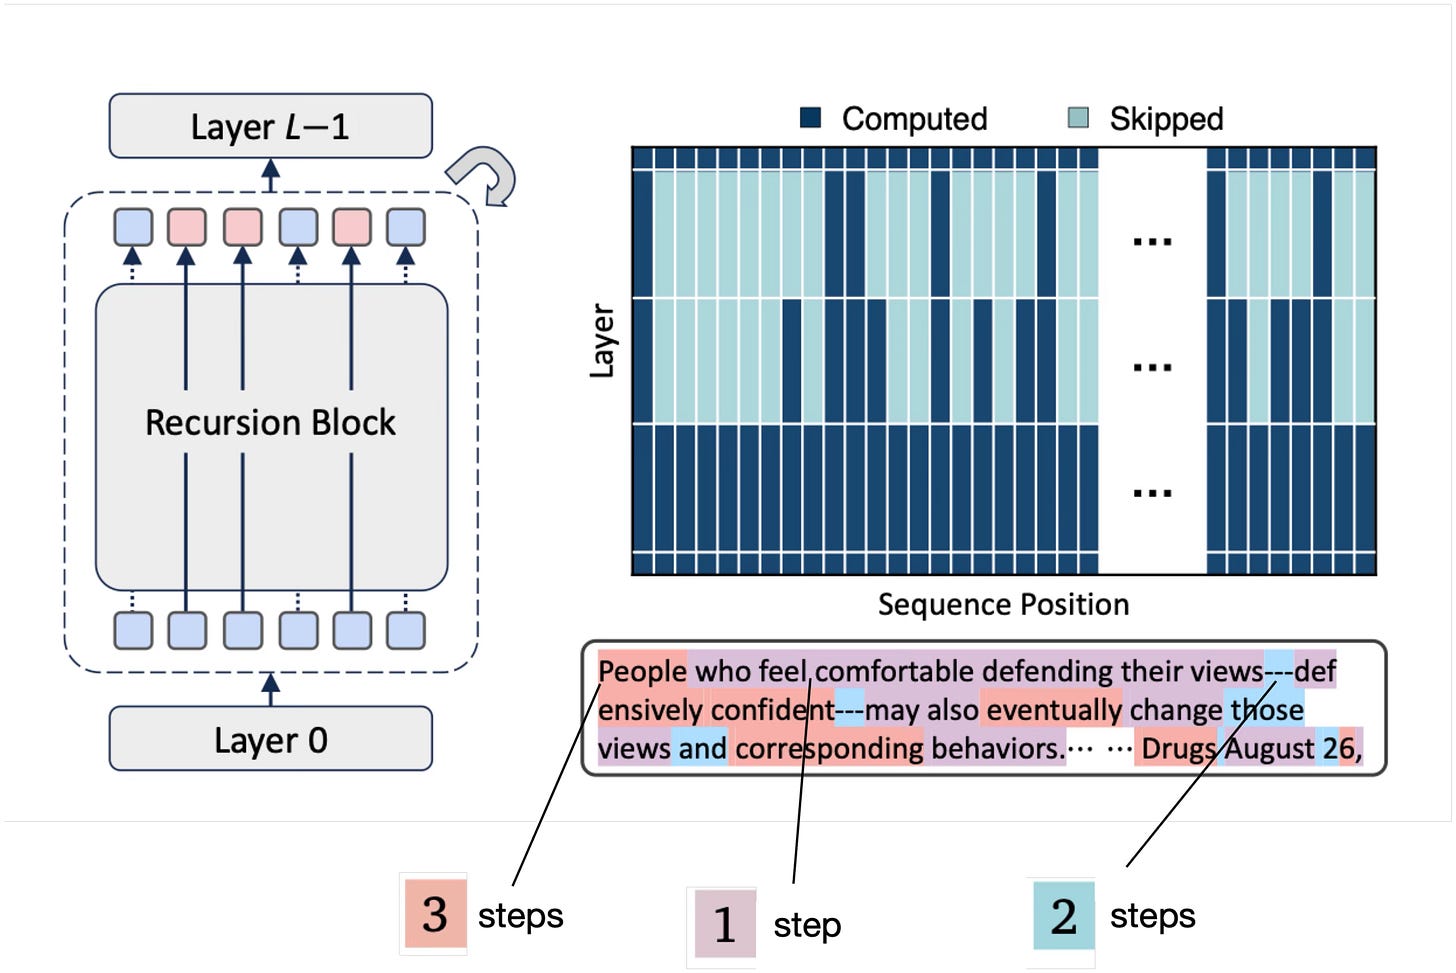
How does the model decide how many times a token should go through the recursion block? In the previously discussed Universal Transformer, it’s based on a learned halting probability at each step. This Mixture-of-Recursion approach here uses a small, learned router. This is similar to the routing idea in a mixture-of-experts model, except that here the routing decision determines how many times to apply the shared stack.
中文译文 12
300 字2.4 通过路由灵活决定循环次数
另一种方法来自 2025 年的 Mixture-of-Recursions 论文,它可以看作前面讨论的 Universal Transformer 的更复杂版本。与 Universal Transformer 类似,各个 token 会经过 Transformer 块一次或多次,如下图所示。不过,它的创新之处在于,如何为每个 token 单独决定循环次数。 [1]
在下面这张论文插图中,循环或重复使用的堆栈被称为递归块(recursion block)。它包含多个 Transformer 块,位于独立的首个块和末个块之间,图中分别标为 Layer 0 和 Layer L-1。
模型如何决定某个 token 应当通过递归块多少次?前面讨论的 Universal Transformer 依据每一步学习到的停止概率来决定。这里的 Mixture-of-Recursion 方法则使用一个小型、可学习的路由器。这与混合专家模型的路由思想类似,只不过这里的路由决定的是共享堆栈应当运行多少次。
上下游
本块首次出现的来源与延伸
提供路由、训练与评估实现,便于把论文中的方法用于实际实现。
已读项目说明本块新增 1 项 · 另有 1 项已在前文介绍
判断
对本块内容的判断
这一结构把共享核心放在首尾独立层之间。论文的贡献需要结合路由与缓存设计理解,不能仅归结为增加一个循环;图中的路径示例也不是对某个词固定不变的规定。 路由器依据包含上下文的隐藏表示决策,这支持作者关于同一词可走不同路径的解释。图中两种路由的决策时机不同,比较时还要考虑负载均衡与实现开销。
核验与延伸:Mixture-of-Recursions · NeurIPS 2025 ↗ · MoR · 作者官方复现代码 ↗
解释
本块首次出现的知识点
本块相关内容已在前文介绍
英文原文 13
229 词 · 1 张图The router operates on a token’s hidden representation, which also contains information about its context. So, we shouldn’t think of this as assigning every occurrence of a particular token the same number of passes (i.e., the word “People” in the figure above doesn’t always go through a loop of 3). The decision can change depending on where that word appears and what came before it.
Now, how does the routing work exactly? The paper explores two ways to make this routing decision, as illustrated below.
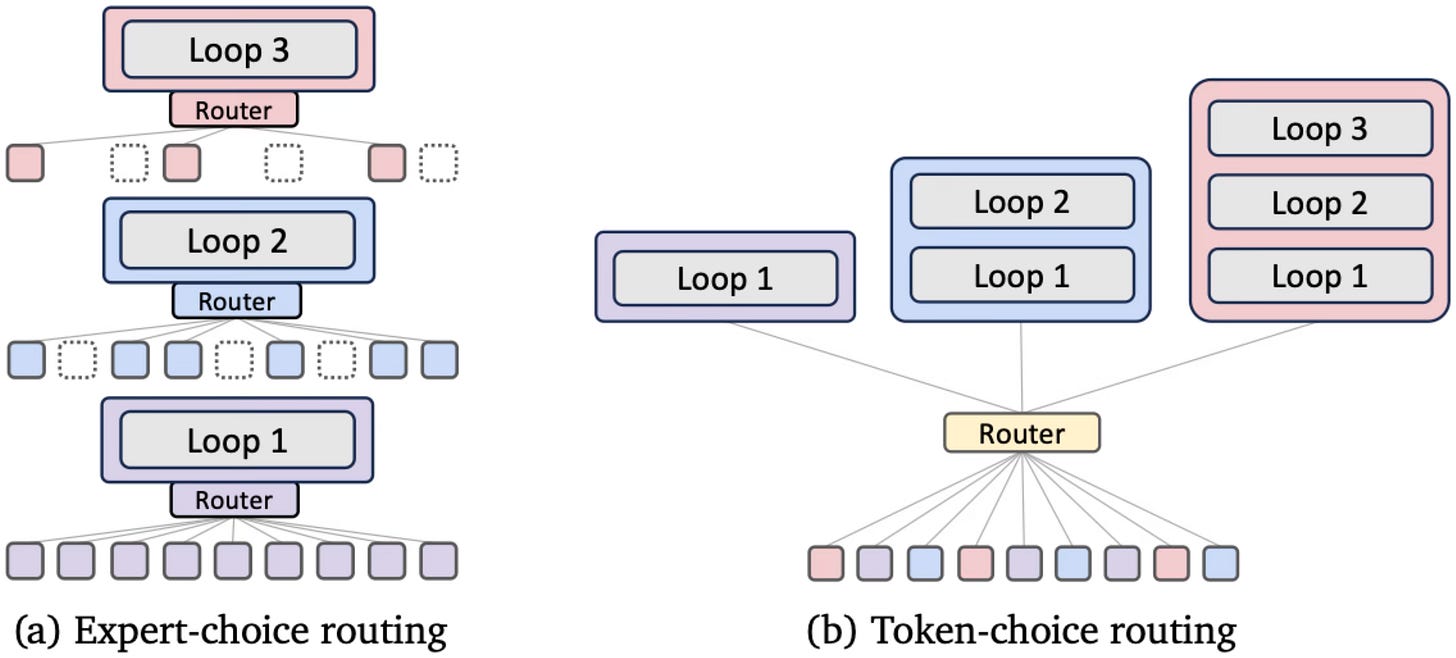
In expert-choice routing, which is shown in the left subpanel in the figure above, each recursion step selects which tokens it will process. Tokens that exit are excluded from later steps. In token-choice routing, shown on the right, the router makes one decision at the beginning, assigning each token to a path with one, two, or three passes.
In both cases, the transformer weights are reused across passes, similar to Nanbeige, etc. But the additional flexibility comes from choosing how much computation each token receives. The model and its routers are trained together, so the model learns to work with these different paths during training.
中文译文 13
348 字路由器处理的是 token 的隐藏表示,其中也包含上下文信息。因此,不应理解为同一个 token 每次出现都会被分配相同的循环次数。例如,上图中的单词“People”并不总是循环 3 次;决定会随它出现的位置和前面的内容而变化。
那么,这种路由究竟如何工作?论文探索了两种做出路由决策的方法,如下图所示。
在上图左侧的 expert-choice routing(专家选择路由)中,每个递归步骤选择自己将处理哪些 token。退出的 token 不再进入后续步骤。在右侧的 token-choice routing(token 选择路由)中,路由器在开始时只做一次决策,将每个 token 分配到经过一遍、两遍或三遍计算的路径。
在这两种情况下,Transformer 权重都会在不同轮次间复用,与 Nanbeige 等模型相似。它的灵活之处在于,可以为不同 token 分配不同的计算量。模型与路由器一起训练,因此模型会在训练过程中学会适应这些不同的路径。
上下游
本块首次出现的来源与延伸
本块相关内容已在前文介绍
判断
对本块内容的判断
路由器依据包含上下文的隐藏表示决策,这支持作者关于同一词可走不同路径的解释。图中两种路由的决策时机不同,比较时还要考虑负载均衡与实现开销。 图中同时改变模型规模和计算预算,纵轴是验证损失。路由与模型联合训练这一点很关键:不能把训练好的普通模型临时多循环几次,视作相同的实验。
核验与延伸:Mixture-of-Recursions · NeurIPS 2025 ↗ · MoR · 作者官方复现代码 ↗
解释
本块首次出现的知识点
本块相关内容已在前文介绍
英文原文 14
222 词 · 1 张图2.5 How well does this work?
The plot from the Mixture-of-Recursions paper below compares a regular transformer (Vanilla), a transformer with fixed recursion (Recursive), and Mixture-of-Recursions (MoR) for different model sizes and compute budgets (x-axis).
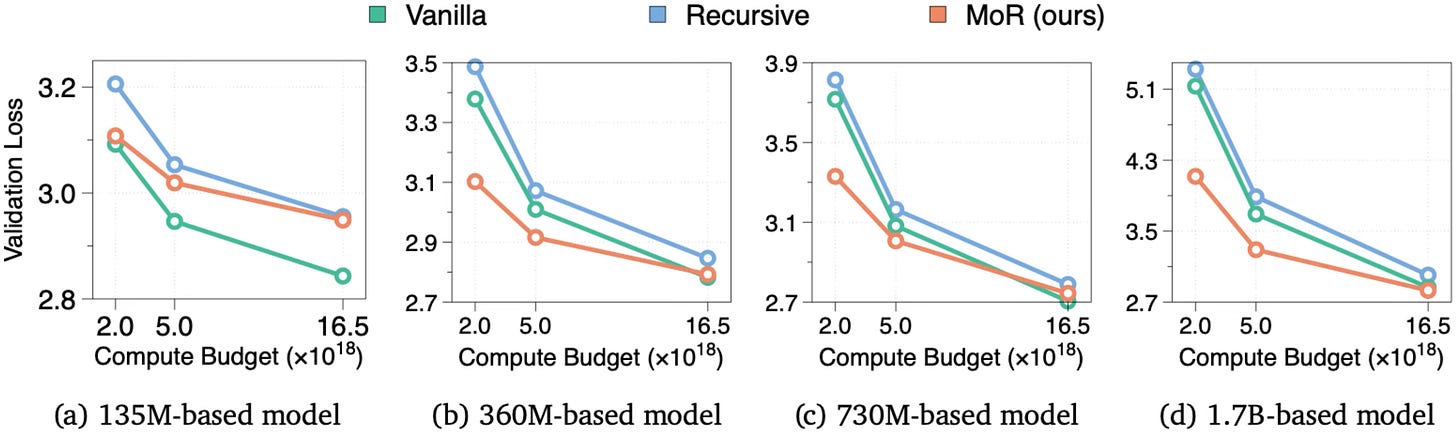
At the smallest model scale, the regular transformer performs best. For the larger models, Mixture-of-Recursions catches up and often performs better, especially at the smaller training budgets. At the largest budget, several of the curves are very close. So, the advantage depends on the model size and how much compute we spend on training.
Another detail here is that equal training compute doesn’t necessarily mean an equal number of training tokens. By skipping some computation, Mixture-of-Recursions can process more tokens within the same budget.
I think this is an interesting example because it shows that there are several choices within the looped-transformer idea, that is, how many loops there are at each position and how that’s decided.
So, in short, we can say that using looped transformers can improve model quality at a fixed compute budget if the model is large enough. (It also illustrates the importance of running some experiments at scale; e.g., just looking at the smaller 135M parameter model, we would have drawn the opposite conclusion.)
中文译文 14
356 字2.5 这种方法效果如何?
下方来自 Mixture-of-Recursions 论文的图,在不同模型规模和计算预算下,比较了常规 Transformer(Vanilla)、固定循环次数的 Transformer(Recursive),以及 Mixture-of-Recursions(MoR)。横轴表示计算预算。
在最小的模型规模下,常规 Transformer 表现最好。对于较大的模型,Mixture-of-Recursions 能够追平,并且经常表现得更好,尤其是在较低的训练预算下。在训练预算最高时,几条曲线已经非常接近。因此,优势取决于模型规模,以及我们投入多少训练计算量。
这里还有一个细节:训练计算量相同,并不一定意味着训练 token 数相同。通过跳过一部分计算,Mixture-of-Recursions 可以在同一预算内处理更多 token。
我认为这个例子很有意思,因为它说明,循环 Transformer 并不只有一种实现方式:每个位置循环多少次,以及如何决定这些次数。
因此,可以简要地说:如果模型足够大,循环 Transformer 能在计算预算不变的情况下提升模型表现。这也说明了在较大规模上做实验的重要性;例如,如果只看较小的 135M 参数模型,我们会得出相反的结论。
上下游
本块首次出现的来源与延伸
6.8%—18% 是根据特定实验范围内的计算量与表现关系拟合出的节省幅度,需保留模型配置与计算范围。
已核对预算匹配与拟合区间本块新增 1 项 · 另有 2 项已在前文介绍
判断
对本块内容的判断
图中同时改变模型规模和计算预算,纵轴是验证损失。路由与模型联合训练这一点很关键:不能把训练好的普通模型临时多循环几次,视作相同的实验。 固定训练 FLOPs 不等于固定训练 token 数;较低损失可能同时反映路径设计和预算内见到更多数据。原文从具体规模结果推广时,需要保留所测设置这一范围。
SMELT 支持特定配置的收益,不证明所有循环都划算
原图 11 在 135M 规模上就显示常规 Transformer 更优。SMELT 的 6.8%—18% 则来自特定的 MoE 设计方案、相同预算下的比较和缩放律拟合;论文更大计算量处还明确区分了外推。因此可以说“所测配置在相应范围内有优势”,不能把它扩展为任意模型、任意循环数、任意部署硬件都更好。SMELT ↗ · MoR ↗ · 定位原文 ↑
核验与延伸:Mixture-of-Recursions · NeurIPS 2025 ↗ · MoR · 作者官方复现代码 ↗ · SMELT · Compute-Matched MoE Looped Transformers ↗
解释
本块首次出现的知识点
本块相关内容已在前文介绍
英文原文 15
256 词 · 2 张图3. Side note: Recurrent Neural Networks (RNNs)
By the way, if you have a background in deep learning (or even artificial neural networks in the 1990s), the looping or “recurrent depth” idea should be somewhat familiar. Remember recurrent neural networks (RNNs)? The whole idea in RNNs is to reuse the layers (weights) from a previous iteration.
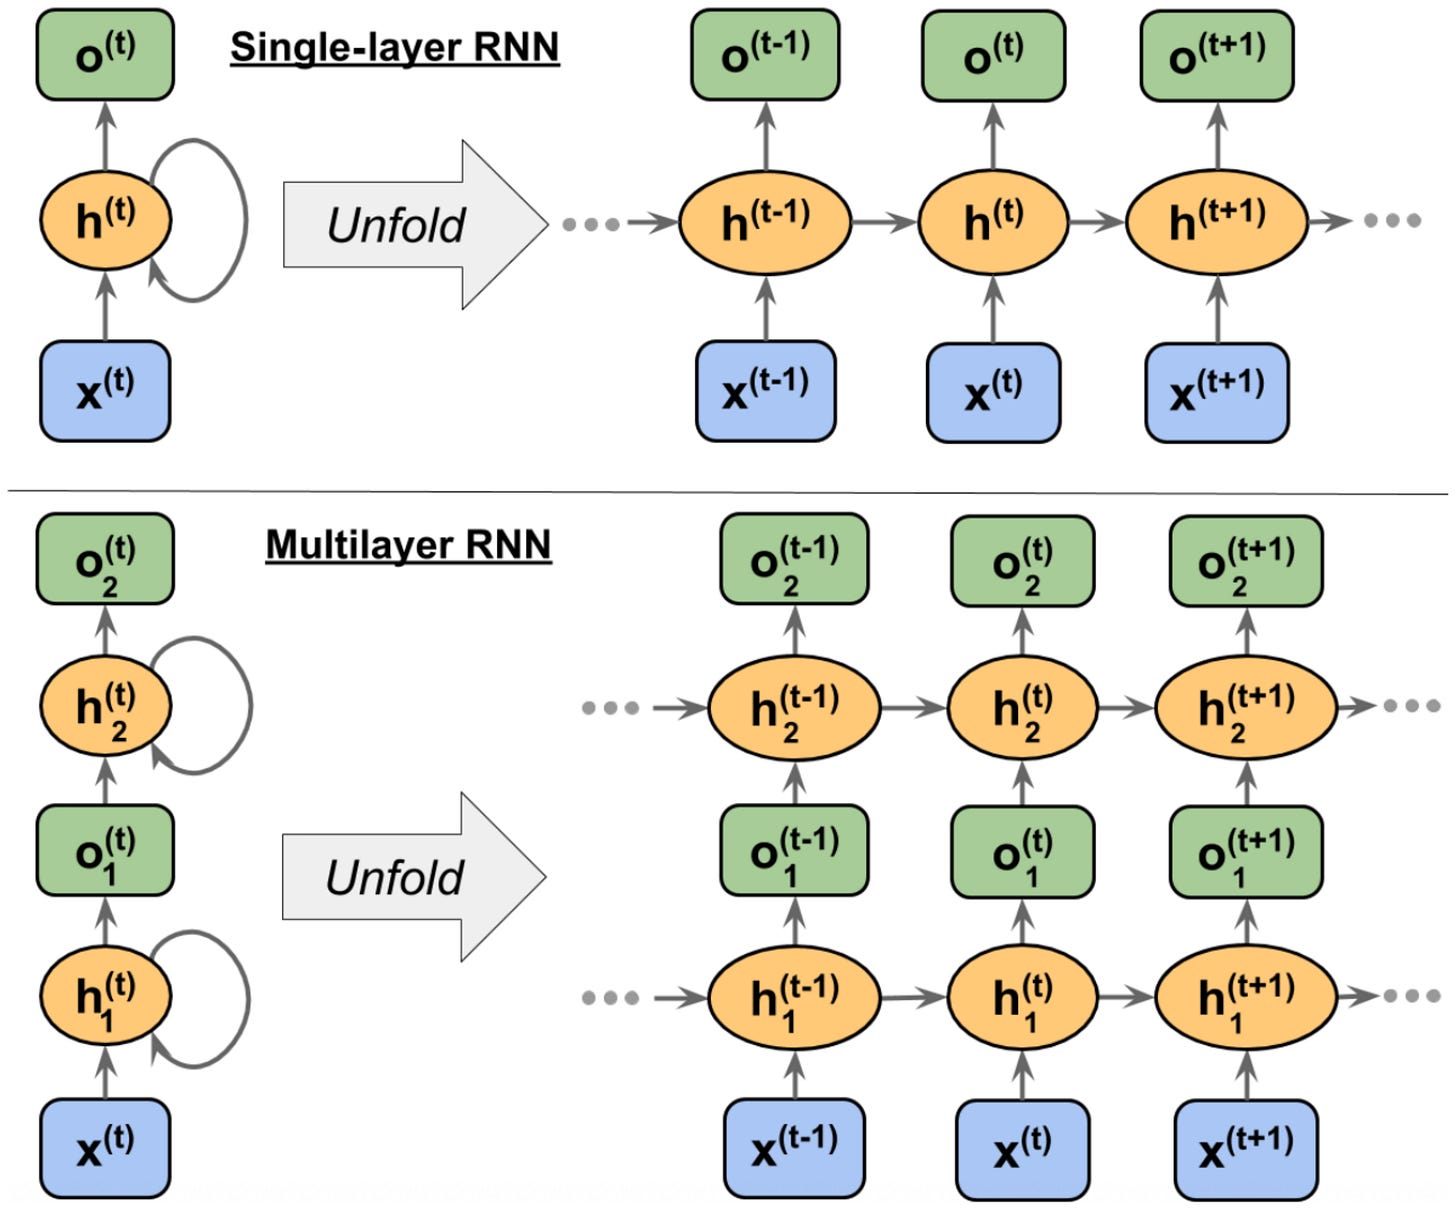
The main distinction is that RNNs reuse their weights across time steps. That is, the hidden state is carried forward from one token to the next. In the looped transformer, the looping of a token is across the architecture depth.
Or, in other words, in a conventional RNN, each step takes the next element in the input sequence and the hidden state from the previous step. So, when the RNN is processing a chunk of text, it reads one word or token at a time and carries information from the earlier words forward in its hidden state.
In a looped transformer, the intermediate representation of a given token goes through the transformer stack multiple times. The model still uses attention to pass information between tokens.
If this analogy is a bit too confusing, don’t worry about it too much. A perhaps simpler way to think about looped transformers is to think of them as reusing transformer blocks, similar to making the model bigger but with weight sharing.
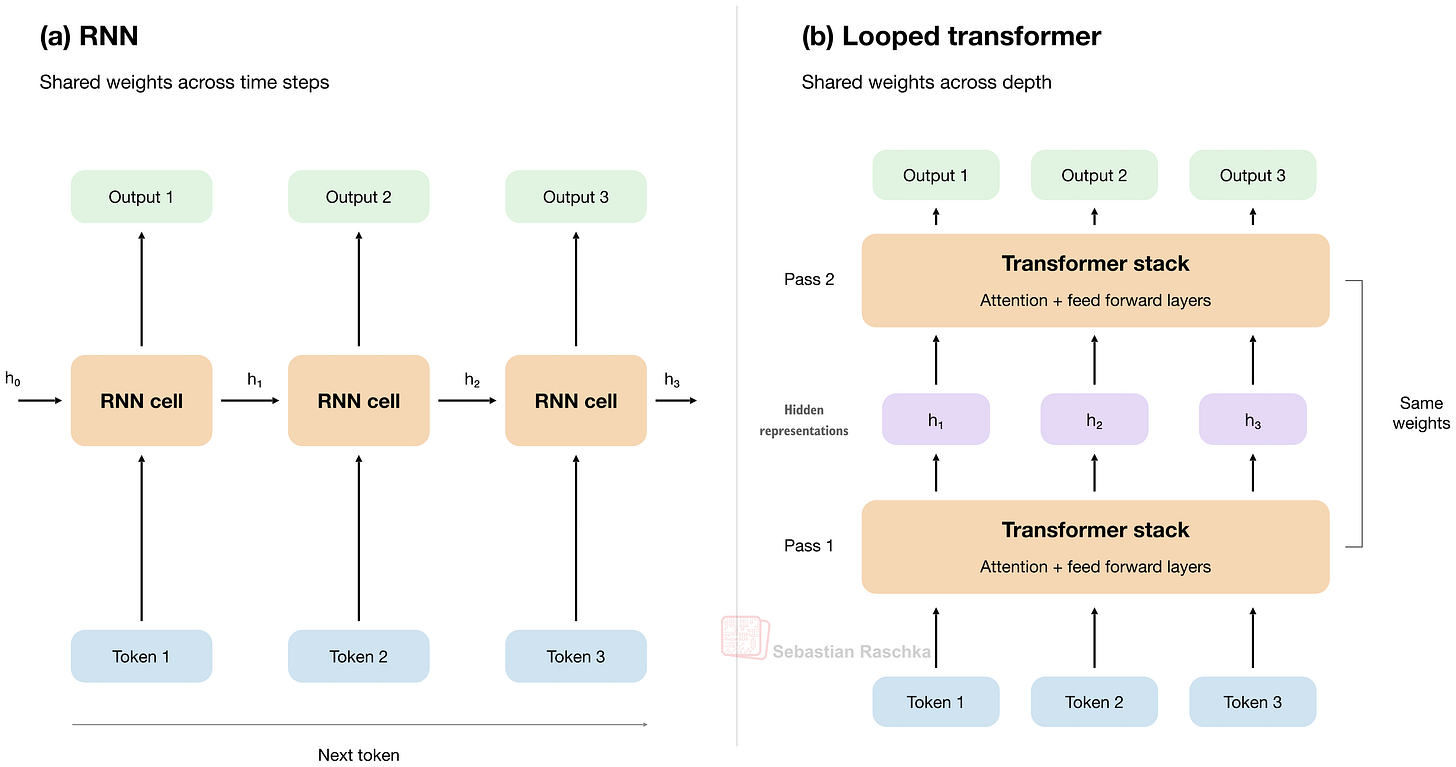
中文译文 15
373 字3. 补充说明:循环神经网络(RNN)
顺便一提,如果你有深度学习背景,甚至接触过 20 世纪 90 年代的人工神经网络,那么循环或“递归深度”的想法应该会让你觉得有些熟悉。还记得循环神经网络(RNN)吗?RNN 的核心思想,就是复用前一次迭代中的层及其权重。
主要区别在于,RNN 跨时间步复用权重,也就是把隐藏状态从一个 token 传给下一个 token。循环 Transformer 中,某个 token 的循环则发生在架构深度方向上。
换句话说,在常规 RNN 中,每一步接收输入序列中的下一个元素,以及上一步的隐藏状态。所以,当 RNN 处理一段文本时,它一次读入一个词或 token,并通过隐藏状态把前面词语的信息向后传递。
在循环 Transformer 中,某个 token 的中间表示会多次通过 Transformer 堆栈;模型仍然利用注意力在不同 token 之间传递信息。
如果这个类比让你有些困惑,也不必过于纠结。或许更简单的理解方式,是将循环 Transformer 理解为反复使用同一组 Transformer 块:类似于把模型做得更大,只不过权重是共享的。
上下游
本块首次出现的来源与延伸
保留原文提供的资源地址,供查看对应材料和上下文。
原文链接;未将未核验内容当作新证据前置块、循环核心、后置块,以及随机训练深度和推理时停止策略。
已读结构与推理机制本块新增 2 项 · 另有 2 项已在前文介绍
判断
对本块内容的判断
用 RNN 解释“复用权重”是有帮助的类比。关键区别是状态沿序列时间还是沿架构深度传递;不能因二者都有循环箭头,就当成相同模型。 本块先完成结构类比,再转向 Astra 的架构证据。图示说明一种机制如何工作,却不能证明某个闭源模型使用了该机制;作者注明尚无官方确认是必要的限定。
核验与延伸:amzn.to · 原文资源 ↗ · Universal Transformers · 2018 / ICLR 2019 ↗ · Scaling up Test-Time Compute with Latent Reasoning ↗ · The Information · 原始报道入口 ↗
解释
本块首次出现的知识点
两种循环轴:沿序列时间,或沿网络深度
RNN 将 ht−1 传给下一个位置 t,沿序列共享权重。循环 Transformer 则在生成当前 token 前,多次更新同一位置的隐藏状态。Full-bandwidth 研究又把前一个 token 的最终表示反馈到下一个位置。理解箭头沿哪个方向移动,比看到“recurrent”就把它们当成同一种结构更可靠。
注意力仍负责不同 token 之间的信息交互。保留连续隐藏表示,与把上一次的文字回答作为下一次提示输入,也不是相同的计算过程。
本块新增 1 项 · 另有 1 项已在前文介绍
英文原文 16
270 词 · 1 张图4. Does Astra even use looped transformers?
Before we discuss whether the looped transformer mechanism obscured reasoning traces, as rumored in The Information quote from earlier, does GPT-6 Astra even use the looped transformer concepts?
We have to keep in mind that this is still just a rumor or scoop, with no official confirmation. If the model were open-weight, we could double-check this ourselves, of course, but in this case we have to rely on unverified reporting.
However, I think it’s highly likely that GPT-6 Astra uses looped transformer aspects. First, there is the reporting mentioned above. Second, it’s a technique that has shown promise in past studies (as discussed earlier), so why not? Third, OpenAI’s chief scientist said the following.
[...] The depth of the computation graph for our present frontier models, including Astra, is within a factor of two of GPT-4. [...]
However, this doesn’t confirm the looped transformer architecture explicitly, and it could also just mean they use twice as many regular transformer blocks.
In my opinion, the success (i.e., good modeling performance) behind Astra is likely primarily due to other reasons, namely improved training recipes and training data.
The looped transformer tweak might help a bit, but I think that The Information is overestimating its contribution.
5. Hiding chains of thought
Next, let’s finally address the elephant in the room: does looped transformer obscure the reasoning traces?
First, OpenAI has been hiding (most of) the reasoning traces from users from the very beginning, since OpenAI o1, anyway. So, for the end-user, there shouldn’t be a big difference.
中文译文 16
424 字4. Astra 究竟有没有使用循环 Transformer?
前面引用的 The Information 报道称,循环 Transformer 会让推理轨迹变得不透明。在讨论这一说法之前,我们先弄清楚:GPT-6 Astra 到底有没有采用循环 Transformer 这类设计?
必须记住,这仍然只是传闻或独家消息,并没有得到官方确认。如果模型开放了权重,我们当然可以自己核查,但在这里,我们只能依赖尚未证实的报道。
不过,我认为 GPT-6 Astra 很可能使用了循环 Transformer 的某些设计。首先,有前面提到的报道;其次,过去的研究已经显示这项技术有前景,那么为什么不采用呢?第三,OpenAI 的首席科学家曾发表以下说法。 [1]
[……]我们目前的前沿模型,包括 Astra,其计算图深度在 GPT-4 的二分之一至两倍范围内。[……]
不过,这并没有明确确认循环 Transformer 架构,也可能只是说他们使用了两倍数量的常规 Transformer 块。
在我看来,Astra 之所以表现出色,很可能主要是因为训练方法和训练数据得到了改进。
循环 Transformer 的调整或许有所帮助,但我认为 The Information 高估了它的贡献。
5. 隐藏思维链
接下来,我们终于要正面讨论核心问题:循环 Transformer 会让推理轨迹变得不透明吗?
首先,OpenAI 从一开始,也就是从 OpenAI o1 起,就已经对用户隐藏了大部分推理轨迹。因此,对最终用户来说,应该不会有太大区别。
上下游
本块首次出现的来源与延伸
保留原文提供的资源地址,供查看对应材料和上下文。
原文链接;未将未核验内容当作新证据计算图深度的范围没有直接指明共享权重、循环次数或训练方案。
引文来自所供本地文件本块新增 2 项 · 另有 5 项已在前文介绍
判断
对本块内容的判断
本块先完成结构类比,再转向 Astra 的架构证据。图示说明一种机制如何工作,却不能证明某个闭源模型使用了该机制;作者注明尚无官方确认是必要的限定。 报道、可行性和计算图深度范围都不是唯一确定架构的证据。关于数据、训练方案或循环贡献大小的判断,也需要消融实验才能分离。
Astra 使用循环架构,仍不是本文已经证明的事实
报道、其他模型采用该技术,以及计算图深度的范围,能构成讨论线索,却不能唯一确定 Astra 的结构。相同深度可以来自独立层,也可以来自共享层。进一步说,性能究竟主要来自数据、训练方案还是架构,需要控制其他条件的消融实验;仅凭架构改动看起来很小,也不能判断其贡献很小。定位原文 ↑ · 官方发布说明 ↗
核验与延伸:The Information · 原始报道入口 ↗ · said the following ↗ · Universal Transformers · 2018 / ICLR 2019 ↗ · Scaling up Test-Time Compute with Latent Reasoning ↗
解释
本块首次出现的知识点
本块相关内容已在前文介绍
英文原文 17
289 词 · 2 张图So, the interpretation-concern is mostly with respect to the model developers.
Either way, I don’t think that looped transformers are significant contributors towards hiding or obscuring chains of thought. To explain my own reasoning (no pun intended), let’s take a step back and explain how reasoning models work.
5.1 Reasoning in brief
Reasoning models typically generate intermediate steps before producing a final answer. These steps use regular text token (that are optionally hidden from the user in some user interfaces) and called a reasoning trace or chain of thought.
For example, say we ask for two numbers whose sum is 10 and whose product is 21. In the figure below, the model tries 5 and 5 at first. While the sum is correct, the product is 25, not 21. Next, it then tries 3 and 7 and checks both conditions again.
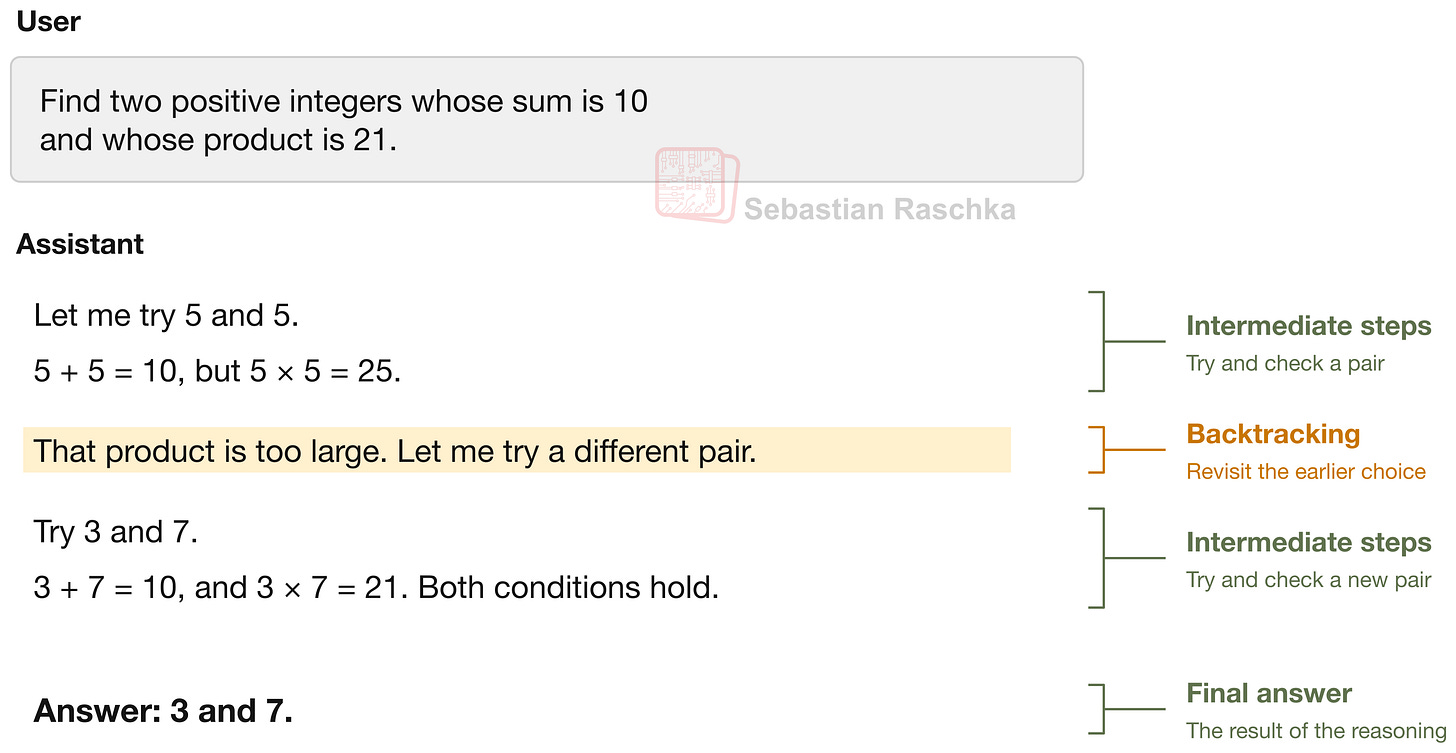
The figure illustrates how a reasoning model “reasons,” including backtracking. That is, the model notices a mistake, then revisits an earlier choice, and then continues with a different approach.
Note that the model still generates one token at a time, using the prompt and previous tokens as context. So, these intermediate steps work as a scratch pad and add computation before the final answer.
The final answer can then be much shorter than the reasoning trace that preceded it, as shown in the example above. (OpenAI tends to hide most of the reasoning traces from the users.)
For more details on understanding and developing reasoning models, I recommend my book Build a Reasoning Model From Scratch.
中文译文 17
455 字所以,这里的可解释性担忧,主要涉及模型开发者能否理解模型的推理过程。
无论如何,我并不认为循环 Transformer 是隐藏思维链、或使思维链变得不透明的重要原因。为了说明我的推理依据(这里并非有意玩文字游戏),我们先退一步,看看推理模型是如何工作的。
5.1 简述推理过程
推理模型通常会在给出最终答案之前生成中间步骤。这些步骤使用普通的文本 token,在某些界面中可以选择对用户隐藏;它们被称为推理轨迹或思维链。
例如,假设我们要求找出两个数,它们的和是 10,乘积是 21。下图中,模型首先尝试 5 和 5。虽然和正确,但乘积是 25,而不是 21。随后,模型尝试 3 和 7,并重新检查两个条件。
这张图展示了推理模型如何“推理”,其中包括回溯:模型发现错误,回到之前的选择,再换一种方式继续。
注意,模型仍然以提示和先前的 token 为上下文,每次生成一个 token。因此,这些中间步骤相当于草稿纸,让模型在给出最终答案前进行更多计算。
如上面的例子所示,最终答案可以比它前面的推理轨迹短得多。OpenAI 通常会对用户隐藏大部分推理轨迹。
如果想进一步了解和开发推理模型,我推荐自己的书《Build a Reasoning Model From Scratch》。 [1]
上下游
本块首次出现的来源与延伸
保留原文提供的资源地址,供查看对应材料和上下文。
原文链接;未将未核验内容当作新证据文字解释可能遗漏实际影响答案的因素;不把该研究直接当成 Astra 的测量。
已读研究摘要本块新增 2 项 · 另有 3 项已在前文介绍
判断
对本块内容的判断
算术图是帮助理解推理轨迹的示意,不是评测数据。看见模型写出纠错过程,不等于已经观察到所有决定答案的内部因素,也不意味着每条轨迹都同样忠实。 中间 token 与循环都能增加计算,但两者并非逐个等价。要证明循环替代了文字步骤,需要同时测量循环预算、输出长度和任务表现,不能只比较最终答案的长短。
核验与延伸:Build a Reasoning Model From Scratch ↗ · Language Models Don’t Always Say What They Think ↗ · GPT-6 Astra 系统卡 · §9 Monitorability ↗ · GPT-6 Astra 官方发布说明 ↗
解释
本块首次出现的知识点
本块相关内容已在前文介绍
英文原文 18
289 词 · 2 张图5.2 Token usage and shorter chains of thought
Now, extra tokens in the reasoning trace add more computation. Looped transformers add more computation, because the tokens go through more transformer blocks. One might argue that a model with looping uses more computation internally, it doesn’t need as many external thinking tokens.
Below is a selection of the GPT-6 benchmarks with the output token number on the x-axis.
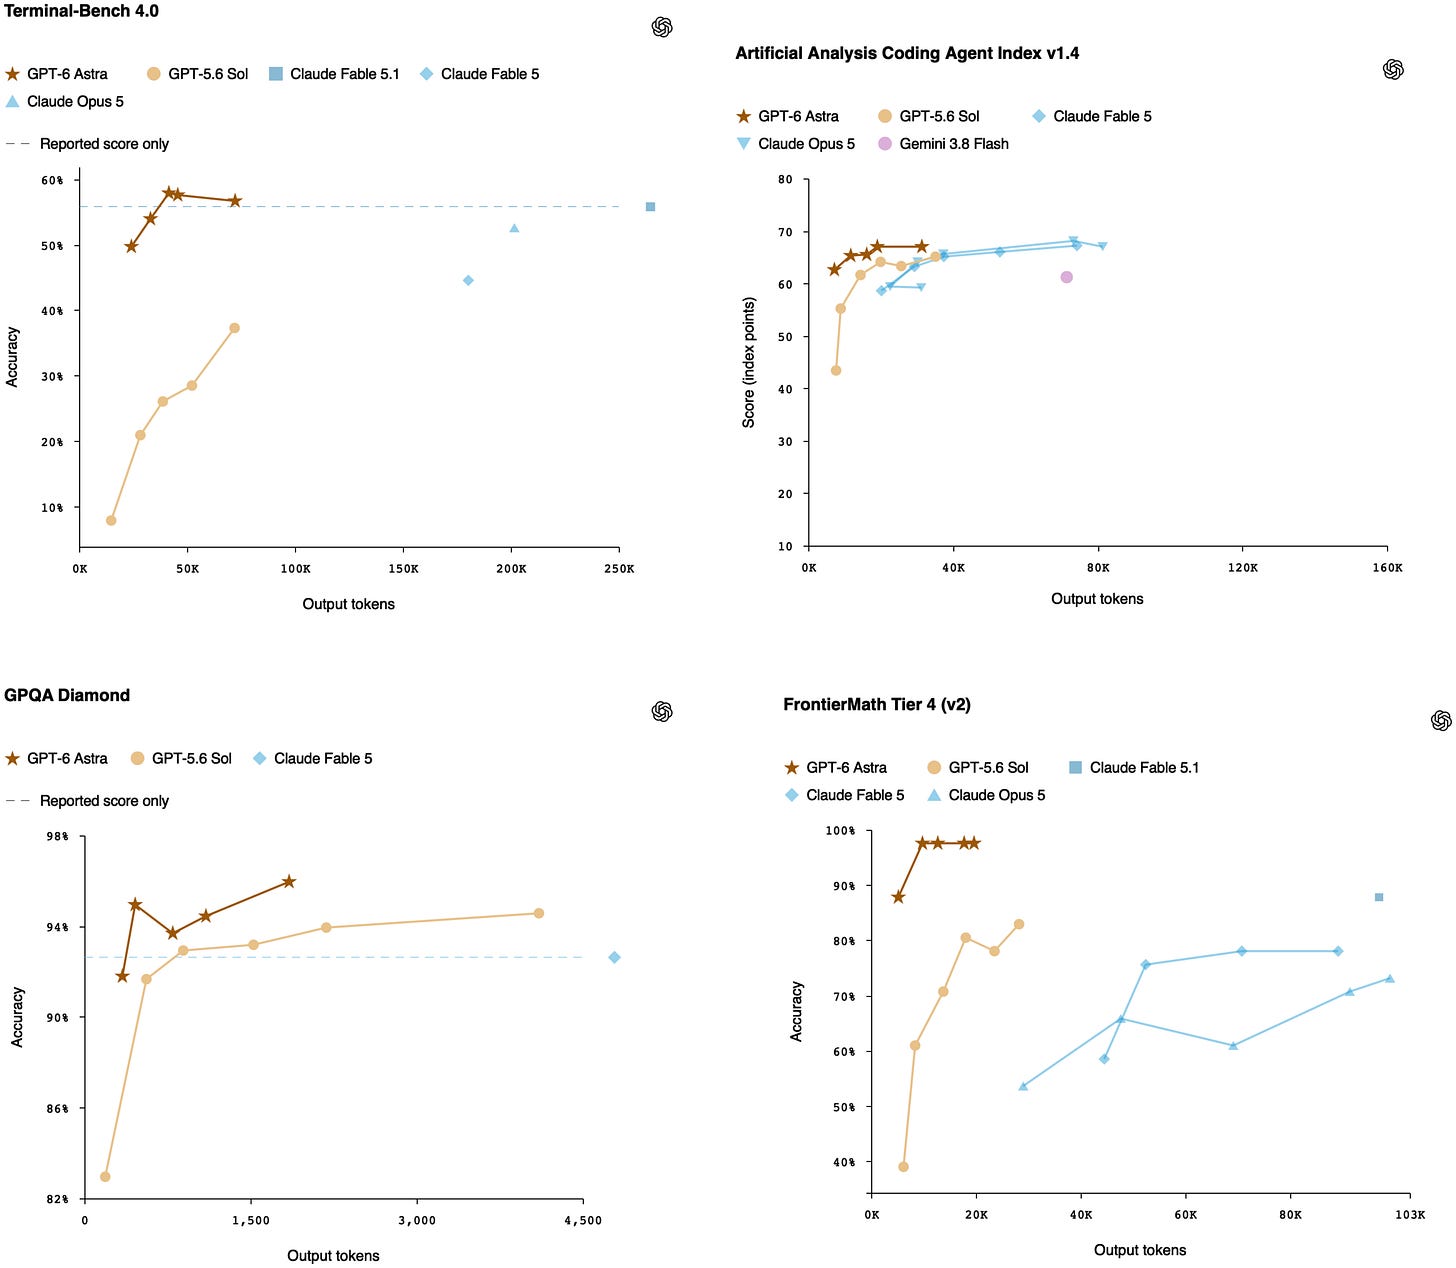
We can see that GPT-6 Astra doesn’t necessarily use fewer tokens than its GPT 5.6 Sol predecessor across effort levels overall. However, at a fixed accuray, it is true that GPT-6 Astra uses fewer tokens than GPT 5.6 Sol.
Is this a concern for interpretability? Not necessarily. Using fewer tokens could just mean that the model is more capable and makes fewer mistakes, uses less backtracking, and so on. I.e., it might just get more things right on the first try. To me, that doesn’t raise an immediate concern regarding interpretability.
I mean, the same is true for previous models. I don’t think that anyone has strong concerns that GPT 5.6 Sol is so much less interpretable than the smaller GPT 5.6 Luna model, which uses many more tokens for the same task performance, as shown below.
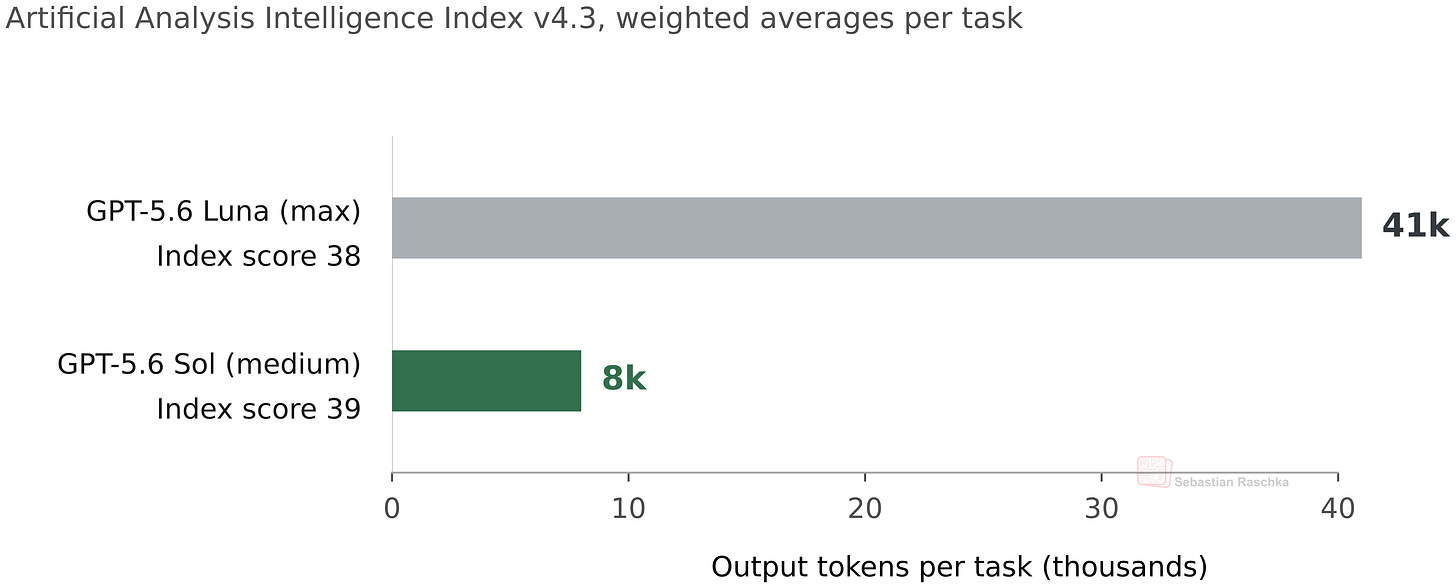
In fact, as we can see that Luna uses 80% more tokens than Sol at similar modeling performance. Does that make Sol that much less interpretable?
Rather, the more plausible answer here is that more capable (bigger, well-trained models that use more compute) can solve problems more efficiently, where “efficient” here means fewer tokens.
中文译文 18
465 字5.2 Token 用量与更短的思维链
推理轨迹中的额外 token 会增加计算量。循环 Transformer 也会增加计算,因为 token 要经过更多次 Transformer 块。有人可能会认为,采用循环的模型在内部做了更多计算,因此就不需要那么多以文字形式呈现的推理 token。
下面选取了一些 GPT-6 基准评测,横轴表示输出 token 数量。 [1]
从不同推理强度下的结果来看,GPT-6 Astra 使用的 token 并不一定比上一代 GPT 5.6 Sol 更少。不过,在准确率固定时,GPT-6 Astra 确实比 GPT 5.6 Sol 使用更少的 token。
这是否会引起可解释性方面的担忧?不一定。使用更少的 token,可能只是说明模型能力更强,犯错更少,回溯也更少,等等。也就是说,它也许在第一次尝试时就能把更多事情做对。对我而言,这不会立即引发可解释性方面的担忧。
我的意思是,以前的模型也是如此。较小的 GPT 5.6 Luna 要达到相同的任务表现,需要使用多得多的 token,如下图所示。我不认为有人会因此特别担心 GPT 5.6 Sol 的推理过程比 Luna 难理解得多。
实际上,可以看到,在模型表现相近时,Luna 比 Sol 多使用了 80% 的 token。这就意味着 Sol 的可解释性差了那么多吗?
更合理的解释是,能力更强的模型——规模更大、训练更充分、使用更多计算的模型——能够更高效地解决问题。这里的“高效”指使用更少的 token。
上下游
本块首次出现的来源与延伸
保留原文提供的资源地址,供查看对应材料和上下文。
原文链接;未将未核验内容当作新证据把这篇长文与其较早的简短观点连接起来。
先前已在 X 核对本块新增 2 项 · 另有 6 项已在前文介绍
判断
对本块内容的判断
中间 token 与循环都能增加计算,但两者并非逐个等价。要证明循环替代了文字步骤,需要同时测量循环预算、输出长度和任务表现,不能只比较最终答案的长短。 这一块既有比较条件问题,也有可以直接由原图复核的百分比问题。请留意模型推理强度、指数版本与百分比所用的分母。 “链更短”不足以解释所有监控差异;可监控性下降也不要求模型有意欺骗。系统卡提供了更具体的测量,因此这里需要比原文的直觉解释更谨慎。
41k 对 8k,应是 Sol 约少 80%,而非 Luna 只多 80%
所供图 18 标出 Luna 41k、Sol 8k。以 Sol 为基准,Luna 多用 (41−8)÷8 = 412.5%;以 Luna 为基准,Sol 少用 (41−8)÷41 ≈ 80.5%。两者分别是“多约 4.1 倍”和“少约八成”。这项纠正依据原图标示数字,不依赖对在线榜单当前数值的猜测。查看图注与原图 ↑ · 查看原句 ↑
核验与延伸:GPT-6 Astra 官方发布说明 ↗ · Artificial Intelligence Index v4.3 ↗ · Scaling up Test-Time Compute with Latent Reasoning ↗ · GPT-6 Astra 系统卡 · §9 Monitorability ↗
解释
本块首次出现的知识点
本块相关内容已在前文介绍
英文原文 19
293 词It’s also worth keeping in mind that a reasoning trace is not guaranteed to faithfully describe everything that happens inside the model. In my view, the only valid concern is that looped transformers purposefully mislead users by presenting “fake” reasoning traces more often than conventional transformers. But I don’t think we have any strong evidence that this is happening.
Now, Astra’s system card does state that there is also evidence of reduced monitorability of their reasoning traces, and there is a bit of regression relative to Sol. It’s mostly associated with shorter, less informative traces. But again, this doesn’t establish looping as the root cause. It could just be due to the shorter length in general, similar to the Luna vs Sol example above.
A few hours after I shared my thoughts about looped transformers with respect to hiding reasoning chains, Jakub Pachocki (OpenAI’s Chief Scientist) also shared the following clarification:
I want to prevent a race into unmonitorability kicked off by confused reporting. The depth of the computation graph for our present frontier models, including Astra, is within a factor of two of GPT-4. OpenAI has worked to preserve and utilize chain-of-thought monitoring since our very first reasoning models. We deeply care about this technique, as it can give us a view into how model alignment generalizes from its training distribution. I do think it is fragile and unfortunately trending in a negative direction, for reasons not contingent on architecture changes that I will write about soon. But there are things we can do to strengthen it, and it’s a core goal of our current research program.
The “confused reporting” likely refers to The Information’s aforementioned paragraph here, implying that the looping aspect does not have anything to do with chain-of-thought changes.
中文译文 19
500 字还需要记住,推理轨迹并不保证能够忠实描述模型内部发生的一切。在我看来,唯一站得住脚的担忧,是循环 Transformer 比常规 Transformer 更频繁地给出“虚假”推理轨迹,借此有意误导用户。但我认为,目前并没有有力证据表明这种情况正在发生。 [1]
不过,Astra 的系统卡确实指出,有证据表明它的推理轨迹可监控性有所下降,与 Sol 相比存在一定退步。这主要与更短、信息量更少的推理轨迹有关。但再次强调,这并不能证明循环就是根本原因。原因也可能只是推理轨迹总体变短,类似于前面 Luna 与 Sol 的比较。
在我分享了循环 Transformer 与隐藏推理链关系的看法之后,过了几个小时,OpenAI 首席科学家 Jakub Pachocki 也作出了以下澄清: [1] [2]
我不希望含混的报道引发一场竞赛,把模型推向越来越难以监控的方向。我们目前的前沿模型,包括 Astra,其计算图深度在 GPT-4 的二分之一至两倍范围内。从最早的推理模型起,OpenAI 就一直致力于保留并利用思维链监控。我们非常重视这项技术,因为它能让我们了解模型在训练分布之外的对齐表现。我确实认为,这项技术很脆弱,而且遗憾的是,目前正朝着不利的方向发展;造成这一趋势的原因不取决于架构是否发生变化,我很快会专门写文章讨论。不过,我们可以采取一些措施来加强它,这也是我们当前研究计划的核心目标。
这里的“含混的报道”很可能指前面提到的 The Information 那段文字;这番话暗示,循环这一架构设计与思维链的变化并没有关系。
上下游
本块首次出现的来源与延伸
保留原文提供的资源地址,供查看对应材料和上下文。
原文链接;未将未核验内容当作新证据本块新增 1 项 · 另有 5 项已在前文介绍
判断
对本块内容的判断
“链更短”不足以解释所有监控差异;可监控性下降也不要求模型有意欺骗。系统卡提供了更具体的测量,因此这里需要比原文的直觉解释更谨慎。 引文中的“不依赖架构变化”并不等于证明任何架构都绝不会影响监控。它也没有披露完整网络结构。目前可以得出的结论是:不能只凭架构传闻解释监控趋势。
可监控性的退化,不能简单归因于推理链较短
系统卡 §9.1.1 报告:在大多数相同 CoT 长度下,Astra 的 CoT 可监控性仍低于 Sol,较长链时差距缩小;不同监控范围也有不同结果。因此“主要只是变短”的解释不充分。同时,这些结果仍未把循环架构确认为原因。监控信息减少也不要求模型有意说谎,所以原文把唯一有效担忧限定为“有意提供假推理”过窄。系统卡 §9 ↗ · 定位原文 ↑
核验与延伸:Language Models Don’t Always Say What They Think ↗ · my thoughts ↗ · shared the following clarification ↗ · GPT-6 Astra 系统卡 · §9 Monitorability ↗
解释
本块首次出现的知识点
本块相关内容已在前文介绍
英文原文 20
310 词 · 1 张图6. Looped transformer research
Lastly, I want to share some interesting papers related to looped transformer architectures beyond the ones we already discussed.
6.1 Latent reasoning
Related to the Universal Transformer, the 2025 Scaling up Test-Time Compute with Latent Reasoning: A Recurrent Depth Approach paper studies how a model can use additional loops at inference time. For this, they trained a relatively modest but also not super tiny 3.5B-parameter model on 800B tokens.
Instead of reusing the same block over and over again as in the Universal Transformer, it repeats a stack like in Nanbeige; however, in contrast to Nanbeige, it sandwiches this shared stack of four blocks between 2 initial and 2 final blocks.
Also, what’s different from Nanbeige is that the shared stack receives the output of the initial blocks at the start of every loop, in addition to the previous loop’s hidden state. These are concatenated and passed through a learned linear projection before entering the four shared blocks. You can think of this as giving the stack access to the same initial input representation on every pass. This whole layout is summarized in the figure below.
So, in short, this is an additional and interesting looped transformer variant.
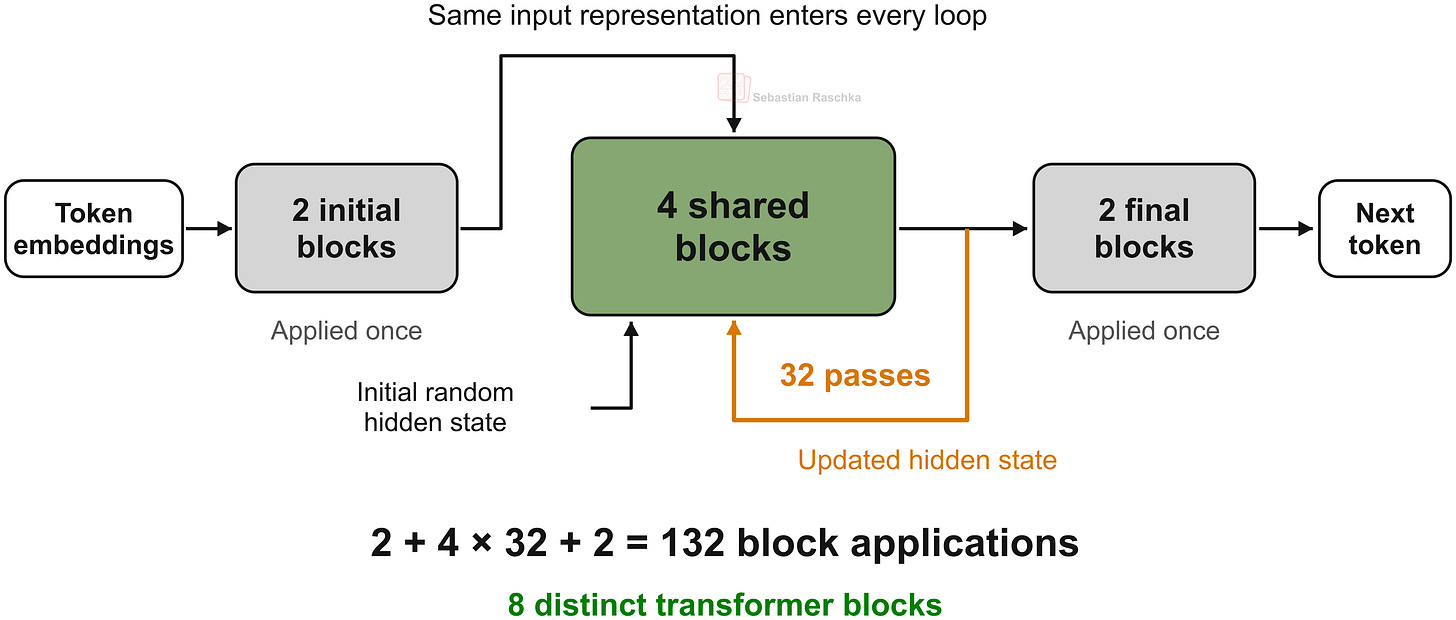
An interesting detail is that the researchers vary the number of loops during training. This prepares the model to work with different amounts of computation at inference time.
Here, during training, the loop count is randomly sampled. At inference, a fixed budget is chosen by whoever runs the model, such as 8, 32, or 64 loops. Additionally, they have an adaptive stopping mechanism for each token based on the next-token probability distribution. If the KL-divergence between 2 successive rounds is below a certain threshold, i.e., if the distributions are too similar, the looping is halted.
中文译文 20
491 字6. 循环 Transformer 研究
最后,除了已经讨论过的研究,我还想分享几篇与循环 Transformer 架构有关的有趣论文。
6.1 隐空间推理
另一个相关研究是 2025 年的《Scaling up Test-Time Compute with Latent Reasoning: A Recurrent Depth Approach》。论文探讨了模型如何在推理时增加循环次数。为此,研究人员用 800B token 训练了一个规模相对适中、但也并非特别小的 3.5B 参数模型。 [1]
它并没有像 Universal Transformer 那样反复运行同一个块,而是像 Nanbeige 一样重复运行一组块。不过,与 Nanbeige 不同的是,它把由四个共享块组成的堆栈,夹在前面的两个块和后面的两个块之间。
另一个与 Nanbeige 不同的地方是,在每轮循环开始时,共享堆栈除了接收上一轮的隐藏状态,还会接收初始块的输出。这两部分会先拼接,再经过一个可学习的线性投影,然后进入那四个共享块。你可以把它理解为:每一遍计算都允许堆栈访问同一份初始输入表示。下图概括了整个结构。
因此,这是循环 Transformer 的另一种有趣变体。
一个有意思的细节是,研究人员会在训练期间改变循环次数。这让模型提前适应推理阶段可能使用的不同计算量。
具体而言,训练时会随机采样循环次数。到了推理阶段,运行模型的人可以选择固定预算,例如 8、32 或 64 次循环。此外,模型还提供了基于下一个 token 概率分布的逐 token 自适应停止机制:如果连续两轮之间的 KL 散度低于某个阈值,也就是两个分布已经足够相似,就停止循环。
上下游
本块首次出现的来源与延伸
研究如何训练循环深度语言模型;不是 Astra 的源码或架构证据。
由论文直接链接对应 Geiping 等人的循环深度研究,可用于后续实现实验。
已核对模型入口本块新增 2 项 · 另有 3 项已在前文介绍
判断
对本块内容的判断
引文中的“不依赖架构变化”并不等于证明任何架构都绝不会影响监控。它也没有披露完整网络结构。目前可以得出的结论是:不能只凭架构传闻解释监控趋势。 初始表示与上一轮状态共同进入共享核心,是具体的结构选择。它与复用整个 Nanbeige 堆栈不同;“隐空间推理”这个名称也不意味着禁止模型生成文字思维链。 相邻两轮输出分布接近,可以作为停机信号,却不保证预测正确。不同任务的收益曲线不同;训练时如何变化轮数,也会影响推理时增加轮数是否有效。
核验与延伸:Scaling up Test-Time Compute with Latent Reasoning ↗ · Jakub Pachocki 的澄清 · 原文链接 ↗ · GPT-6 Astra 系统卡 · §9 Monitorability ↗ · Recurrent Pretraining · 官方代码与数据方案 ↗
解释
本块首次出现的知识点
KL 散度如何帮助决定何时停止循环
每轮循环都可以给出对下一个 token 的概率预测。KL 散度衡量两个分布的差异:DKL(P∥Q) = Σ P(x) log[P(x)/Q(x)]。它通常不对称,因此不是日常几何意义上的距离。
当相邻两轮的分布变化很小,继续计算也许暂时没有改变预测,于是可作为停止信号。但一个错误答案的分布也可能非常稳定。阈值决定计算成本与任务表现之间的取舍,并不能证明答案正确。论文中的自适应推理 ↗
本块新增 1 项 · 另有 4 项已在前文介绍
英文原文 21
253 词 · 1 张图The overall benefit depends on the task. In their evaluations, HellaSwag performance largely levels off after about eight loops, while GSM8K and HumanEval benefit from more.
However, while the title of the paper mentions “latent reasoning”, the model can still generate a textual chain of thought. Looping just gives it additional computation before each output token.
6.2 Knowledge retrieval vs reasoning
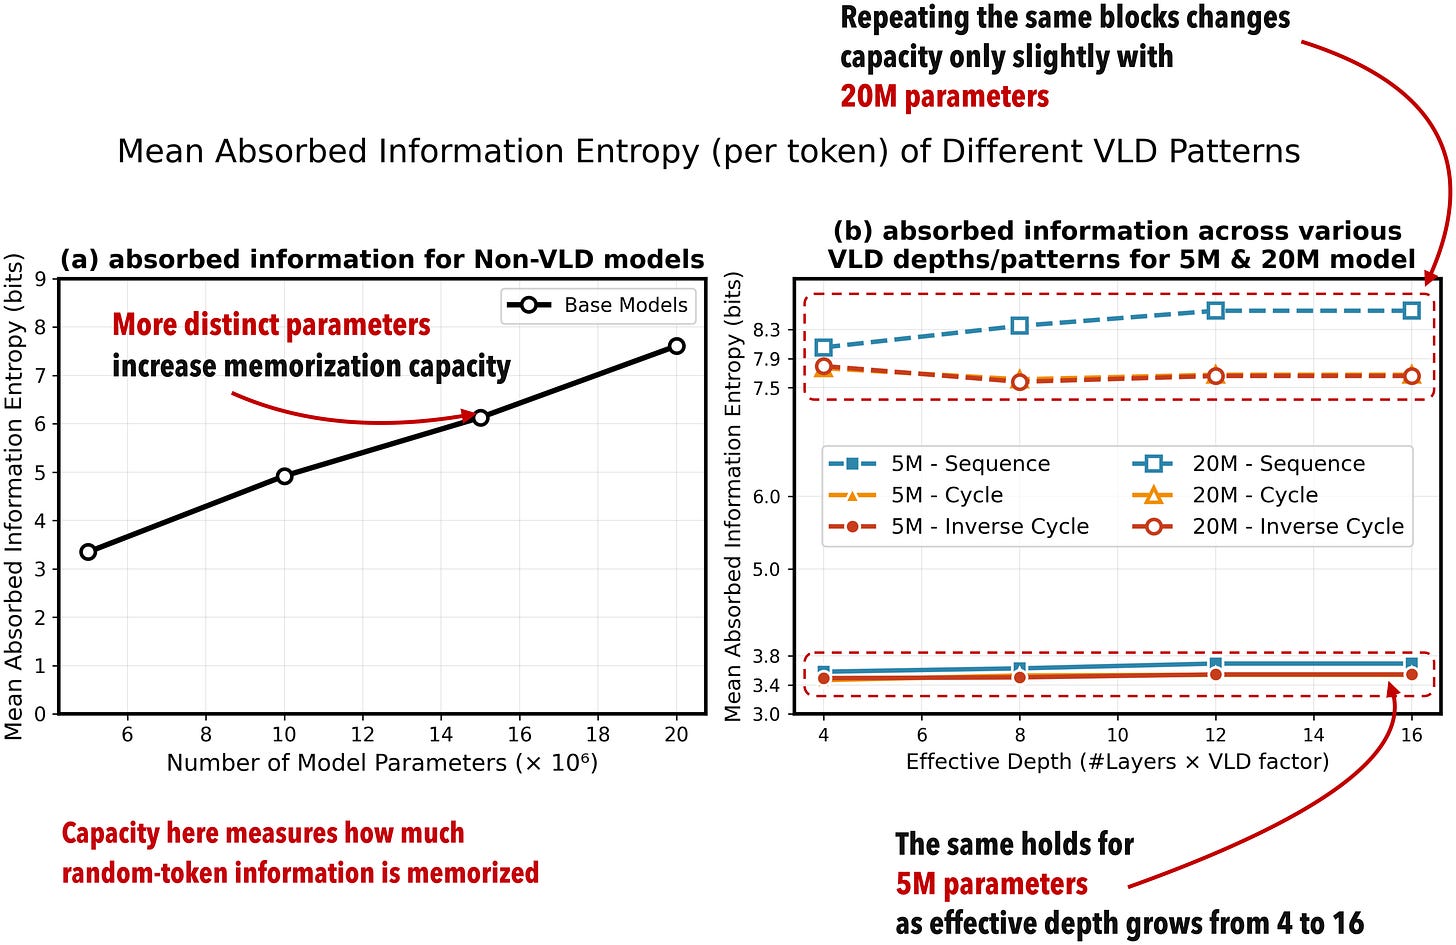
There’s a useful distinction between storing information and using it to solve a problem. For instance, the Beyond Parameters: Exploring Virtual Logic Depth for Scaling Laws paper from June 2025 investigates this by measuring memorization and reasoning in an LLM separately.
First, in the memorization experiments, looping leaves the amount of stored information nearly unchanged when the parameter count stays fixed. Increasing the number of distinct parameters does increase this capacity. From this, we can conclude that looping doesn’t add or let’s the model retrieve more knowledge. This makes sense. Information retrieval is a relatively simple task once the information is stored. Also, looping in itself is computing not “storing” mechanism.
Second, in separate reasoning experiments, reusing the blocks improves performance on multi-step math problems without adding parameters. This is interesting. Here, we can conclude that extra computation can help a model solve problems even when it doesn’t have more space to store information. But again, bigger models can also improve reasoning (although they add parameters as well).
中文译文 21
458 字总体收益取决于任务。在他们的评测中,HellaSwag 的表现大约在八次循环之后趋于稳定,而 GSM8K 和 HumanEval 则能从更多循环中获益。
不过,虽然论文标题提到“隐空间推理”,模型仍然能够生成文本形式的思维链。循环只是让它在输出每一个 token 之前,都能进行额外计算。
6.2 知识提取与推理
存储信息和利用信息解决问题是两回事,值得分别考察。例如,2025 年 6 月的《Beyond Parameters: Exploring Virtual Logic Depth for Scaling Laws》通过分别测量大语言模型的记忆能力与推理能力,研究了这个问题。 [1]
首先,在记忆实验中,如果参数量保持固定,循环几乎不会改变模型存储的信息量;增加独立参数的数量,则确实会增加这种容量。据此可以得出,循环不会增加模型的知识,也不会让模型提取出更多知识。这是合理的:一旦信息已经存好,提取信息就是相对简单的任务。此外,循环本身是一种计算机制,而不是“存储”机制。
其次,在单独进行的推理实验中,复用块能够在不增加参数的情况下,提高模型解决多步骤数学问题的表现。这很有意思:它说明,即使模型没有更多的空间存储信息,额外计算也能帮助它解决问题。不过,更大的模型同样能够改善推理,只是它们也会增加参数。
上下游
本块首次出现的来源与延伸
区分实验中测得的记忆容量和推理表现,不能将小规模随机信息实验直接推广为所有知识检索。
原文链接;未将未核验内容当作新证据本块新增 1 项 · 另有 3 项已在前文介绍
判断
对本块内容的判断
相邻两轮输出分布接近,可以作为停机信号,却不保证预测正确。不同任务的收益曲线不同;训练时如何变化轮数,也会影响推理时增加轮数是否有效。 原图测的是特定记忆实验,不能把它直接等同于现实任务中的知识检索。共享参数不增加独立存储空间,但额外计算仍可能改变已有信息的组合和使用方式。
记忆容量实验不等于所有知识检索都不会受益
图 20 测的是较小模型吸收随机 token 信息的容量。它支持“该记忆测试中,增加循环对容量影响小”,但不足以证明更深的计算不会改善任何已有知识的提取、组合或访问。存储上限与把信息正确用于某个问题,是不同的测量对象。原论文 ↗ · 定位原文 ↑
核验与延伸:Beyond Parameters · Virtual Logic Depth ↗ · Scaling up Test-Time Compute with Latent Reasoning ↗ · Recurrent Pretraining · 官方代码与数据方案 ↗ · Huginn-0125 · 公开模型 ↗
解释
本块首次出现的知识点
“记得更多”与“推得更好”如何区分
记忆容量实验测量模型能吸收多少给定信息;推理测试则测量它能否组合信息、完成多步运算。共享同一套权重反复计算,并没有直接增加可存储的独立参数,却可能帮助模型更有效地利用这些参数。
图 20 的信息熵单位是 bit,测量的是特定随机 token 任务。它不能自动等同于日常常识覆盖、检索准确率或事实可靠性。由具体基准推到一般认知概念时,需要明确中间的假设。实验范围 ↗
本块新增 1 项 · 另有 3 项已在前文介绍
英文原文 22
257 词 · 1 张图6.3 Looping at a matched compute budget
The just-released SMELT: Scaling Laws for Compute-Matched MoE Looped Transformers paper from September 2026 comes back to the cost comparison from section 2.2. What happens if we compare looped and conventional transformers with approximately the same compute per token, total non-embedding parameters, and KV cache requirements?
The researchers use a mixture-of-experts architecture and apply the middle half of the transformer blocks twice, kind of similar to Nanbeige except with the sandwiching in Latent Reasoning.
However, they narrow the hidden dimension to compensate for the compute needed for the extra block applications. And then, because that makes the parameter count smaller, they then add experts to recover the total parameter count. They also adjust the attention head configuration to keep the KV cache comparable.
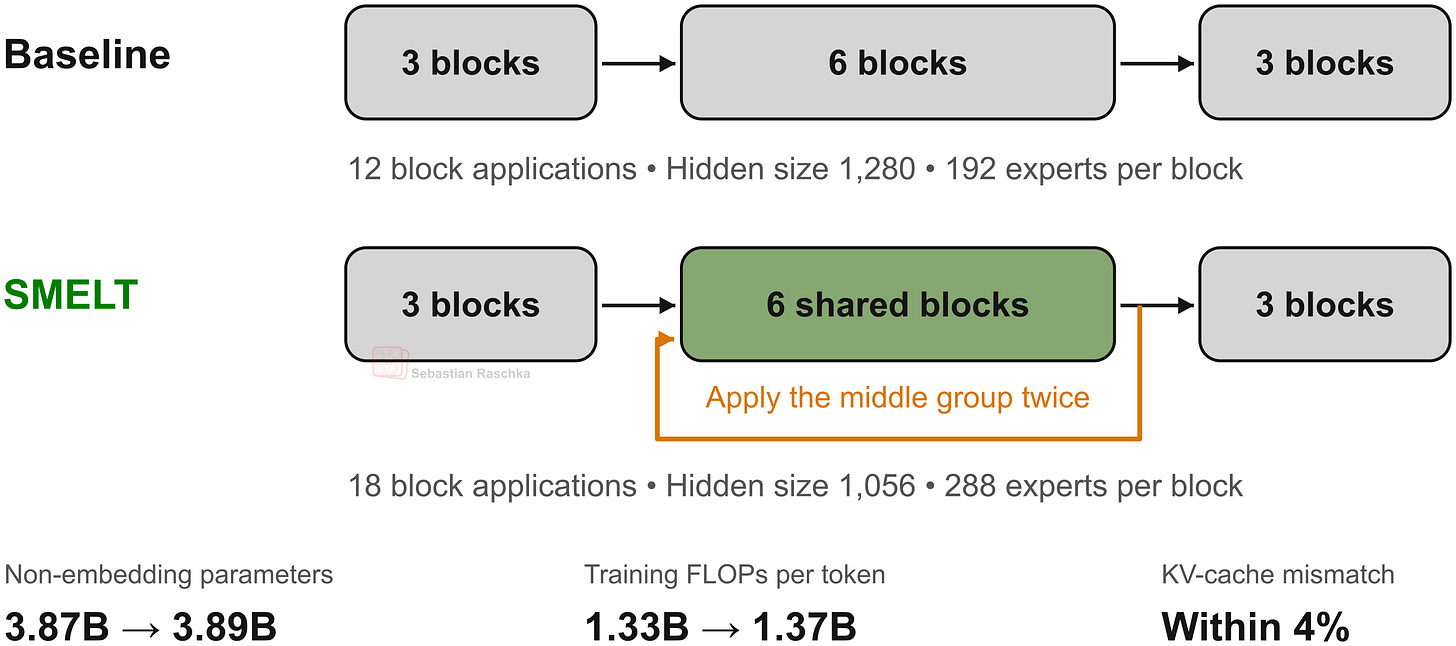
The experiments scale up to 54B non-embedding parameters and so on. Then, from fitted scaling curves, the researchers estimate that SMELT requires about 6.8-18% less training compute to reach the same validation loss within the studied compute range.
So, this answers the question of whether looped transformers are worth it computationally: Yes! They give us a slightly better model when using the same compute budget.
6.4 Full-bandwidth transformer
Finally, the also very recent Full-bandwidth transformer paper from August 2026 studies recurrence across token positions. At each decoding step, it combines the previous token’s final hidden state with the newly sampled token’s embedding through a learned gate. This becomes the input for the next forward pass.
中文译文 22
444 字6.3 在相同计算预算下比较循环方案
2026 年 9 月刚发表的《SMELT: Scaling Laws for Compute-Matched MoE Looped Transformers》,重新讨论了第 2.2 节的成本比较问题:如果让循环 Transformer 和常规 Transformer 的每 token 计算量、非嵌入总参数量以及 KV 缓存需求都大致相同,会发生什么? [1]
研究人员采用混合专家架构,让位于中间的一半 Transformer 块运行两遍。这与 Nanbeige 有些相似,只是又采用了隐空间推理模型那种前后夹着独立块的结构。
不过,他们通过缩小隐藏维度,抵消额外执行这些块所增加的计算量。由于这会减少参数量,他们随后增加专家数量,使总参数量恢复到原来的规模。他们还调整了注意力头的配置,以保持 KV 缓存需求可比。
实验所用模型的非嵌入参数量最高达到 54B。随后,研究人员根据拟合的扩展曲线估计,在所研究的计算量范围内,SMELT 达到相同验证损失所需的训练计算量,大约减少了 6.8%—18%。
因此,这回答了循环 Transformer 在计算上是否值得采用的问题:值得!在相同计算预算下,它们能让模型表现略有提升。
6.4 全带宽 Transformer
最后,2026 年 8 月发表的另一篇近期论文《Full-bandwidth transformer》,研究了跨 token 位置的循环。在每一步解码时,它通过一个可学习的门,把前一个 token 的最终隐藏状态与新采样 token 的嵌入组合起来,作为下一次前向传播的输入。 [1]
上下游
本块首次出现的来源与延伸
跨 token 传递隐藏表示;基础模型、指令微调和反馈方式需要分别比较。
原文链接;未将未核验内容当作新证据本块新增 1 项 · 另有 2 项已在前文介绍
判断
对本块内容的判断
图中的参数、每 token FLOPs 和 KV 缓存是近似匹配。观察到的收益属于缩窄隐藏维度、增加专家与循环策略的整体设计方案,且节省比例来自指定范围内的拟合。 本块从一般循环收益转到跨 token 的隐状态反馈。要保留基础模型、指令微调、反馈方式和长度统计量的区别,不能只看图形柱高或都含有“循环”二字。
Full-bandwidth 的跨 token 反馈,不宜等同于固定深度循环
这里把上一个 token 的最终隐藏表示传给下一个 token,而前面 Nanbeige 的重点是同一位置跨深度复用层。它们都传递隐藏状态,但循环轴不同。原图 22 的长度是中位数,纵轴也未从零开始;应依据数值和基础模型设置读图,不能仅凭柱高推断巨大节省,更不能把链变短直接当作更忠实或更不忠实。论文与图 6 ↗ · 定位原文 ↑
核验与延伸:SMELT · Compute-Matched MoE Looped Transformers ↗ · Full-bandwidth transformer ↗ · Mixture-of-Recursions · NeurIPS 2025 ↗
解释
本块首次出现的知识点
MoE 如何帮助 SMELT 同时匹配三种预算
混合专家模型保存多个专家,但每个 token 只选择其中一部分执行。因此,总参数量可以与单 token 的计算量部分解耦。SMELT 通过缩窄隐藏维度腾出额外循环的计算预算,再增加专家数量,将总参数量恢复到原来的规模,并调整注意力配置以匹配 KV 缓存。
这项比较同时涉及多项设计调整,不能把结果简化成“随便给模型加一个循环就省算力”。论文通过拟合,估计达到相同验证损失所需的计算量,再据此计算节省幅度,还应关注区间、误差和外推标记。设计与缩放律 ↗
本块新增 1 项 · 另有 3 项已在前文介绍
英文原文 23
261 词 · 1 张图So, the next token’s computation has access to the previous token’s final representation from the bottom of the stack, which is somewhat similar to Latent Reasoning.
When using a 1B base model, they found that their latent feedback approach outputs shorter reasoning traces on MATH500 while maintaining or improving accuracy. However, the shortening effect disappears after instruction tuning.
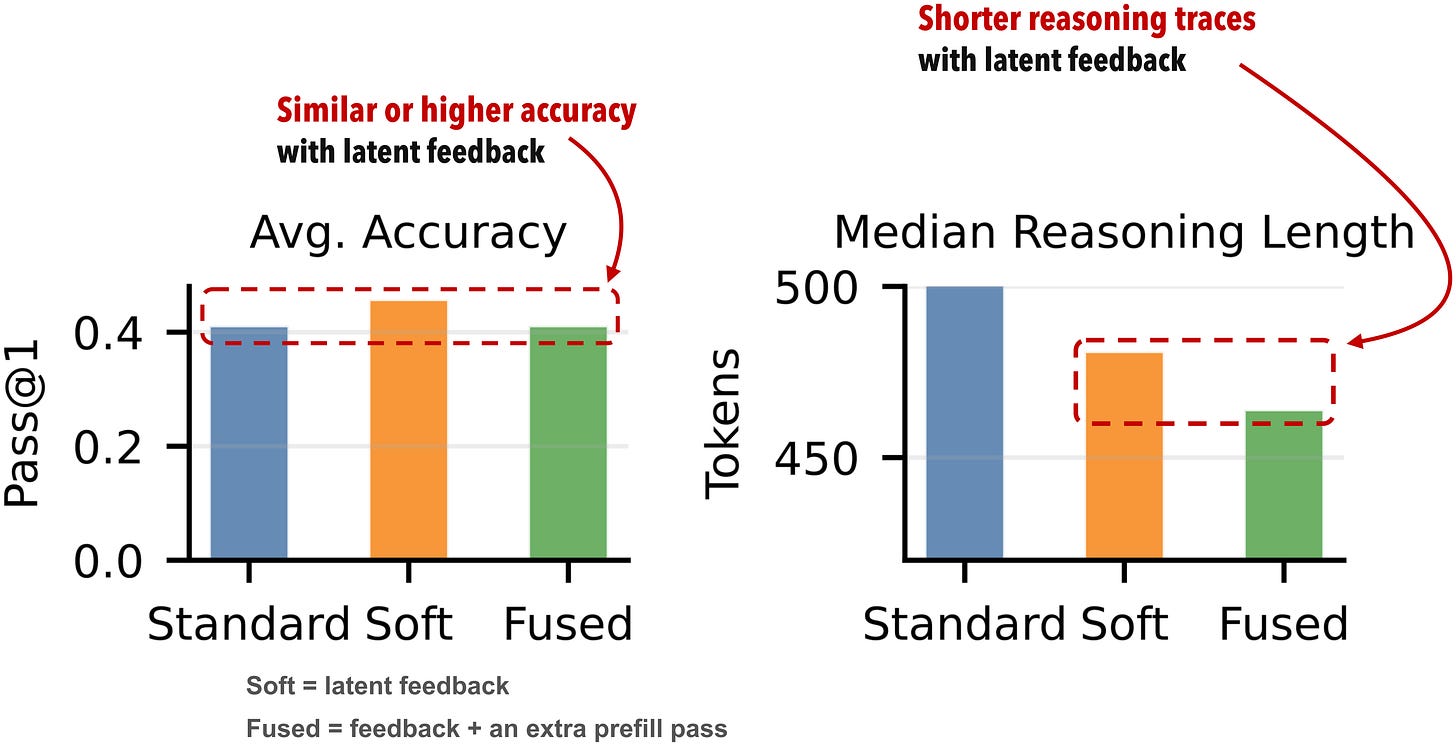
Anyway, this is interesting because this connects directly to the earlier discussion about whether looping results in shorter reasoning traces. The result depends on both the feedback mechanism and how the model is trained, of course. Also, the experiment doesn’t establish whether those shorter traces are less faithful.
Also, the big caveat of the study is that they didn’t test whether increasing the size of the model in conventional ways (adding more transformer blocks instead of looping) has a similar effect on the reasoning trace lengths.
Conclusion
To wrap it all up, we can say that yes, OpenAI GPT-6 Astra is a very strong model. And it’s making a particularly large leap in computer use. I believe computer use will be the next big focus area for open-source and proprietary harnesses in the upcoming months. I find open-source especially important when it comes to computer use, as “with great power come great responsibilities”, and it’s nice to be able to audit the harness before giving it access to my main computer.
中文译文 23
441 字因此,计算下一个 token 时,从堆栈的第一层起就能利用前一个 token 的最终表示。这与隐空间推理模型有些相似。
在使用 1B 基础模型时,研究人员发现,他们的隐状态反馈方法能让模型在 MATH500 上输出更短的推理轨迹,同时保持或提高准确率。不过,经过指令微调后,这种缩短效果就消失了。
无论如何,这项结果很有意思,因为它直接回应了前面讨论的问题:“循环是否会导致推理轨迹变短”。显然,结果同时取决于反馈机制和模型的训练方式。此外,这项实验也没有证明那些较短的推理轨迹是否更不忠实。
这项研究还有一个重要限制:他们没有测试,采用常规方式增大模型,例如增加 Transformer 块而不是循环,是否会对推理轨迹长度产生相似影响。
结论
总结来看,OpenAI 的 GPT-6 Astra 确实是一个很强的模型,尤其在计算机操作方面取得了很大的进步。我认为,在未来几个月,计算机操作将成为开源和专有运行框架的下一个重点。我觉得开源在计算机操作场景中特别重要,因为“能力越大,责任越大”:在让框架访问我的日常工作电脑之前,最好能先审查它的工作方式。
上下游
本块首次出现的来源与延伸
保留原文提供的资源地址,供查看对应材料和上下文。
原文链接;未将未核验内容当作新证据本块新增 1 项 · 另有 4 项已在前文介绍
判断
对本块内容的判断
本块从一般循环收益转到跨 token 的隐状态反馈。要保留基础模型、指令微调、反馈方式和长度统计量的区别,不能只看图形柱高或都含有“循环”二字。 缺少“增加常规层”的匹配对照,会限制对反馈机制独特效果的归因。结尾关于计算机操作与开源的判断是作者的展望和价值选择,不应当作已经完成的对照实验。
核验与延伸:Full-bandwidth transformer ↗ · CC BY 4.0 ↗ · SMELT · Compute-Matched MoE Looped Transformers ↗ · GPT-6 Astra 官方发布说明 ↗
解释
本块首次出现的知识点
本块相关内容已在前文介绍
英文原文 24
262 词 · 1 张图Besides, GPT-6 Astra is likely to use a variant of the looped transformer. Looped transformers simply give better modeling performance at a fixed compute budget.
Also, better modeling performance may decrease in shorter reasoning chains. But this is not a new trend. We have always seen that within a model family with models of different sizes (e.g., GPT 5.6 Luna versus Sol).
In my opinion, shorter reasoning traces are a side effect of more “intelligent” or capable models that make fewer mistakes and can access more compute internally inside their architecture versus using a reasoning trace as a scratchpad. In a sense, the same is true for humans. During an in-person college math exam, a smart and well-prepared student likely requires less use of the notepaper and needs to backtrack less often, and so on.
Thanks for reading and supporting my work!
If you’d like to learn how to build reasoning models yourself, check out my book Build a Reasoning Model (From Scratch). We start with a pre-trained LLM and add reasoning capabilities step by step, with code you can run and experiment with. It’s both fun and rewarding, and a good investment in future-self to build the fundamentals to keep up with the AI field.
Also, if you’ve read one of my books, I’d appreciate a short, honest review on Amazon. Reviews help other readers decide whether a book is right for them and are a simple way to support authors.
中文译文 24
451 字此外,GPT-6 Astra 很可能采用了循环 Transformer 的某种变体。循环 Transformer 在固定计算预算下,确实能带来更好的模型表现。
另外,更好的模型表现也可能伴随着更短的推理链。不过,这并不是什么新趋势:在同一模型家族中,不同规模的模型之间一直能看到这种现象,例如 GPT 5.6 Luna 与 Sol。
在我看来,更短的推理轨迹是模型变得更“聪明”、能力更强后自然伴随的结果:模型犯错更少,也能在模型内部完成更多计算,而不是依靠把推理轨迹当作草稿纸。从某种意义上说,人也是如此。在大学数学的线下考试中,一个聪明且准备充分的学生,大概不需要用那么多草稿纸,也不需要那么频繁地回过头来修改先前的尝试。
感谢阅读,也感谢你对我工作的支持!
如果你想学习如何亲手构建推理模型,可以看看我的书《Build a Reasoning Model (From Scratch)》。我们从一个预训练大语言模型出发,逐步为它加入推理能力,并提供可供运行和试验的代码。这既有趣,也很有成就感;学好基础有助于跟上 AI 领域的发展,也能让自己长远受益。 [1]
另外,如果你读过我的任何一本书,我会很感激你在 Amazon 留下一则简短、诚实的评价。书评能帮助其他读者判断一本书是否适合自己,也是支持作者的一种简单方式。
上下游
本块首次出现的来源与延伸
对应原文推荐的书籍,用代码连接推理时扩展、训练与评估。
已核对作者仓库本块新增 1 项 · 另有 4 项已在前文介绍
判断
对本块内容的判断
更强模型、更多内部计算和更短轨迹之间可能有关联,但人的考试类比不构成机制证据。这里关于 Astra 架构和循环普遍优势的表述仍需保留前文的条件。 这一块是作者的学习资源与书籍推荐,不是新的性能证据。学习推理时扩展、蒸馏和强化学习时,应分别确认哪些方法改变了参数、哪些增加了运行计算。
核验与延伸:Build a Reasoning Model (From Scratch) ↗ · SMELT · Compute-Matched MoE Looped Transformers ↗ · Mixture-of-Recursions · NeurIPS 2025 ↗ · GPT-6 Astra 系统卡 · §9 Monitorability ↗
解释
本块首次出现的知识点
蒸馏与推理时扩展
知识蒸馏通常利用较强模型给出的答案或推理样例来训练另一个模型,属于训练阶段的变化。推理时扩展是在模型运行时投入更多计算,例如多生成步骤、尝试多个答案或增加循环。强化学习则依据奖励调整模型;三者可以组合,但不应混为同一种成本。
本块新增 1 项 · 另有 3 项已在前文介绍
分块与版本说明
按中文译文约 400 字分块,常规范围为 300–500 字,优先在章节和完整段落之间结束。中英文同步分块;完整代码、表格等结构不拆开,无法避免的超长或短块在分块记录中注明原因。
原文采用你提供的本地文件,文字与 24 张图片保真;完整译文对应原文、列表、引文、图注和文末介绍。判断按原文块补充;同一资料与知识点只在首次涉及的块中展开,也可从右侧汇总栏查阅并返回首次出现的位置。图内说明是编辑补充,图片内英文和作者水印仍保留。
原文件中的两处视频只有占位,未包含视频文件;占位保持原样,视频可在在线原文查看。图片与文字内嵌,离线可读,外部资料链接需要联网。
资料核对日期:2026 年 9 月 10 日。原文中的已发现错误保留,在对应块的“判断”中说明;文中的建议只作为原作者内容处理。