Controlling Reasoning Effort in LLMs
控制大语言模型的推理强度
6,507 个英文词 · 26 个原文块 · 35 张保存图片 · 原文与完整中文译文对照 · 原图保留
总结
同一个模型怎样按需花更多时间推理?本文从奖励训练、思考模式开关讲到强度条件、硬预算和专家蒸馏,保留完整英中对照及35张原图。
阅读重点是区分公开方法、作者推测和实测结果;模型比较中的费用、token数与任务条件不能互相替代。
- 推理强度
- RLVR
- 推断扩展
- 思考预算
- 模式融合
英文原文 01
260 词 · 2 张图It has been almost two years since OpenAI released o1, a model that popularized the idea of LLM-based reasoning models. DeepSeek-R1 followed about four months later, together with details of a reinforcement learning with verifiable rewards (RLVR) recipe to train such reasoning models.
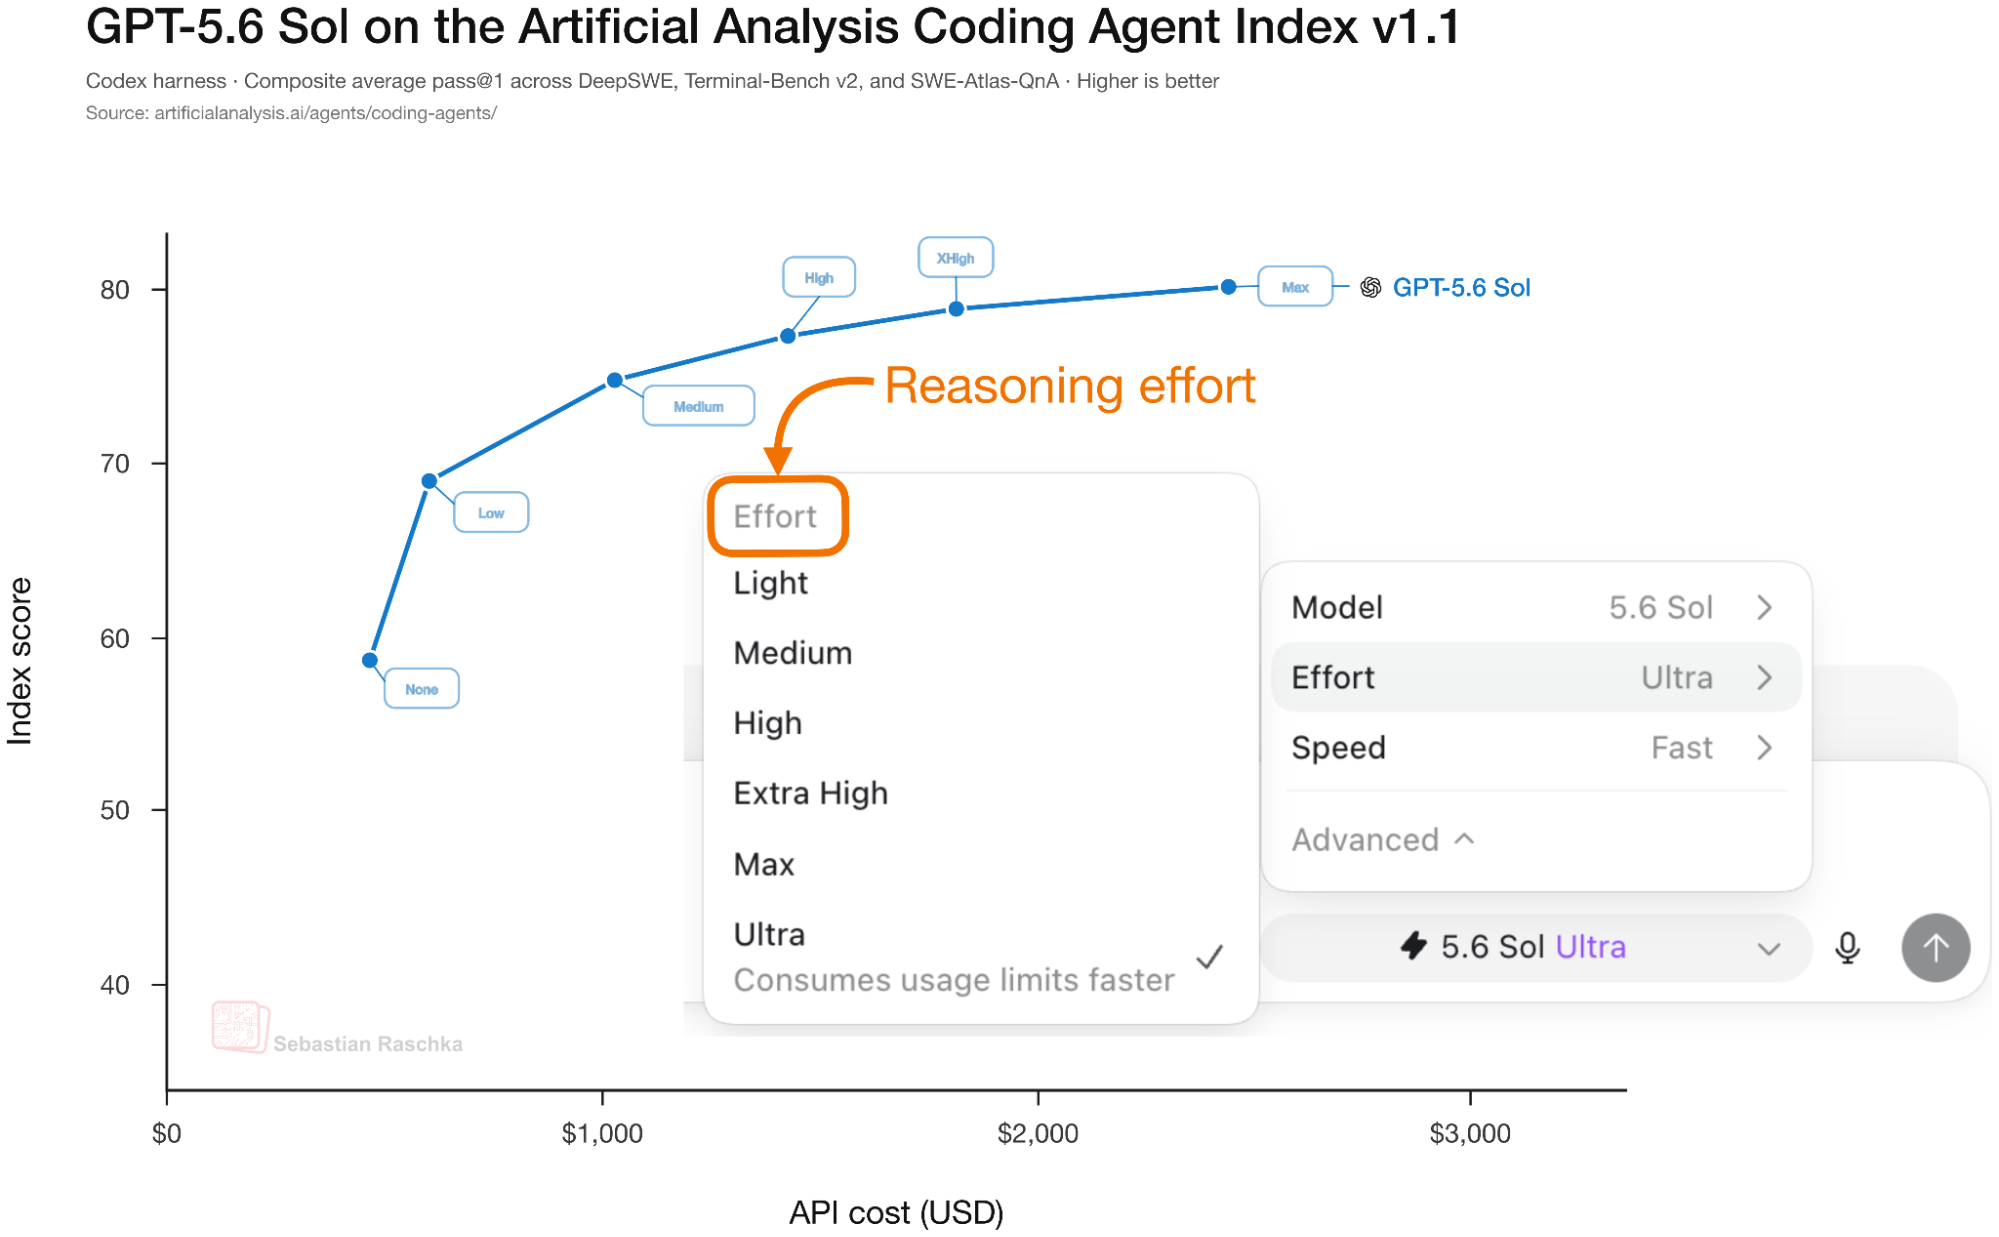
Last week, OpenAI released the GPT-5.6 model family. It comes in three sizes, each with roughly five or six reasoning-effort settings.
So yes, reasoning models are here to stay. They have become a standard part of modern model releases.
In the past, I covered the methodology of reasoning models (Understanding Reasoning LLMs) as well as relevant research papers (The State of Reinforcement Learning for LLM Reasoning and The State of LLM Reasoning Model Inference). And I even wrote a whole new 440-page book on how to develop reasoning models, Build A Reasoning Model (From Scratch).
These resources have focused on turning a conventional LLM into a reasoning model. Now, in this article, I want to focus on and explain how to develop a reasoning model that has multiple effort modes, similar to what’s shown in the figure at the beginning of this article.
No worries, this article can be read as a standalone article. However, the aforementioned resources may be interesting and useful.
中文译文 01
422 字距离 OpenAI 发布 o1 已经快两年了;这个模型让基于大语言模型的推理模型理念广为人知。约四个月后,DeepSeek-R1 随之问世,并公开了利用可验证奖励强化学习(RLVR)训练这类推理模型的具体方法。
上周,OpenAI 发布了 GPT-5.6 模型家族。它包含三种规模,每种大致提供五到六个推理强度设置。
所以,推理模型显然会长期存在。它们已经成为如今模型发布中的标准组成部分。
过去,我介绍过推理模型的方法论(《理解推理大语言模型》),也梳理过相关研究论文(《大语言模型推理强化学习现状》和《大语言模型推理模型的推断现状》)。我甚至还专门写了一本 440 页的新书,讲解如何开发推理模型:《从零构建推理模型》。 [1] [2] [3] [4]
这些资料重点讨论的是如何把传统大语言模型变成推理模型。而本文将集中讲解:怎样开发具有多种推理强度模式的推理模型,就像文章开头那张图展示的一样。
不必担心,本文可以独立阅读。不过,上述资料也可能会让你感兴趣,并对你有所帮助。
上下游
本块首次出现的来源与延伸
来源身份与原文对应;未把链接存在当作事实核验。
保留来源;未独立逐项核验来源身份与原文对应;未把链接存在当作事实核验。
保留来源;未独立逐项核验来源身份与原文对应;未把链接存在当作事实核验。
保留来源;未独立逐项核验来源身份与原文对应;未把链接存在当作事实核验。
保留来源;未独立逐项核验来源身份与原文对应;未把链接存在当作事实核验。
保留来源;未独立逐项核验按用户文件完整翻译;文中模型、日期和作者推测均保持原义。
已核对用户提供HTML、全部正文和35张图片核对GRPO目标与准确性/格式奖励,未复现实验。
已读§2.2.1–2.2.2本块新增 7 项
判断
对本块内容的判断
先区分作者的解释性示例、论文报告和本站核验;推理轨迹不等于对内部机制的完整观测。
核验与延伸:Understanding Reasoning LLMs ↗ · The State of Reinforcement Learning for LLM Reasoning ↗ · The State of LLM Reasoning Model Inference ↗ · Build A Reasoning Model (From Scratch) ↗
解释
本块首次出现的知识点
本文解释:结果奖励怎样影响推理
可以把一次回答看作一条包含中间步骤和最终答案的生成路径。验证器给出路径的奖励,策略更新调整这条路径生成的概率;不逐句评分,不意味着中间token在训练中不存在。
本块新增 1 项
英文原文 02
190 词 · 2 张图1. A brief definition of reasoning models
When talking about pretty much any machine learning or AI technique or subfield, the one lesson is that we usually shouldn’t take technical terms “literally”. For example, an (artificial) neural network in machine learning and AI doesn’t literally work like a biological neural network like the human brain.
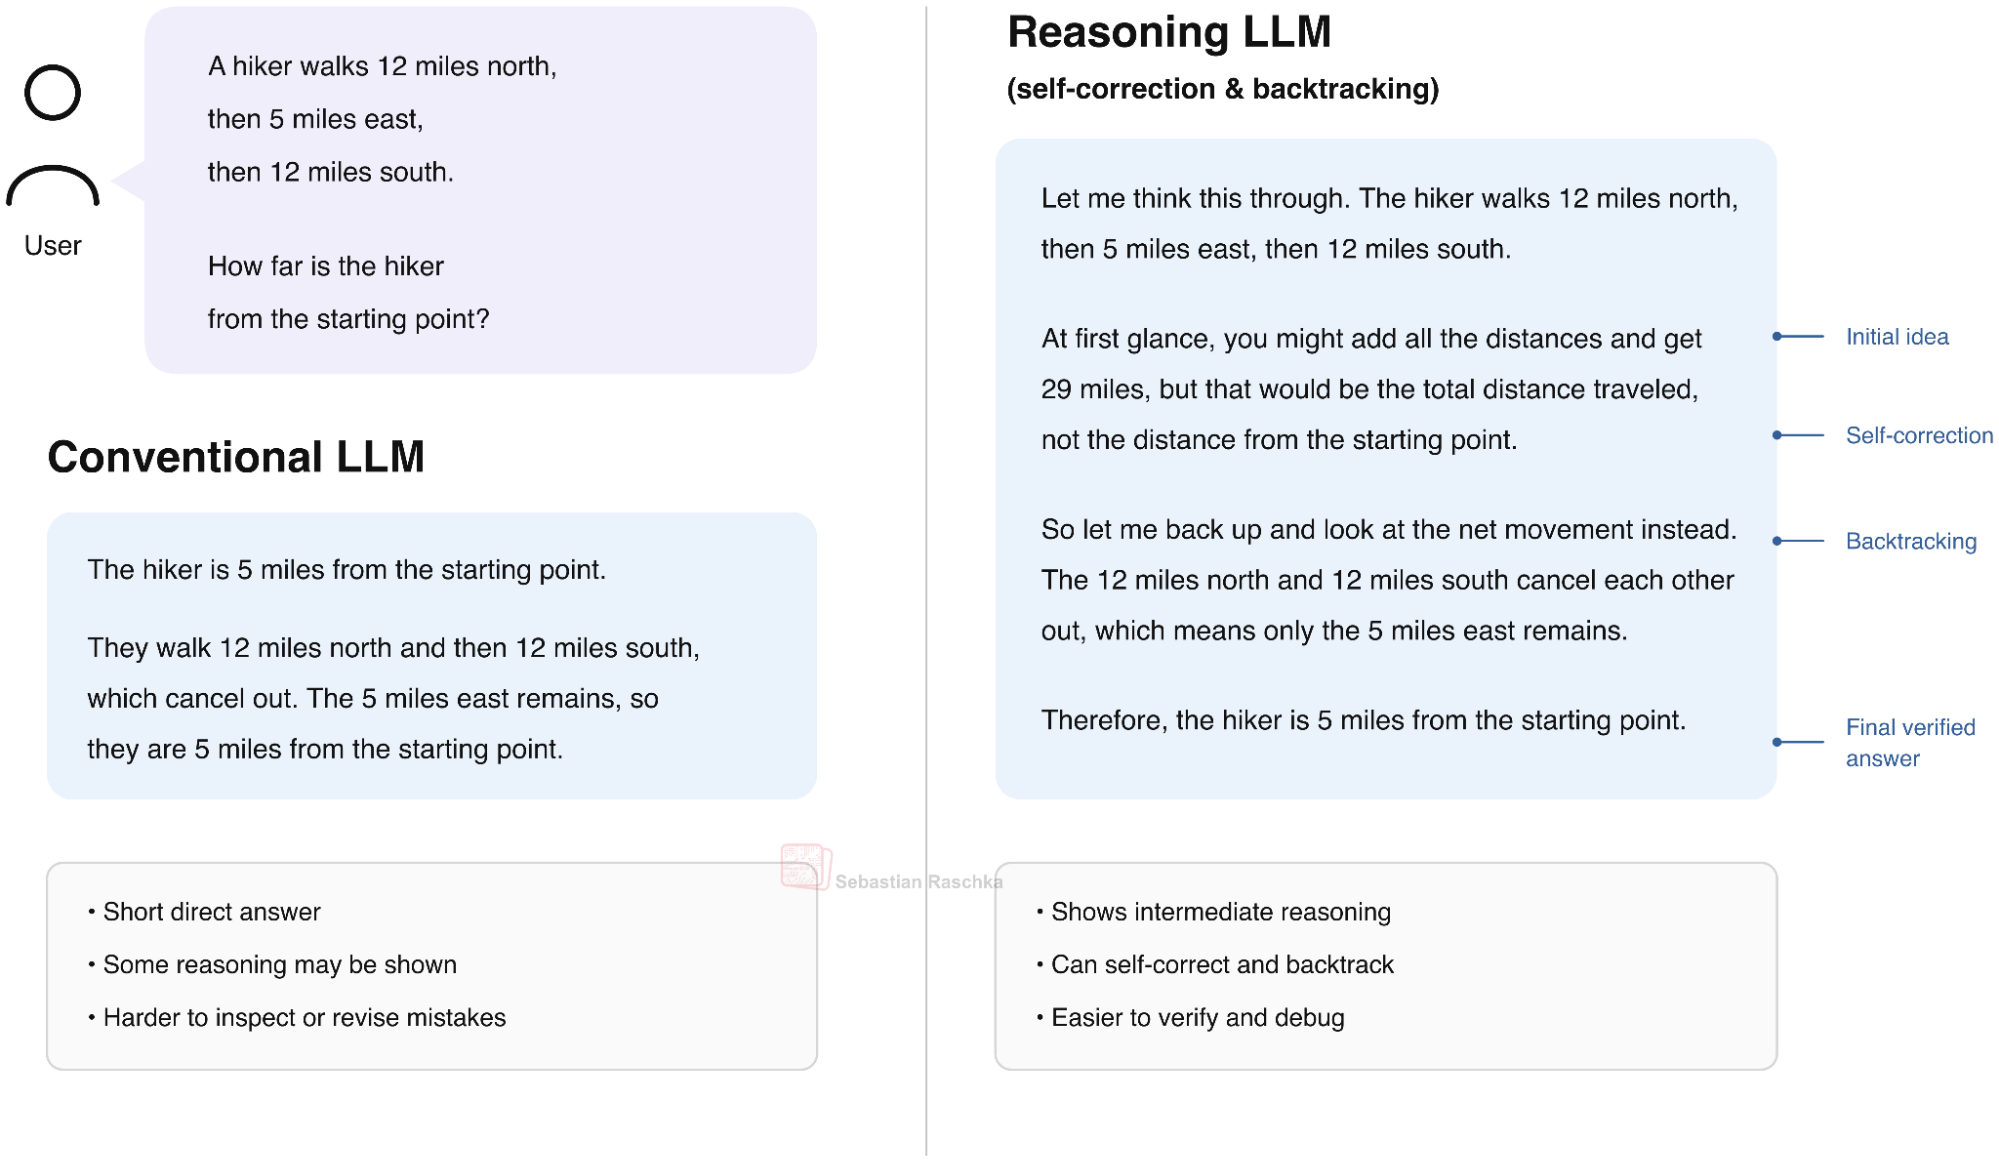
Similarly, when talking about “reasoning models”, we shouldn’t expect that these models literally reason like us humans. In the context of AI and LLM research, “reasoning model” means a model that outputs an intermediate reasoning trace, which is like an intermediate response that works through a question or task step by step.
It’s probably easiest to explain this by showing an example.
2. A brief overview of training and inference scaling reasoning models
There are essentially two ways to improve (reasoning) task performance: training scaling and inference scaling.
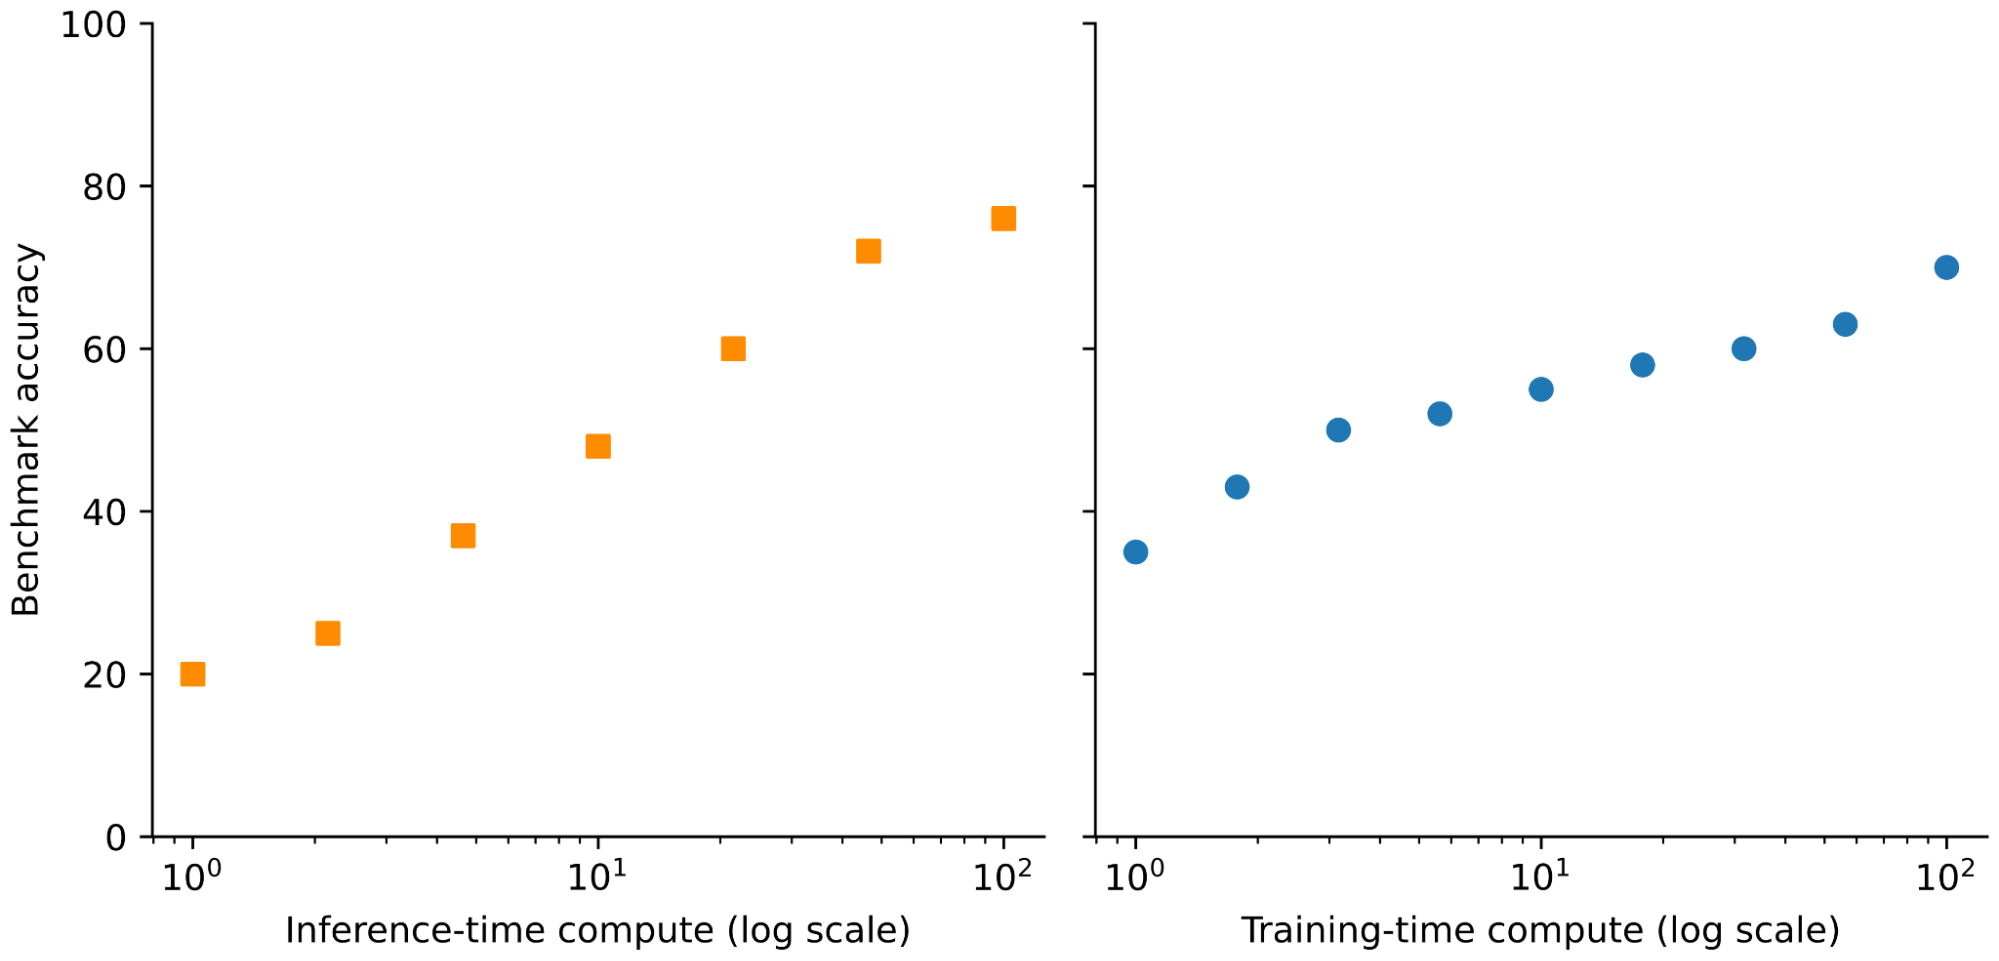
Let’s briefly talk about training first.
中文译文 02
312 字1. 推理模型的简要定义
谈论几乎任何机器学习或人工智能技术及其分支时,有一点值得记住:通常不应按字面理解技术术语。例如,机器学习和人工智能中的人工神经网络,并不真的像人脑这样的生物神经网络那样工作。
同样,谈论“推理模型”时,也不应期待它们真的像人类一样推理。在人工智能和大语言模型研究中,“推理模型”指的是会输出中间推理轨迹的模型:这相当于一段中间回答,逐步处理一个问题或任务。
举个例子,可能最容易说明这一点。
2. 推理模型的训练扩展与推断扩展概览
提高推理任务表现,基本有两条途径:扩大训练投入,以及扩大推断投入。
先简要谈谈训练。
上下游
本块首次出现的来源与延伸
来源身份与原文对应;未把链接存在当作事实核验。
保留来源;未独立逐项核验本块新增 1 项 · 另有 2 项已在前文介绍
判断
对本块内容的判断
先区分作者的解释性示例、论文报告和本站核验;推理轨迹不等于对内部机制的完整观测。
核验与延伸:Learning to reason with LLMs ↗ · Sebastian Raschka · Controlling Reasoning Effort in LLMs ↗ · DeepSeek-R1 论文 v1 ↗
解释
本块首次出现的知识点
本块相关内容已在前文介绍
英文原文 03
269 词 · 3 张图2.1 Training reasoning models
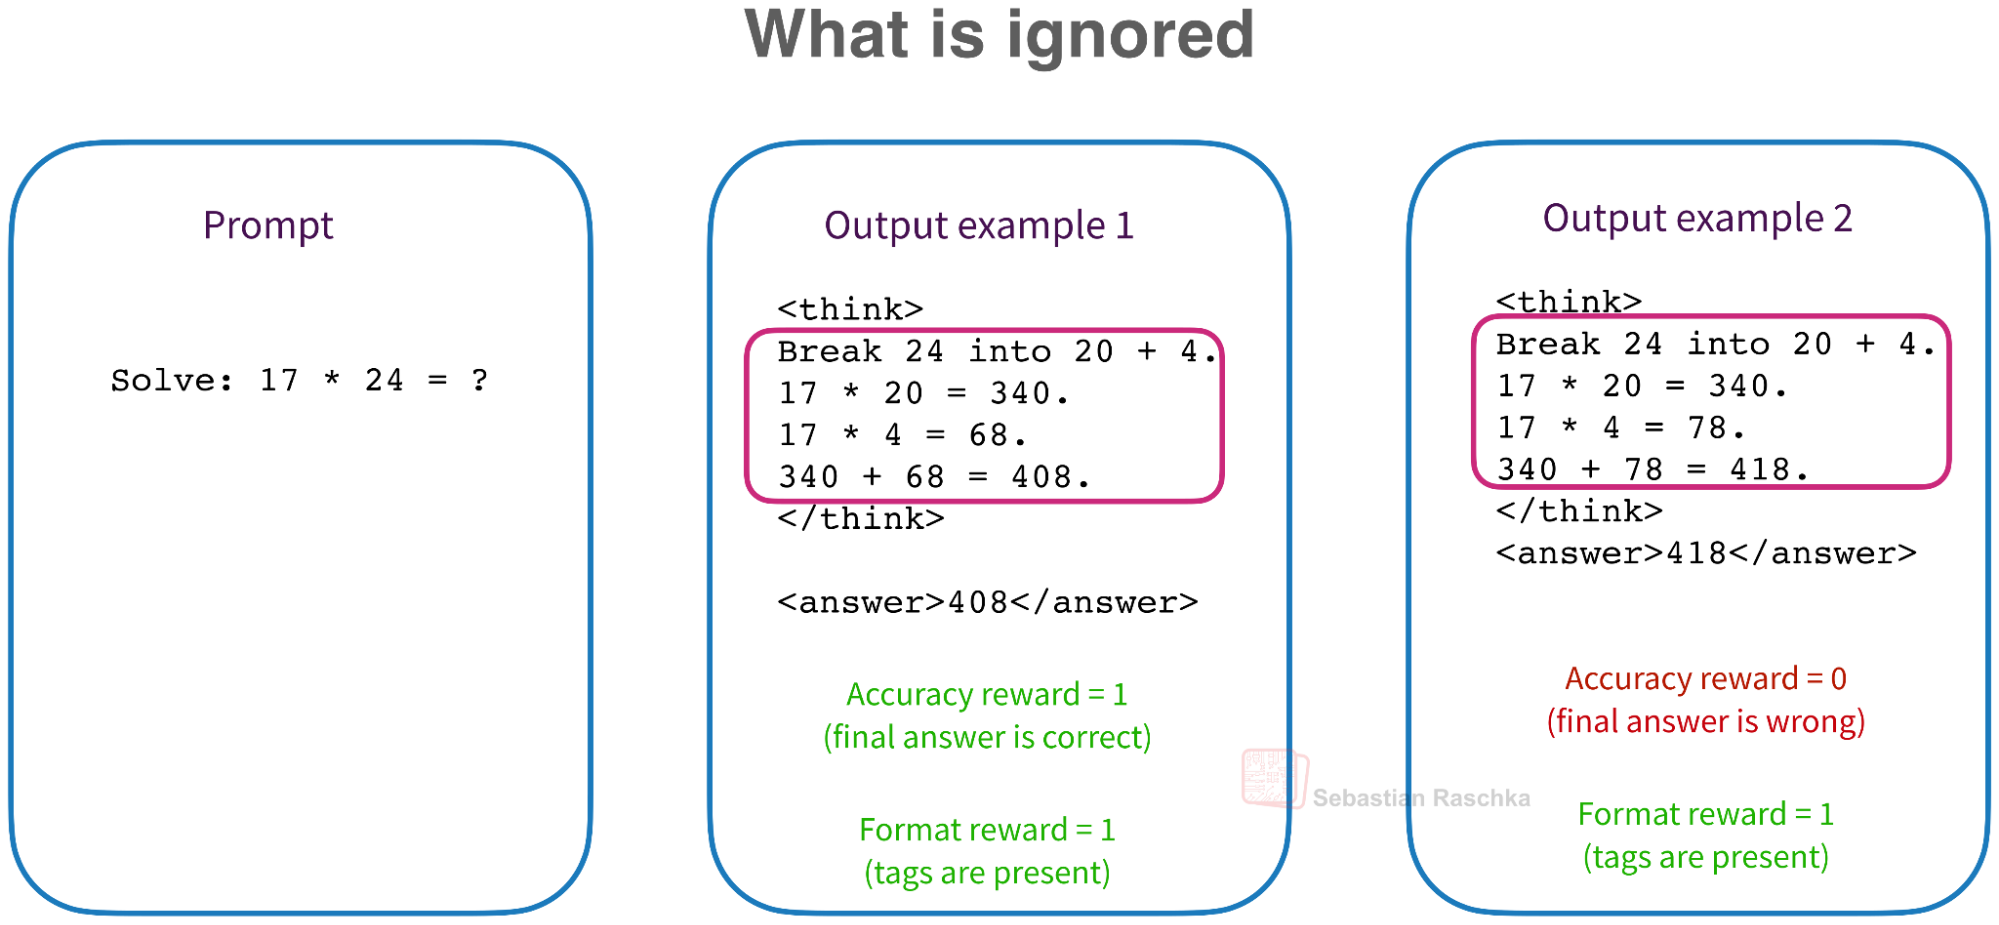
In a nutshell, DeepSeek-R1 proposed training an LLM using reinforcement learning with verifiable rewards (RLVR) to turn it into a reasoning model. RLVR is a technique to provide a reward signal (0=incorrect and 1=correct) for verifiable data domains. These verifiable data domains here are math (we can use a symbolic math checker like SymPy or WolframAlpha to check results) and code (we can use a compiler or unit tests, or integrated platforms like LeetCode) to check for correctness.
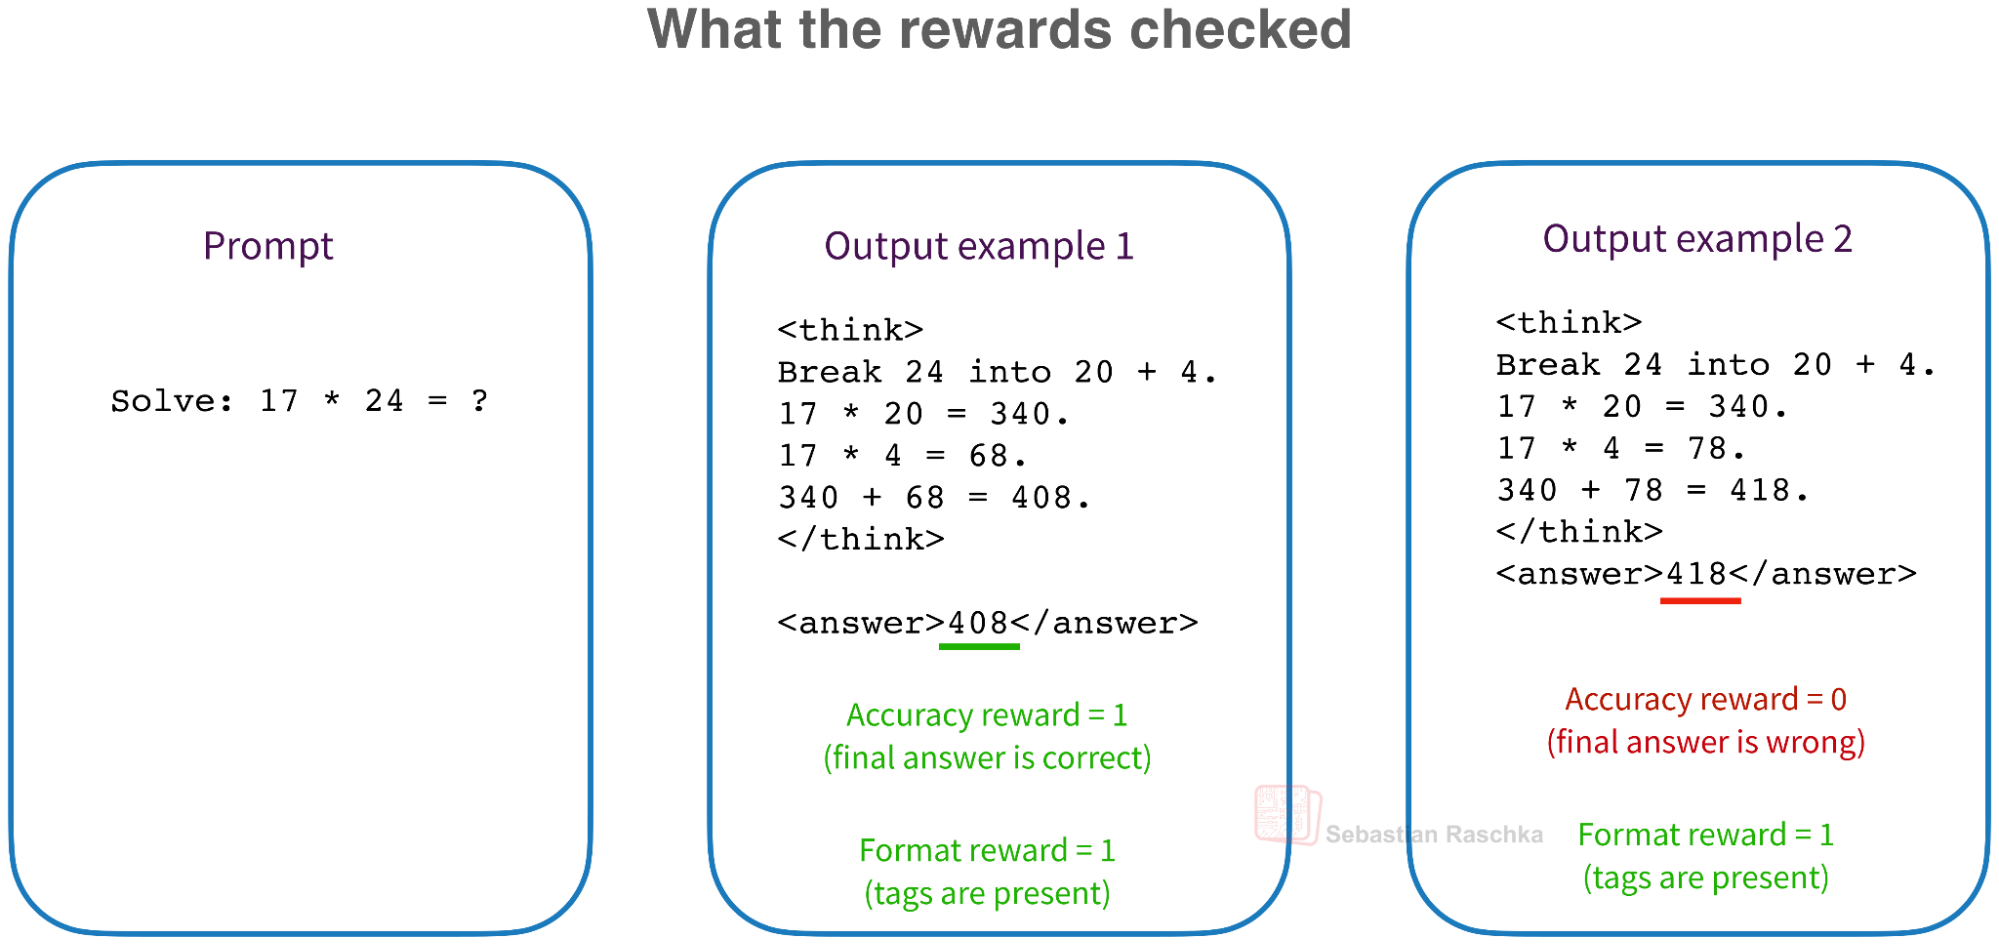
Notably, the reasoning trace itself was not used for training or updating the model. Although they tried to use this intermediate response information for training, the DeepSeek-R1 paper reported that it wasn’t helpful for the model training, so it was ultimately not used. (Whether and how to incorporate intermediate reasoning traces in the training signal via process reward models is an active area of research.)
2.2 “Aha” moments
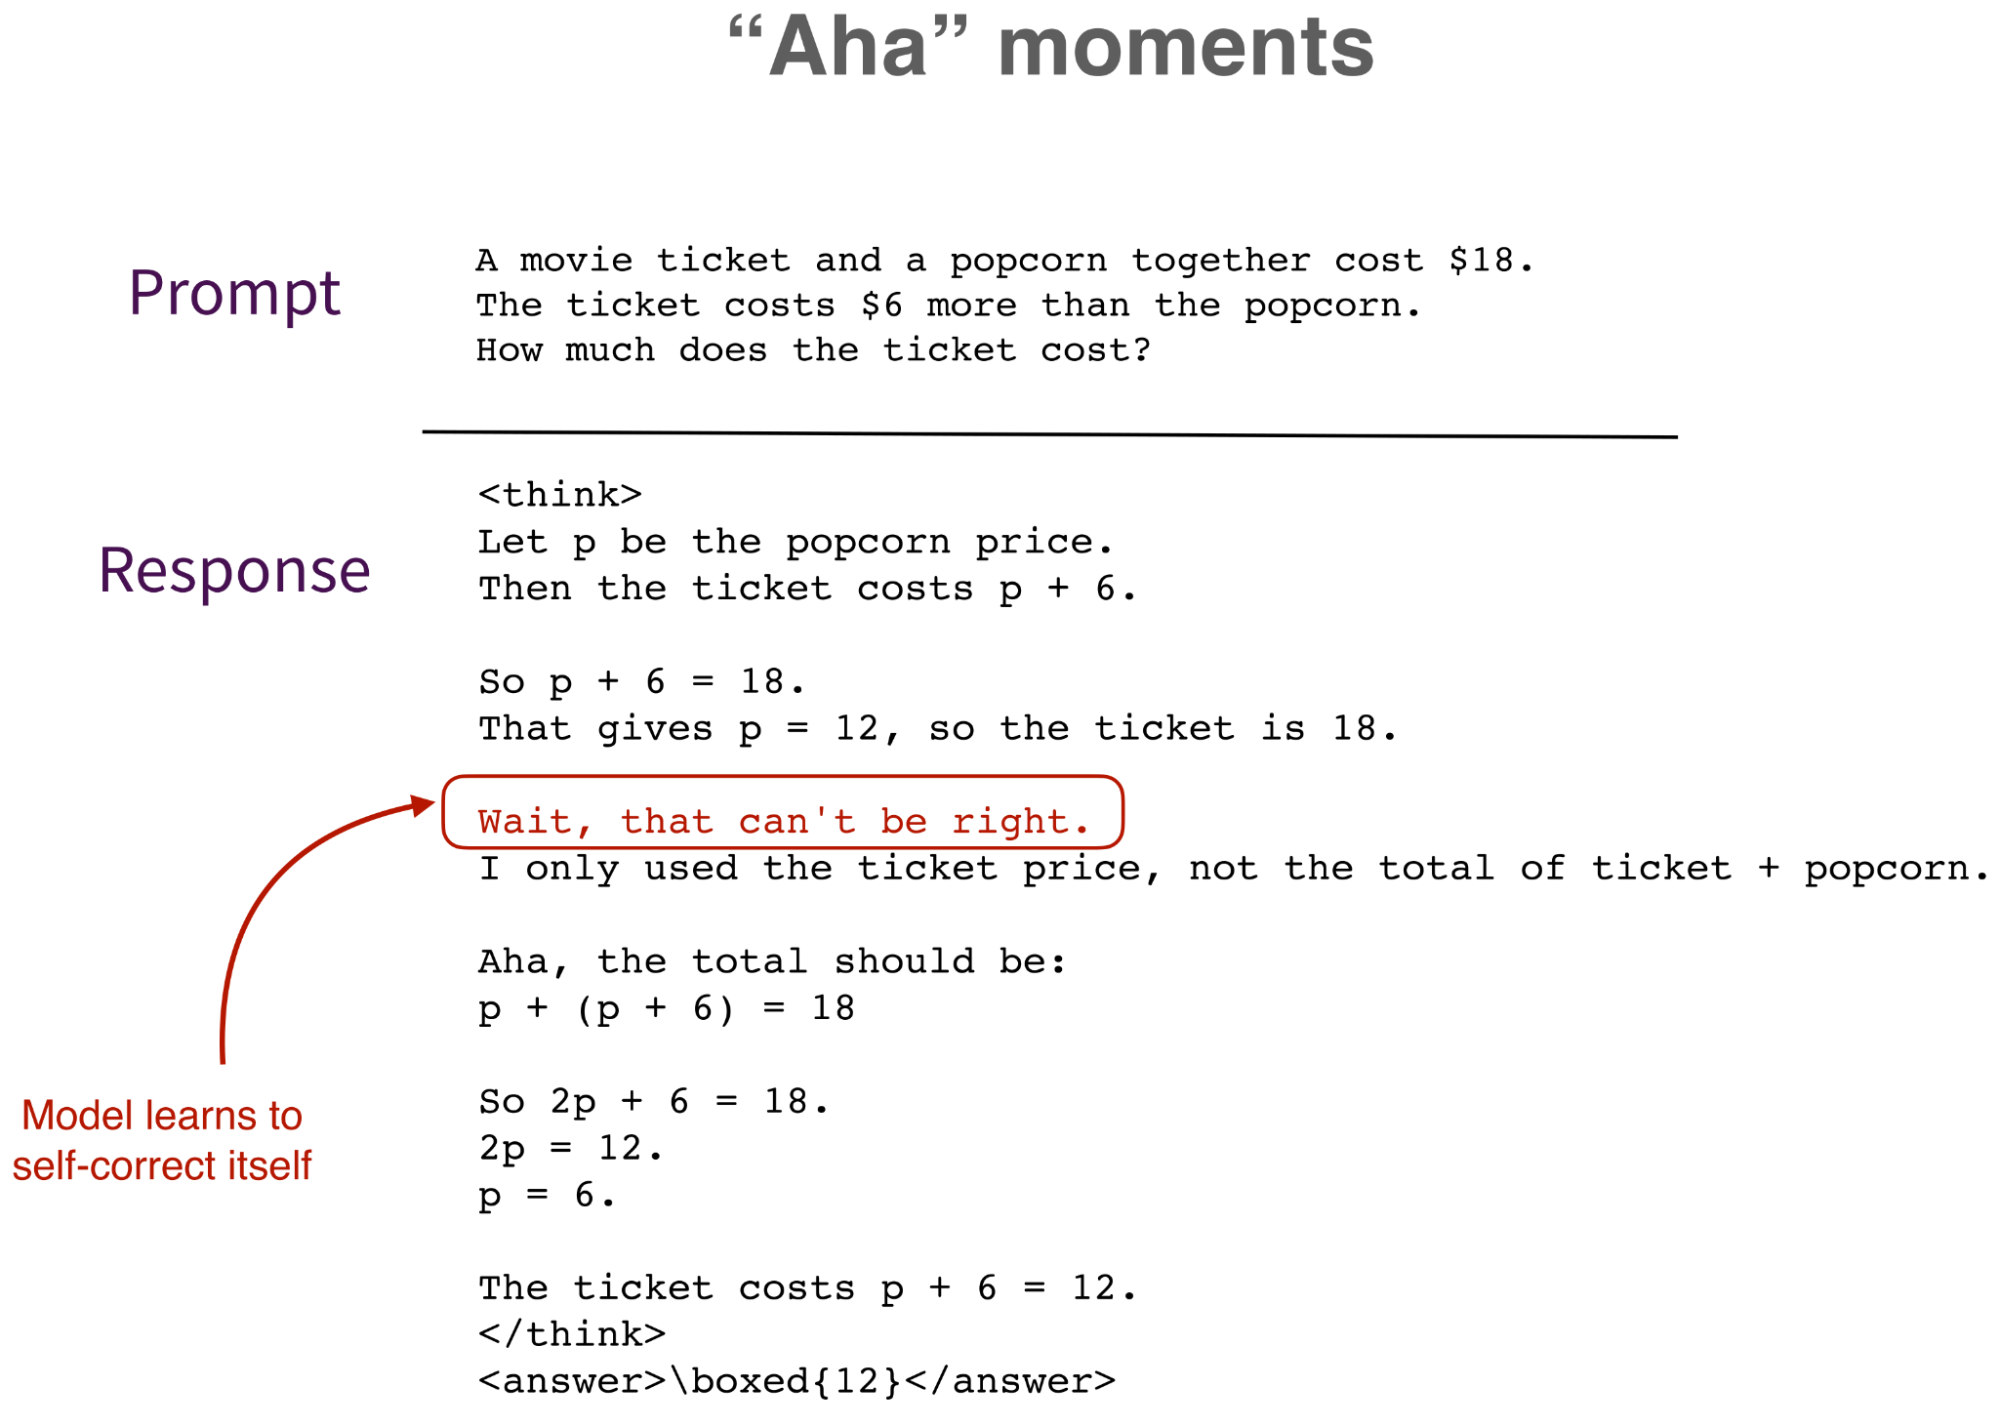
Anyway, just training on the output rewards alone, as Figure 7 shows, turned out to be sufficient for the model to learn how to reason through a problem, meaning that it would learn to write intermediate explanations, backtrack, and self-correct itself. These moments when the model realizes that it made a mistake and self-corrects itself are called “Aha” moments.
中文译文 03
405 字2.1 训练推理模型
简而言之,DeepSeek-R1 提出通过可验证奖励强化学习(RLVR)训练大语言模型,将其变成推理模型。RLVR 针对结果可验证的数据领域提供奖励信号:0 表示错误,1 表示正确。这里的可验证领域包括数学和代码:数学结果可以使用 SymPy、WolframAlpha 等符号数学工具检查;代码则可以通过编译器、单元测试,或 LeetCode 等综合平台检查正确性。 [1]
值得注意的是,推理轨迹本身并未用于训练或更新模型。虽然研究人员尝试过利用这些中间回答信息进行训练,但 DeepSeek-R1 论文报告说,这对模型训练没有帮助,因此最终没有采用。(是否以及如何通过过程奖励模型,把中间推理轨迹纳入训练信号,仍是一个活跃的研究方向。)
2.2 “顿悟”时刻
不过,正如图 7 所示,仅依据输出奖励进行训练,就足以让模型学会推导问题:它会学着写出中间解释、回溯并自我纠正。模型意识到自己犯了错误并进行修正的这些时刻,被称为“顿悟”时刻。
上下游
本块首次出现的来源与延伸
本块相关内容已在前文介绍
判断
对本块内容的判断
先区分作者的解释性示例、论文报告和本站核验;推理轨迹不等于对内部机制的完整观测。
没有过程奖励,不等于推理输出不参与训练
原文这一句容易造成误解。DeepSeek-R1-Zero用结果与格式计算奖励;GRPO仍通过生成序列的概率优化策略。不能由“没有逐步过程奖励”推出“推理轨迹完全不参与模型更新”。这里保留原文和译文,在补充层作范围澄清。 论文§2.2.1–2.2.2。
核验与延伸:DeepSeek-R1 论文 v1 ↗ · Sebastian Raschka · Controlling Reasoning Effort in LLMs ↗
解释
本块首次出现的知识点
本块相关内容已在前文介绍
英文原文 04
298 词 · 2 张图By the way, while DeepSeek-R1 is inarguably the more popular paper, and the paper that created excitement around reinforcement learning with verifiable rewards and the development of reasoning models, there is another paper, Kimi K1.5, published on exactly the same day on arXiv (22 Jan 2025). Also, the term RLVR was already coined two months earlier in Tülu 3: Pushing Frontiers in Open Language Model Post-Training.
One reason why the DeepSeek R1 is ultimately the more popular paper is that it demonstrated that reasoning behavior can be achieved with pure reinforcement learning (RL).
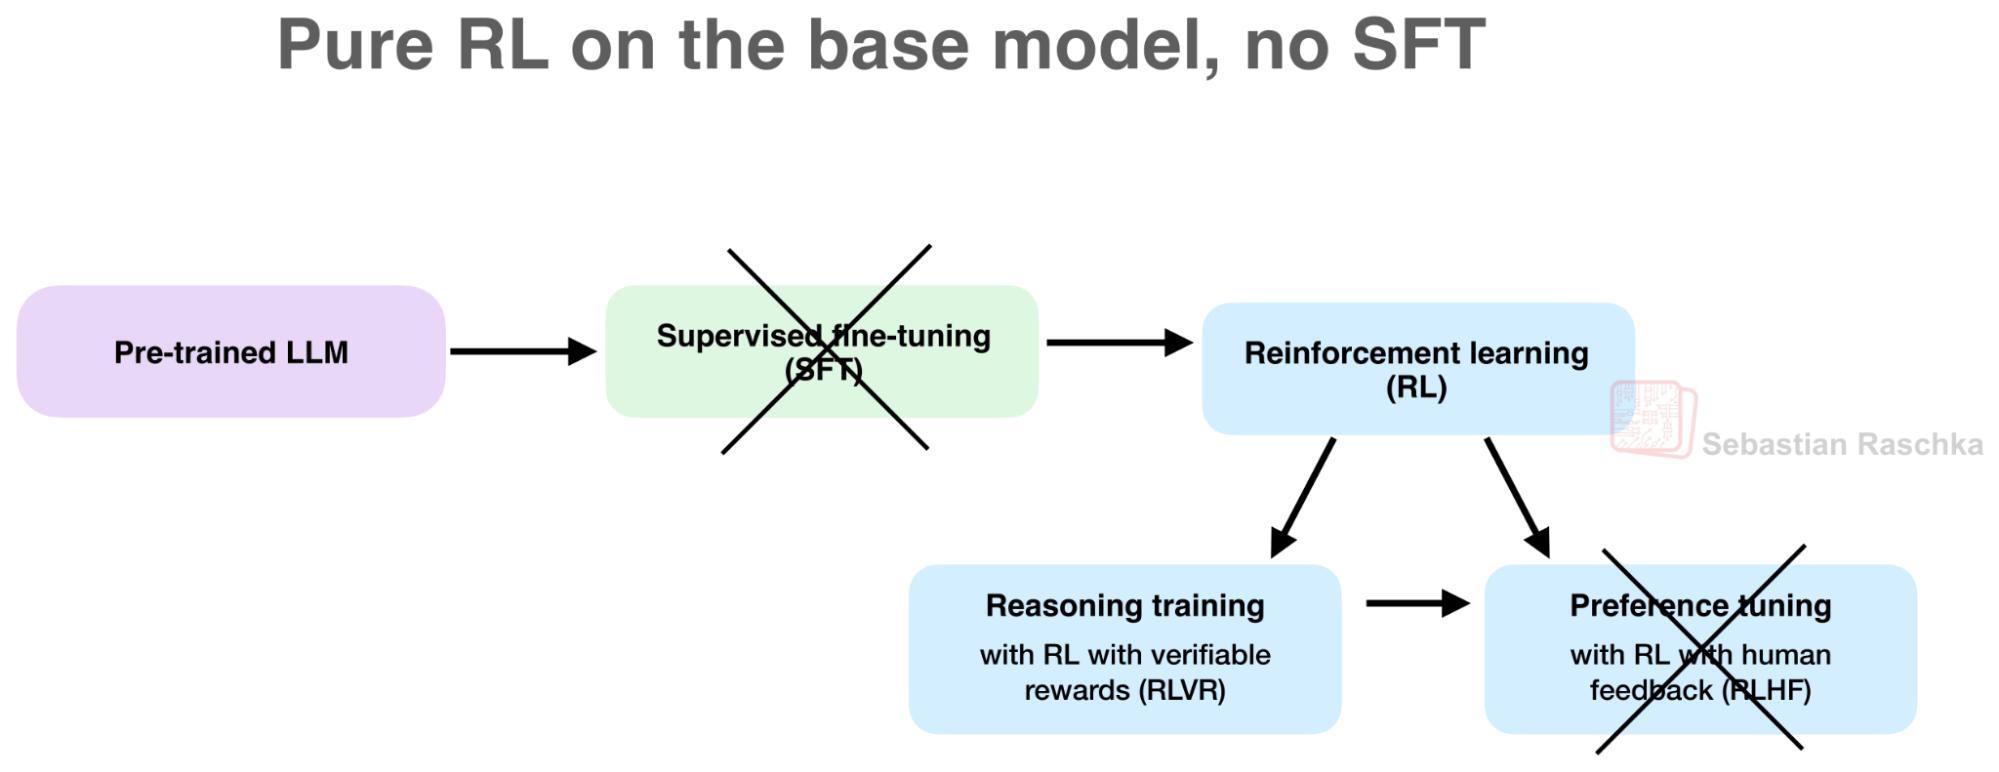
For instance, Tülu 3 and Kimi K1.5 applied reinforcement learning on top of a supervised fine-tuned (SFT) model. The DeepSeek-R1 model was also trained from an SFT checkpoint of the DeepSeek-V3 base model, and it included a DeepSeek-R1-Zero variant trained with pure RLVR. R1 Zero is a weaker model than R1, but it showed that RLVR is sufficient for teaching the model to generate and use reasoning traces.
While R1-Zero was more of a proof-of-concept model, note that the full DeepSeek-R1 reasoning model training pipeline is usually multi-stage and a bit more complicated, as mentioned above.
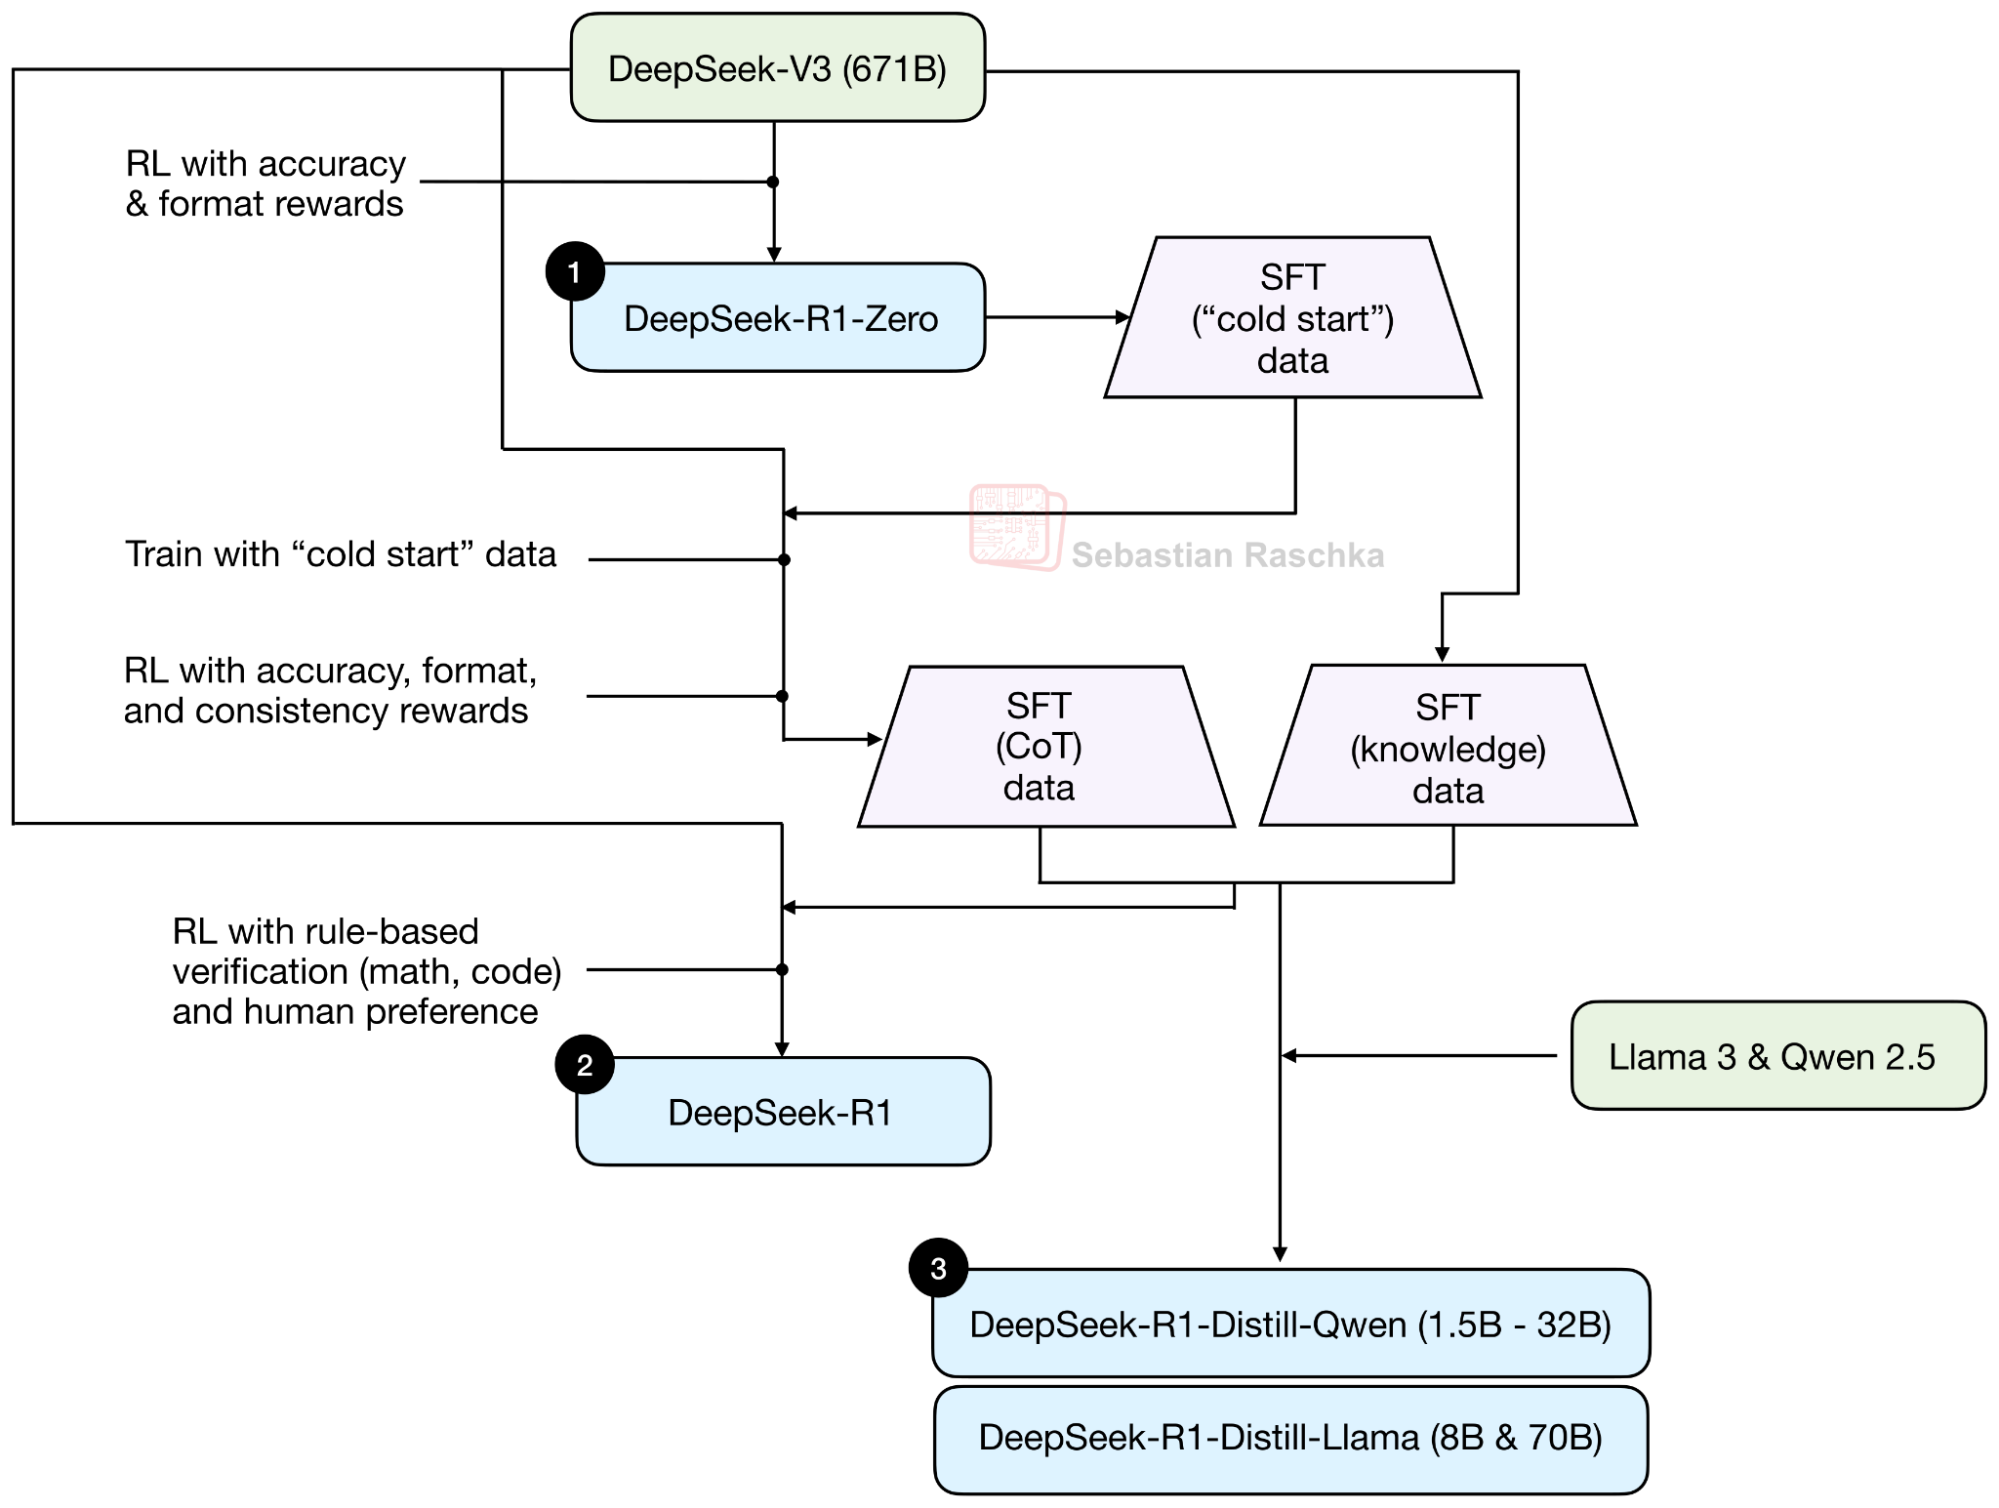
By the way, most of today’s LLMs are effectively reasoning models, meaning they have been trained in a similar fashion to DeepSeek-R1 using a form of RLVR.
2.3 Inference scaling in a nutshell
Next to improving reasoning behavior through training, another lever for improving model performance is inference compute scaling. In short, this means that we are spending more compute after training the model, during usage, to get better answers.
中文译文 04
463 字顺带一提,DeepSeek-R1 无疑更受关注,也正是这篇论文掀起了人们对可验证奖励强化学习和推理模型开发的热情。不过,另一篇论文 Kimi K1.5 也在同一天——2025 年 1 月 22 日——发表于 arXiv。RLVR 这个术语则更早两个月,就已在《Tülu 3:拓展开放语言模型后训练的前沿》中提出。 [1] [2]
DeepSeek-R1 最终更受欢迎的原因之一,是它证明了仅靠强化学习(RL)也能产生推理行为。
例如,Tülu 3 和 Kimi K1.5 都是在经过监督微调(SFT)的模型基础上实施强化学习。DeepSeek-R1 本身也从 DeepSeek-V3 基础模型的一个 SFT 检查点开始训练,同时还提供了一个仅用 RLVR 训练的 DeepSeek-R1-Zero 变体。R1-Zero 的能力弱于 R1,但它说明,RLVR 足以教会模型生成并使用推理轨迹。
虽然 R1-Zero 更像是概念验证模型,但要注意,如前所述,完整的 DeepSeek-R1 推理模型训练流程通常包含多个阶段,也更加复杂。
顺便说一句,如今大多数大语言模型实际上都是推理模型,也就是说,它们采用了某种形式的 RLVR,以类似 DeepSeek-R1 的方式训练。
2.3 推断扩展简述
除了通过训练改善推理行为,提高模型表现的另一根杠杆是扩展推断计算。简言之,就是在训练结束后的使用阶段投入更多计算,以获得更好的答案。
上下游
本块首次出现的来源与延伸
来源身份与原文对应;未把链接存在当作事实核验。
保留来源;未独立逐项核验来源身份与原文对应;未把链接存在当作事实核验。
保留来源;未独立逐项核验来源身份与原文对应;未把链接存在当作事实核验。
保留来源;未独立逐项核验本块新增 3 项 · 另有 2 项已在前文介绍
判断
对本块内容的判断
先区分作者的解释性示例、论文报告和本站核验;推理轨迹不等于对内部机制的完整观测。
核验与延伸:Kimi K1.5 ↗ · Tülu 3: Pushing Frontiers in Open Language Model Post-Training ↗ · Understanding Reasoning LLMs ↗ · Sebastian Raschka · Controlling Reasoning Effort in LLMs ↗
解释
本块首次出现的知识点
本块相关内容已在前文介绍
英文原文 05
277 词 · 4 张图This is a whole topic by itself, and you could read through my The State of LLM Reasoning Model Inference for a more detailed rundown:
I will try to summarize what’s most essential to mention as background info below.
First, training a model with RLVR is already implicitly leading to a form of inference scaling, since reasoning models usually output more tokens during inference compared to conventional LLMs, and that means we are spending more compute during inference.
Second, we can further adjust this output length via reasoning effort levels, but more on that later.
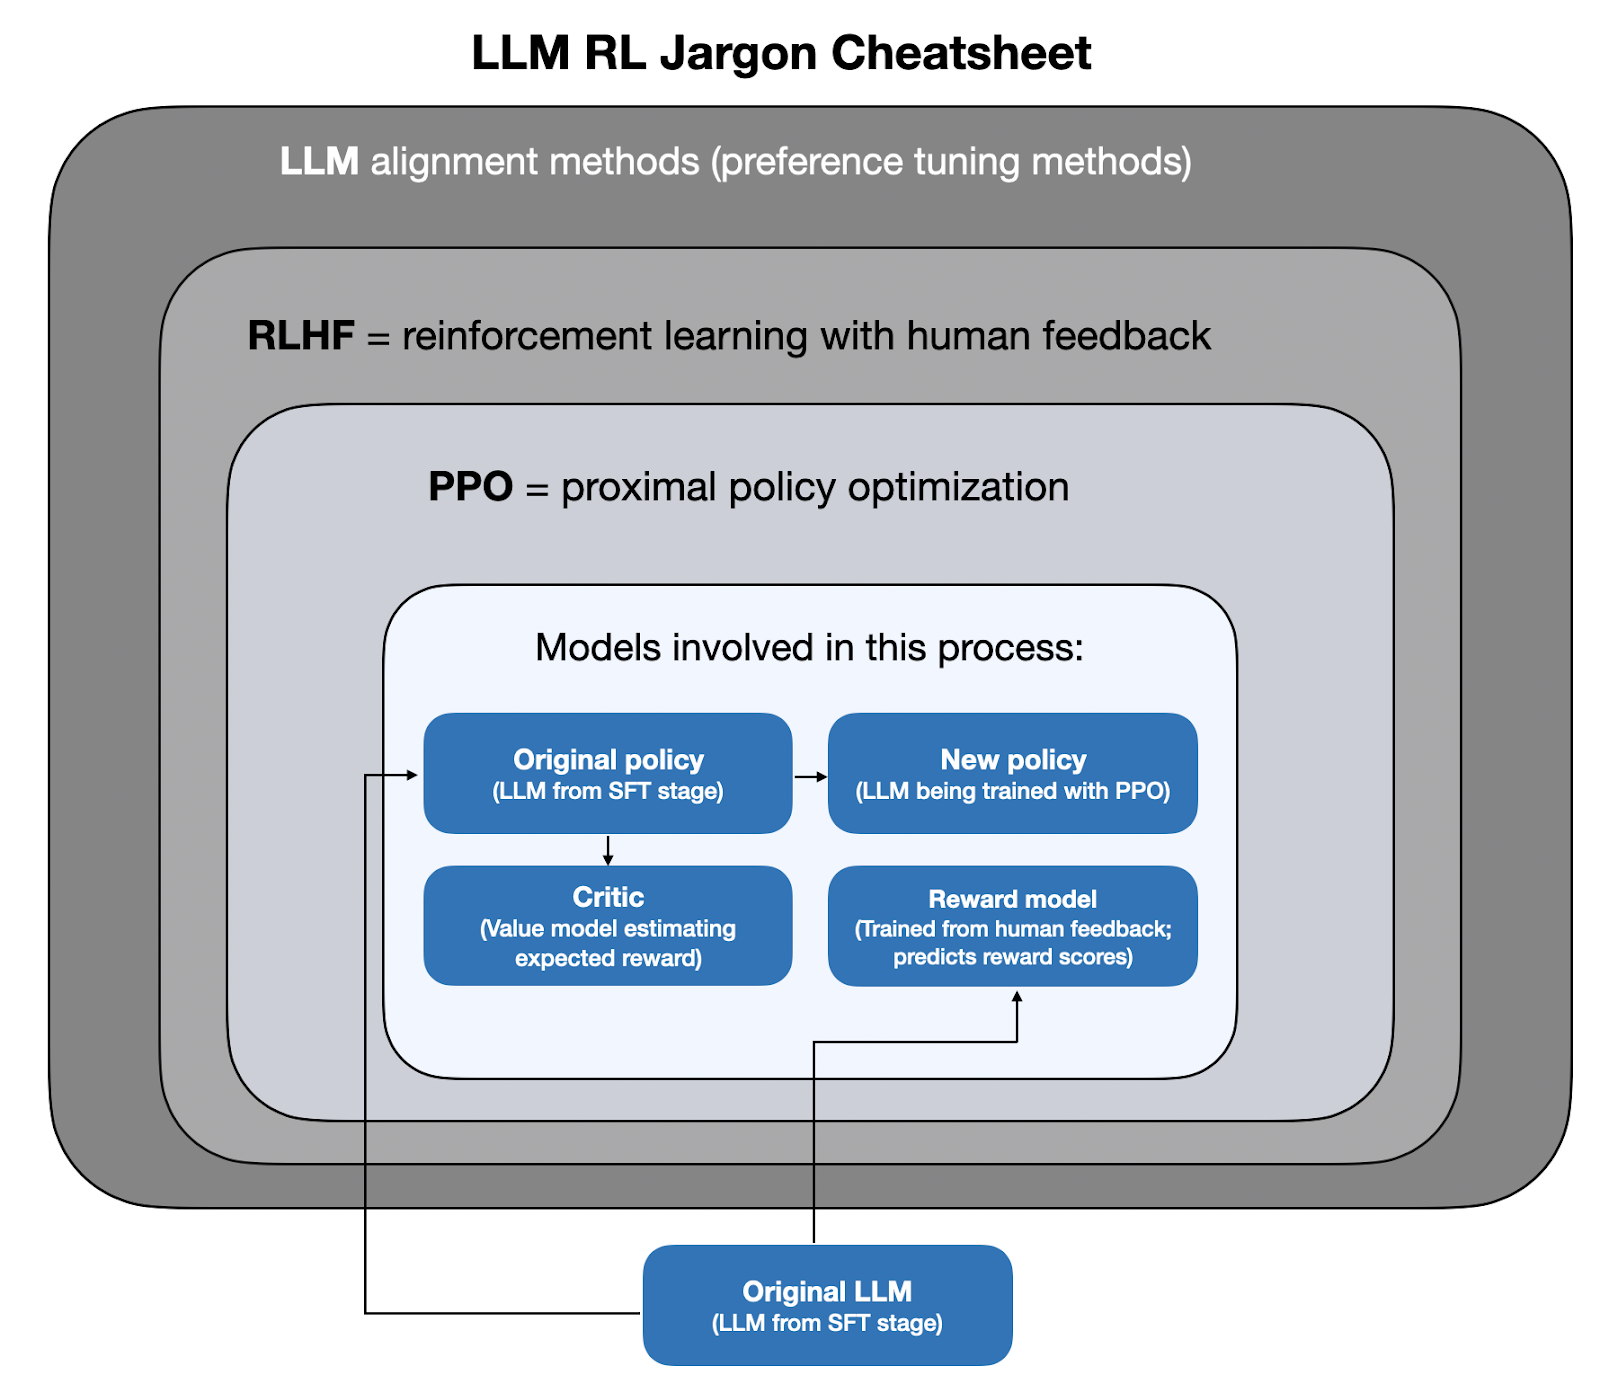
Third, there are many additional inference scaling techniques. A popular one is self-consistency, which is often implemented as a form of majority voting where the model is queried multiple times, and the final answer is selected via majority vote.
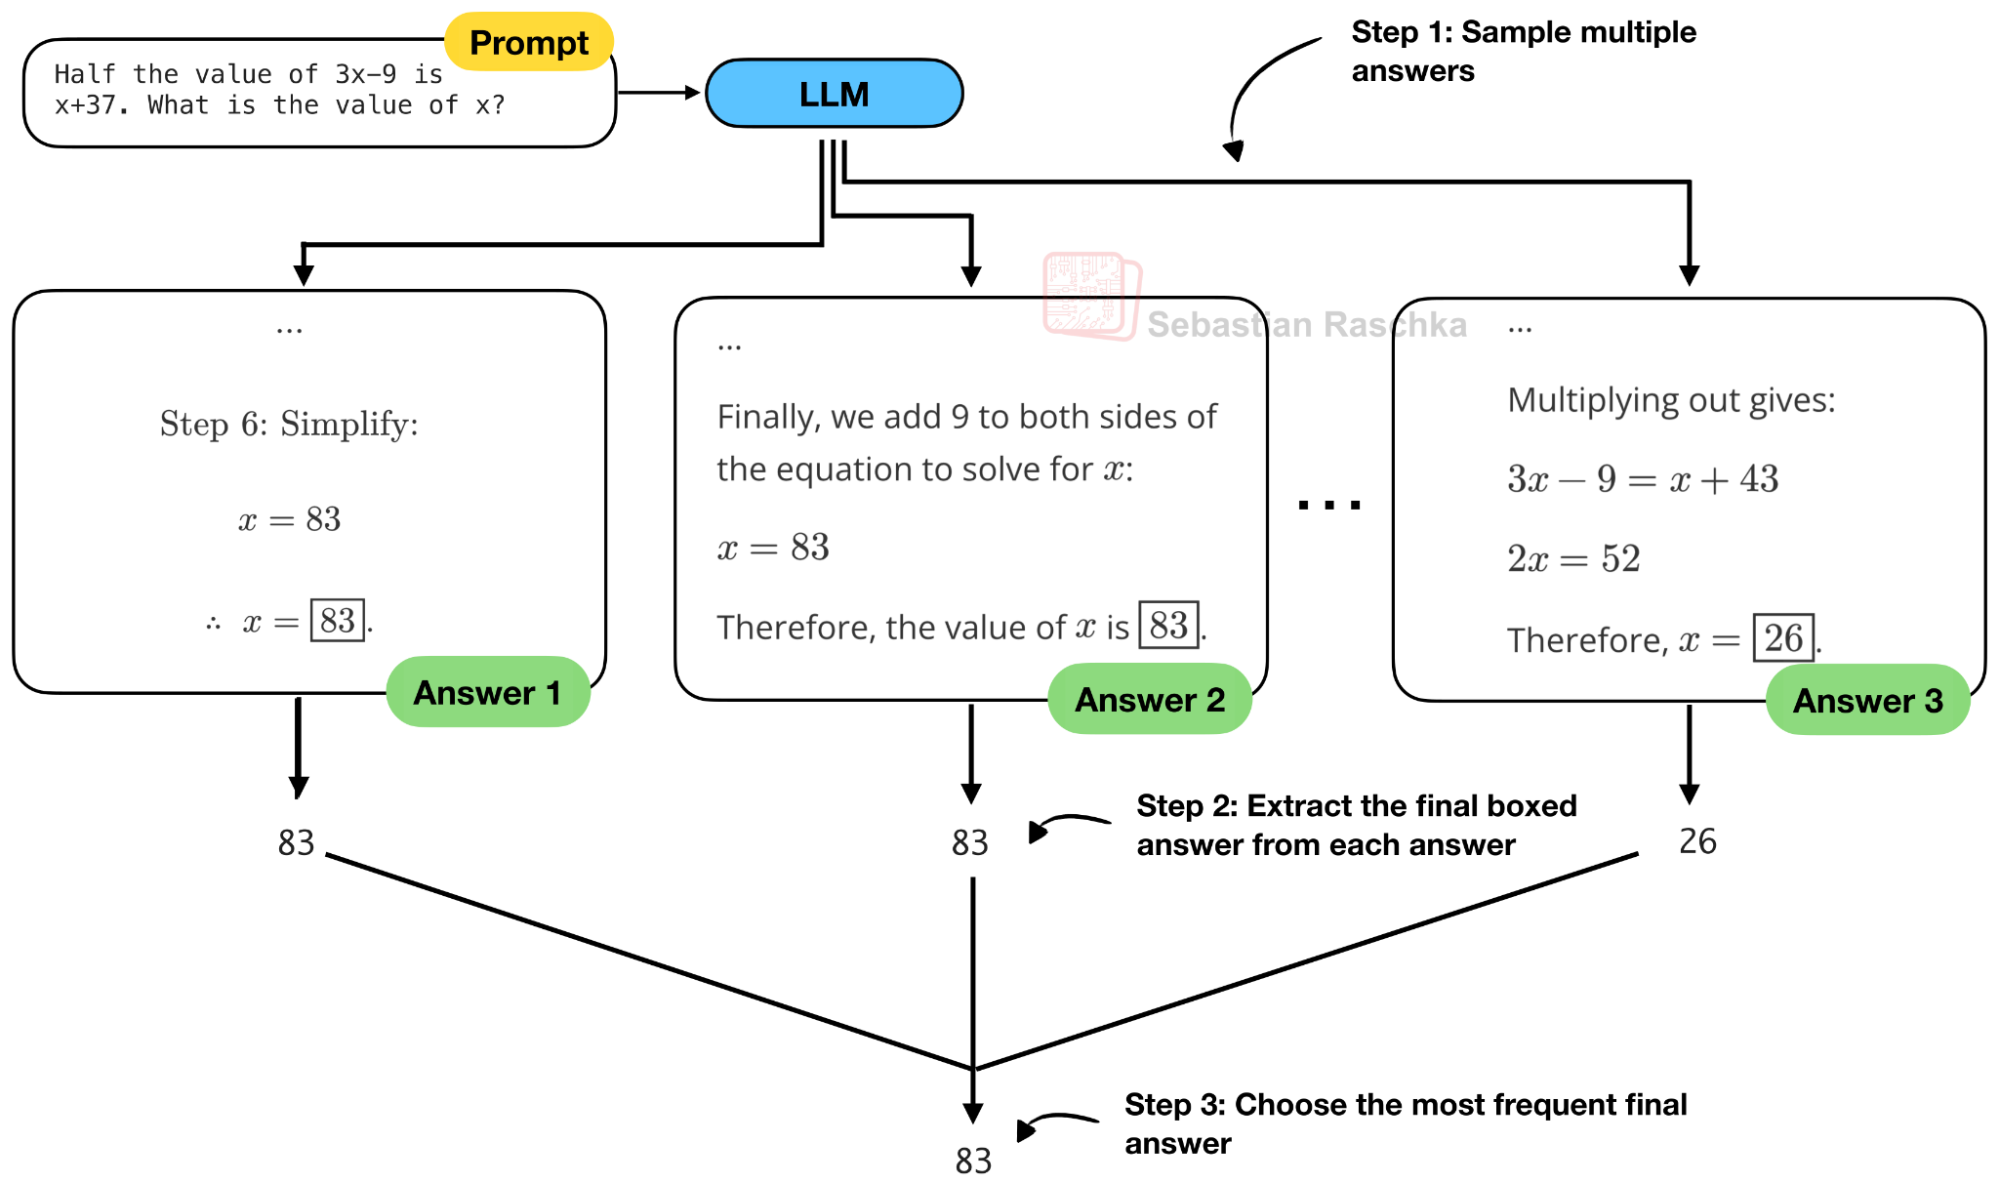
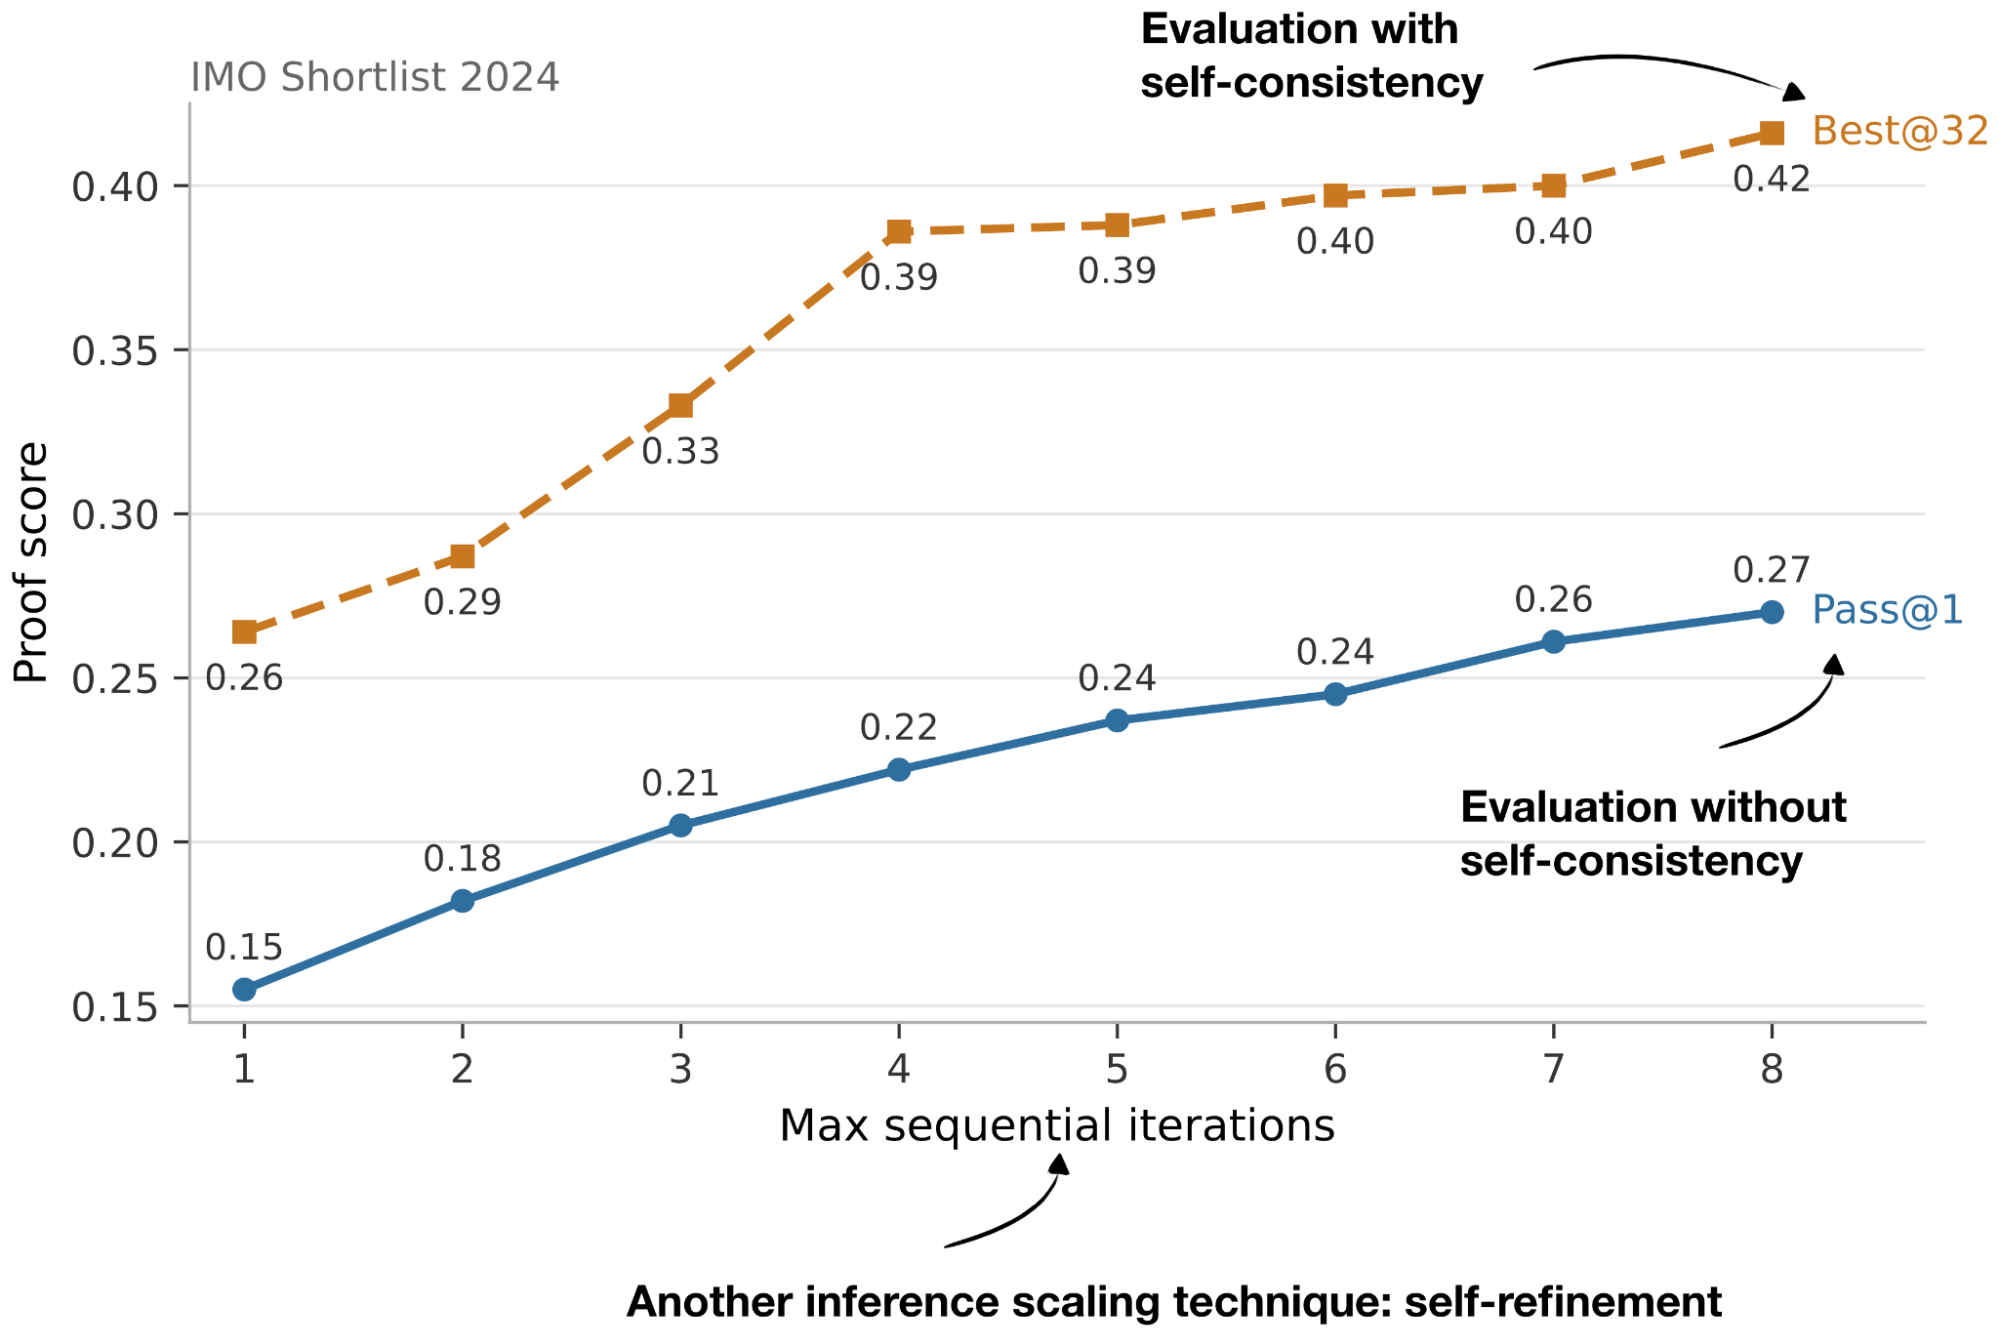
This can be applied to conventional LLMs as well as reasoning models. Also, this method can be used on demand and in addition to reasoning training. A good example of that is DeepSeekMath-V2, where the researchers applied extreme inference-scaling on top of a reasoning model (specialized for math) to achieve state-of-the-art performance on challenging math olympiad-type problems.
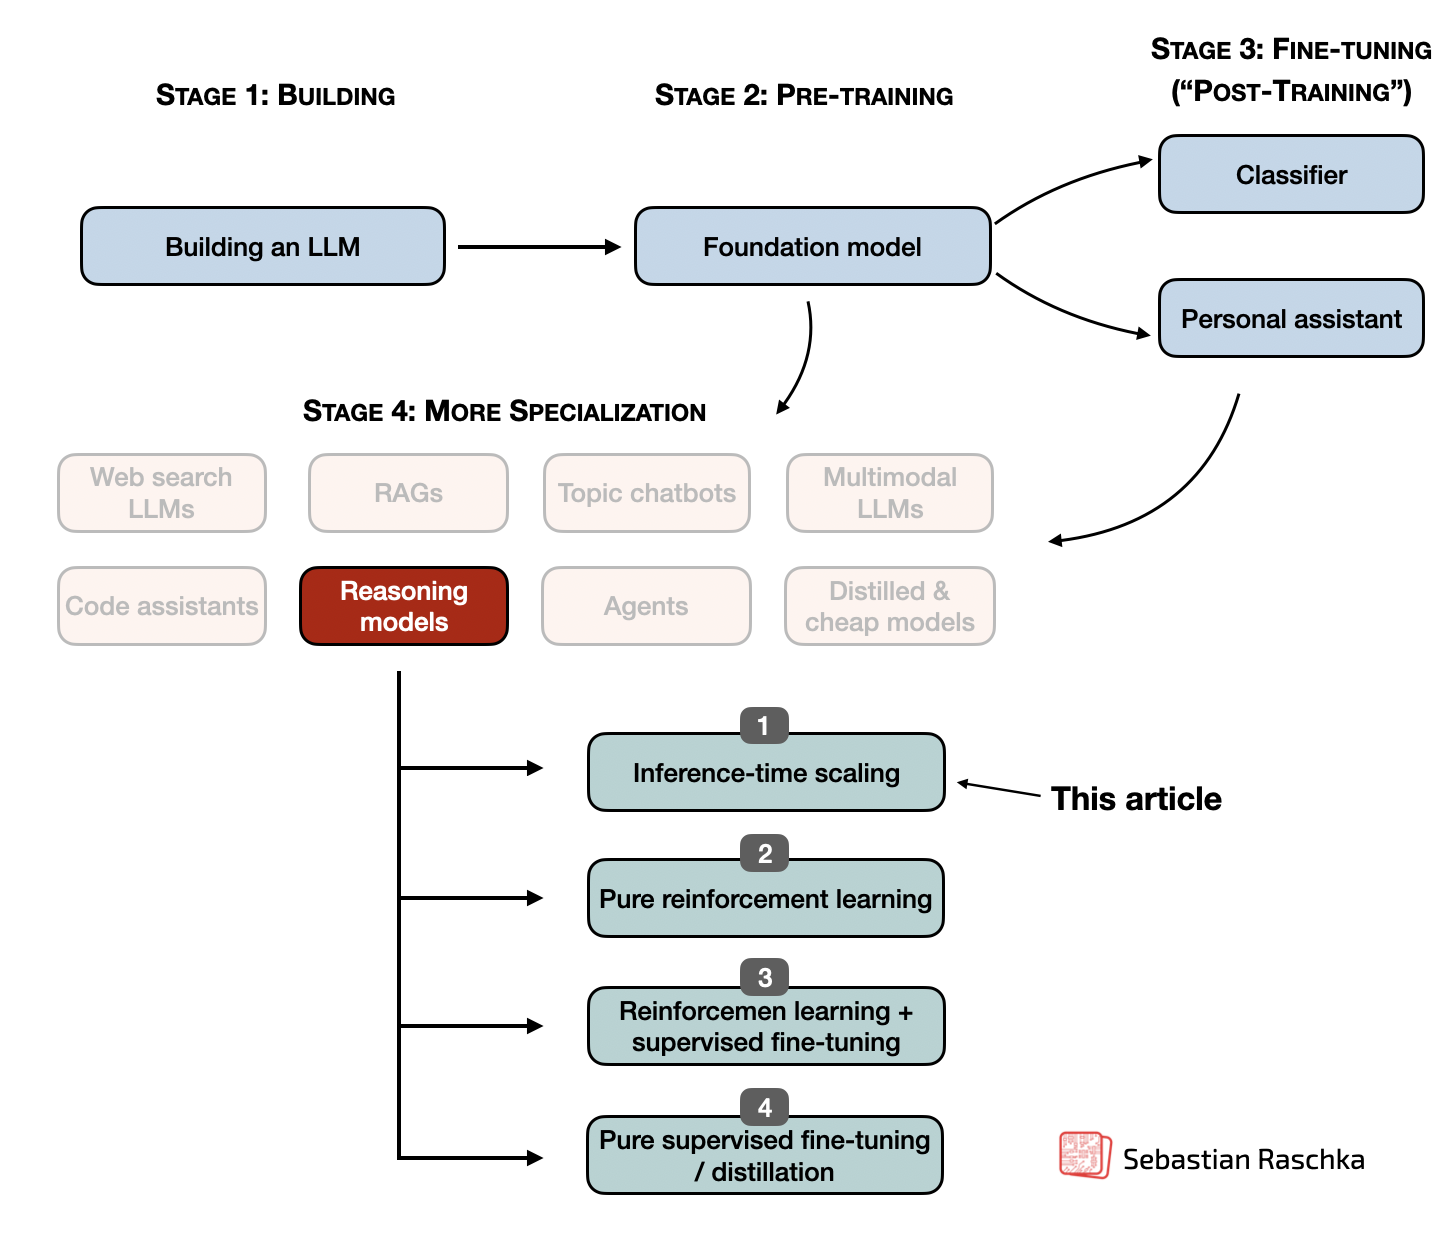
But again, I will refer to my other article, The State of LLM Reasoning Model Inference for an overview of other techniques:
中文译文 05
465 字这本身就是一个完整的话题。想了解更详细的梳理,可以阅读我的《大语言模型推理模型的推断现状》:
下面我会尽量概括其中最需要交代的背景。
第一,用 RLVR 训练模型,本身就隐含地带来了一种推断扩展:推理模型在推断时通常会比传统大语言模型输出更多 token,这意味着推断阶段消耗了更多计算。
第二,我们可以通过推理强度档位进一步调整输出长度,后文会详细讨论。
第三,还有许多其他推断扩展技术。其中一种常见方法是自一致性:通常多次向模型提问,再以多数投票的方式选出最终答案。
这种方法既适用于传统大语言模型,也适用于推理模型,而且可以按需使用,作为推理训练之外的补充。DeepSeekMath-V2 就是一个很好的例子:研究人员在专门面向数学的推理模型之上进行大规模推断扩展,使其在高难度数学奥赛类问题上取得了当时最先进的表现。
至于其他技术的概览,仍推荐阅读我的另一篇文章《大语言模型推理模型的推断现状》:
上下游
本块首次出现的来源与延伸
来源身份与原文对应;未把链接存在当作事实核验。
保留来源;未独立逐项核验本块新增 1 项 · 另有 2 项已在前文介绍
判断
对本块内容的判断
先区分作者的解释性示例、论文报告和本站核验;推理轨迹不等于对内部机制的完整观测。
核验与延伸:DeepSeekMath-V2: Towards Self-Verifiable Mathematical Reasoning ↗ · Sebastian Raschka · Controlling Reasoning Effort in LLMs ↗ · DeepSeek-R1 论文 v1 ↗
解释
本块首次出现的知识点
本块相关内容已在前文介绍
英文原文 06
278 词 · 1 张图3. Think tokens
You may have seen the <think></think> tokens in the earlier “Aha moments” figure. I also included the corresponding figure below so you don’t have to scroll all the way up.
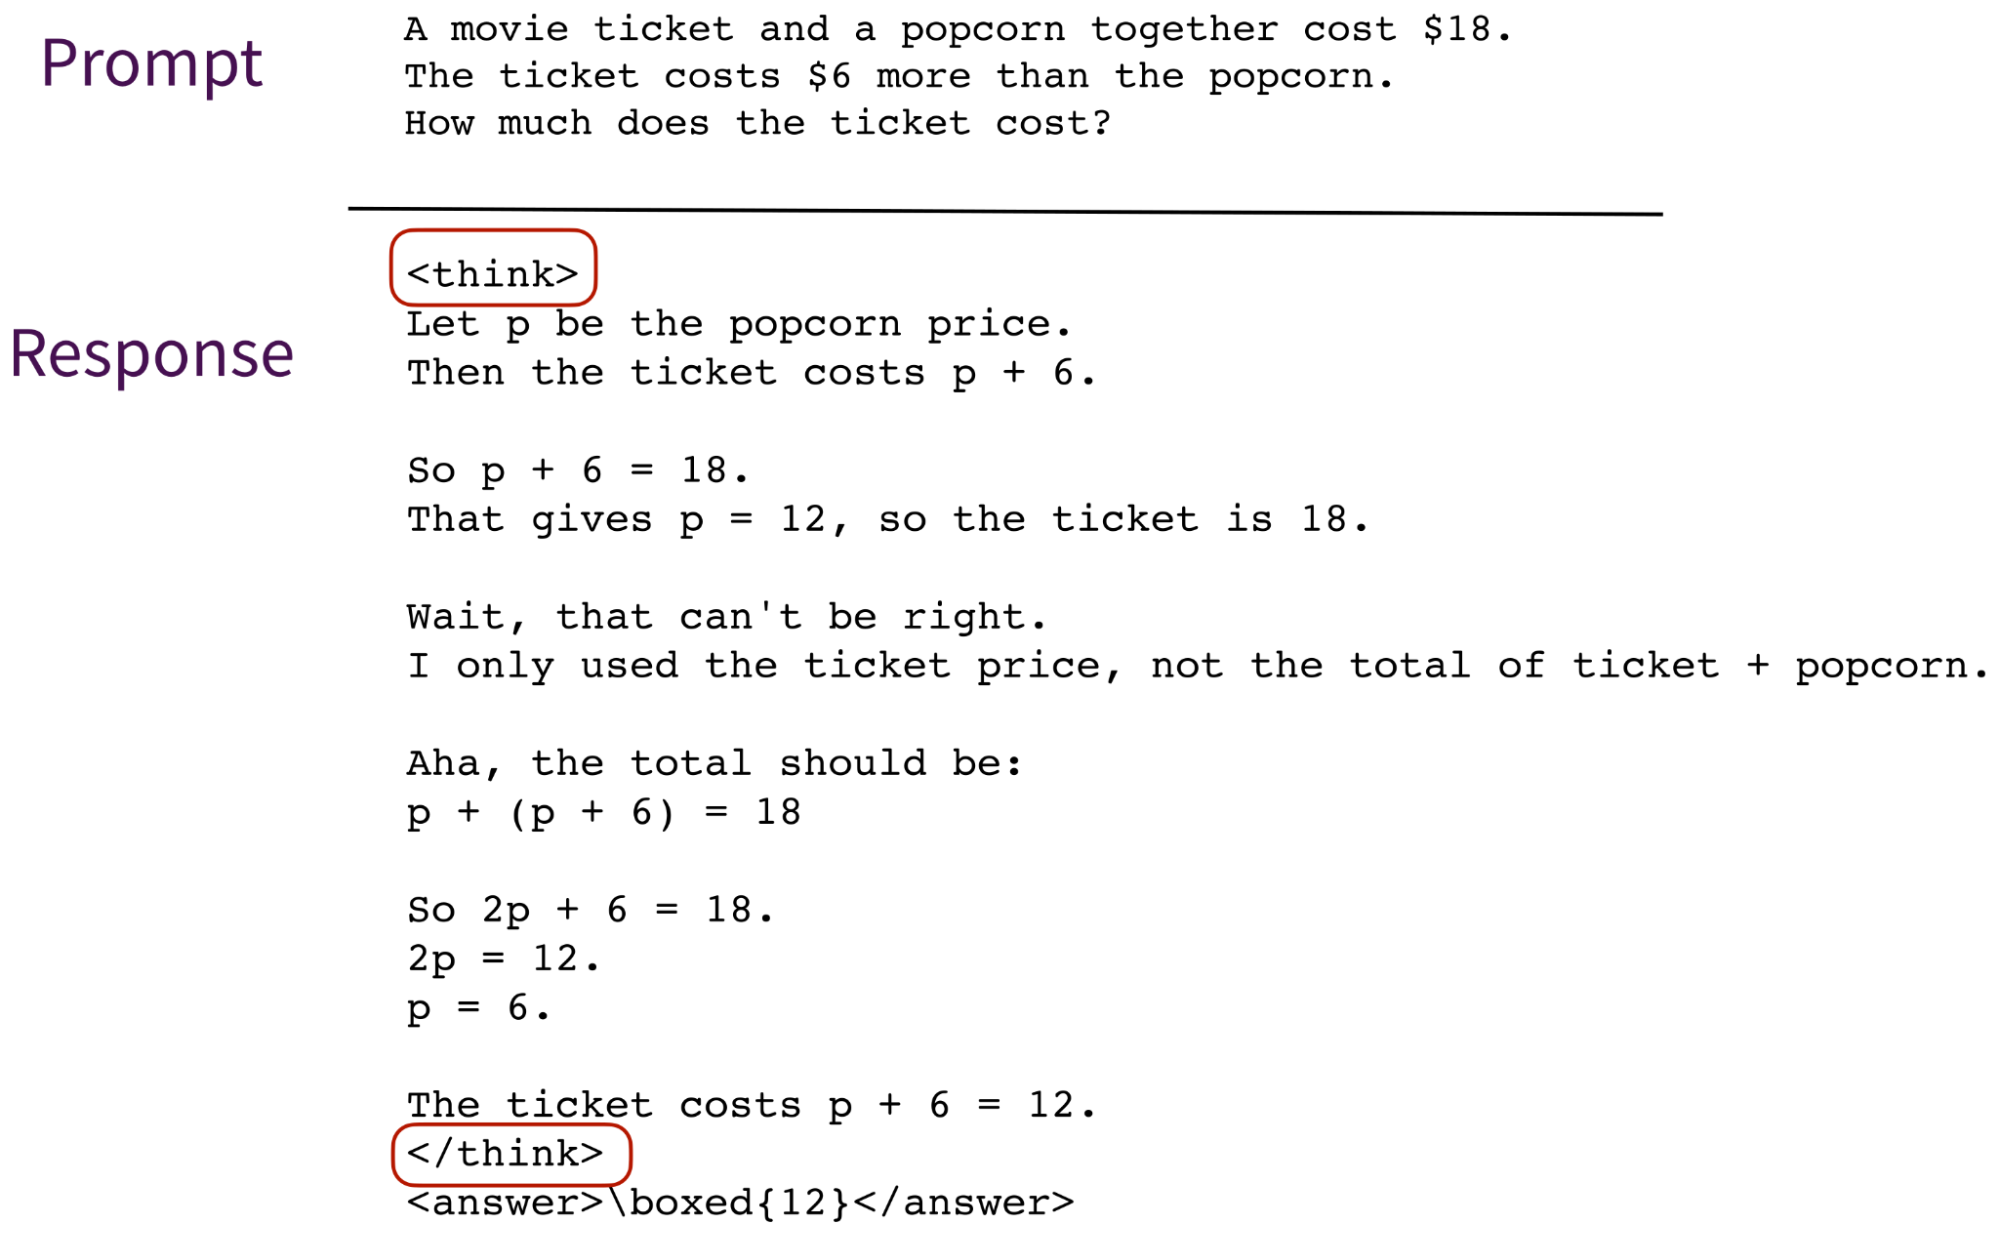
These <think> and </think> tags are cosmetic with respect to reasoning ability. They do not make the model reason, and they are not required to achieve good reasoning performance. One could train the same model without these delimiters and likely reach similar benchmark performance.
The purpose of these <think> tags or tokens is mainly to mark where the reasoning trace begins and ends so that the training pipeline or user interface can separate it from the final answer and optionally hide it from the user. (UIs like ChatGPT or Codex usually do this.)
The point here is that the <think> tokens are not giving the model the ability to “think” or reason or reason better. One could train the same models without such <think> tokens and reach similar benchmark performance.
There is also nothing special about the literal strings <think> and </think>. Another pair of delimiters could serve the same purpose.
By the way, the way this is implemented is typically by adding a formatting reward during the RLVR stage. So instead of just rewarding the model based on answer correctness, one would provide additional reward for the use of <think> tokens, which in turn encourages the model to use those.
In DeepSeek-R1, for example, the overall reward was calculated as
R_total = R_accuracy + R_format
where the format reward was a simple rule-based check that encouraged the model to place its reasoning inside:
<think>
reasoning trace
</think>.
中文译文 06
414 字3. Think 标记
你可能已经在前面“顿悟”时刻的图中看到了 <think></think> 标记。我在下面再次放上相关图示,这样你就不必向上翻找了。
对于推理能力而言,<think> 和 </think> 这些标签只是形式上的安排。它们不会让模型获得推理能力,也不是取得良好推理表现的必要条件。即使不用这些分隔符来训练同一个模型,也很可能取得相近的基准表现。
这些 <think> 标签或 token 的主要用途,是标记推理轨迹的起止位置,让训练流程或用户界面能够把它与最终答案分开,并根据需要对用户隐藏它。(ChatGPT 或 Codex 等界面通常会这样做。)
关键在于,<think> 标记不会赋予模型“思考”、推理或更好推理的能力。训练同样的模型时不使用这些标记,也可能达到相近的基准表现。
字面字符串 <think> 和 </think> 也没有什么特别之处。换一对分隔符也能发挥同样的作用。
顺带一提,典型的实现方式是在 RLVR 阶段添加格式奖励。除了根据答案正确性奖励模型,还会对使用 <think> 标记给予额外奖励,从而鼓励模型采用这些标记。
例如,在 DeepSeek-R1 中,总奖励的计算方式是:
R_total = R_accuracy + R_format
其中,格式奖励是一项简单的规则检查,用来鼓励模型把推理放在以下标签之间:
<think>
推理轨迹
</think>。
上下游
本块首次出现的来源与延伸
核对思考/非思考SFT、聊天模板与预算截断;没有泛化到所有Qwen版本。
已读§4.3–4.4本块新增 1 项 · 另有 2 项已在前文介绍
判断
对本块内容的判断
先区分作者的解释性示例、论文报告和本站核验;推理轨迹不等于对内部机制的完整观测。 区分训练中形成的行为、聊天模板的选择信号,以及运行时强制限制。
核验与延伸:Sebastian Raschka · Controlling Reasoning Effort in LLMs ↗ · DeepSeek-R1 论文 v1 ↗ · Qwen3 技术报告 v1 ↗
解释
本块首次出现的知识点
本文解释:行为模式与硬预算
强度标签用于选择模型学到的推理行为;硬预算规定还能生成多久。像“写得简洁”和“到500字必须停”分别约束习惯与边界,二者可以同时使用,效果仍需按任务检验。
本块新增 1 项 · 另有 1 项已在前文介绍
英文原文 07
208 词 · 2 张图4. Reasoning mode on and off switches
The first generation of reasoning models was dedicated reasoning models. With that, I mean that there was a DeepSeek-V3 base model and a separate DeepSeek-R1 reasoning model.
No matter what the prompt is, R1 generally outputs very verbose responses using lots of tokens, even for simple prompts. It also lacks a built-in option to turn off the reasoning mode.
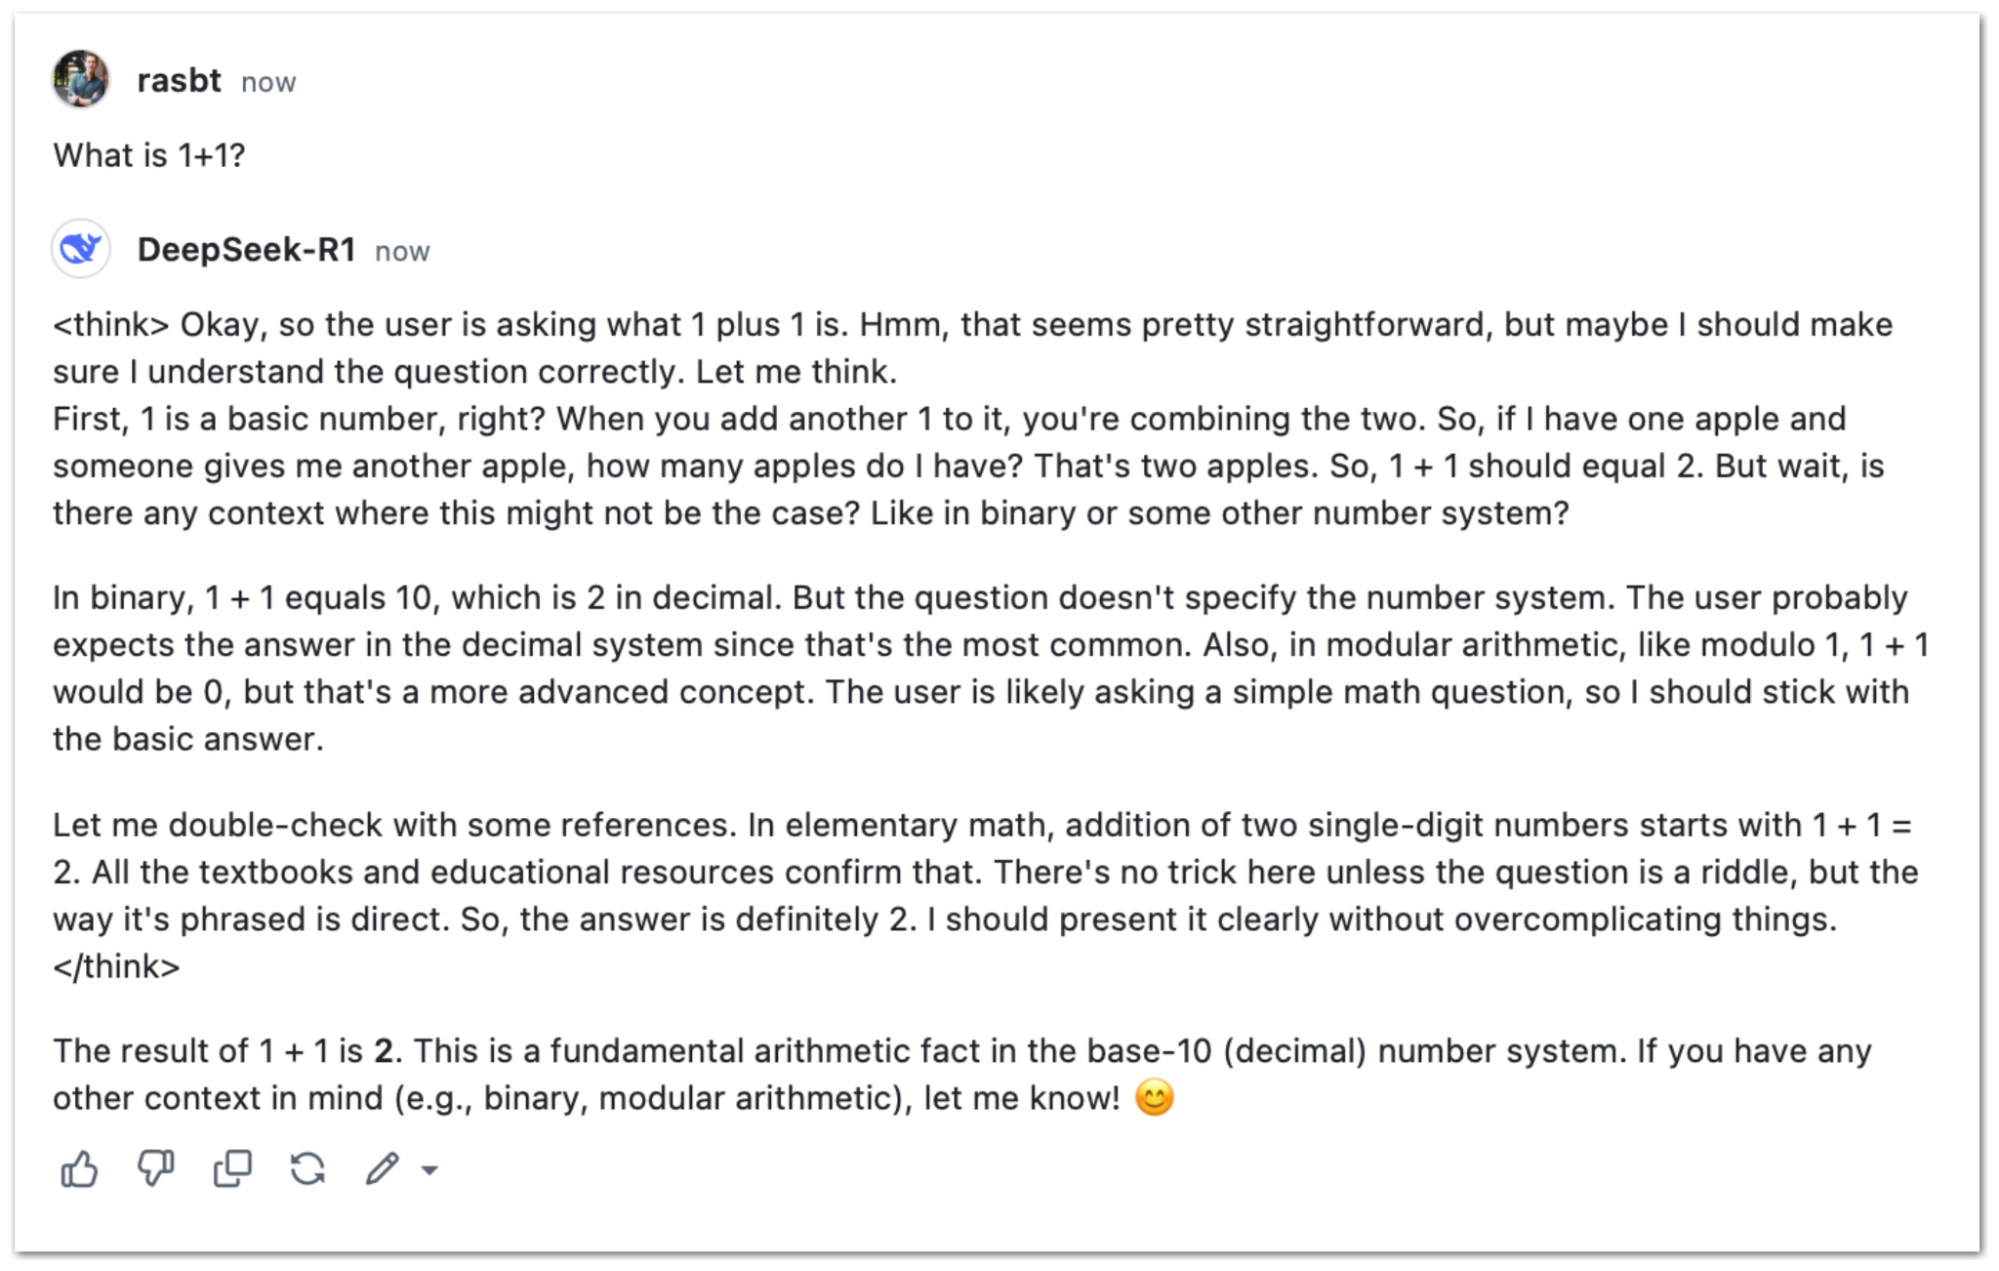
Later models, like Qwen3 and others, experimented with hybrid approaches, where the same model can behave like a regular instruction fine-tuned model or a reasoning model on demand.
Note: Some model developers call this “thinking mode,” while others call it “reasoning mode.” Both terms refer to the same behavior.
In Qwen3, this is handled via the tokenizer using enable_thinking=True or enable_thinking=False. Under the hood, setting enable_thinking=False essentially adds an empty <think></think> section to the beginning of the assistant response to turn off Qwen3’s reasoning (”thinking”) mode.
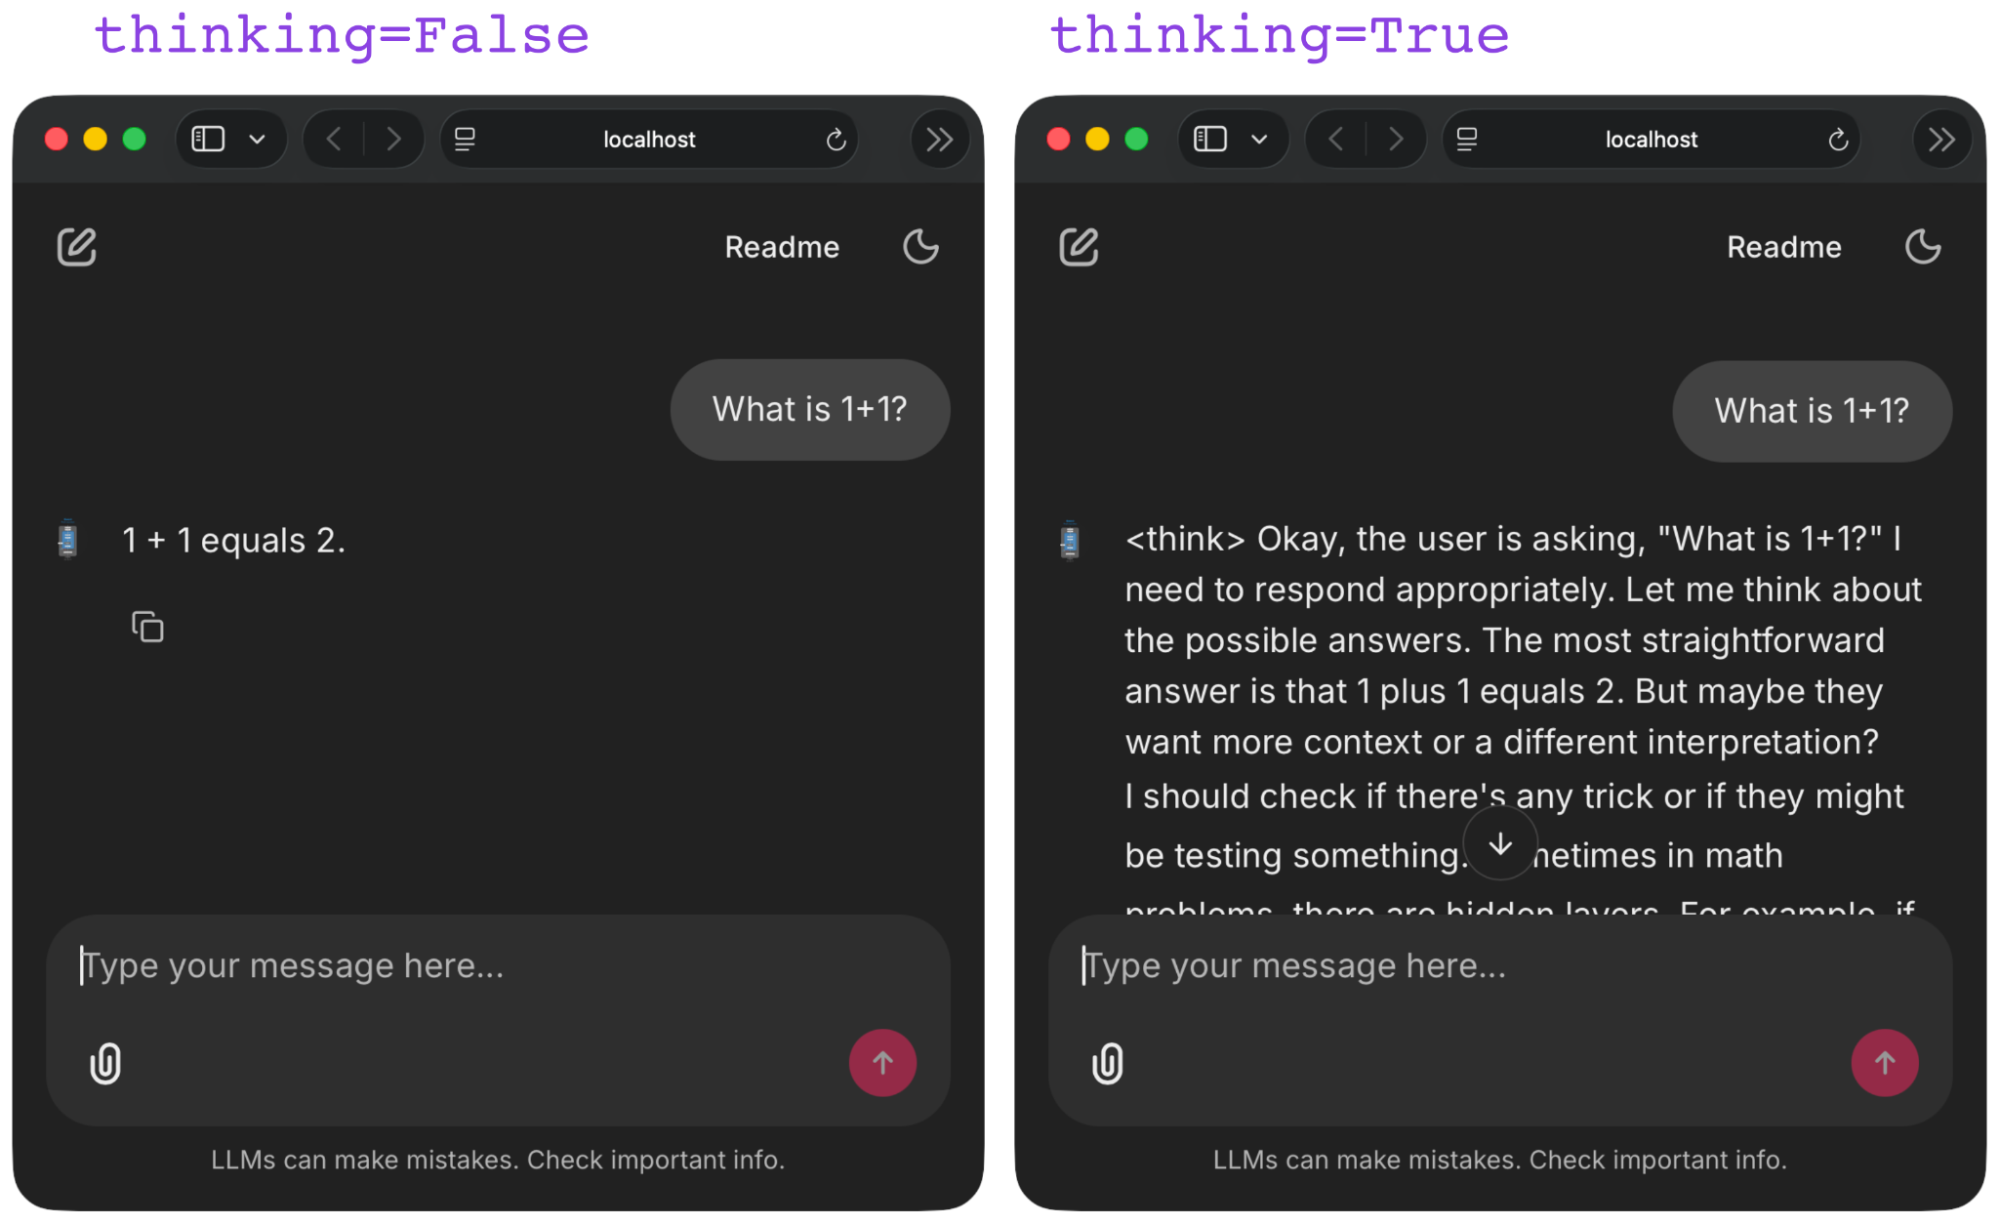
thinking=False and thinking=True. (The empty <think></think> tags are hidden in the interface on the left as they are part of the modified input prompt, not the generated answer.)中文译文 07
342 字4. 推理模式的开关
第一代推理模型是专门用于推理的模型。我的意思是,当时有一个 DeepSeek-V3 基础模型,以及一个与它分开的 DeepSeek-R1 推理模型。
无论提示是什么,R1 通常都会使用大量 token,给出十分冗长的回答,即便面对简单提示也是如此。它也没有内置的关闭推理模式选项。
后来的模型,例如 Qwen3 等,开始尝试混合方案:同一个模型可以根据需要,像普通指令微调模型那样回答,也可以像推理模型那样工作。
说明:一些模型开发者称之为“思考模式”,另一些则称之为“推理模式”。两者指的是同一种行为。
在 Qwen3 中,这通过分词器的 enable_thinking=True 或 enable_thinking=False 参数处理。从底层实现看,设置 enable_thinking=False,实际上是在助手回答开头预先填入一个空的 <think></think> 段,从而关闭 Qwen3 的推理(“思考”)模式。
上下游
本块首次出现的来源与延伸
本块相关内容已在前文介绍
判断
对本块内容的判断
区分训练中形成的行为、聊天模板的选择信号,以及运行时强制限制。
核验与延伸:Sebastian Raschka · Controlling Reasoning Effort in LLMs ↗ · Qwen3 技术报告 v1 ↗
解释
本块首次出现的知识点
本块相关内容已在前文介绍
英文原文 08
236 词 · 1 张图How is this implemented during training, such that the model supports this toggle during inference time, as shown in the figure above?
In short, as explained in the Qwen3 technical report, this on/off behavior is introduced primarily through supervised fine-tuning (SFT) and then reinforced during general RL in their largest flagship models.
For instance, after the initial reasoning model is trained via long-chain-of-thought SFT and reasoning RL, they add a “Thinking Mode Fusion” stage. During this additional SFT stage, the model sees both thinking and non-thinking examples:
/think: <think>{reasoning}</think>{answer}/no_think: <think></think>{answer}
Thinking is the default behavior, so /think can also be omitted. The subsequent general RL stage further reinforces this mode and format following.
These /think and /no_think flags are a “soft” switch. However, the enable_thinking=False setting mentioned earlier, which force-adds the empty <think></think> in the False case, acts then as a “hard” switch.
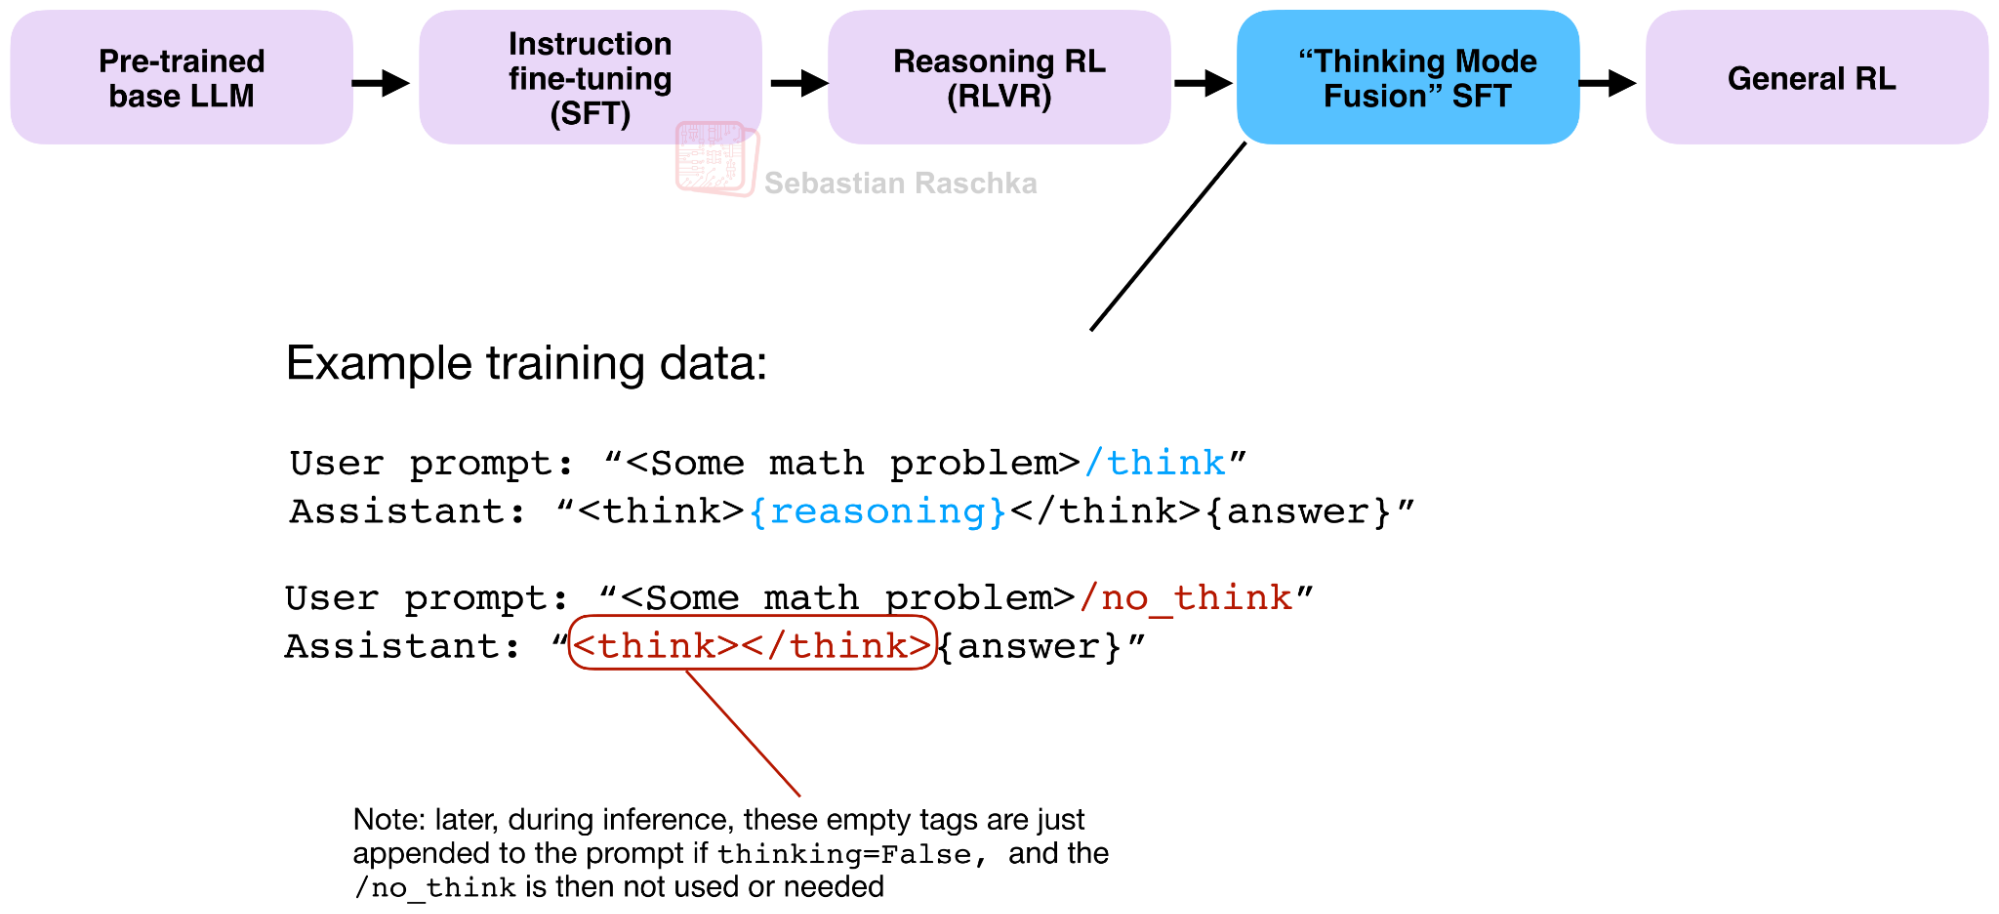
In other words, the tokenizer does not add /no_think to the query. It directly fills in the empty <think></think> section at the beginning of the assistant response. The model only sees the resulting tokens and continues directly with the answer.
Anyway, this on-and-off toggle is essentially a simplified version of the reasoning effort levels in GPT-5.6 and others, which I cover in the next section.
中文译文 08
363 字训练时怎样实现这一点,让模型能在推断阶段支持图中所示的开关?
简而言之,正如 Qwen3 技术报告所述,这种开关行为主要通过监督微调(SFT)引入,随后在最大旗舰模型的通用强化学习阶段得到进一步强化。 [1]
例如,在通过长思维链 SFT 和推理强化学习训练出初始推理模型之后,他们会增加一个“思考模式融合”阶段。在这个额外的 SFT 阶段,模型会同时看到思考与非思考两类示例:
/think: <think>{reasoning}</think>{answer}
/no_think: <think></think>{answer}
思考是默认行为,因此也可以省略 /think。随后的通用强化学习阶段会进一步强化模式选择与格式遵循。
/think 和 /no_think 这些标记属于“软”开关。前面提到的 enable_thinking=False 则会在设为 False 时强制补入空的 <think></think>,因而相当于一个“硬”开关。
换句话说,分词器不会给查询添加 /no_think,而是直接在助手回答开头填入一个空的 <think></think> 段。模型只会看到处理后的 token,并直接接着生成答案。
总之,这种开关基本可以看作 GPT-5.6 等模型推理强度档位的简化版本,下一节会讨论这些档位。
上下游
本块首次出现的来源与延伸
本块相关内容已在前文介绍
判断
对本块内容的判断
区分训练中形成的行为、聊天模板的选择信号,以及运行时强制限制。
Qwen3的模式融合与硬预算有原报告依据
Qwen3报告§4.3描述混合思考和非思考SFT、空思考块模板,以及达到长度阈值后插入停止指令。报告称部分思考续答能力没有被显式训练。该结论限报告版本,示例未运行。
核验与延伸:Qwen3 技术报告 v1 ↗ · Sebastian Raschka · Controlling Reasoning Effort in LLMs ↗
解释
本块首次出现的知识点
本块相关内容已在前文介绍
英文原文 09
256 词 · 3 张图5. How “reasoning effort” settings work
In this section, I want to provide a brief overview of how the different reasoning effort toggles may be implemented, which have been introduced in models like GPT 5 and are present in pretty much any flagship model today.
Concretely, at the beginning of this article, I showed a figure from the Codex GPT 5.6 interface that lets users select multiple reasoning “effort” settings.
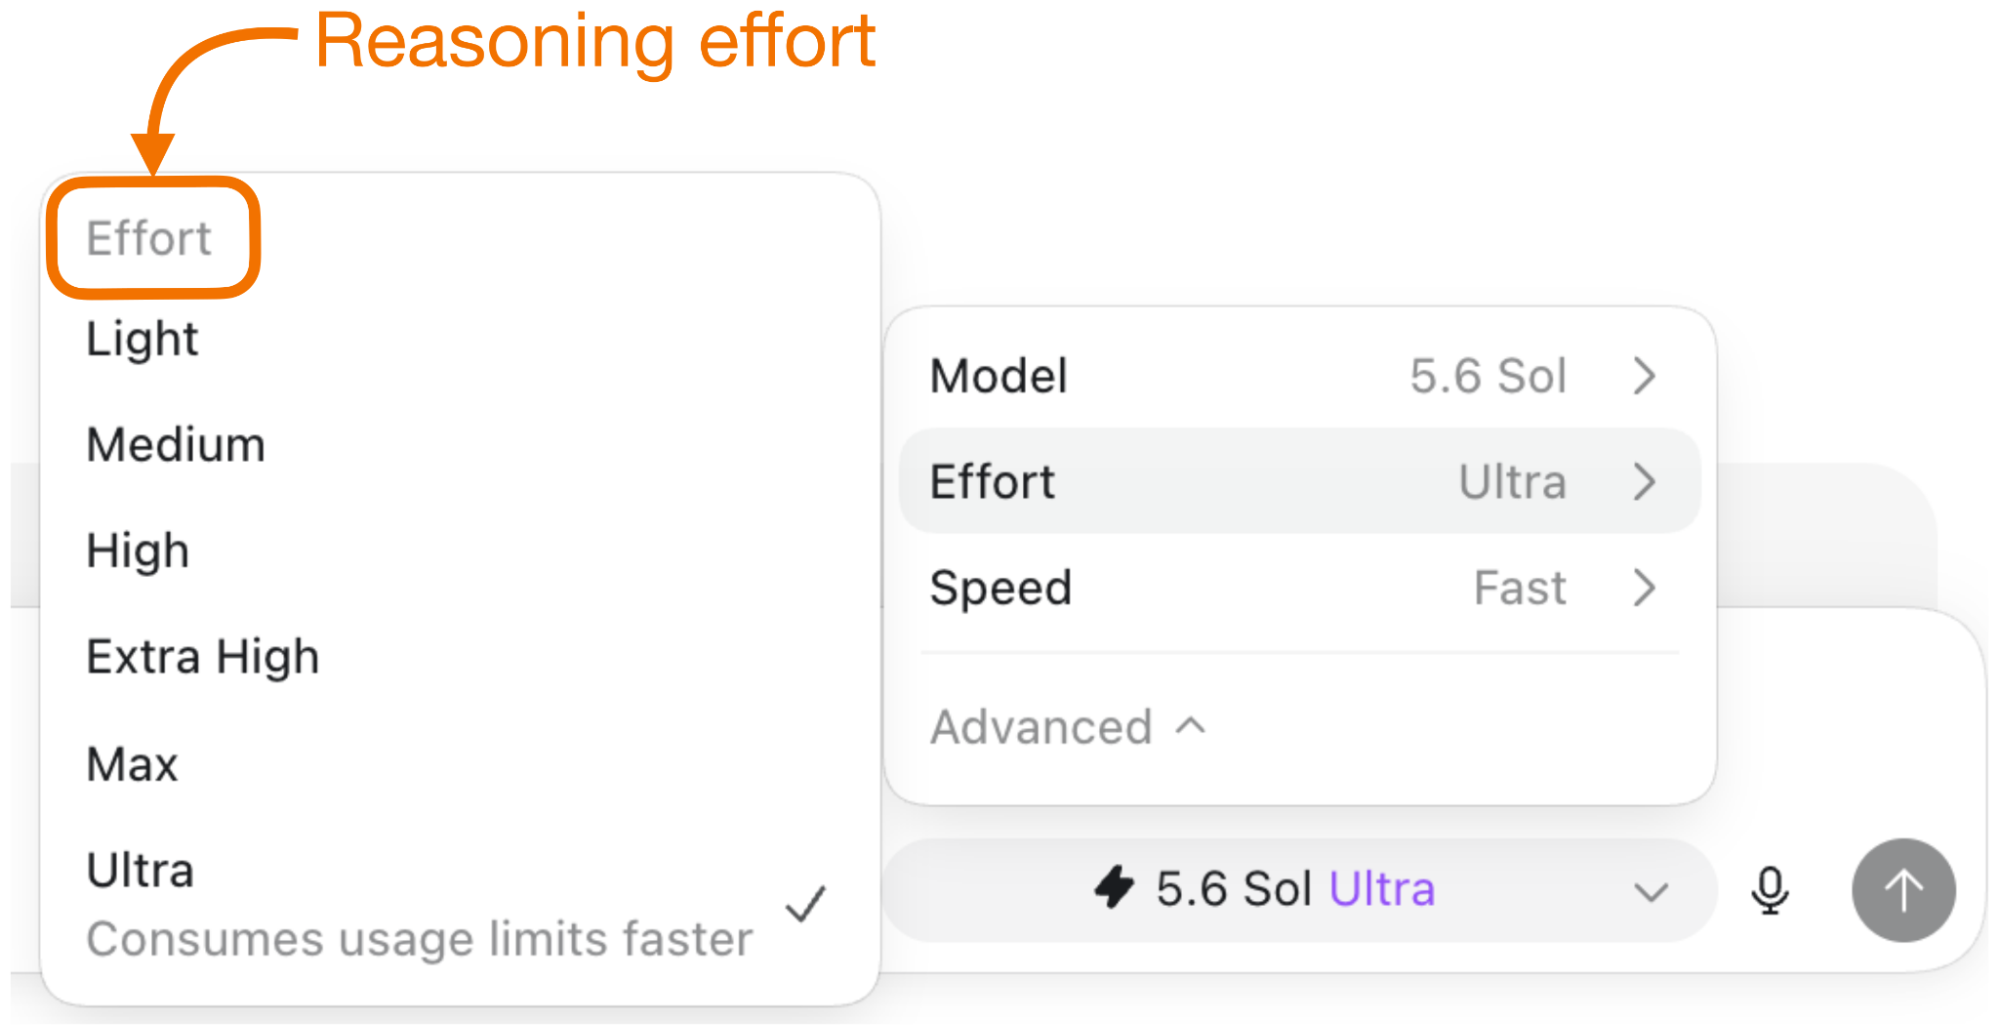
The following subsection will illustrate how these settings may be implemented. Then, in the next section, I will go over some of the more interesting research papers related to this topic.
5.1 Reasoning effort and response length and quality
Unfortunately, the implementation details of their effort settings are not shared by OpenAI, but there is some evidence out there that can be used for educated guesses.
For instance, via their open-source gpt-oss models from last year (I wrote about them in From GPT-2 to gpt-oss: Analyzing the Architectural Advances), we know that OpenAI allows us to toggle the reasoning effort setting via the system prompt (”Reasoning effort: low/medium/high”) that is prepended to each prompt.
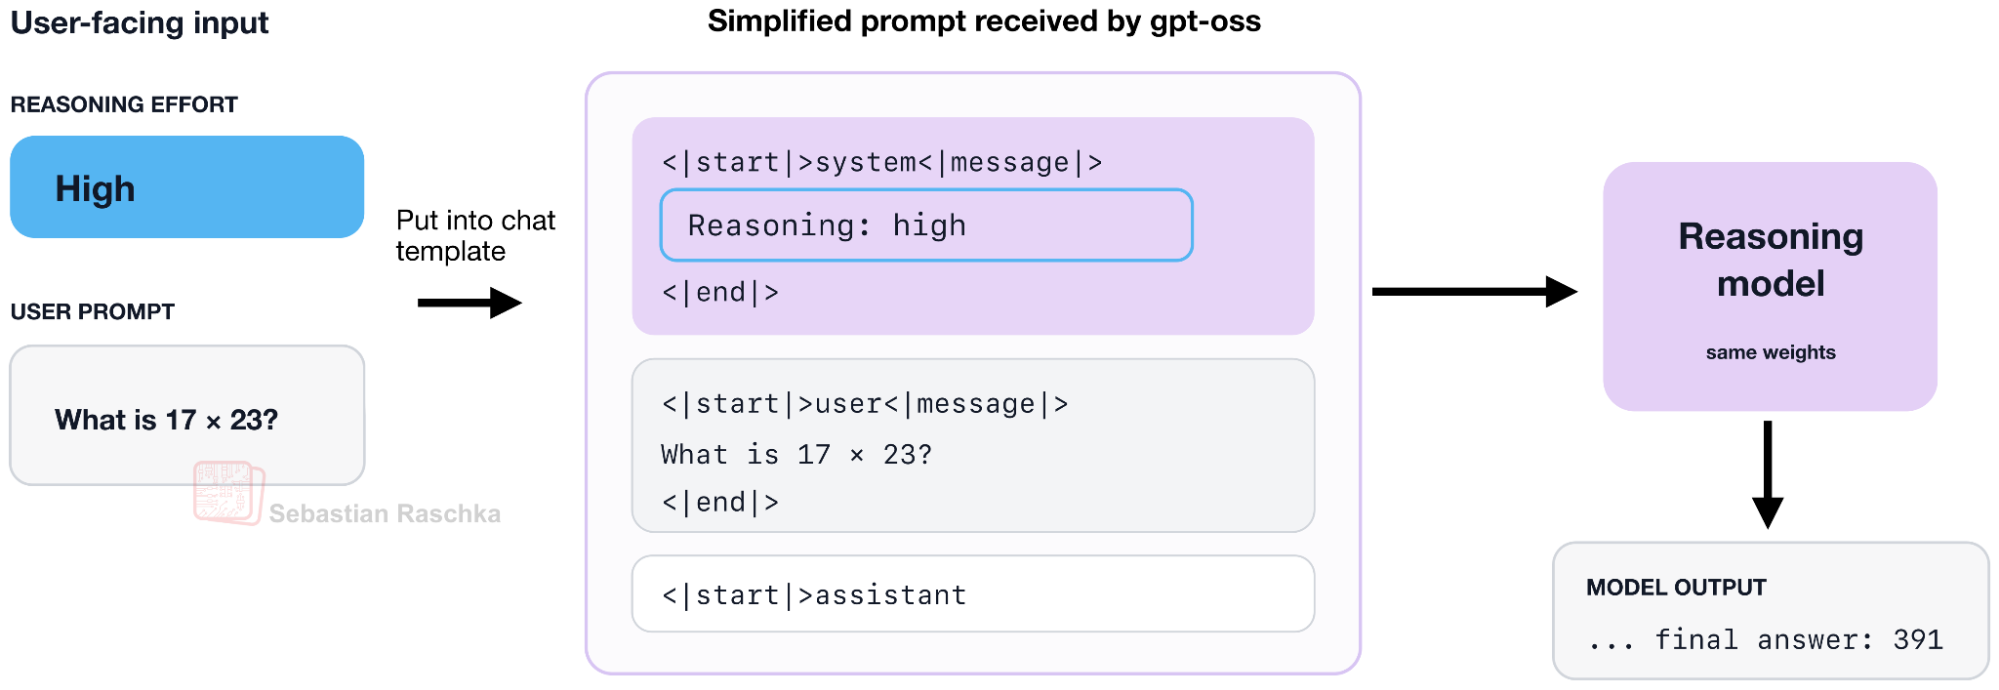
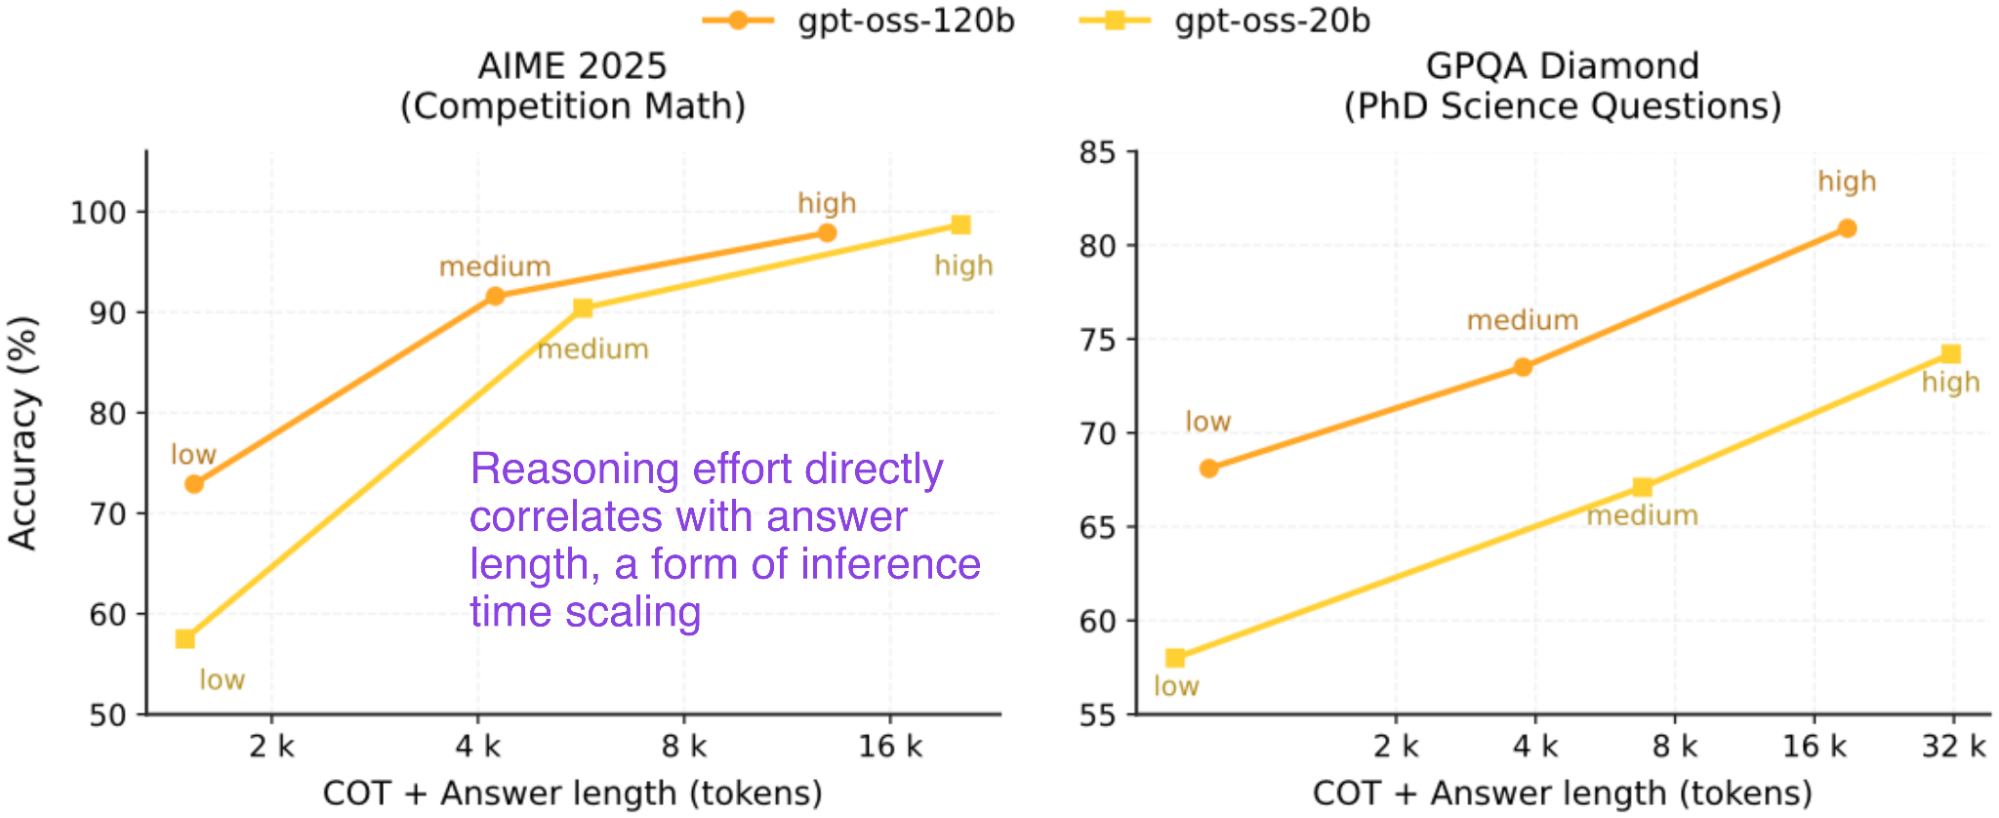
As expected, the reasoning effort directly affects the response length and accuracy, as shown below.
中文译文 09
373 字5. “推理强度”设置如何工作
本节会简要概述不同推理强度开关可能采用的实现方式。这些设置出现在 GPT-5 等模型中,如今几乎所有旗舰模型都提供类似选项。
具体来说,文章开头展示了一张 Codex GPT-5.6 界面的图片,用户可以在其中选择多个推理“强度”设置。
下面的小节会说明这些设置可能如何实现。之后,我会介绍这个话题中一些较有意思的研究论文。
5.1 推理强度、回答长度与质量
遗憾的是,OpenAI 没有公开这些强度设置的实现细节。不过,现有的一些证据可以帮助我们作出有依据的猜测。
例如,通过他们去年开源的 gpt-oss 模型——我在《从 GPT-2 到 gpt-oss:架构进展分析》中介绍过——我们知道,OpenAI 允许通过置于每个提示之前的系统提示“Reasoning effort: low/medium/high”,切换推理强度设置。 [1]
正如预期,推理强度会直接影响回答长度和准确率,如下图所示。
上下游
本块首次出现的来源与延伸
来源身份与原文对应;未把链接存在当作事实核验。
保留来源;未独立逐项核验来源身份与原文对应;未把链接存在当作事实核验。
保留来源;未独立逐项核验本块新增 2 项 · 另有 2 项已在前文介绍
判断
对本块内容的判断
区分训练中形成的行为、聊天模板的选择信号,以及运行时强制限制。 保留作者对闭源实现的推测语气;图中数字属于各自来源和测试条件,不是本站实测。
公开模型的机制不能证明闭源模型采用同一配方
作者明确使用“很可能”“我猜测”等限定。本文将这些保留为作者推测,不作为OpenAI已公开的训练实现。界面存在档位,也不能单独证明后端只改变系统提示。
核验与延伸:From GPT-2 to gpt-oss: Analyzing the Architectural Advances ↗ · model card ↗ · Sebastian Raschka · Controlling Reasoning Effort in LLMs ↗ · Qwen3 技术报告 v1 ↗
解释
本块首次出现的知识点
本文解释:怎样读成本曲线
先固定任务、评价指标、模型版本和运行框架,再比较费用或延迟。一次较便宜的调用如果需要大量重试,未必使整个任务更便宜;本文图表没有测量所有现实工作负载。
本块新增 1 项 · 另有 1 项已在前文介绍
英文原文 10
236 词 · 2 张图Presumably, their GPT 5 models, including the recent GPT 5.6 models, use a similar approach.
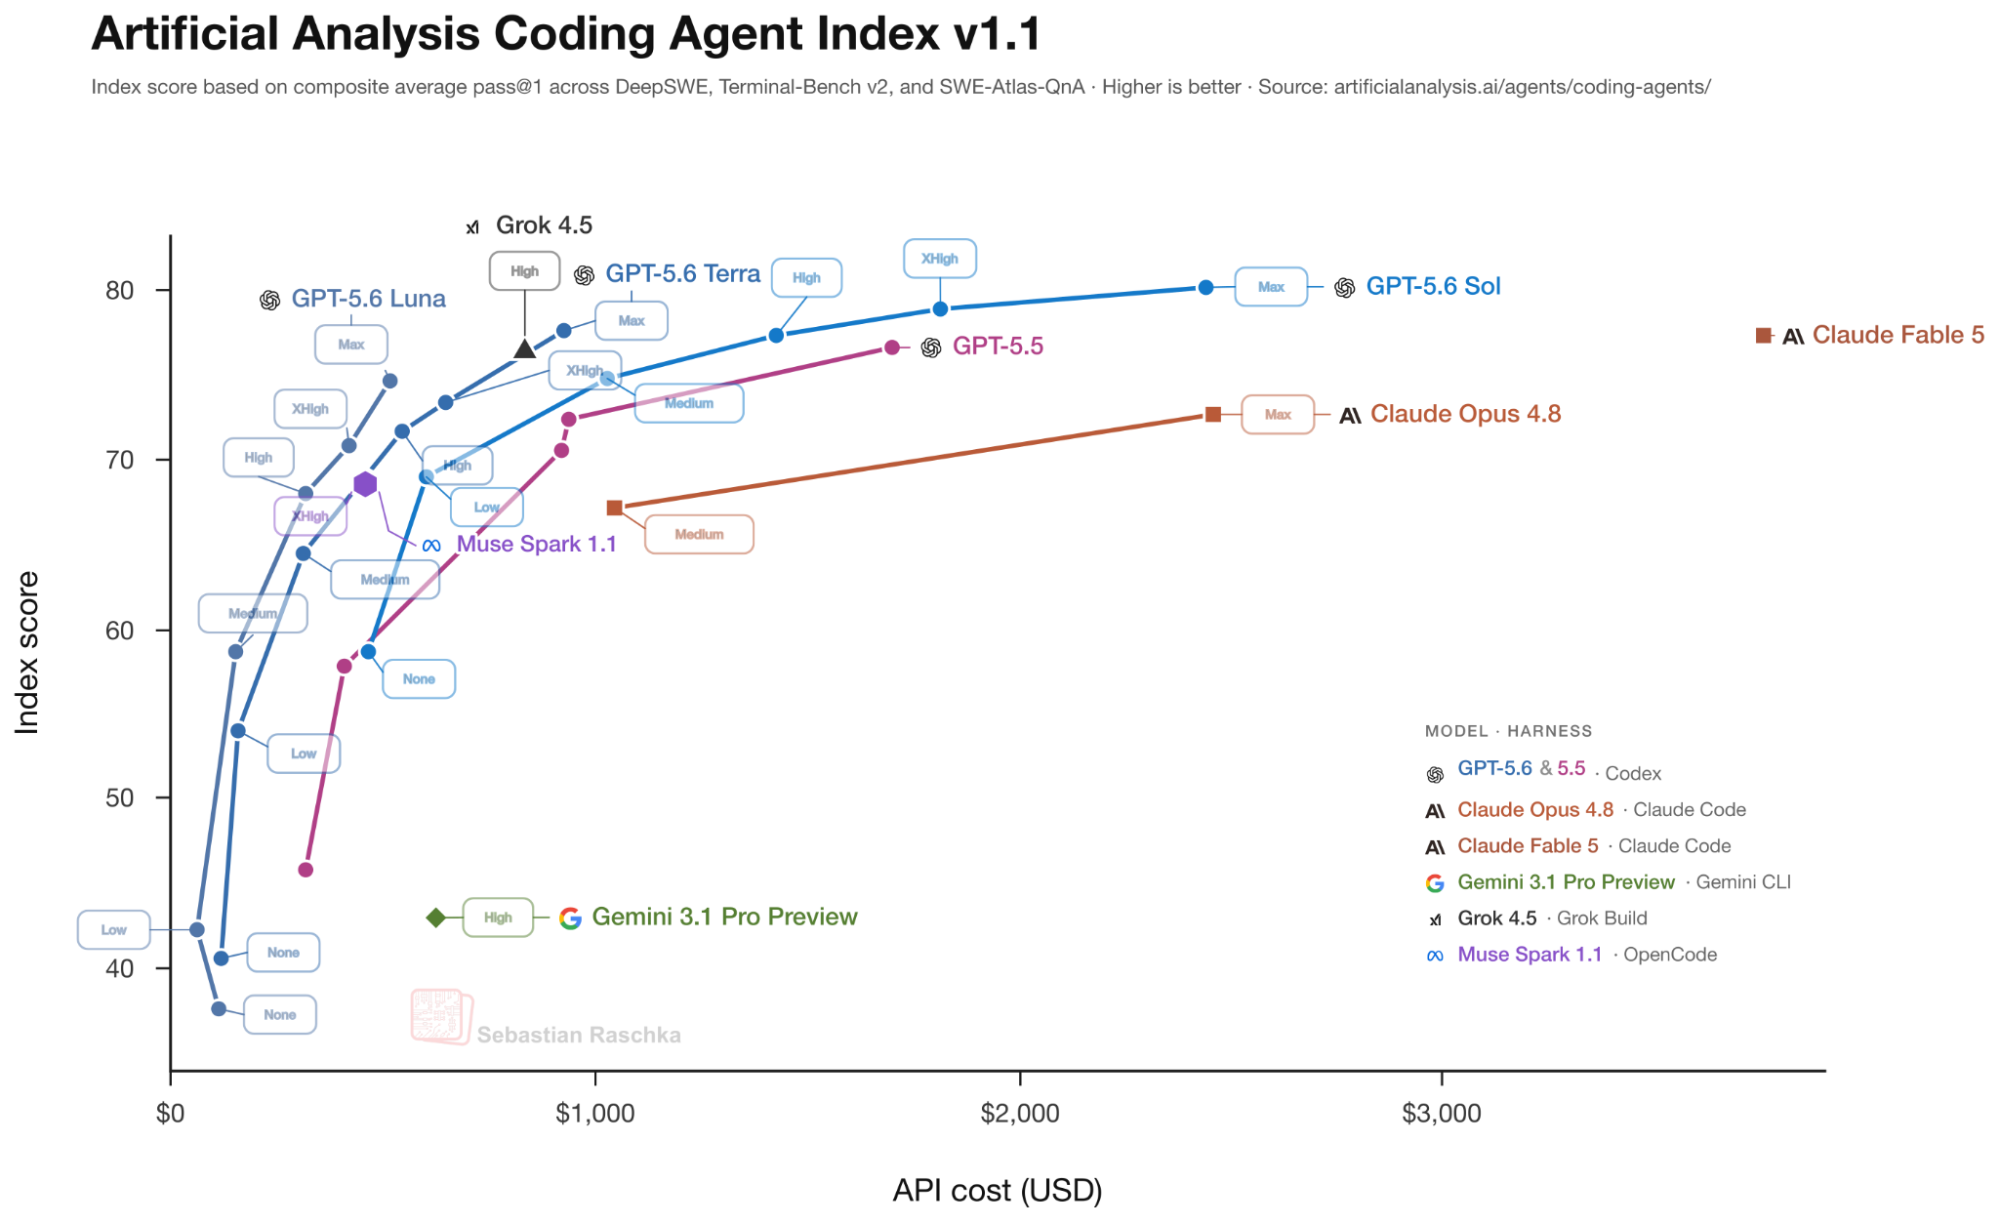
By the way, note how different effort settings scale the response length in the figure above. The effort level seems directly correlated to token usage, which in turn seems correlated to accuracy. It might be possible to come up with effort settings beyond the “high” one, but I assume performance would saturate at some point. This saturation can be seen more clearly for the GPT 5.6 Sol model, which also shows that increasing reasoning budgets can become uneconomical at some point.
Another good, very recent data point that shows the relationship between reasoning effort, token usage, and benchmark performance is this week’s new open-weight Inkling release by Thinking Machine Labs.
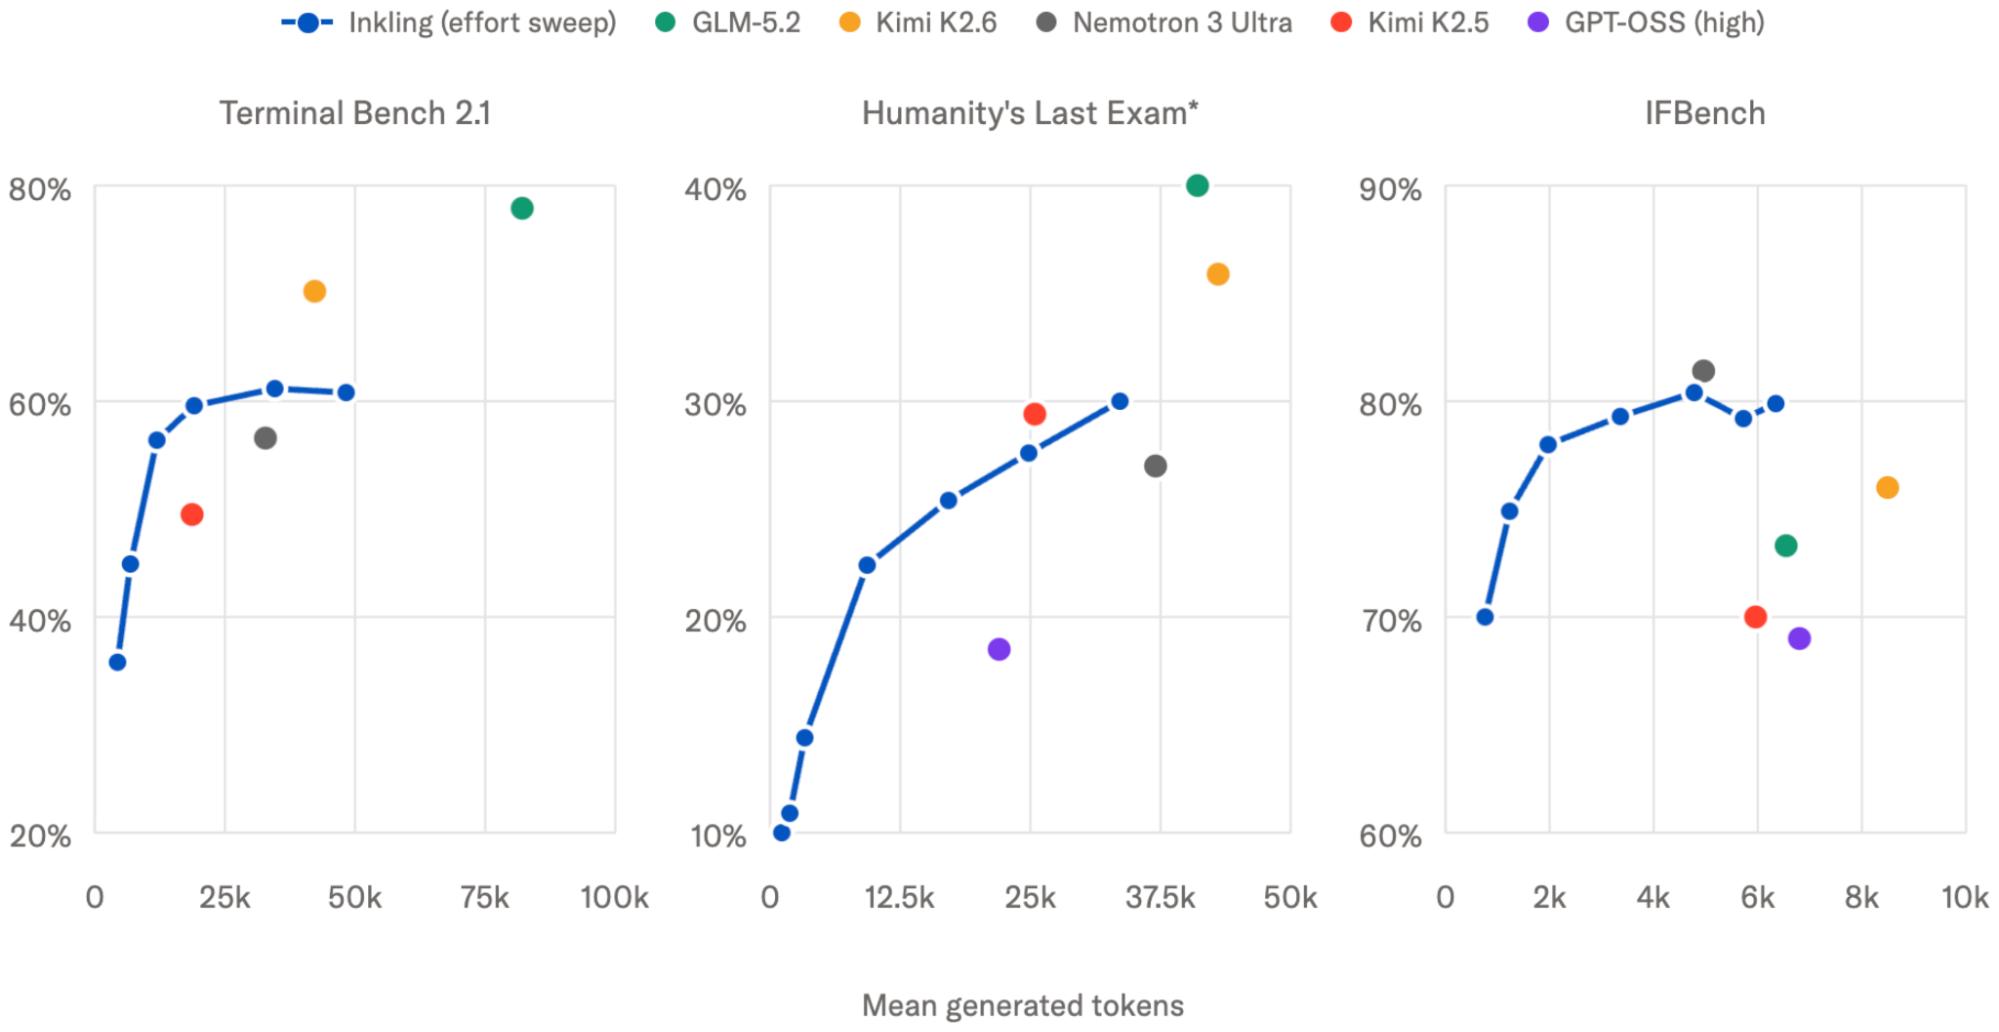
As discussed in this section, during inference, the reasoning effort level can simply be controlled via a system prompt. (The ChatGPT UI presumably simply maps the menu choice to a system prompt.) However, this would not work for an arbitrary model and requires certain modifications to the training pipeline, which will be discussed next.
中文译文 10
366 字他们的 GPT-5 模型,包括近期的 GPT-5.6,很可能也采用类似方法。
顺带注意一下,上图中不同强度设置如何改变回答长度:强度档位似乎与 token 用量直接相关,而 token 用量又似乎与准确率相关。也许可以设置比“high”更高的档位,但我认为性能终会在某个点趋于饱和。GPT-5.6 Sol 的这种饱和趋势更明显,也说明增加推理预算到了某个程度后可能不再划算。
本周 Thinking Machine Labs 新发布的开放权重模型 Inkling,也提供了一个很新、很有价值的例子,展示推理强度、token 用量与基准表现之间的关系。 [1]
如本节所述,在推断阶段,可以直接用系统提示控制推理强度。(ChatGPT 界面很可能只是把菜单选择映射为一条系统提示。)但这并不适用于任意模型,而需要对训练流程进行某些调整,下面将讨论这些调整。
上下游
本块首次出现的来源与延伸
来源身份与原文对应;未把链接存在当作事实核验。
保留来源;未独立逐项核验来源身份与原文对应;未把链接存在当作事实核验。
保留来源;未独立逐项核验本块新增 2 项 · 另有 1 项已在前文介绍
判断
对本块内容的判断
保留作者对闭源实现的推测语气;图中数字属于各自来源和测试条件,不是本站实测。
API费用、token数与实际计算量要分开
图1、19、24的横轴是API费用;gpt-oss和Inkling图使用输出长度。收费、模型每个token的计算量与任务设置都会影响比较,不能把美元直接当成算力或把曲线外推到所有任务。
核验与延伸:open-weight Inkling release ↗ · Inkling announcement blog ↗ · Sebastian Raschka · Controlling Reasoning Effort in LLMs ↗
解释
本块首次出现的知识点
本块相关内容已在前文介绍
英文原文 11
241 词 · 1 张图5.2 Possible effort level implementations
While the training details are not public, neither for GPT 5.6 nor the open-source gpt-oss models, typically, the reasoning effort label is included in prompts during post-training.
There are typically two ways to implement this.
First, we can implement it as part of the RLVR process and apply a different length penalty when different system prompts are used. For example, a high length penalty when “Reasoning effort: low” and a mild or no penalty when “Reasoning effort: high”.
Second, we can fine-tune the model after RLVR to follow different effort instructions via supervised fine-tuning (SFT).
For instance, after the core RLVR stage and during SFT, the prompts in the training dataset are paired with target responses that exhibit the desired amount of reasoning. (The targets may be written by humans, generated by another model, or generated and then filtered.)
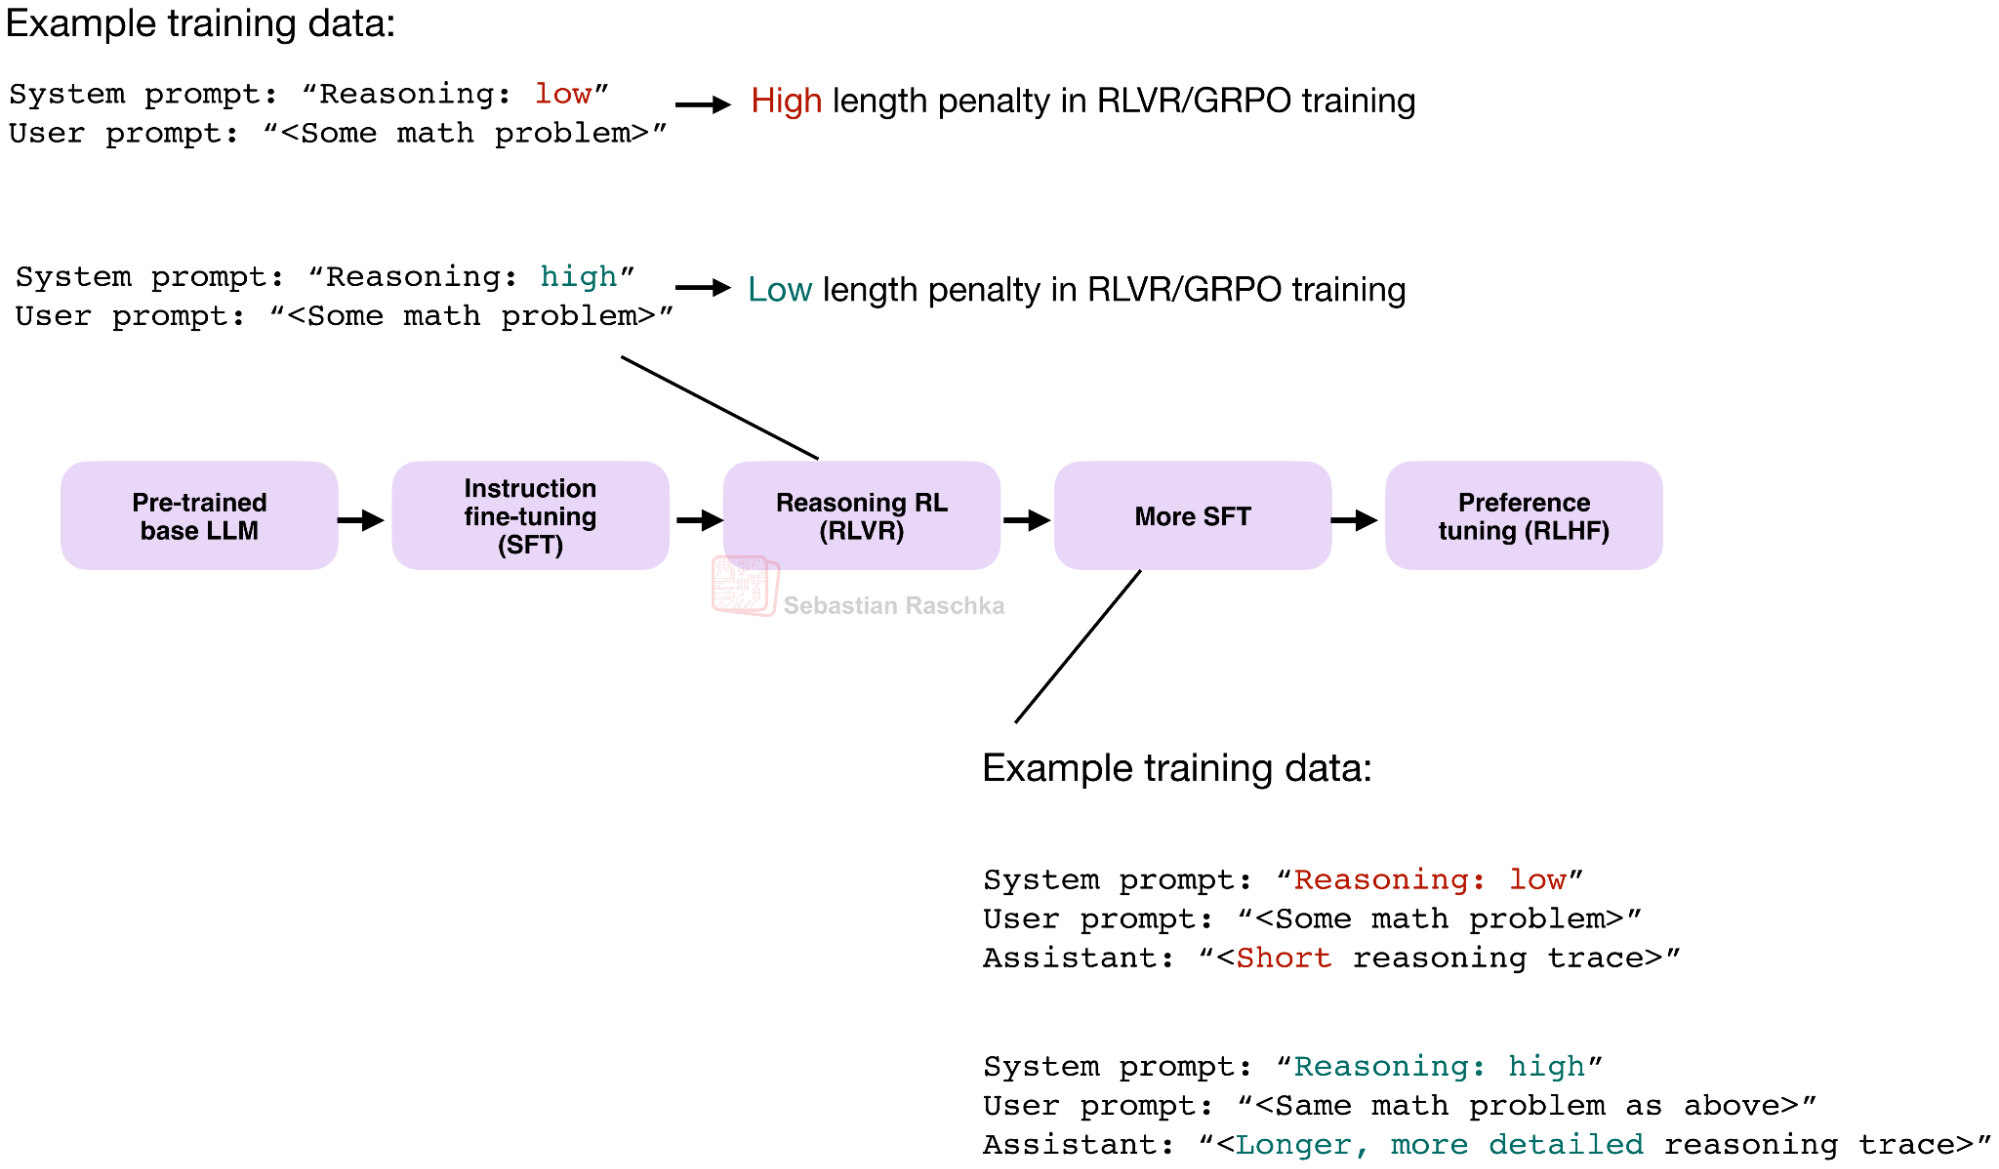
During this SFT stage, the model learns the association between the effort label and the target reasoning length directly from the training examples. An RL-based implementation would instead place the effort labels and budget-aware reward inside the RLVR stage. The two approaches could also be combined, which I suspect was done for both gpt-oss and GPT 5.6 (note that effort settings in GPT 5.6 are likely just changing the system prompt for a given user query).
中文译文 11
381 字5.2 强度档位的可能实现方式
无论 GPT-5.6 还是开源的 gpt-oss,都没有公开相关训练细节。不过,通常会在后训练阶段把推理强度标签加入提示中。
这通常有两种实现方法。
第一种是在 RLVR 过程中实现:针对不同系统提示,使用不同的长度惩罚。例如,当提示是“Reasoning effort: low”时施加较大的长度惩罚;当提示是“Reasoning effort: high”时,则采用较小的惩罚或不施加惩罚。
第二种是在 RLVR 之后通过监督微调(SFT),让模型学会遵循不同的强度指令。
例如,在核心 RLVR 阶段结束后的 SFT 中,训练集中的提示会与体现目标推理量的回答配对。这些目标回答可以由人编写、由其他模型生成,或在生成之后进行筛选。
在这个 SFT 阶段,模型直接从训练示例中学会强度标签与目标推理长度之间的联系。如果使用基于强化学习的实现,则会在 RLVR 阶段加入强度标签和考虑预算的奖励。两种方法也可以结合;我猜测 gpt-oss 和 GPT-5.6 都采用了这种组合。请注意,GPT-5.6 中的强度设置,很可能只是针对同一用户查询改变系统提示。
上下游
本块首次出现的来源与延伸
本块相关内容已在前文介绍
判断
对本块内容的判断
保留作者对闭源实现的推测语气;图中数字属于各自来源和测试条件,不是本站实测。
核验与延伸:Sebastian Raschka · Controlling Reasoning Effort in LLMs ↗
解释
本块首次出现的知识点
本块相关内容已在前文介绍
英文原文 12
208 词 · 1 张图5.3 Inkling case study
The just-released Inkling technical report gives a small but somewhat concrete example of effort-level training.
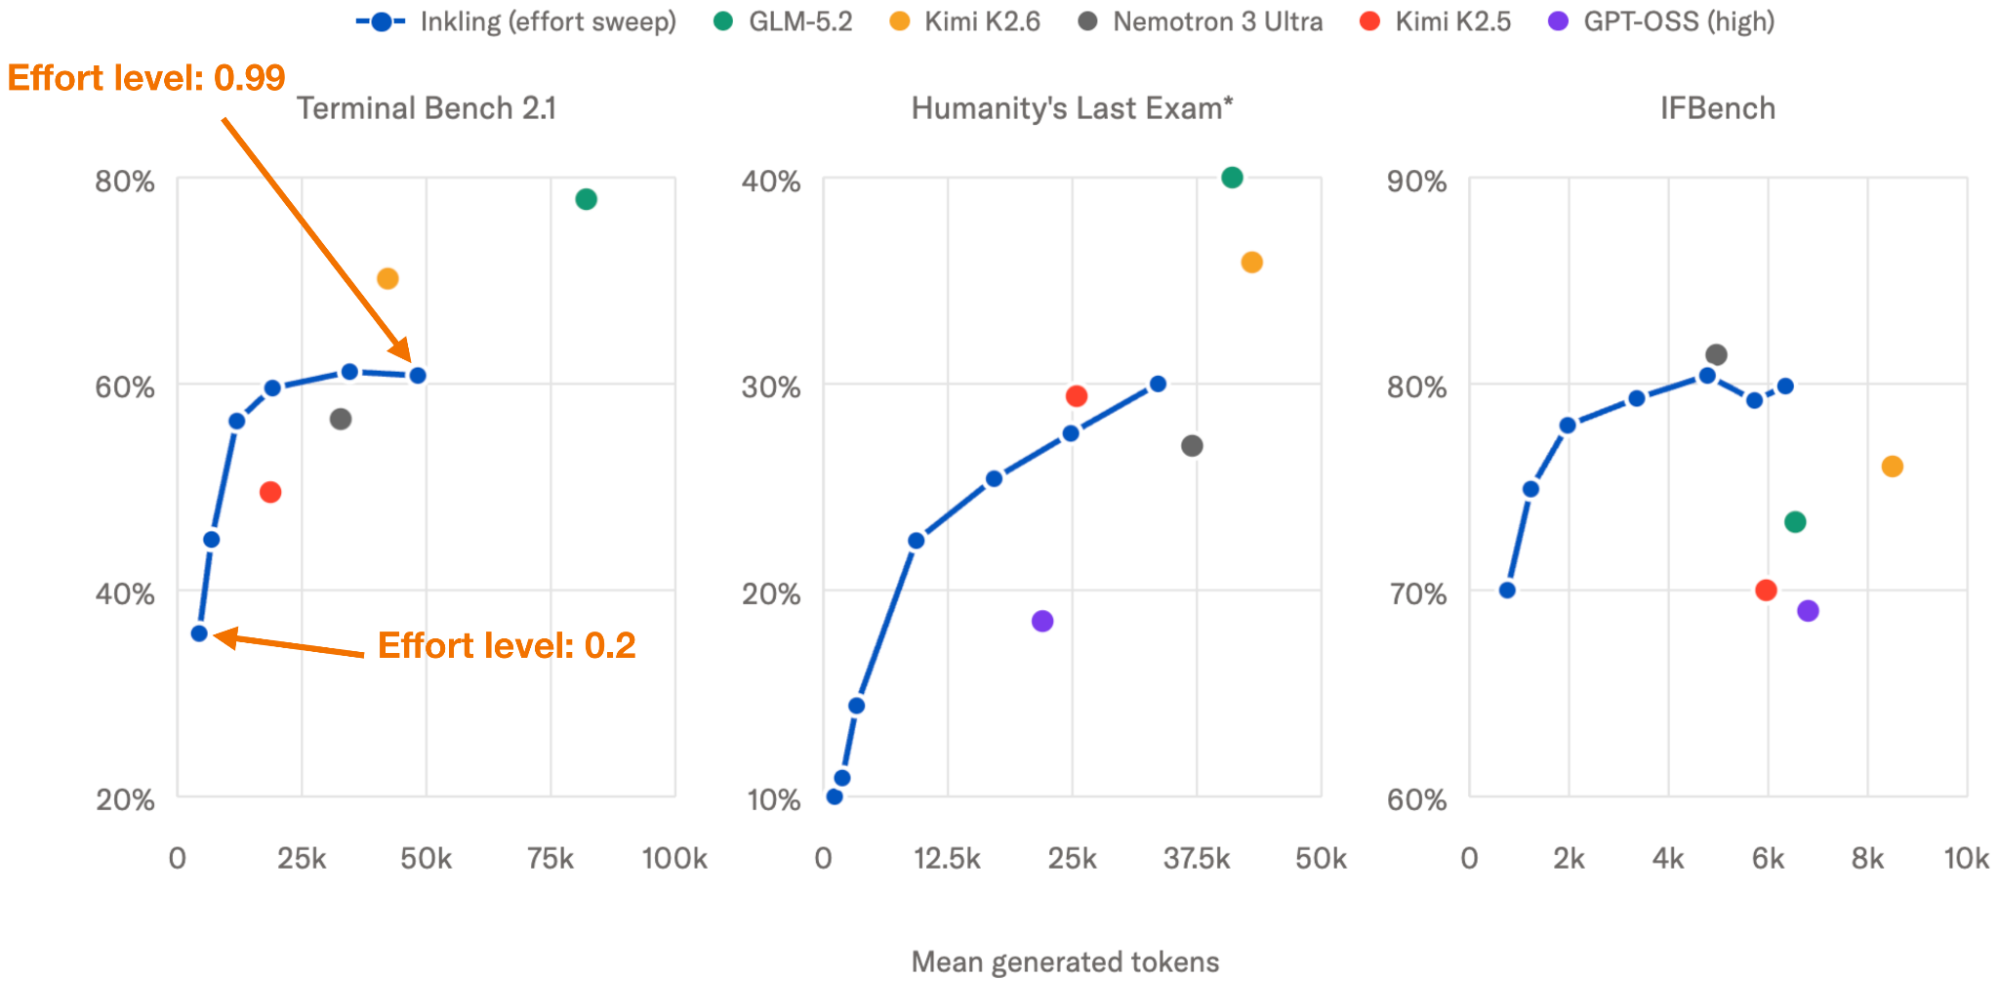
During large-scale RL, they did two things for each sample:
Specified the desired effort level in the system message.
Adjusted the cost assigned to each generated token.
Conceptually, the reward likely looked something like this:
Here, e is the requested effort level and λ(e) controls the token penalty.
Low effort uses a larger per-token cost, encouraging shorter reasoning traces.
High effort uses a smaller per-token cost, allowing the model to spend more tokens.
Then, at inference time, Inkling receives a system message such as Thinking effort level: 0.8, and adjusts its token usage accordingly. The difference between Inkling and models such as gpt-oss and GPT-5.6 is that the effort label is a continuous number between 0 and 1 instead of ordinal labels such as low, medium, and high.
This places Inkling’s effort-level conditioning primarily in the Reasoning RL stage, not only in the later SFT stage.
They do not disclose the exact reward formula, token-cost coefficients, or whether effort conditioning was also included in SFT, though.
中文译文 12
346 字5.3 Inkling 案例研究
刚发布的 Inkling 技术报告,为强度档位训练提供了一个篇幅不多、但相对具体的例子。
在大规模强化学习中,他们对每个样本做了两件事:
在系统消息中指定期望的强度档位。
调整每个生成 token 所对应的成本。
从概念上看,奖励函数可能类似下面这样:
这里,e 是请求的强度值,λ(e) 控制 token 惩罚。
低强度使用更大的单 token 成本,鼓励模型生成较短的推理轨迹。
高强度使用较小的单 token 成本,让模型可以消耗更多 token。
在推断时,Inkling 会收到类似“Thinking effort level: 0.8”的系统消息,并相应调整 token 用量。Inkling 与 gpt-oss、GPT-5.6 等模型的区别在于:它的强度标签是 0 到 1 之间的连续数值,而不是 low、medium、high 这样的有序档位。
这意味着,Inkling 主要在推理强化学习阶段引入强度条件,而不只是到后续 SFT 阶段才加入。
不过,他们没有披露确切的奖励公式、token 成本系数,以及 SFT 阶段是否也加入了强度条件。
上下游
本块首次出现的来源与延伸
本块相关内容已在前文介绍
判断
对本块内容的判断
保留作者对闭源实现的推测语气;图中数字属于各自来源和测试条件,不是本站实测。
核验与延伸:Sebastian Raschka · Controlling Reasoning Effort in LLMs ↗
解释
本块首次出现的知识点
本块相关内容已在前文介绍
英文原文 13
245 词 · 1 张图5.4 A short note about inference scaling versus training scaling
Before moving on to the reasoning effort papers, I want to briefly connect this section back to the earlier “2.3 Inference scaling in a nutshell” section.
Earlier, I separated scaling into training compute scaling and inference-time scaling. The GPT-5.6 interface provides a nice way to illustrate the difference, as shown below.
On the left, selecting Luna, Terra, or Sol changes the model itself. As a rough analogy, this corresponds to training compute scaling. These are separate trained models. At a fixed training recipe and dataset size, a larger model requires more training compute. It also generally requires more compute per generated token.
On the right, we keep the model fixed and only change the reasoning effort. This is inference-time scaling. The model weights stay the same, but the model is allowed to spend fewer or more tokens working on the answer.
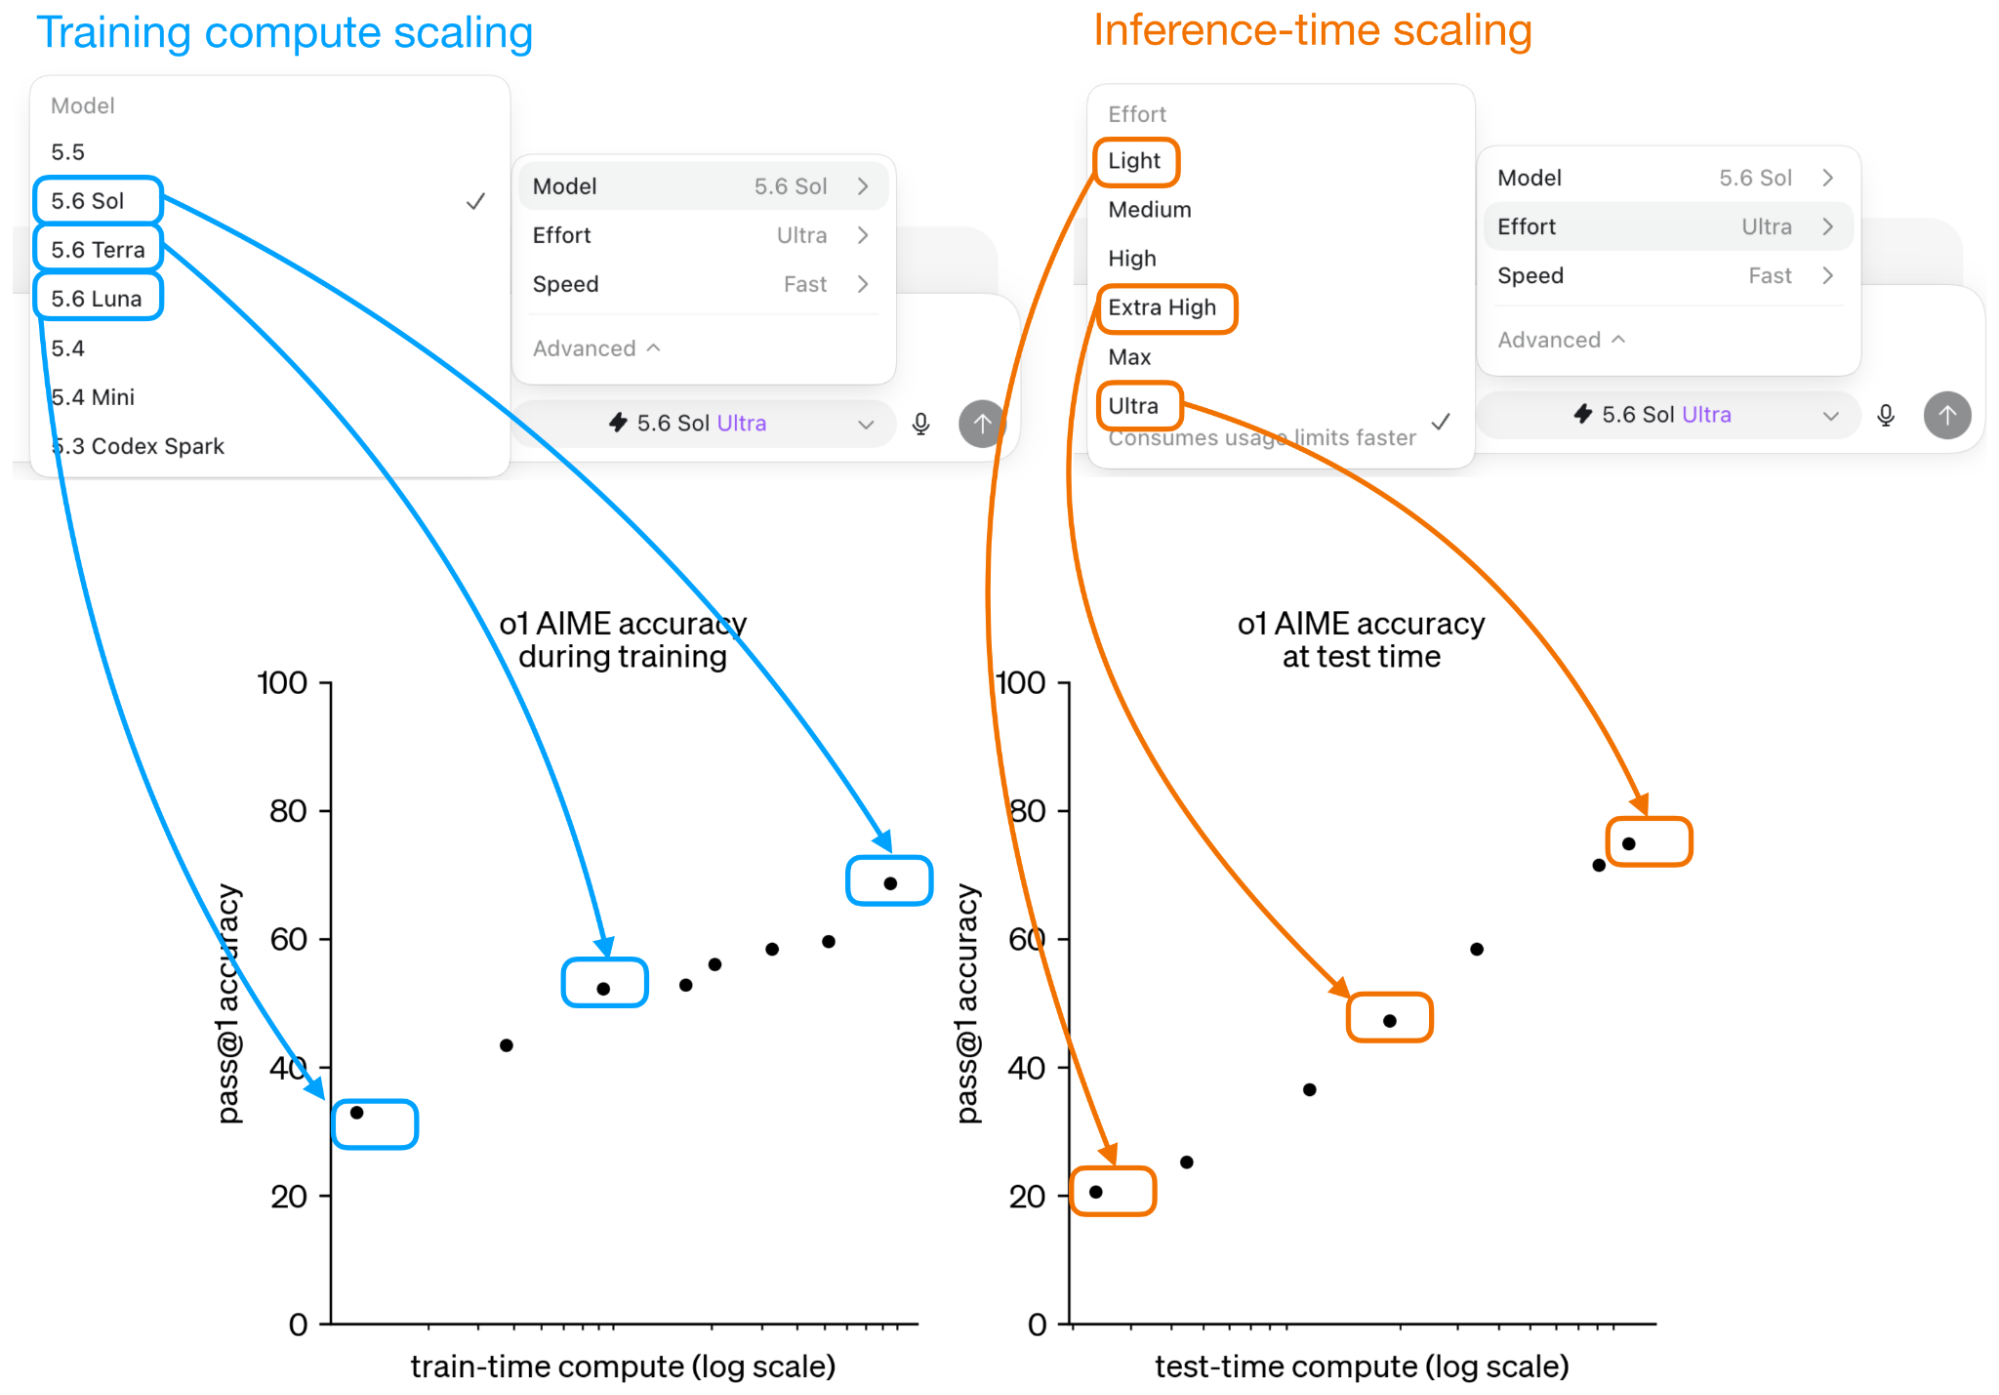
One small terminology caveat is that selecting a different model from the menu is not training scaling at that moment. The training has already happened. It is better to think of the model menu as selecting among models that were produced at different training scales.
The Artificial Analysis results below show how these two axes interact in practice.
中文译文 13
377 字5.4 再谈推断扩展与训练扩展
在进入推理强度相关论文之前,我想先把本节内容与前面的“2.3 推断扩展简述”联系起来。
此前,我把扩展分为训练计算扩展与推断阶段扩展。GPT-5.6 的界面恰好可以很好地说明二者的区别,如下图所示。
左边选择 Luna、Terra 或 Sol,会改变模型本身。粗略类比,这对应训练计算扩展:它们是分别训练出来的模型。在训练方法与数据集规模固定时,更大的模型需要更多训练计算,通常每生成一个 token 也需要更多计算。
右边则保持模型不变,只改变推理强度。这是推断阶段扩展:模型权重不变,但允许模型用更少或更多 token 来推导答案。
这里有一个小小的术语提醒:从菜单里选择另一个模型,并不是在那个时刻进行训练扩展,因为训练早已完成。更准确的理解是:从由不同训练规模产生的模型中作出选择。
下面的 Artificial Analysis 结果展示了这两条轴在实际应用中如何相互作用。
上下游
本块首次出现的来源与延伸
本块相关内容已在前文介绍
判断
对本块内容的判断
保留作者对闭源实现的推测语气;图中数字属于各自来源和测试条件,不是本站实测。
核验与延伸:Sebastian Raschka · Controlling Reasoning Effort in LLMs ↗
解释
本块首次出现的知识点
本块相关内容已在前文介绍
英文原文 14
275 词 · 1 张图Each blue curve corresponds to one model, Luna, Terra, or Sol. Moving along a curve by increasing the reasoning effort is inference scaling. Moving from one model curve to another corresponds to model scaling, which I use here as a practical proxy for training scaling.
As expected, both approaches can improve the benchmark score, but they also increase the cost. More interestingly, the curves overlap. For instance, a smaller model at a higher reasoning effort can sometimes reach a similar score as a larger model at a lower reasoning effort.
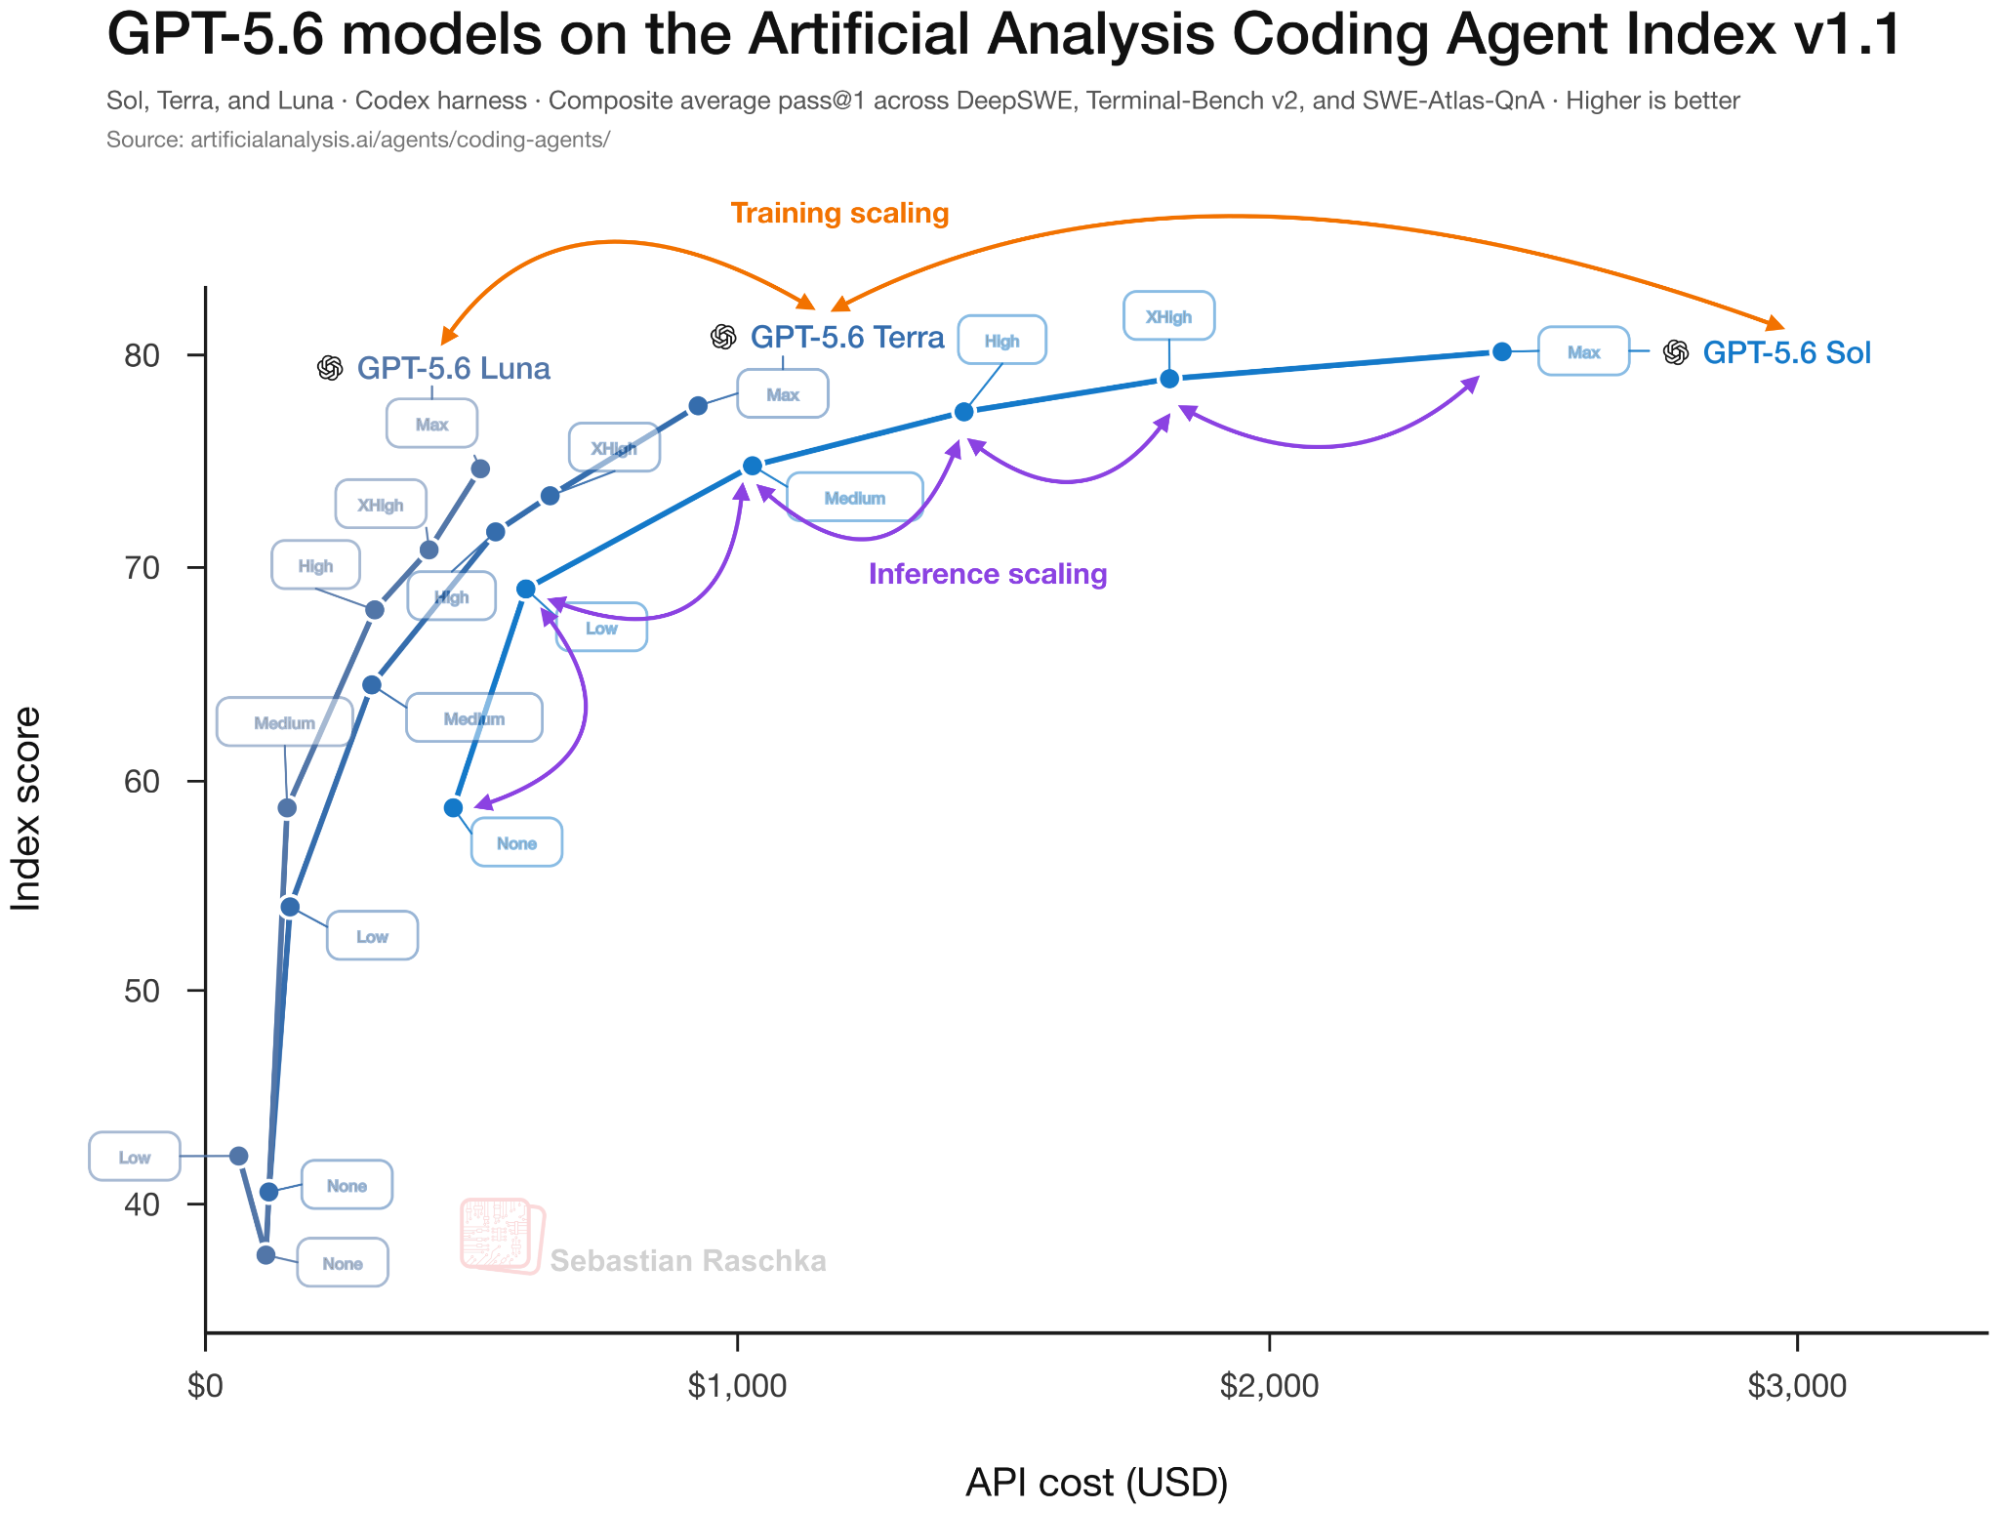
By the way, the x-axis in this figure shows API cost rather than raw compute. The API cost is a useful practical measure, but it also depends on the provider’s pricing and the number of generated tokens. Also, the exact shape of these curves is benchmark-specific.
So, the model size and reasoning effort form two separate knobs. We can use a larger model, increase the reasoning effort, or combine both. Which combination is best depends on the desired accuracy, cost, and latency.
So far, the article should give you a pretty solid understanding of how reasoning effort modes work and how they are implemented. This is a fine point to wrap the article if you are short on time. Otherwise, if you want to look into some of the nitty-gritty details of some of the recent open-weight models, please read on!
中文译文 14
409 字每条蓝色曲线都对应一个模型:Luna、Terra 或 Sol。通过提高推理强度沿曲线移动,属于推断扩展;从一条模型曲线转到另一条,则对应模型规模扩展,这里把它作为训练扩展的实用近似。
正如预期,两种方式都能提高基准分数,也都会增加成本。更有意思的是,曲线之间存在重叠。例如,较小模型在较高推理强度下,有时能达到较大模型在较低强度下的相近分数。
顺带一提,这张图的横轴表示 API 成本,而不是原始计算量。API 成本是一个实用指标,但它也取决于服务商定价和生成 token 数。此外,曲线的具体形状与所选基准有关。
因此,模型规模与推理强度是两个不同的调节旋钮。我们可以用更大的模型、提高推理强度,或把两者结合。哪种组合最好,取决于所需的准确率、成本与延迟。
读到这里,你应该已经比较扎实地理解了推理强度模式如何工作,以及它们怎样实现。如果时间有限,读到这里就可以结束。如果还想深入了解近期一些开放权重模型的细节,请继续往下读!
上下游
本块首次出现的来源与延伸
本块相关内容已在前文介绍
判断
对本块内容的判断
保留作者对闭源实现的推测语气;图中数字属于各自来源和测试条件,不是本站实测。
核验与延伸:Sebastian Raschka · Controlling Reasoning Effort in LLMs ↗
解释
本块首次出现的知识点
本块相关内容已在前文介绍
英文原文 15
285 词 · 1 张图6. Bonus: Different ways to implement reasoning efforts (in flagship open-weight LLMs)
[This section is fine to skip unless you are interested in some additional details]
Section 5 described two possible ways to train reasoning-effort controls, namely effort-conditioned supervised fine-tuning and reinforcement learning with different token costs. Originally, I wanted to cover research articles on alternative ways to implement reasoning budgets. However, reading through most of these articles, they seemed more like proofs-of-concept that may or may not work well in practice.
So, instead of covering those, I decided to pivot a bit and cover those recipes used by state-of-the-art and notable open-weight (flagship) LLMs. For these models, there is at least evidence that the methods work in practice.
This leaves six examples. DeepSeek V4, Nemotron 3 Ultra, Kimi K2.5, GLM-5, Qwen3, and Inkling. They have different levels of detail in their reporting, but each contributes a useful variation. (I exclude models whose reports only show an effort setting in the user interface without explaining how that behavior was trained.)
6.1 DeepSeek V4 trains separate effort specialists
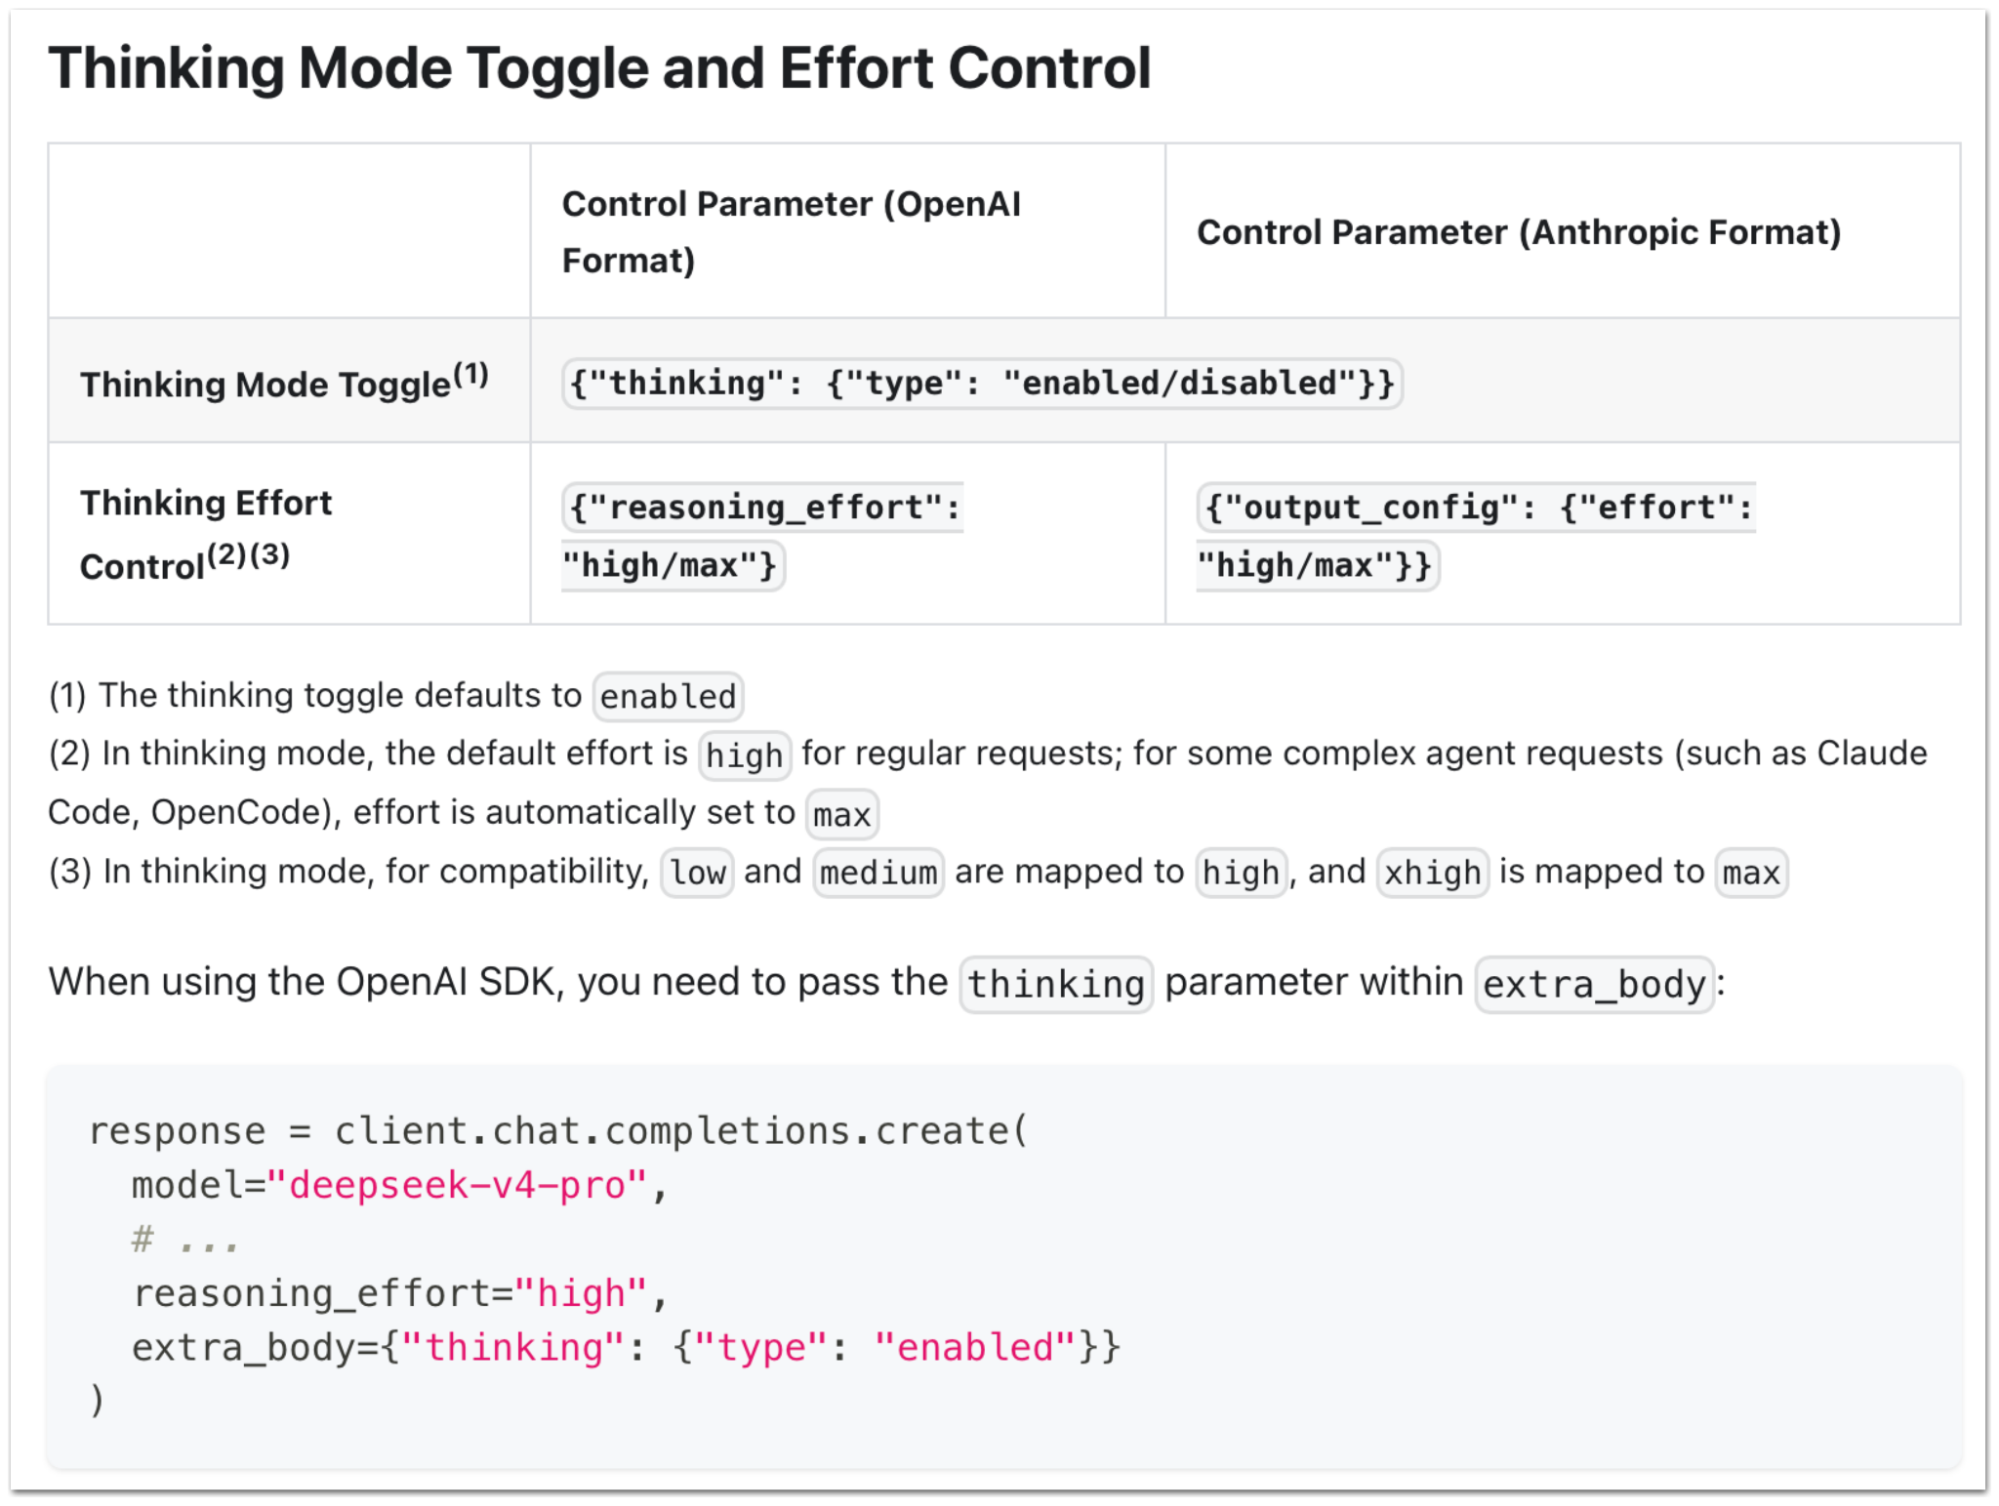
Let’s start with the DeepSeek V4 technical report, which describes the use of three modes:
Non-think produces a direct response without a reasoning trace.
Think High is the classic approach where the model places the reasoning trace between <think> and </think> tags. This is similar to what was discussed in the DeepSeek R1 section (section 2) at the beginning of this article.
Think Max is the same as above but adds a special system instruction. (More on that below.)
The additional system prompt instruction for Think Max starts with “Reasoning Effort: Absolute maximum with no shortcuts permitted.”
中文译文 15
460 字6. 加餐:旗舰开放权重模型实现推理强度的不同方式
[如果你不想了解更多细节,可以跳过本节。]
第 5 节介绍了两种训练推理强度控制的方法:以强度为条件的监督微调,以及采用不同 token 成本的强化学习。原本我打算介绍一些用其他方式实现推理预算的研究论文,但读过其中的大多数之后,我觉得它们更像是概念验证,实际应用时未必有良好效果。
因此,我决定稍微转个方向,介绍那些最先进、值得关注的开放权重旗舰模型所采用的方法。至少对于这些模型,已有证据表明这些方法能在实践中发挥作用。
这样筛选后,留下六个例子:DeepSeek V4、Nemotron 3 Ultra、Kimi K2.5、GLM-5、Qwen3 和 Inkling。它们报告细节的程度各不相同,但都提供了一种有价值的变体。(如果报告只是展示界面中的强度设置,却不解释这种行为如何训练得到,我就没有将其纳入。)
6.1 DeepSeek V4 分别训练不同强度的专家模型
先从 DeepSeek V4 技术报告开始,它描述了三种模式: [1] [2]
Non-think:直接生成回答,不输出推理轨迹。
Think High:采用经典方式,把推理轨迹放在 <think> 与 </think> 标签之间。这与本文开头第 2 节讨论的 DeepSeek-R1 类似。
Think Max:与上面相同,但额外加入一条特殊的系统指令,后面会详细说明。
Think Max 额外系统指令的开头是:“Reasoning Effort: Absolute maximum with no shortcuts permitted.”,意思是“推理强度:绝对最高,不允许任何捷径”。
上下游
本块首次出现的来源与延伸
保留原文提供的资源地址,供查看对应材料和上下文。
原文链接;未将未核验内容当作新证据来源身份与原文对应;未把链接存在当作事实核验。
保留来源;未独立逐项核验来源身份与原文对应;未把链接存在当作事实核验。
保留来源;未独立逐项核验本块新增 3 项 · 另有 1 项已在前文介绍
判断
对本块内容的判断
保留作者对闭源实现的推测语气;图中数字属于各自来源和测试条件,不是本站实测。 本节按作者整理的模型报告译出;没有把不同基座和任务下的结果当作受控横向排名。
后半篇模型配方是作者对报告的整理
DeepSeek V4、Nemotron、Kimi、GLM和Inkling的具体配方按作者原文翻译。本站未逐项复现训练,也未把作者汇总表变成方法优劣排行榜;教师数量、奖励系数和未知细节保持原文边界。
核验与延伸: ↗ · DeepSeek V4 technical report ↗ · DeepSeek V4 documentation ↗ · Sebastian Raschka · Controlling Reasoning Effort in LLMs ↗
解释
本块首次出现的知识点
本文解释:专家与统一模型
训练多个专家,再把行为汇集到一个学生模型,与部署时每次都调用所有专家不同。图中教师池说明训练来源,不能直接推断线上每次请求的并发方式。
本块新增 1 项 · 另有 2 项已在前文介绍
英文原文 16
266 词 · 1 张图At first, this sounds like a simple prompt engineering trick, but this prompt is actually backed by a different training setup. That is, each mode uses its own context window and length penalty (unfortunately, the exact length penalty implementation is not detailed in this report). Think Max receives a longer context window and a smaller length penalty than Think High, which gives it more room to continue reasoning.
So, the system instruction selects a behavior that was created during post-training. Adding the same instruction to an arbitrary model would not have the same effect.
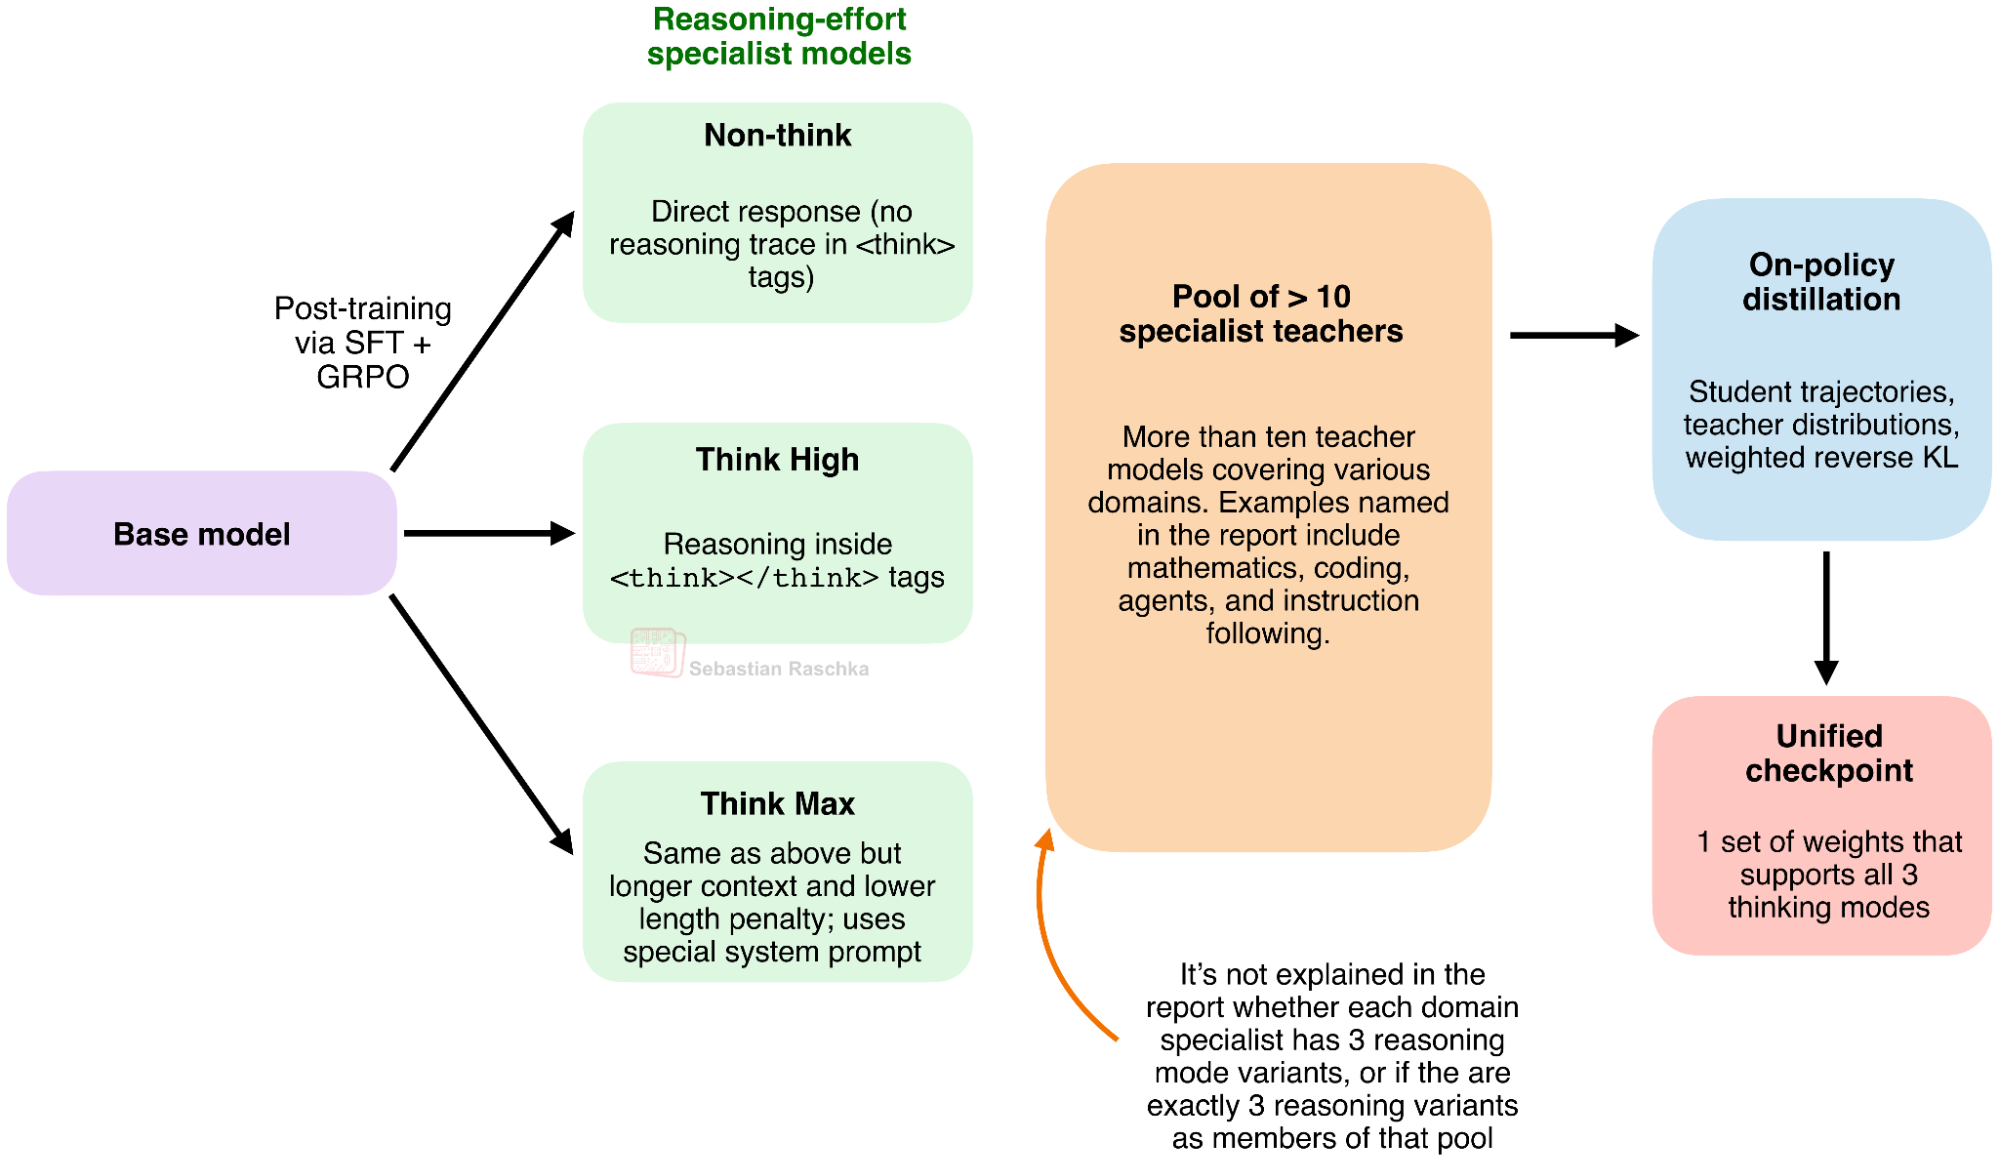
Unfortunately, the public, and otherwise very detailed DeepSeek V4 report does not connect the descriptions of the reasoning mode and domain specialists in enough detail to reconstruct the exact teacher assignment.
However, the report states that the final model, which supports different reasoning effort levels, was created via on-policy distillation from said teachers.
To summarize, DeepSeek V4 develops the three reasoning specialists during post-training. Starting from the base model, it applies supervised fine-tuning followed by RLVR via GRPO. The RL configuration differs for each mode. In particular, each specialist uses its own context window and length penalty, while Think Max additionally receives a special system instruction.
Then, including domain specialists, the different reasoning mode specialists are distilled into a single checkpoint that supports all three effort modes.
中文译文 16
441 字乍一听,这像是一个简单的提示工程技巧,但它实际上对应不同的训练设置。每种模式都有自己的上下文窗口与长度惩罚;遗憾的是,报告没有详细说明长度惩罚如何实现。与 Think High 相比,Think Max 使用更长的上下文窗口和更小的长度惩罚,让模型有更大空间继续推理。
因此,系统指令所选择的行为,是在后训练中形成的。把同样的指令加给任意一个模型,并不会产生同样的效果。
遗憾的是,DeepSeek V4 的公开报告虽然在其他方面十分详细,却没有充分连接推理模式与领域专家的描述,因此无法还原教师模型的确切分配方式。
不过,报告指出,最终支持不同推理强度的模型,是通过对这些教师进行同策略蒸馏得到的。
总结来说,DeepSeek V4 在后训练阶段形成三类推理专家。从基础模型出发,先进行监督微调,再通过 GRPO 实施 RLVR。每种模式的强化学习配置不同:各专家使用不同的上下文窗口和长度惩罚,Think Max 还会额外收到特殊系统指令。
随后,包括领域专家在内的不同推理模式专家,被蒸馏到同一个检查点中,使它支持全部三种强度模式。
上下游
本块首次出现的来源与延伸
本块相关内容已在前文介绍
判断
对本块内容的判断
本节按作者整理的模型报告译出;没有把不同基座和任务下的结果当作受控横向排名。
核验与延伸:Sebastian Raschka · Controlling Reasoning Effort in LLMs ↗
解释
本块首次出现的知识点
本块相关内容已在前文介绍
英文原文 17
311 词 · 1 张图6.2 Nemotron 3 Ultra combines learned modes with hard budgets
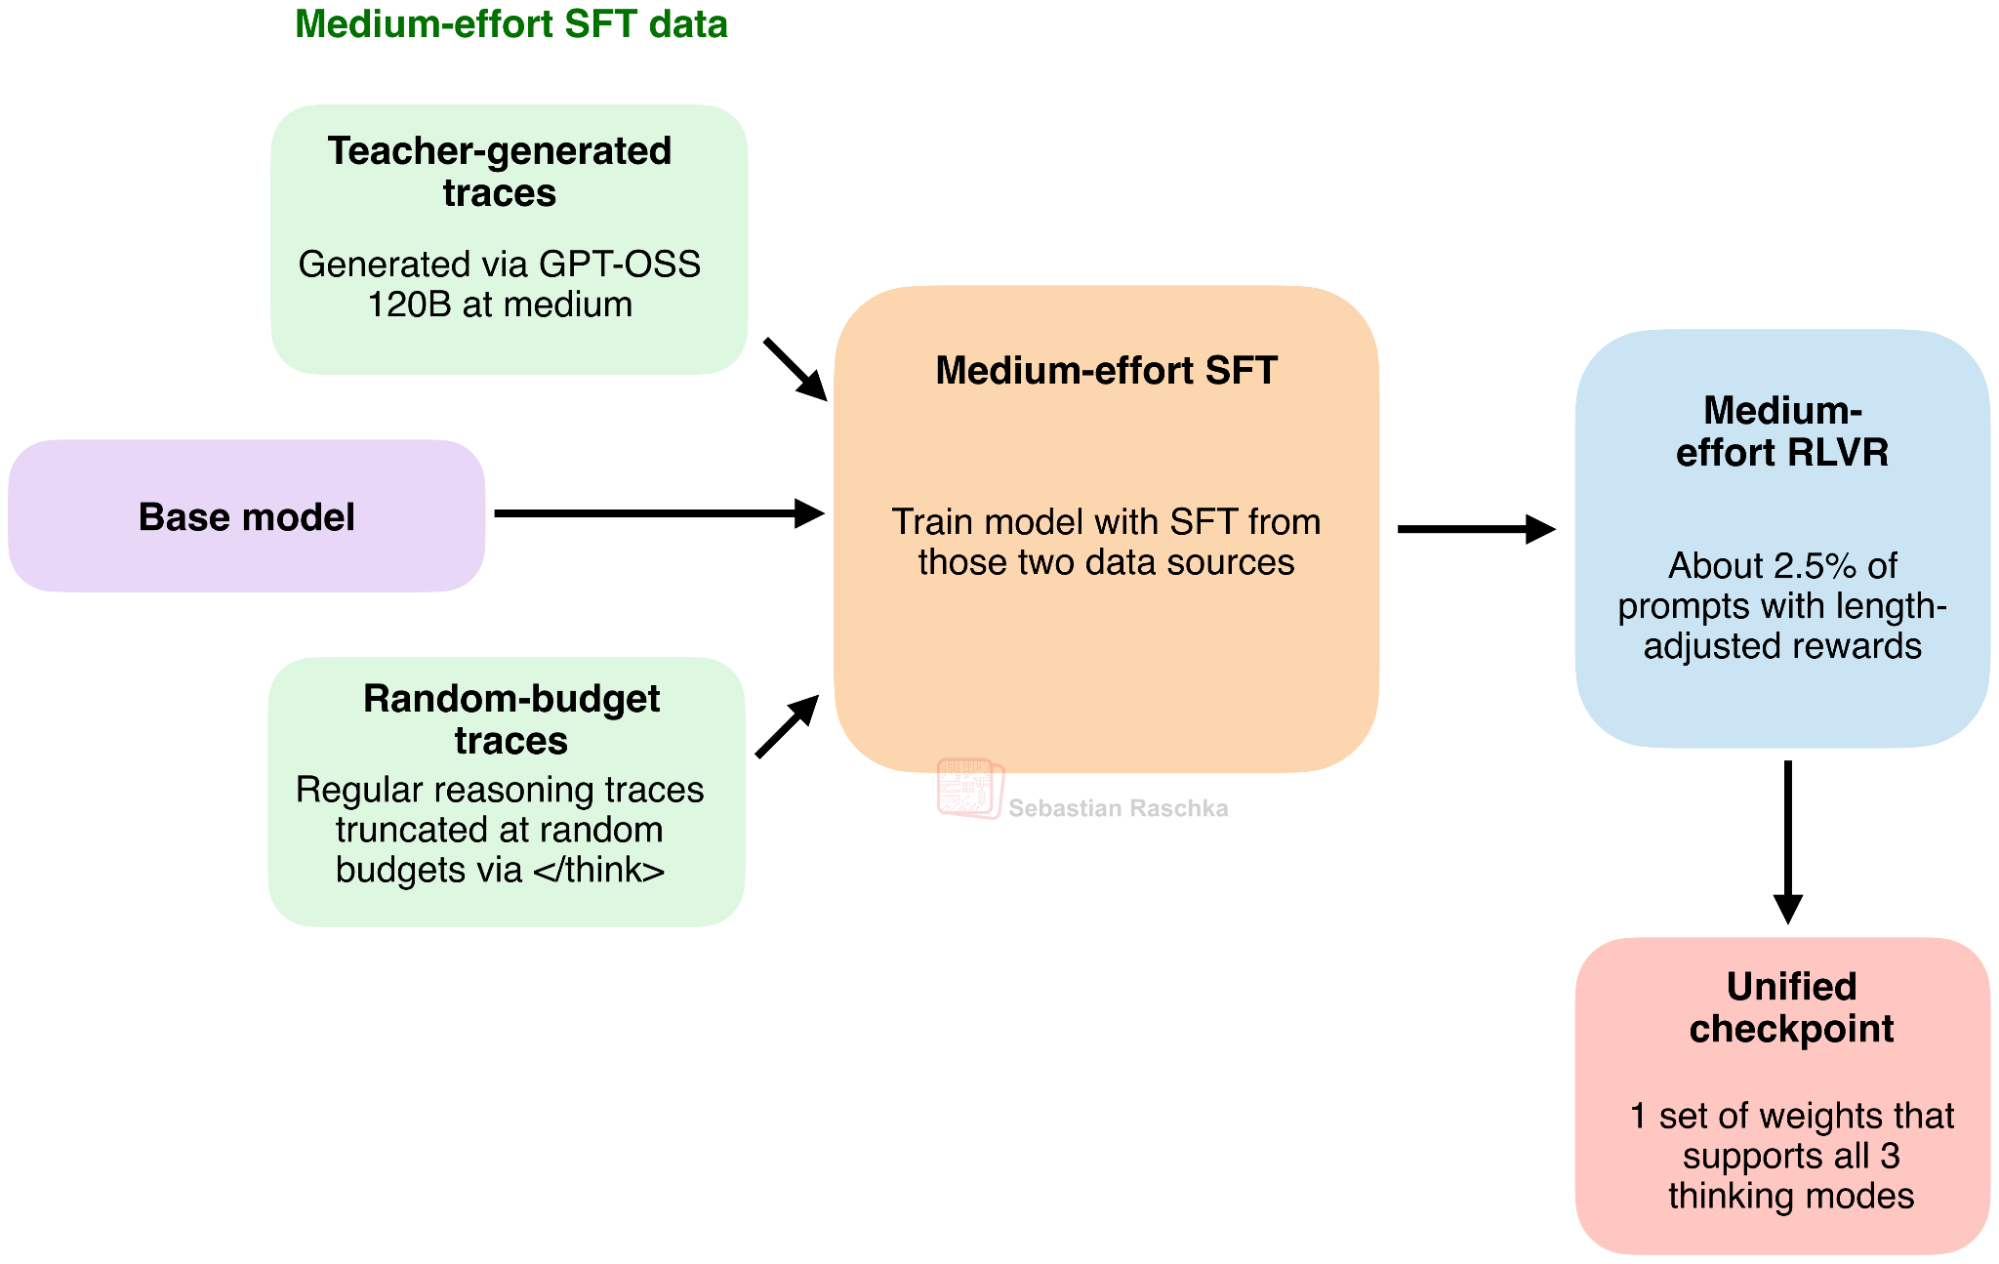
The Nemotron 3 Ultra technical report describes three settings called reasoning-off, regular, and medium-effort, analogous to DeepSeek V4 in the previous section. Medium-effort is the cheaper reasoning mode compared with regular. NVIDIA introduces this mode during SFT using examples generated by GPT-OSS-120B in its medium-effort mode, and then further optimizes it during RLVR. About 2.5% of the RLVR prompts use medium-effort (this corresponds to length-based adjustments applied to their rewards).
6.2.1 Using Nemotron reasoning budgets during inference
At inference time, all three modes are selected through the chat template.
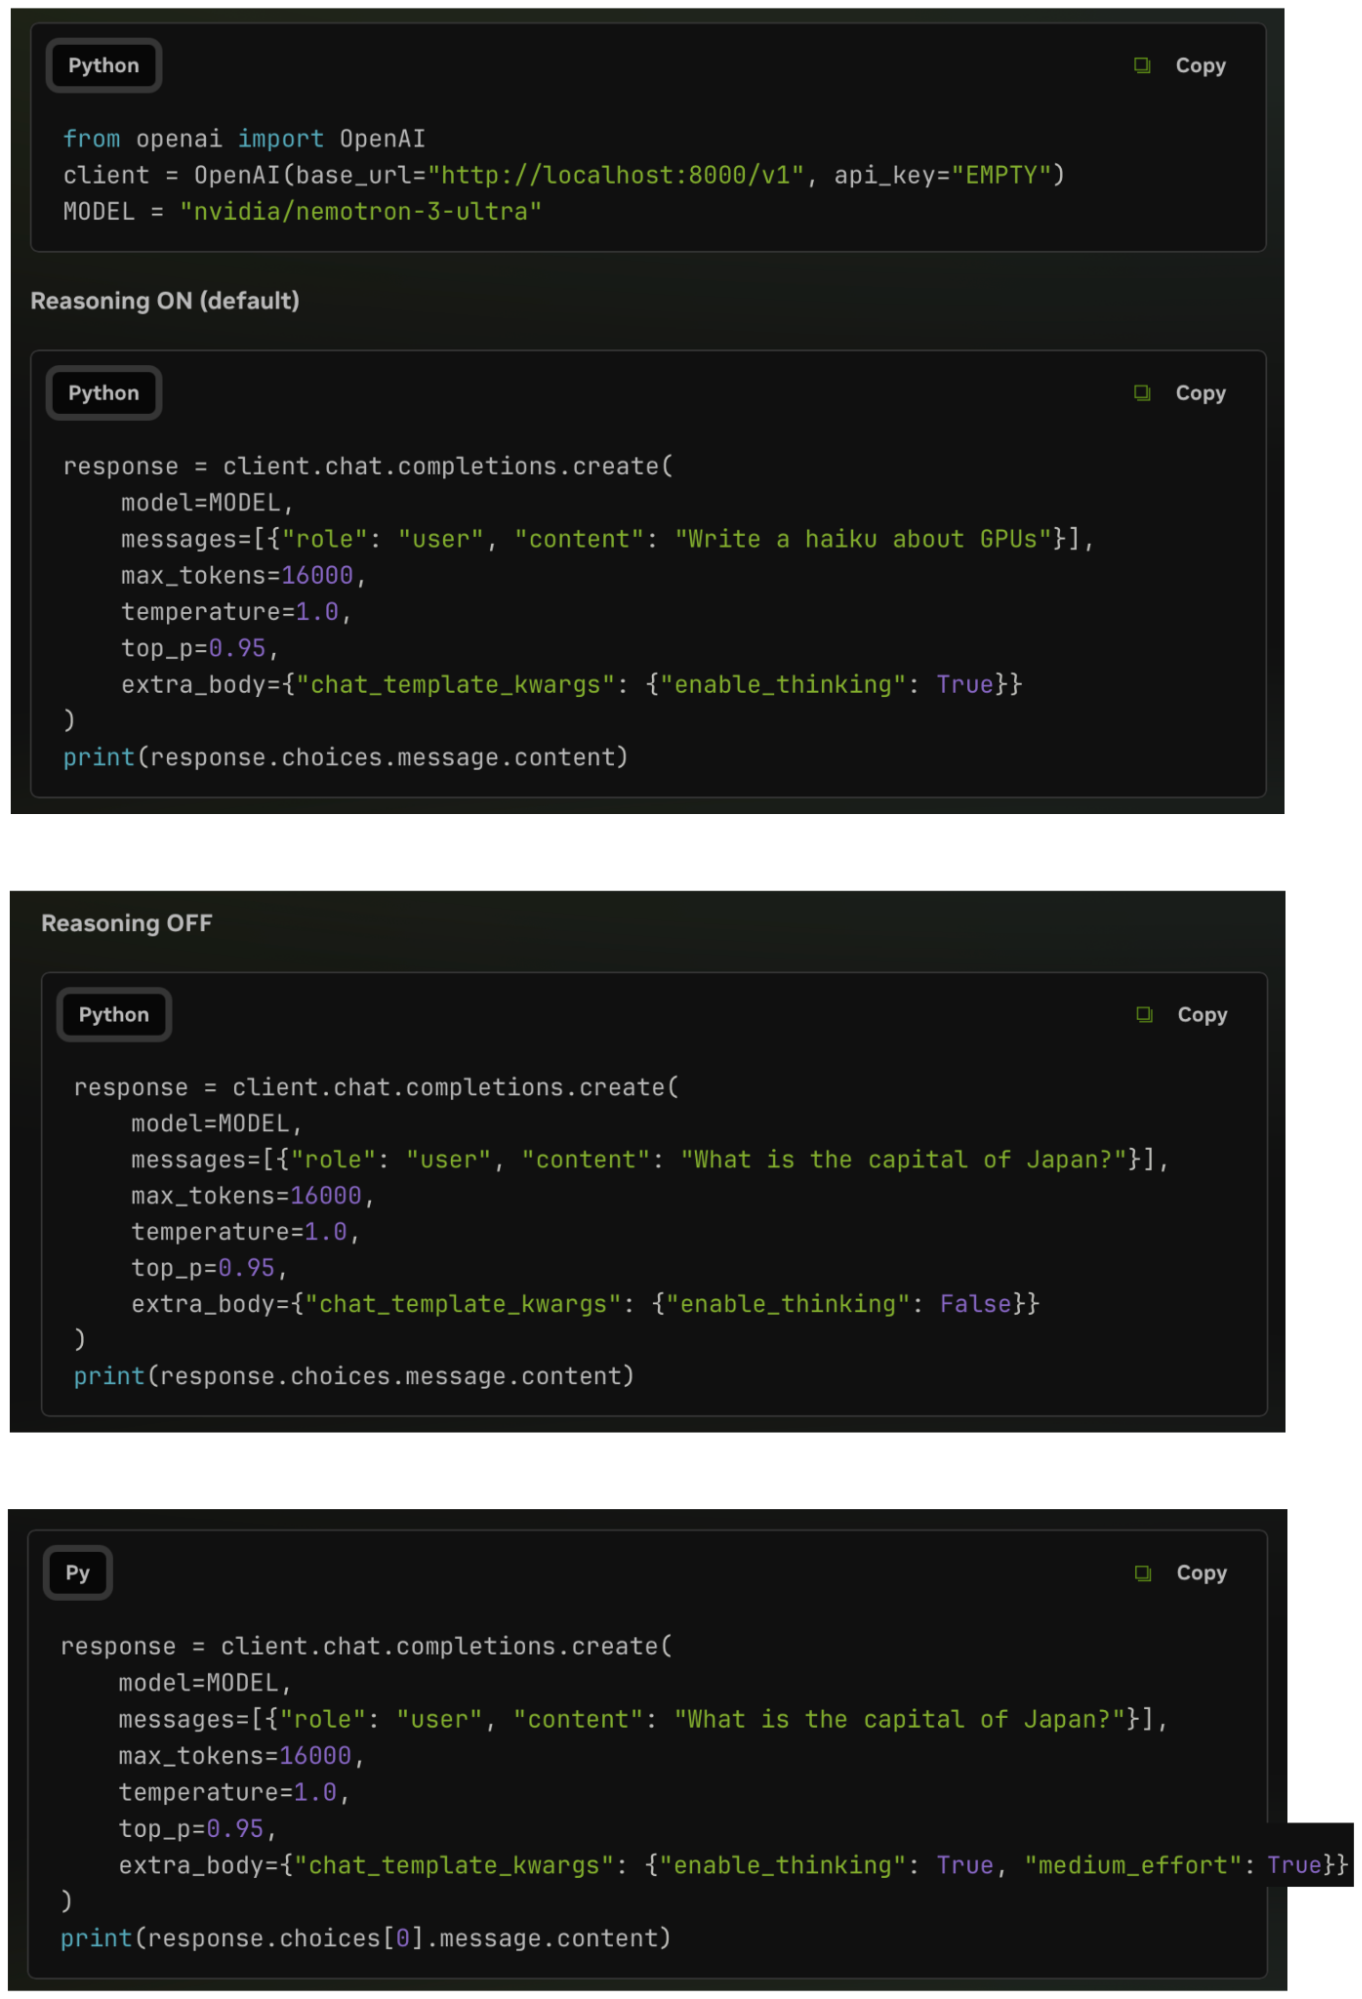
1) Regular is the default and uses enable_thinking=True, which starts the assistant response with an opening <think> tag.
2) Medium-effort uses enable_thinking=True together with medium_effort=True where the latter setting also appends {reasoning effort: efficient} to the latest user message.
By the way, to further complicate things, the regular and medium-effort modes can also be combined with a separate inference-time reasoning budget. This budget acts as an external stopping mechanism. In the released implementation, the chat client asks the model to end the reasoning trace near the chosen token limit. If the model has not emitted </think>, the client closes the reasoning block and continues generation to produce the final answer. The learned effort mode determines how the model uses its reasoning tokens, while the budget constrains how long the reasoning trace can continue. This makes it possible to pair either mode with a tighter or looser budget depending on the desired cost and accuracy.
3) Reasoning-off uses enable_thinking=False, which prefills an empty <think></think> block (similar to Qwen3 discussed in section 4) so that the model proceeds directly to the final response. Thus, these are chat-template controls rather than system prompts.
中文译文 17
459 字6.2 Nemotron 3 Ultra 将学得的模式与硬性预算结合
Nemotron 3 Ultra 技术报告描述了 reasoning-off、regular 和 medium-effort 三种设置,与上一节的 DeepSeek V4 类似。相比 regular,medium-effort 是成本更低的推理模式。NVIDIA 在 SFT 阶段使用 GPT-OSS-120B 的 medium-effort 模式生成示例,以引入这种行为,然后在 RLVR 阶段进一步优化。约 2.5% 的 RLVR 提示采用 medium-effort 设置,对应在奖励中引入基于长度的调整。 [1] [2]
6.2.1 在推断时使用 Nemotron 的推理预算
1)Regular 是默认模式,使用 enable_thinking=True,让助手回答以一个打开的 <think> 标签开头。
2)Medium-effort 同时使用 enable_thinking=True 和 medium_effort=True。后一个设置还会在最近一条用户消息末尾附加 {reasoning effort: efficient}。
另外,让情况更复杂一点的是:regular 与 medium-effort 还可以搭配一个独立的推断阶段推理预算。这个预算是一种外部停止机制。在已发布的实现中,聊天客户端会要求模型在接近所选 token 上限时结束推理轨迹。如果模型还没有输出 </think>,客户端就会关闭推理块,再继续生成最终答案。学得的强度模式决定模型如何使用推理 token,而预算限制推理轨迹能持续多长。因此,可以根据成本与准确率要求,为任一模式搭配更紧或更宽松的预算。
3)Reasoning-off 使用 enable_thinking=False,预先填入空的 <think></think> 块,让模型直接进入最终回答,类似第 4 节讨论的 Qwen3。因此,这些是聊天模板控制,而不是系统提示。
上下游
本块首次出现的来源与延伸
保留原文提供的资源地址,供查看对应材料和上下文。
原文链接;未将未核验内容当作新证据来源身份与原文对应;未把链接存在当作事实核验。
保留来源;未独立逐项核验保留原文提供的资源地址,供查看对应材料和上下文。
原文链接;未将未核验内容当作新证据来源身份与原文对应;未把链接存在当作事实核验。
保留来源;未独立逐项核验来源身份与原文对应;未把链接存在当作事实核验。
保留来源;未独立逐项核验本块新增 5 项 · 另有 1 项已在前文介绍
判断
对本块内容的判断
本节按作者整理的模型报告译出;没有把不同基座和任务下的结果当作受控横向排名。
核验与延伸: ↗ · Nemotron 3 Ultra technical report ↗ · ↗ · chat template ↗
解释
本块首次出现的知识点
本块相关内容已在前文介绍
英文原文 18
217 词 · 1 张图6.2.2 Reasoning budget-aware training in Nemotron
The inference controls described above are backed by two related SFT components. The first introduces medium-effort behavior using GPT-OSS-120B traces, as discussed earlier. The second prepares the model for hard reasoning budgets.
To construct this training data, the authors take regular reasoning traces, truncate them at randomly selected token budgets, and keep the original final answers. The inserted </think> token is masked from the SFT loss. As a result, the model sees examples where it has to move from an incomplete reasoning trace to the answer after the reasoning block has been closed externally.
Medium-effort training then continues during RLVR. About 2.5% of the RL prompts use the medium-effort setting across math, STEM, and coding tasks. The report notes that the mode can be calibrated through reward hyperparameters where length-based reward adjustments provide additional control over the cost-quality trade-off.
6.3 Kimi K2.5 alternates budgeted and unconstrained RL
The Kimi K2.5 technical report discusses a training method called Token Efficient RL for lower reasoning effort. (While there was a K3 announcement this week, the reasoning-effort methodology of K3 is not publicly disclosed, but it could be similar or related to K2.5.)
中文译文 18
370 字6.2.2 Nemotron 中考虑推理预算的训练
上述推断控制由两个相关的 SFT 组成部分支撑。第一个如前所述,使用 GPT-OSS-120B 的推理轨迹引入 medium-effort 行为;第二个则让模型为硬性推理预算做好准备。
为了构造这类训练数据,作者会取普通推理轨迹,在随机选择的 token 预算处截断它们,同时保留原来的最终答案。插入的 </think> token 不计入 SFT 损失。因此,模型会看到这样的示例:推理块被外部关闭后,它必须从不完整的推理轨迹转向给出答案。
接下来,medium-effort 的训练会在 RLVR 阶段继续。数学、STEM 与编码任务中,约 2.5% 的强化学习提示采用 medium-effort 设置。报告指出,可以通过奖励超参数校准这一模式,基于长度的奖励调整则为成本与质量之间的权衡提供进一步控制。
6.3 Kimi K2.5 交替进行有预算与无预算约束的强化学习
Kimi K2.5 技术报告讨论了一种用于降低推理强度的训练方法,称为 Token Efficient RL。(尽管本周已经发布了 K3,但 K3 的推理强度方法尚未公开,可能与 K2.5 相似或相关。) [1]
上下游
本块首次出现的来源与延伸
来源身份与原文对应;未把链接存在当作事实核验。
保留来源;未独立逐项核验本块新增 1 项 · 另有 1 项已在前文介绍
判断
对本块内容的判断
本节按作者整理的模型报告译出;没有把不同基座和任务下的结果当作受控横向排名。
保留发表时叙述与后续更新的时间差
前文说K3报告尚未公开,后面的“更新”节说明报告在文章发表后发布。这是不同时间点的记录,不应把前文悄悄改写,也不能忽略更新节。
核验与延伸:Kimi K2.5 technical report ↗ · Sebastian Raschka · Controlling Reasoning Effort in LLMs ↗
解释
本块首次出现的知识点
本块相关内容已在前文介绍
英文原文 19
254 词 · 2 张图6.3.1 Kimi’s Toggle method
The report mentions that a fixed token budget can make a reasoning model overfit to short solutions. That means the model becomes more concise (i.e., faster and cheaper), but it may lose the ability to benefit from additional inference-time compute and can thus perform poorly.
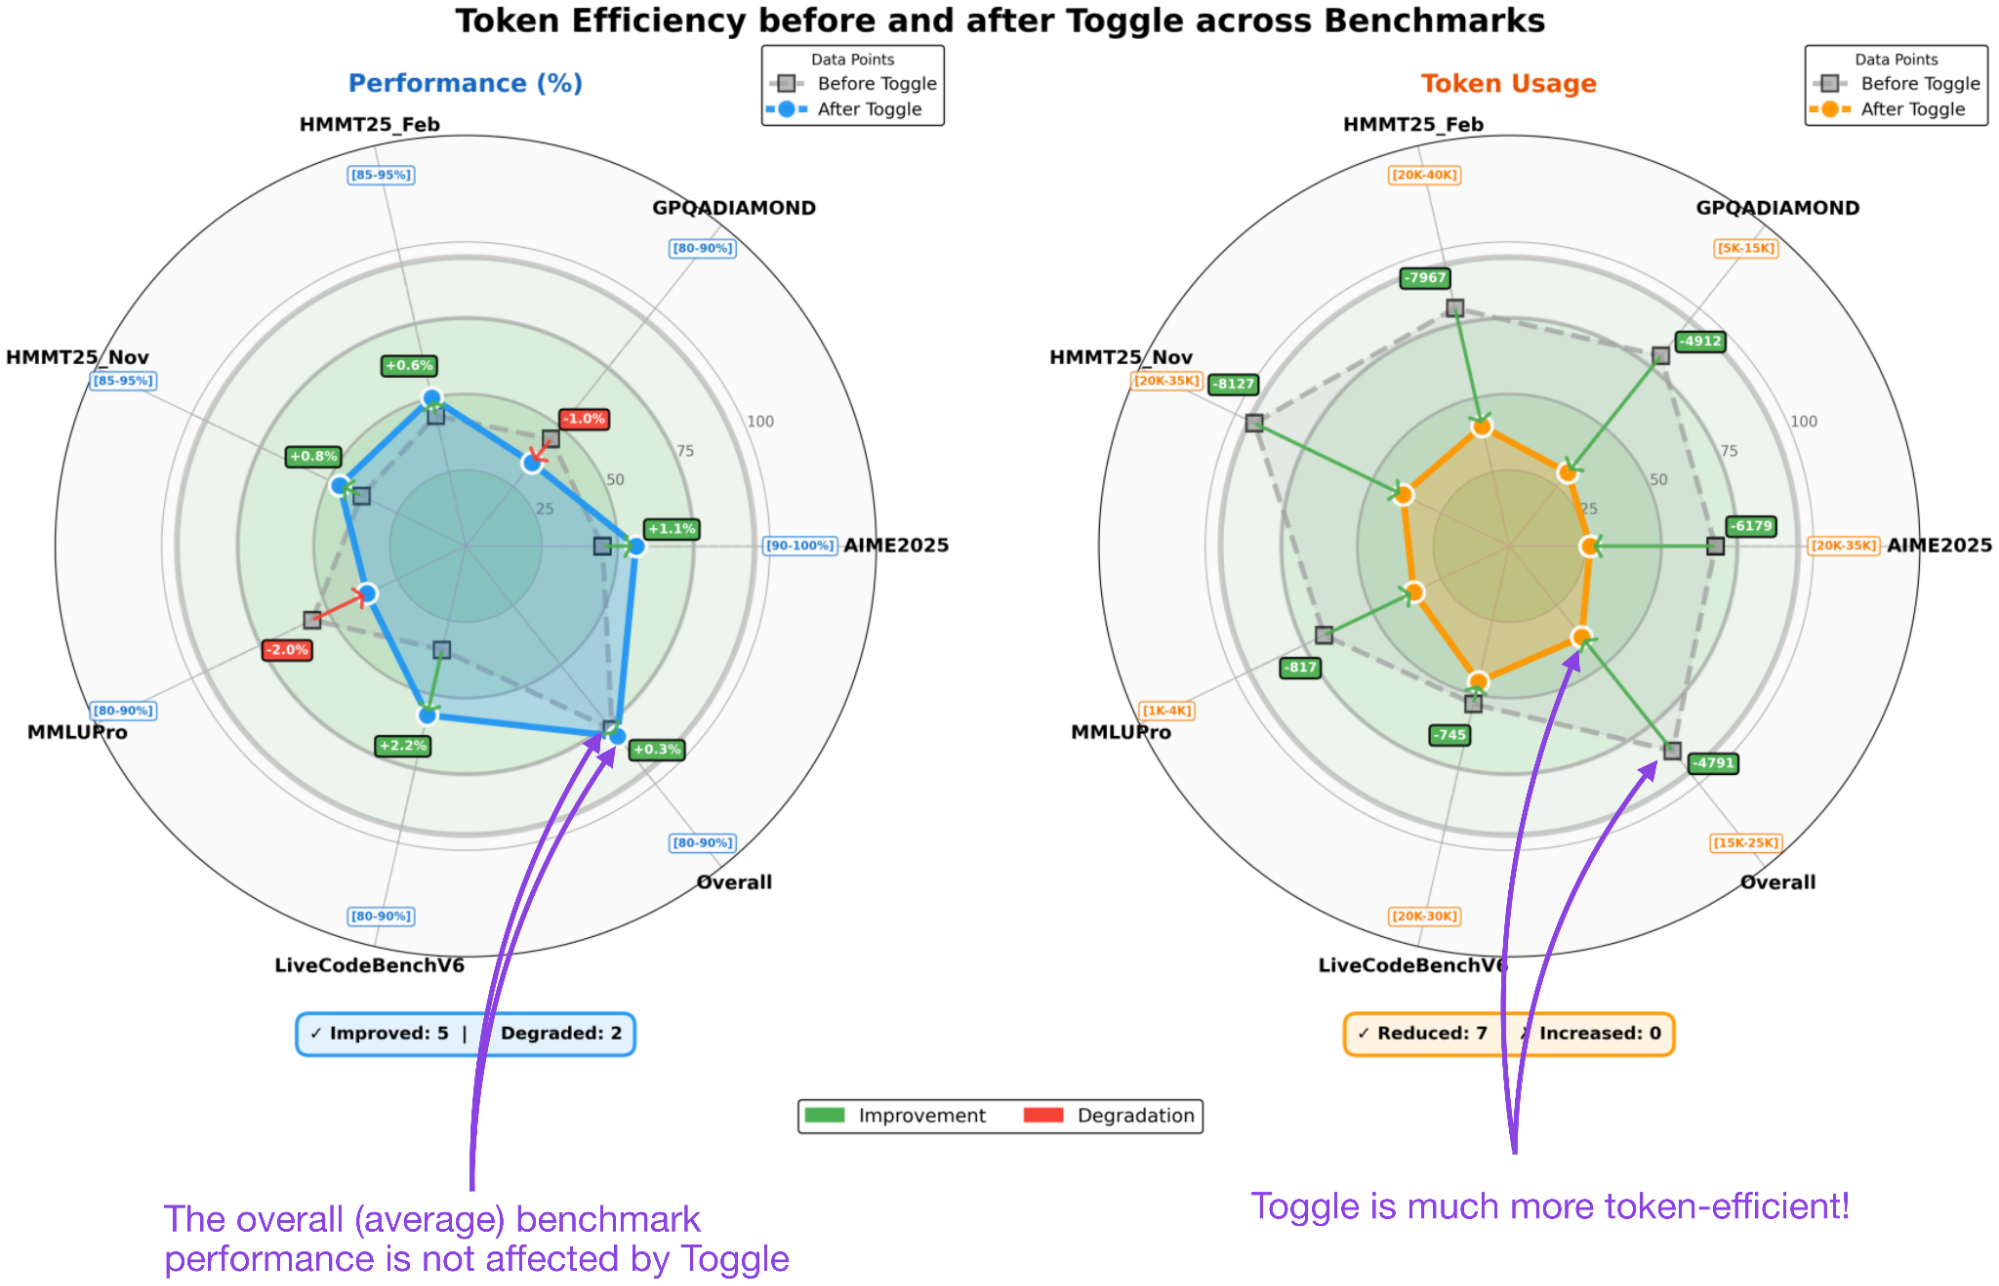
Kimi K2.5’s method, called Toggle, alternates between two RL phases every fixed number of training iterations:
1. In the budgeted phase, correct solutions are encouraged to stay within a problem-specific token budget.
2. In the unconstrained phase, the usual maximum generation length is restored so that the model can still learn from longer solutions.
For each problem, the budget is estimated from a selected percentile of response lengths among correct rollouts in RLVR. The budget constraint is then only activated once the mean accuracy on that problem exceeds a threshold. This avoids forcing the model to shorten its reasoning before it can solve the problem reliably.
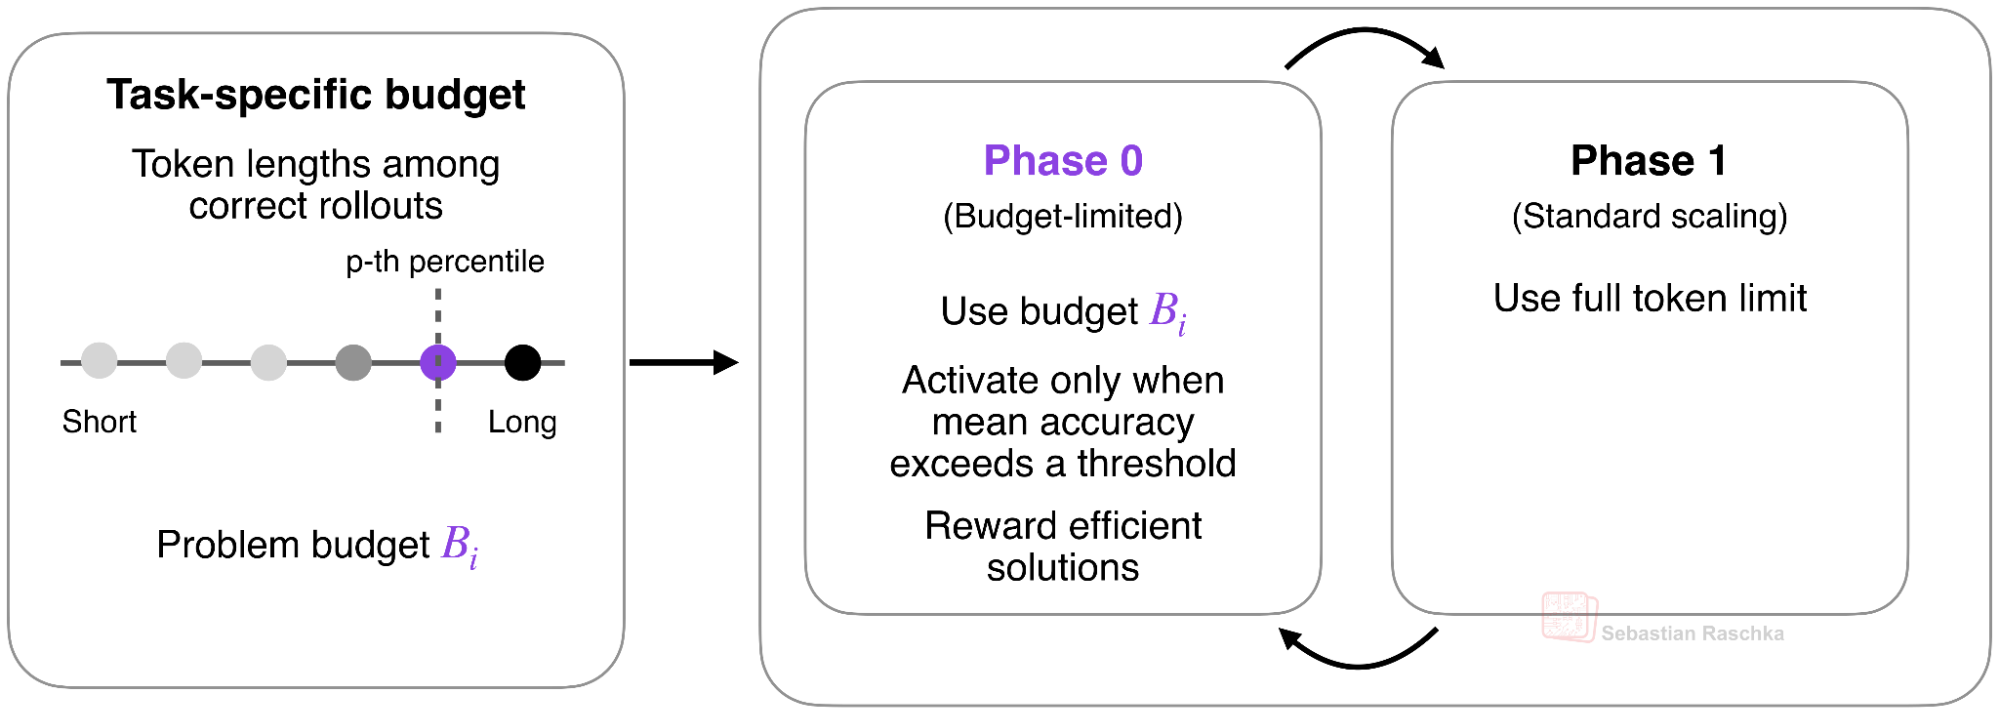
The report evaluates Toggle on K2 Thinking and finds that it reduces generated tokens by about 25 to 30% with little change in benchmark performance. The same behavior also transfers from math and coding RL tasks to GPQA and MMLU-Pro.
Toggle supplies a concrete flagship-model recipe for training a more token-efficient reasoning policy while preserving its ability to scale at test time.
中文译文 19
410 字6.3.1 Kimi 的 Toggle 方法
报告指出,固定的 token 预算可能让推理模型过度适应短解答。这意味着模型虽然变得更简洁,也就是更快、更便宜,却可能失去从额外推断计算中获益的能力,因而表现变差。
Kimi K2.5 的这一方法称为 Toggle,每经过固定次数的训练迭代,就在两个强化学习阶段之间切换:
1. 在有预算阶段,鼓励正确解答保持在针对具体问题设置的 token 预算以内。
2. 在无预算约束阶段,恢复通常的最大生成长度,让模型仍能从较长解答中学习。
对于每个问题,预算根据 RLVR 中正确采样回答长度的某个选定分位数估计。只有当模型在该问题上的平均准确率超过某个阈值后,才启用预算约束。这能避免模型还无法可靠解题时,就被迫缩短推理。
报告在 K2 Thinking 上评估了 Toggle,发现它能将生成 token 数减少约 25% 至 30%,而基准表现几乎不变。同样的行为还能从数学和代码强化学习任务迁移到 GPQA 与 MMLU-Pro。
Toggle 提供了一套具体的旗舰模型训练方法:在保留测试阶段扩展能力的同时,训练出 token 效率更高的推理策略。
上下游
本块首次出现的来源与延伸
本块相关内容已在前文介绍
判断
对本块内容的判断
本节按作者整理的模型报告译出;没有把不同基座和任务下的结果当作受控横向排名。
核验与延伸:Sebastian Raschka · Controlling Reasoning Effort in LLMs ↗
解释
本块首次出现的知识点
本块相关内容已在前文介绍
英文原文 20
284 词6.3.2 What Toggle changes at inference
Toggle operates entirely during RL training. Both alternating phases update the same policy (i.e., LLM), and the final (unified) checkpoint has no budgeted-versus-unconstrained selector. At inference, the resulting model then runs in thinking mode by default.
Interestingly, though, Kimi K2.5 itself exposes a separate binary choice between thinking and instant modes in some APIs I checked (like vLLM or SGLang). Thinking mode is enabled by default. Instant mode disables the reasoning trace through thinking: {”type”: “disabled”} in the official API or chat_template_kwargs={”thinking”: False} when serving the model through vLLM or SGLang. However, these settings are separate from Toggle.
Also, the official Kimi report does not provide a separate training recipe for instant mode. However, K2.5’s SFT data were generated using both the earlier K2 model, which produces direct responses without long reasoning, and K2 Thinking, which produces extended reasoning traces. This likely exposes the unified checkpoint to both response formats similar to what’s done in Nemotron 3 above. At inference time, the chat template selects between them by prefilling either an open <think> tag for thinking mode or an empty <think></think> block for instant mode. But again, unfortunately, the report does not disclose the exact data mixture or whether additional mode-specific RL was used.
The newer Kimi K3 provides a more direct inference-time effort interface. The current Kimi Code documentation lists three settings called low, high, and max, with max as the default. These are passed through the reasoning_effort parameter. However, Moonshot has not yet explained how the three effort levels were created during training. Its launch post says that these details will appear in a future K3 technical report, so I’ll stay tuned for that.
中文译文 20
461 字6.3.2 Toggle 在推断阶段改变了什么
Toggle 完全作用于强化学习训练阶段。两个交替阶段都更新同一个策略,也就是同一个大语言模型;最终统一的检查点并没有“有预算/无预算约束”选择开关。推断时,所得模型默认运行在思考模式。
不过,有趣的是,我检查的一些接口或服务框架,例如 vLLM、SGLang,确实为 Kimi K2.5 提供了独立的思考/即时回答二选一设置。默认开启思考模式;在官方 API 中使用 thinking: {”type”: “disabled”},或通过 vLLM、SGLang 部署时设置 chat_template_kwargs={”thinking”: False},可以切换到即时模式、关闭推理轨迹。但这些设置与 Toggle 是两回事。
此外,Kimi 官方报告并没有单独给出即时模式的训练方法。不过,K2.5 的 SFT 数据同时使用了早期 K2 和 K2 Thinking 生成:前者直接回答,不进行长推理;后者则生成较长的推理轨迹。这很可能像前面 Nemotron 3 的做法一样,让统一检查点接触到两种回答格式。推断时,聊天模板通过预填一个打开的 <think> 标签,或一个空的 <think></think> 块,在思考模式与即时模式之间选择。但遗憾的是,报告仍未披露精确的数据混合比例,以及是否采用了额外的模式专项强化学习。
更新的 Kimi K3 提供了更直接的推断阶段强度接口。当前 Kimi Code 文档列出 low、high、max 三个设置,默认是 max,通过 reasoning_effort 参数传入。但 Moonshot 尚未解释训练时如何形成这三个强度档位。发布文章说,这些细节会出现在未来的 K3 技术报告中,我会继续关注。 [1] [2] [3] [4]
上下游
本块首次出现的来源与延伸
保留原文提供的资源地址,供查看对应材料和上下文。
原文链接;未将未核验内容当作新证据来源身份与原文对应;未把链接存在当作事实核验。
保留来源;未独立逐项核验保留原文提供的资源地址,供查看对应材料和上下文。
原文链接;未将未核验内容当作新证据来源身份与原文对应;未把链接存在当作事实核验。
保留来源;未独立逐项核验本块新增 4 项 · 另有 1 项已在前文介绍
判断
对本块内容的判断
本节按作者整理的模型报告译出;没有把不同基座和任务下的结果当作受控横向排名。
Toggle的训练切换不等于推断菜单
作者描述的有预算/无预算两阶段交替发生在训练期间;最终模型的thinking/instant接口是另外一项控制。不能把两者合并成同一个开关。
核验与延伸: ↗ · current Kimi Code documentation ↗ · ↗ · launch post ↗
解释
本块首次出现的知识点
本块相关内容已在前文介绍
英文原文 21
240 词6.3.3 Kimi K3 (Update)
Based on the new Kimi K3 technical report (released after I published this article), Kimi K3 has three reasoning modes: low-, high-, and max-effort.
For each training problem, the researchers first estimate an initial token budget. On a simple verifiable task, a correct response would normally receive a reward of +1 and an incorrect response 0. But here, if the response exceeds the selected token budget, its reward is instead set to -1. This gives the model a strong incentive to stay within the budget. (The exact reward setup is different for non-verifiable and agentic tasks, and Kimi also uses learned reward models and pairwise comparisons.)
To have Kimi K3 support the three reasoning effort modes, the training looked as follows. First, the researchers start by training a max-effort version (“specialist”) with a relatively generous budget. They then lower the budget to train high- and low-effort versions.
This process is repeated for three domains: general tasks, general agents, and coding agents. And each domain gets one specialist for each effort level. So, for example, one specialist learns low-effort coding behavior, while another learns max-effort agent behavior. This gives nine specialist models in total.
The behaviors of these nine specialist models are then combined into a single Kimi K3 model using multi-teacher on-policy distillation. At inference time, a natural-language thinking-effort instruction in the prompt can then be used to tell the model which effort level to use.
中文译文 21
370 字6.3.3 Kimi K3(更新)
根据本文发表之后发布的新 Kimi K3 技术报告,Kimi K3 有 low、high 和 max 三种推理强度模式。 [1]
对于每个训练问题,研究人员首先估计初始 token 预算。在简单的可验证任务上,正确回答通常获得 +1 奖励,错误回答则为 0。但在这里,如果回答超过所选 token 预算,奖励会被设为 -1,从而强烈激励模型控制在预算内。(对于不可验证任务和智能体任务,具体奖励设置有所不同;Kimi 也使用学习得到的奖励模型与成对比较。)
为了让 Kimi K3 支持这三个推理强度档位,训练过程如下:先用相对充足的预算训练一个 max-effort 版本,也就是“专家”;随后降低预算,训练 high-effort 与 low-effort 版本。
这个过程会在三个领域重复:通用任务、通用智能体和编码智能体。每个领域在每个强度档位上都有一位专家。例如,一位专家学习低强度的编码行为,另一位学习最高强度的智能体行为。总共得到九个专家模型。
之后,通过多教师同策略蒸馏,把这九个专家模型的行为合并到一个 Kimi K3 模型中。推断时,就可以在提示中使用自然语言的 thinking-effort 指令,指定要使用的强度档位。
上下游
本块首次出现的来源与延伸
来源身份与原文对应;未把链接存在当作事实核验。
保留来源;未独立逐项核验本块新增 1 项 · 另有 1 项已在前文介绍
判断
对本块内容的判断
本节按作者整理的模型报告译出;没有把不同基座和任务下的结果当作受控横向排名。
核验与延伸:Kimi K3 technical report ↗ · Sebastian Raschka · Controlling Reasoning Effort in LLMs ↗
解释
本块首次出现的知识点
本块相关内容已在前文介绍
英文原文 22
236 词 · 1 张图6.4 GLM-5 introduces turn-level and interleaved thinking through SFT
The GLM-5 technical report extends the binary on/off thinking switch introduced with GLM-4.5 to multi-turn and tool-using scenarios. It describes three related behaviors (rather than three effort levels):
Interleaved thinking: this inserts a reasoning block before each response and tool call.
Preserved thinking: here, the chat retains earlier reasoning blocks across turns so that the model can reuse them later.
Turn-level thinking: this enables or disables reasoning separately for each request in a conversation.
At inference time, turn-level thinking is the actual on-off switch. In the Z.ai API, thinking is enabled by default and can be disabled for an individual request with thinking: {”type”: “disabled”}. The hosted implementation is not disclosed but the open GLM-5 chat template shows the equivalent mechanism when self-hosting with Transformers, vLLM, or SGLang.
It starts the assistant response with <|assistant|><think> when thinking is enabled and <|assistant|></think> when it is disabled. The latter closes the reasoning block immediately, so generation proceeds directly to the final answer.
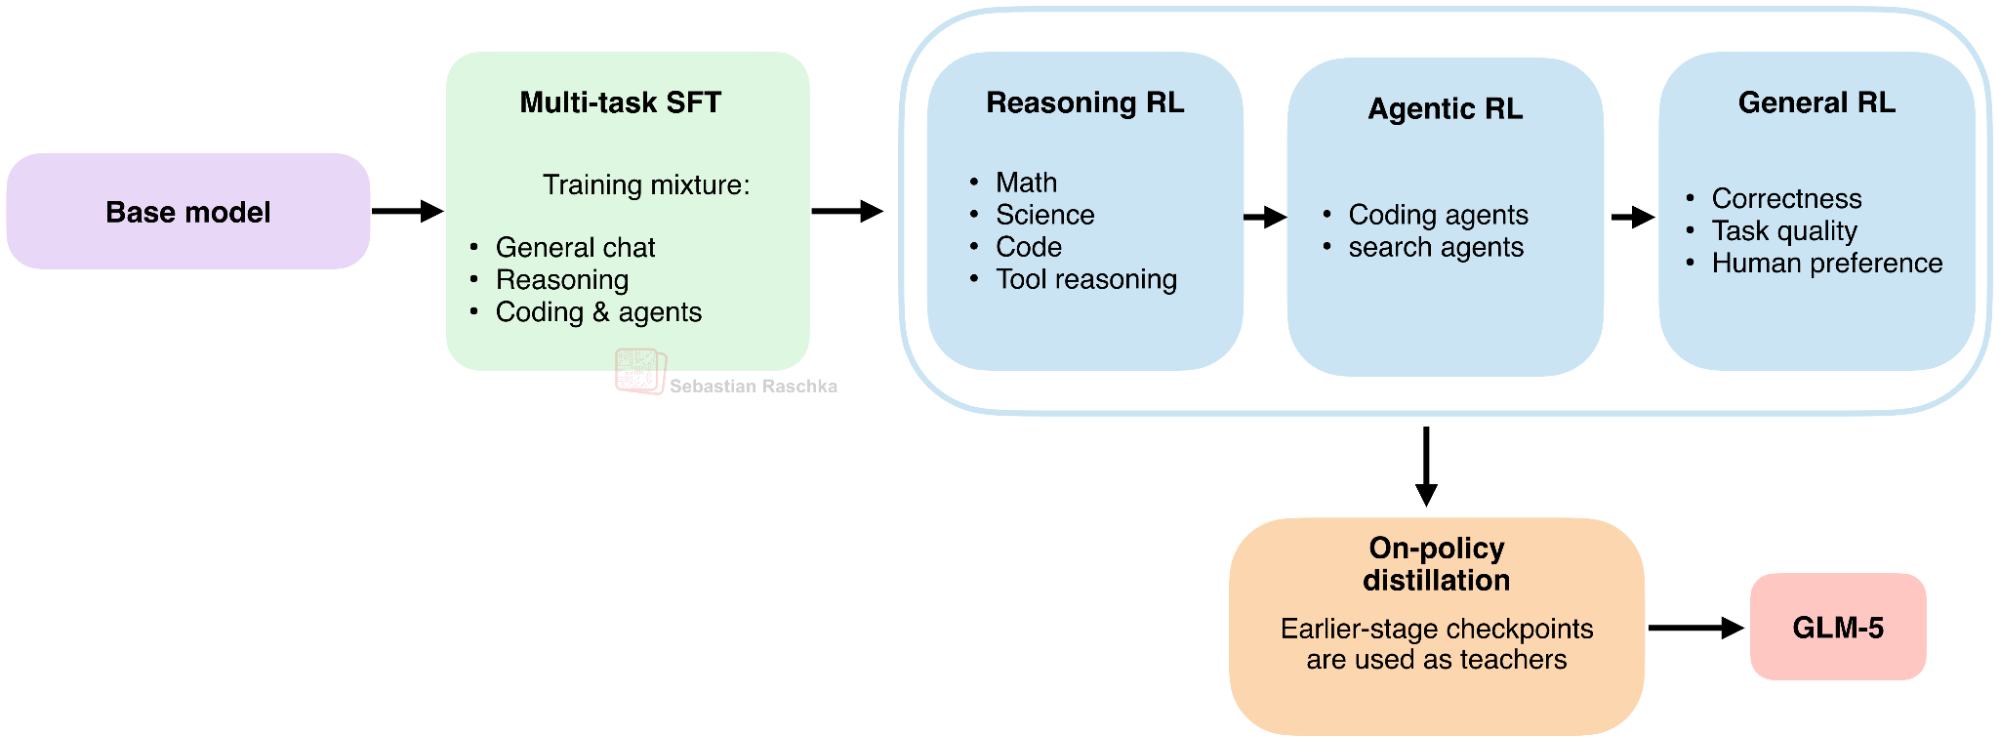
The report says that these behaviors are introduced during multi-task SFT together with an updated chat template.
After SFT, GLM-5 goes through reasoning RL, agentic RL, and general RL. And a final on-policy distillation step uses checkpoints from the preceding stages as teachers. This helps the final model recover capabilities that may have weakened during the sequential RL stages.
中文译文 22
370 字6.4 GLM-5 通过 SFT 引入逐轮思考与交错思考
GLM-5 技术报告把 GLM-4.5 中引入的二元思考开关,扩展到了多轮对话和工具使用场景。它描述的是三种相关行为,而不是三个强度档位: [1] [2]
交错思考:在每次回答和工具调用之前插入一个推理块。
保留思考:跨轮次保留之前的推理块,让模型可以在后续复用。
逐轮思考:为对话中的每一次请求单独开启或关闭推理。
推断时,逐轮思考才是真正的开关。Z.ai API 默认启用思考,可以通过 thinking: {”type”: “disabled”} 对单次请求关闭。托管服务的实现没有公开,但开放的 GLM-5 聊天模板展示了使用 Transformers、vLLM 或 SGLang 自行部署时的等价机制。 [1] [2] [3] [4]
开启思考时,助手回答以 <|assistant|><think> 开头;关闭时则以 <|assistant|></think> 开头。后者立即关闭推理块,使生成直接进入最终答案。
报告说,这些行为是在多任务 SFT 中结合更新后的聊天模板引入的。
SFT 之后,GLM-5 还要经历推理强化学习、智能体强化学习和通用强化学习。最后,再通过同策略蒸馏,以前述阶段的检查点作为教师。这有助于最终模型恢复在连续强化学习阶段中可能减弱的能力。
上下游
本块首次出现的来源与延伸
保留原文提供的资源地址,供查看对应材料和上下文。
原文链接;未将未核验内容当作新证据来源身份与原文对应;未把链接存在当作事实核验。
保留来源;未独立逐项核验保留原文提供的资源地址,供查看对应材料和上下文。
原文链接;未将未核验内容当作新证据来源身份与原文对应;未把链接存在当作事实核验。
保留来源;未独立逐项核验保留原文提供的资源地址,供查看对应材料和上下文。
原文链接;未将未核验内容当作新证据来源身份与原文对应;未把链接存在当作事实核验。
保留来源;未独立逐项核验本块新增 6 项 · 另有 1 项已在前文介绍
判断
对本块内容的判断
本节按作者整理的模型报告译出;没有把不同基座和任务下的结果当作受控横向排名。
核验与延伸: ↗ · GLM-5 technical report ↗ · ↗ · Z.ai API ↗
解释
本块首次出现的知识点
本块相关内容已在前文介绍
英文原文 23
226 词6.5 Qwen3 uses mode fusion and inference-time truncation
Qwen3 was already covered in Section 4, so I will only summarize the parts that matter for this comparison. According to the Qwen3 technical report, its post-training pipeline has four stages. These are long-chain-of-thought SFT, reasoning RL, Thinking Mode Fusion, and general RL.
Thinking Mode Fusion is the key stage for the effort on-off switch. Here the model is trained via SFT on a mixture of thinking and non-thinking examples. The /think examples contain a reasoning trace, while /no_think examples begin with an empty <think></think> block that is accompanied by a short answer. The following general RL stage reinforces instruction and format following for both behaviors.
Qwen3 also supports a hard thinking budget. At the requested threshold, the reasoning span is stopped and a stop-thinking instruction is inserted before the model continues with its final answer. The report says that this partial-reasoning behavior was not trained explicitly. It emerged after Thinking Mode Fusion.
This gives Qwen3 a learned on-off switch plus an inference-time budget. It is similar but simpler than the DeepSeek V4 and Nemotron recipes.
6.6 Inkling conditions RL on a continuous effort value
Inkling was already discussed in Section 5.3. The short version is that its technical report mentions that they use continuous effort conditioning (values between 0.0 and 1.0) rather than fixed effort labels.
中文译文 23
360 字6.5 Qwen3 使用模式融合与推断阶段截断
第 4 节已经介绍过 Qwen3,这里只概括与比较相关的部分。根据 Qwen3 技术报告,它的后训练流程包含四个阶段:长思维链 SFT、推理强化学习、思考模式融合,以及通用强化学习。 [1] [2]
思考模式融合是实现推理开关的关键阶段。模型在这里使用思考和非思考示例的混合数据进行 SFT。/think 示例包含推理轨迹,而 /no_think 示例以空的 <think></think> 块开头,并附上简短答案。之后的通用强化学习阶段会强化这两种行为的指令与格式遵循。
Qwen3 也支持硬性思考预算。达到请求的阈值后,推理段会被停止,并插入停止思考的指令,随后模型继续生成最终答案。报告指出,这种利用部分推理回答的行为没有被显式训练,而是在思考模式融合之后自然出现的。
这使 Qwen3 同时具备学得的开关和推断阶段预算。它与 DeepSeek V4、Nemotron 的方法类似,但更简单。
6.6 Inkling 以连续强度值作为强化学习的条件
第 5.3 节已经讨论过 Inkling。简要来说,它的技术报告提到,采用 0.0 到 1.0 之间的连续强度条件,而不是固定的强度标签。 [1] [2]
上下游
本块首次出现的来源与延伸
保留原文提供的资源地址,供查看对应材料和上下文。
原文链接;未将未核验内容当作新证据来源身份与原文对应;未把链接存在当作事实核验。
保留来源;未独立逐项核验保留原文提供的资源地址,供查看对应材料和上下文。
原文链接;未将未核验内容当作新证据来源身份与原文对应;未把链接存在当作事实核验。
保留来源;未独立逐项核验本块新增 4 项 · 另有 2 项已在前文介绍
判断
对本块内容的判断
本节按作者整理的模型报告译出;没有把不同基座和任务下的结果当作受控横向排名。 把显式预算、模式融合与自动路由分开理解;哪些方法更好仍依赖任务、成本和延迟目标。
核验与延伸: ↗ · Qwen3 technical report ↗ · ↗ · technical report ↗
解释
本块首次出现的知识点
本块相关内容已在前文介绍
英文原文 24
220 词 · 1 张图After a relatively small initial SFT stage, most of Inkling’s post-training comes from asynchronous RL with more than 30 million rollouts. The desired effort is included in the system message, and the token length penalty is adjusted according to that value during RL. As previously discussed, a higher token cost encourages a shorter response. A lower token cost gives the model more room to reason.
6.7 Overview of the known recipes
The table below summarizes what is actually documented in the six technical reports.
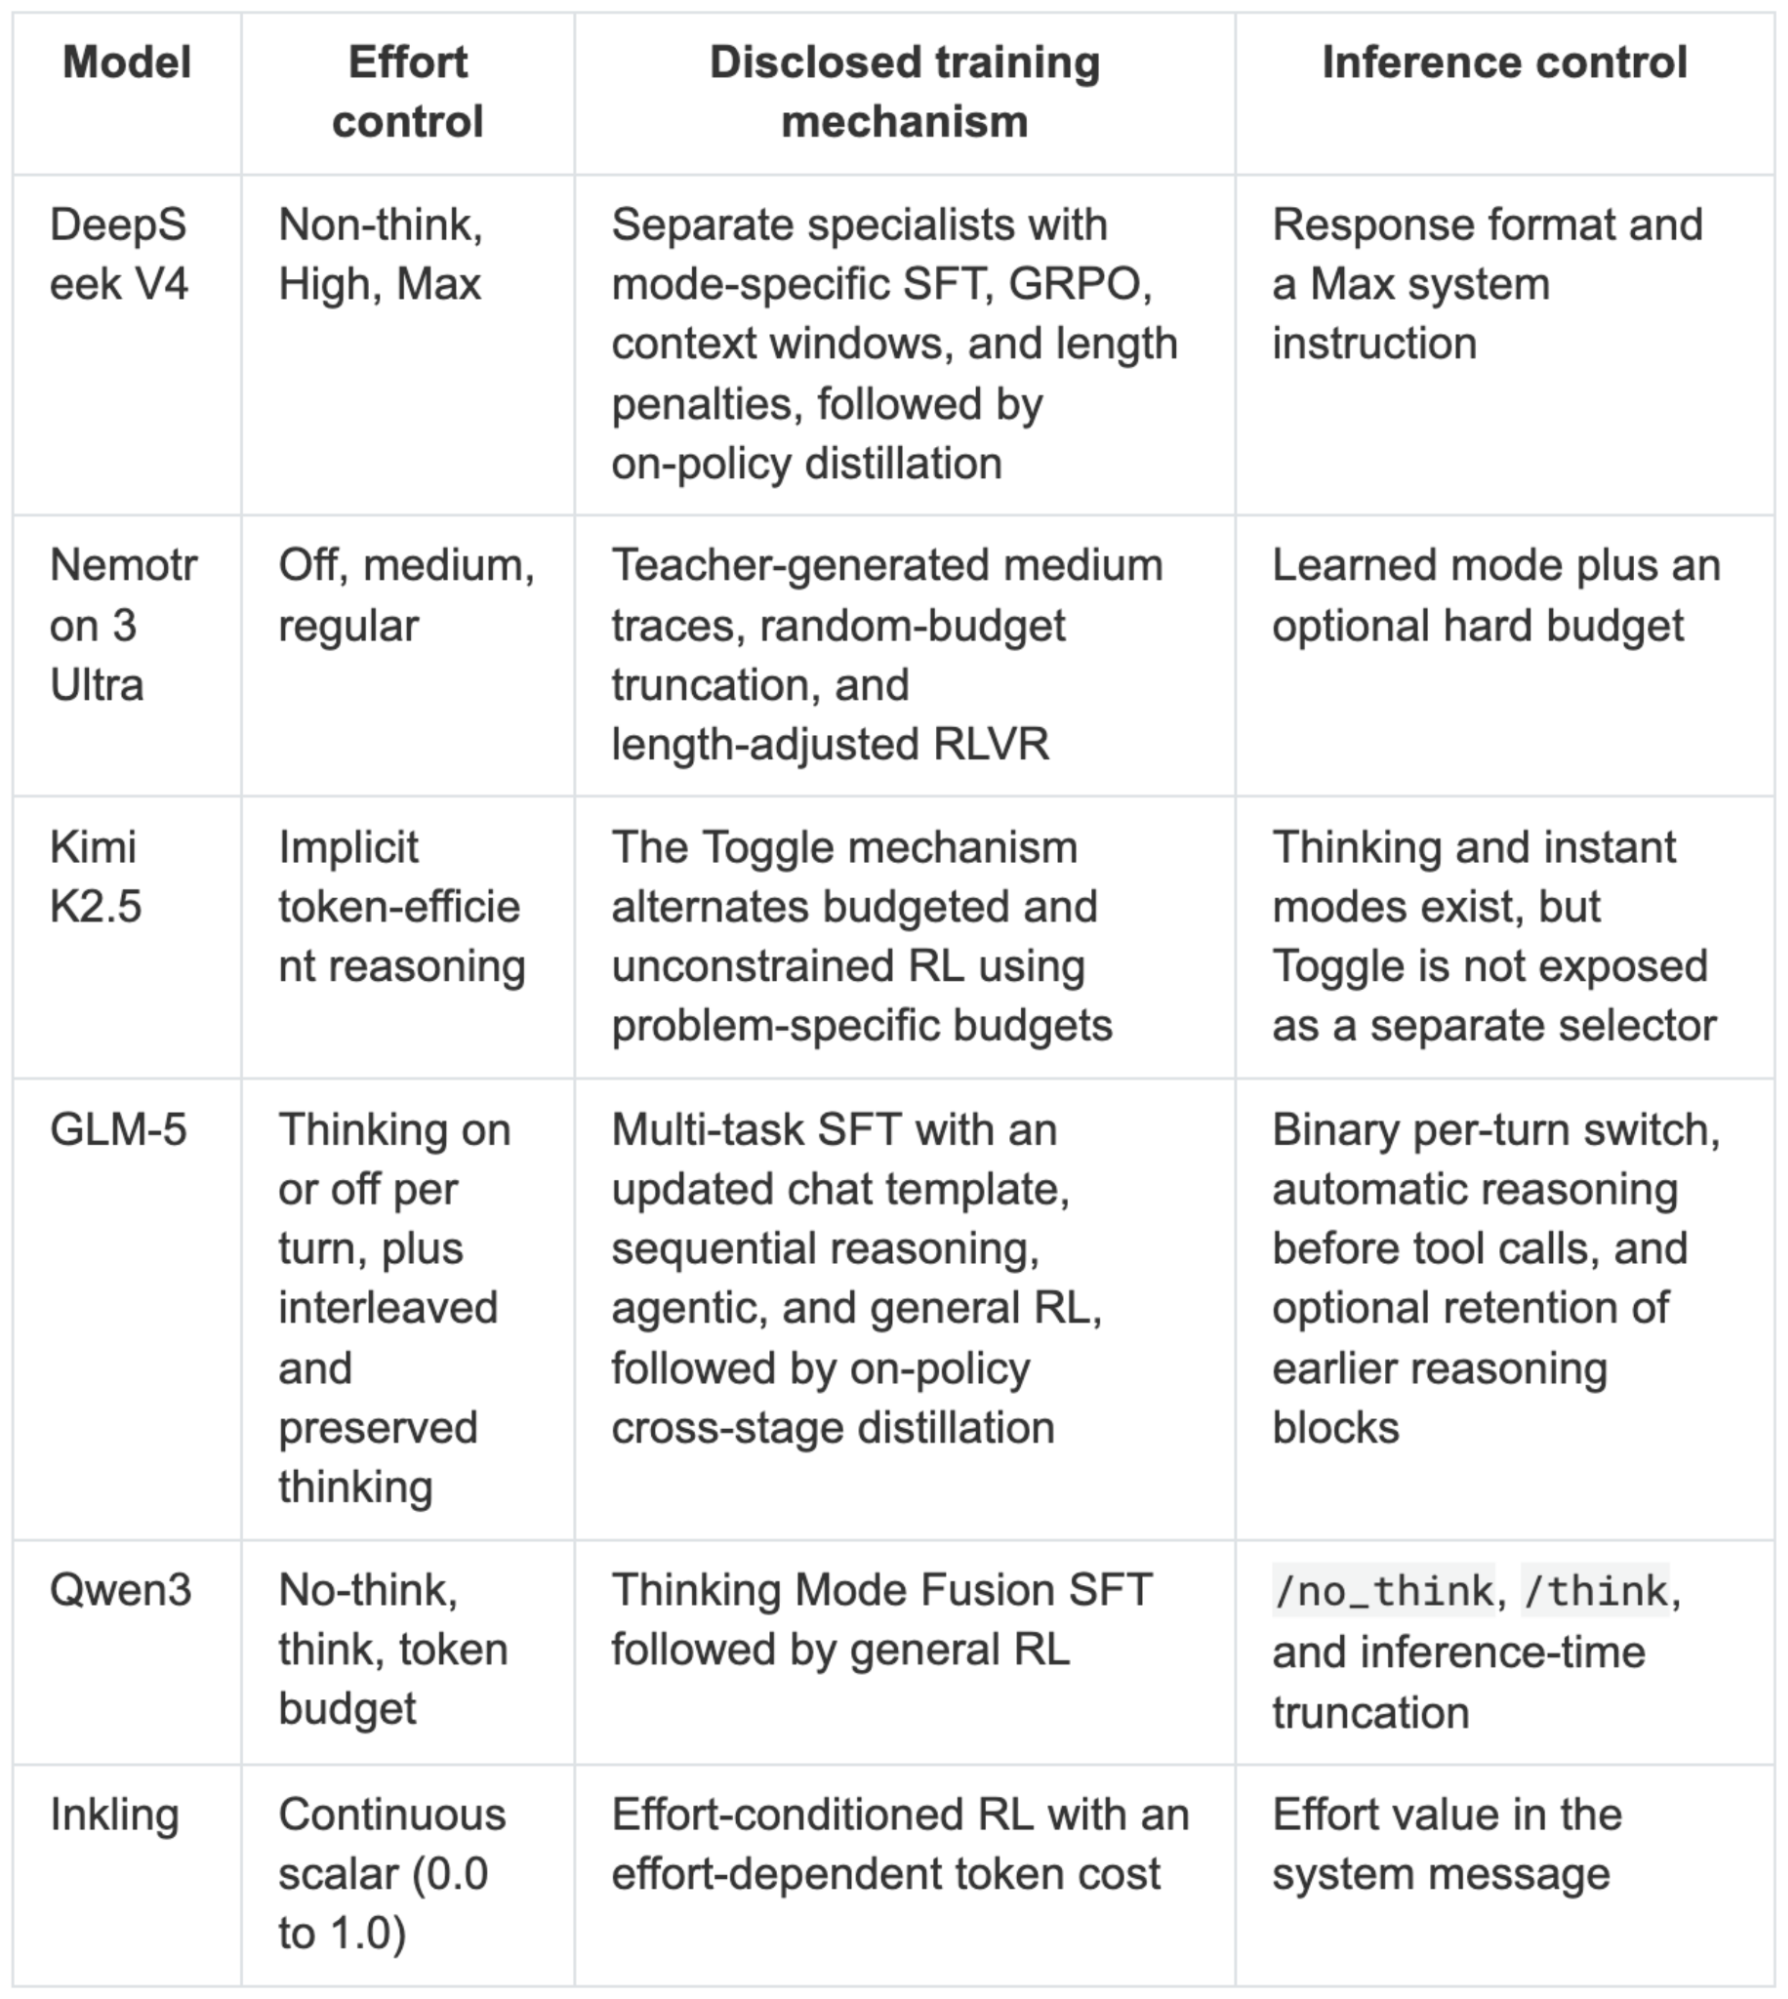
So, looking at the six different open-weight models, they have a shared framework. First, they introduce effort mode control through SFT and the chat template. Qwen3 explicitly mixes thinking and non-thinking examples, while GLM-5 adds interleaved, preserved, and turn-level thinking patterns.
The second shared component is a mode-conditioned RL stage, where context windows and length penalties change with the requested effort. DeepSeek V4, Nemotron 3 Ultra, and Inkling use this approach.
A third ingredient improves robustness under explicit budgets. Nemotron trains on randomly truncated traces, Qwen3 can continue from a forcibly stopped reasoning span, and Kimi alternates budgeted with unconstrained RL. These methods help preserve answer quality when the available reasoning length changes and is even cut short.
中文译文 24
403 字在一个相对较小的初始 SFT 阶段之后,Inkling 后训练的大部分工作来自异步强化学习,使用了超过 3000 万次采样轨迹。期望强度被写入系统消息,强化学习中的 token 长度惩罚则根据该值调整。如前所述,更高的 token 成本鼓励更短的回答,而更低的成本让模型有更大空间推理。
6.7 已知方法概览
下表汇总了六份技术报告中实际记载的内容。
综合来看,这六个不同的开放权重模型有一些共同框架。首先,它们通过 SFT 和聊天模板引入强度模式控制。Qwen3 明确混合了思考与非思考示例,GLM-5 则加入交错思考、保留思考与逐轮思考模式。
第二个共同组成部分是以模式为条件的强化学习阶段:上下文窗口和长度惩罚,会随请求的强度而改变。DeepSeek V4、Nemotron 3 Ultra 与 Inkling 采用了这种方法。
第三类方法用于提高模型在显式预算约束下的稳健性。Nemotron 使用随机截断的轨迹训练;Qwen3 能在推理段被强制停止后继续作答;Kimi 则交替进行有预算和无预算约束的强化学习。这些方法有助于在可用推理长度变化、甚至被提前截断时,保持回答质量。
上下游
本块首次出现的来源与延伸
本块相关内容已在前文介绍
判断
对本块内容的判断
把显式预算、模式融合与自动路由分开理解;哪些方法更好仍依赖任务、成本和延迟目标。
核验与延伸:Sebastian Raschka · Controlling Reasoning Effort in LLMs ↗ · Qwen3 技术报告 v1 ↗
解释
本块首次出现的知识点
本块相关内容已在前文介绍
英文原文 25
211 词7. Conclusion
The open-weight examples in this article implement reasoning effort through several different mechanisms. Similar labels can be backed by separate specialists, mixed SFT data, mode-conditioned rewards, hard token budgets, or combinations of these methods.
It is difficult to say which approach is best. The models differ in their base checkpoints, training data, post-training compute, benchmarks, and serving goals. Their reports also omit many details needed for a controlled comparison. (Also, there may not be a one-size-fits-all, and a method that works well for an interactive assistant may be a poor fit for a long-running coding agent.)
The holy grail is of course automatic effort selection. We saw this a while back with GPT 5’s Auto mode. It’s a tricky problem to solve, and in the end, the implementation was probably more miss than hit, which is why it got removed from the UI (at least, I can’t find it anymore).
In the near future, I think reasoning effort will remain an explicit model input, which will most often be delivered through the system prompt. However agent wrapper/harness around the LLM, or an internal router may increasingly infer the appropriate mode and budget from the task state and available resources automatically (while of course still allowing a user override).
中文译文 25
354 字7. 结论
本文中的开放权重模型,采用了多种不同机制来实现推理强度。相似标签背后,可能是独立专家、混合 SFT 数据、以模式为条件的奖励、硬性 token 预算,也可能是这些方法的组合。
很难判断哪种方法最好,因为这些模型的基础检查点、训练数据、后训练计算、基准与服务目标都不同。报告也省略了许多进行受控比较所需的细节。此外,可能本来就没有放之四海而皆准的方法:适合交互式助手的方案,未必适合长时间运行的编码智能体。
理想目标当然是自动选择推理强度。此前 GPT-5 的 Auto 模式曾展示过这种思路。这是一个难题,而最终的实现很可能是失误多于成功,所以它才从界面中移除了——至少我已经找不到它。
在不远的将来,我认为推理强度仍会是显式的模型输入,最常见的传递方式仍是系统提示。不过,大语言模型外围的智能体封装或运行框架,或者内部路由器,可能会越来越多地根据任务状态与可用资源自动推断合适的模式和预算,同时仍允许用户覆盖选择。
上下游
本块首次出现的来源与延伸
本块相关内容已在前文介绍
判断
对本块内容的判断
把显式预算、模式融合与自动路由分开理解;哪些方法更好仍依赖任务、成本和延迟目标。
核验与延伸:Sebastian Raschka · Controlling Reasoning Effort in LLMs ↗ · Qwen3 技术报告 v1 ↗
解释
本块首次出现的知识点
本块相关内容已在前文介绍
英文原文 26
280 词 · 1 张图I still hope that effort selection will become more automatic. Similar to GPT 5’s auto mode, a cheap model or router could choose the mode from the request, tool state, and remaining time or token budget while still allowing a user override. The override is useful if you want to optimize for latency or cost, or maximum performance.
I realize that this was a long article, and it was perhaps not the flashiest topic. But I thought that given all the talk about LLMs, reasoning models, and agents, a look at reasoning models was something not covered before, and I hope it was a unique and somewhat useful overview!
Further resources
If you want a hands-on implementation of the core training methods behind reasoning models, my Build a Reasoning Model (From Scratch) book walks through reinforcement learning with verifiable rewards and inference-time scaling step by step, with code.
This article focused on how a trained reasoning model can support different effort modes. The book takes a step back and shows how to turn a conventional LLM into a reasoning model in the first place. It is a sequel to Build a Large Language Model (From Scratch) and starts where that book leaves off.
The print edition has now started shipping
If you liked my previous Build a Large Language Model (From Scratch) book, this is essentially a sequel implementing inference-time scaling techniques and reinforcement learning algorithms from scratch.
And if you want to support future long-form articles like this one, consider becoming a paid subscriber. It helps me keep writing these independent deep dives and sharing the accompanying code, figures, and experiments.
中文译文 26
445 字我仍希望推理强度的选择能变得更加自动化。类似 GPT-5 的 Auto 模式,一个低成本模型或路由器可以根据请求、工具状态以及剩余时间或 token 预算选择模式,同时允许用户手动覆盖。当你想优化延迟、成本或追求最高表现时,这种覆盖能力就很有用。
我知道这篇文章很长,话题可能也不算最炫目。不过,在大家不断讨论大语言模型、推理模型和智能体的当下,我觉得这种角度的推理模型梳理还比较少见,希望它能提供一份独特且有些帮助的概览!
延伸资料
如果你想亲手实现推理模型背后的核心训练方法,我的《从零构建推理模型》一书会结合代码,逐步讲解可验证奖励强化学习与推断阶段扩展。 [1]
本文重点讨论已经训练好的推理模型如何支持不同强度模式。书中则退后一步,首先展示如何把传统大语言模型变成推理模型。它是《从零构建大语言模型》的续篇,从前一本书结束的地方讲起。 [1]
纸质版现已开始发货。
如果你喜欢我之前的《从零构建大语言模型》,这本书基本上就是它的续作,会从零实现推断阶段扩展技术和强化学习算法。 [1]
如果你愿意支持今后更多这样的长篇文章,可以考虑成为付费订阅者。这能帮助我继续撰写独立的深入分析,分享配套代码、图示与实验。 [1]
上下游
本块首次出现的来源与延伸
来源身份与原文对应;未把链接存在当作事实核验。
保留来源;未独立逐项核验来源身份与原文对应;未把链接存在当作事实核验。
保留来源;未独立逐项核验来源身份与原文对应;未把链接存在当作事实核验。
保留来源;未独立逐项核验来源身份与原文对应;未把链接存在当作事实核验。
保留来源;未独立逐项核验来源身份与原文对应;未把链接存在当作事实核验。
保留来源;未独立逐项核验本块新增 5 项 · 另有 2 项已在前文介绍
判断
对本块内容的判断
把显式预算、模式融合与自动路由分开理解;哪些方法更好仍依赖任务、成本和延迟目标。
核验与延伸:Build a Reasoning Model (From Scratch) ↗ · Manning ↗ · Amazon ↗ · Build a Large Language Model (From Scratch) ↗
解释
本块首次出现的知识点
本块相关内容已在前文介绍
来源与阅读说明
正文来自你提供的英文HTML,234个翻译单元逐一对齐,35张图片与原图说明均保留。数学式按原有符号与上下标在两栏显示。
图内接口和代码截图没有执行。作者观点与推测按原义翻译,已发现的概念歧义在“判断”中澄清;没有重新运行文中性能基准。
文中7月发表时的表述和后续Kimi K3更新一并保留。图片可离线查看,论文和其他外链需要联网。