KV, Prefix, Prompt and Semantic Caching in LLMs, clearly explained
讲清大语言模型中的 KV、前缀、提示与语义缓存
4,671 个英文词 · 18 个原文块 · 23 张保存图片 · 含 2 张视频预览
总结
文章沿着“单次生成 → 跨请求共享 → 服务商计费 → 直接复用回答”的顺序,讲解 KV、前缀、提示和语义缓存。前三者主要复用模型的中间状态,第四种复用最终文本。缓存是否值得使用,取决于重复发生在哪里、输入是否保持一致、缓存是否仍有效,以及旧回答能否用于新请求。
补充核验后,有几处需要特别留意:示例最后一个生成 token 的 KV 通常尚未计算;改动或截断旧工具输出会破坏改动位置之后的前缀;量化和 CacheBlend 不能一概视为完全精确的复用。计费已按 2026 年 9 月 11 日的官方文档核对:在文中 1.25 倍写入、0.1 倍读取的假设下,一次写入加一次完整读取就能低于两次普通输入的成本,具体仍要看型号、存活时间与实际命中量。
- KV 缓存
- 前缀复用
- 提示缓存计费
- 语义缓存
- 缓存失效
英文原文 01
226 词 · 2 张图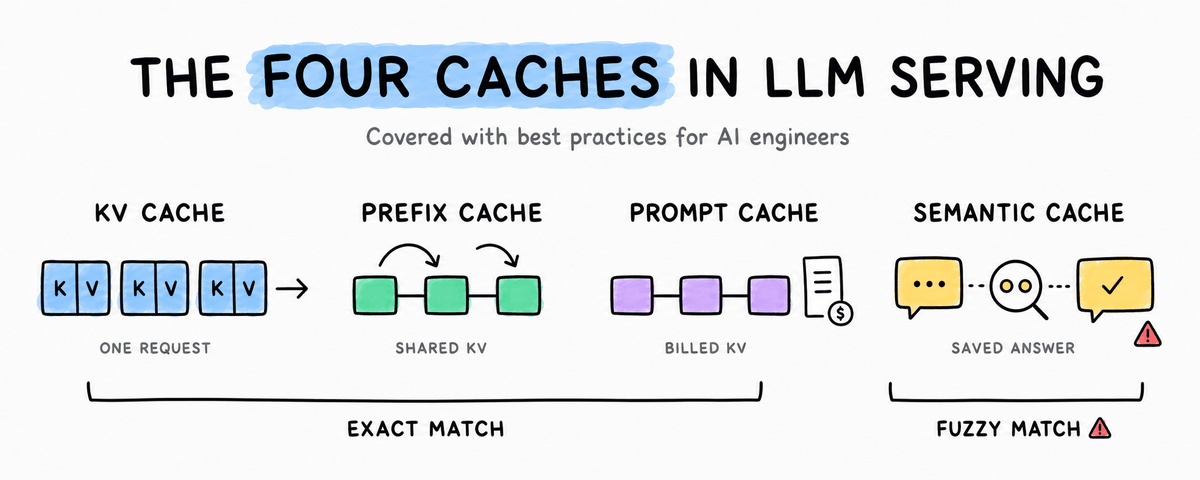
Everything you need to understand where your input tokens are being recomputed and what to do about it. It covers the four cache layers from first principles, their trade-offs, what happens when they interact, and the five most common problems that inhibit cache reuse.
Four things in an LLM stack store four different objects, and all of them get called caching.
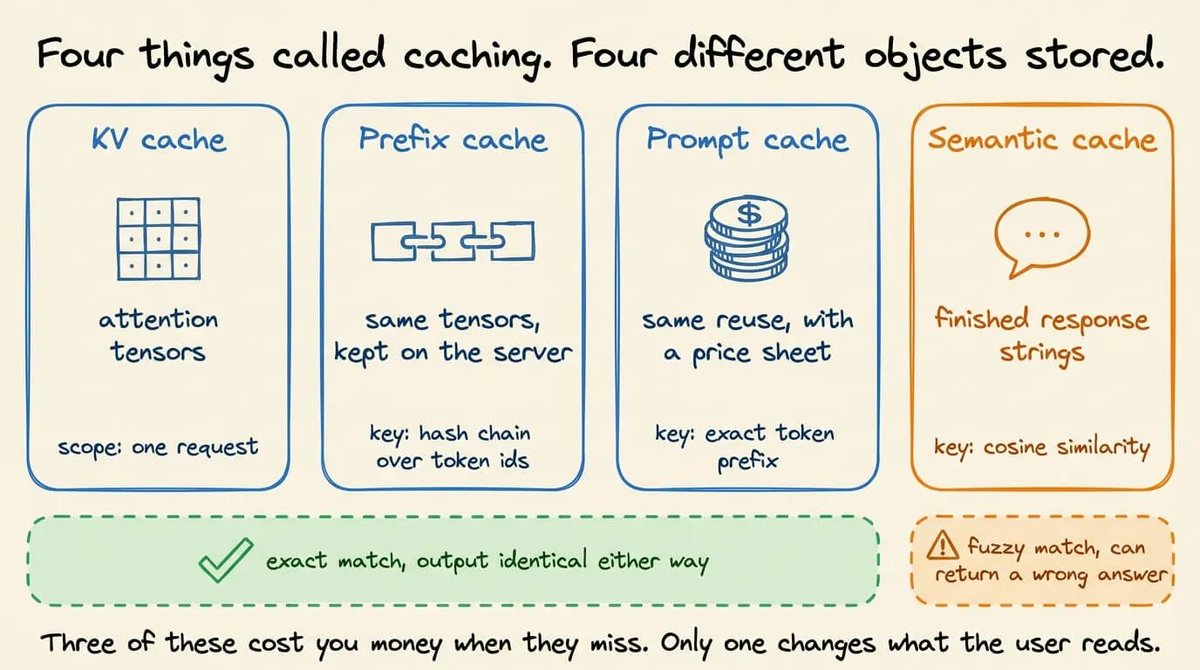
- The KV cache stores attention tensors for one request.
- Prefix caching stores those same tensors on the server, keyed by a hash chain over token IDs.
- Prompt caching is the provider’s billed version of that same lookup, at 0.1x the base input rate on a read against a 1.25x premium on the write.
- A semantic cache stores finished response strings, keyed by cosine similarity over an embedding.
The first three are exact-match and correctness-neutral, so a miss costs you money and latency. The fourth is fuzzy-match, and it will hand you a wrong answer with a 200.
So today, let’s go through all four, what each one stores, and what quietly breaks it.
Everything here runs on one machine, CPU included, with a 360M parameter model. There is also one Anthropic API example and one small semantic cache built on sentence-transformers. Where a mechanism only exists inside a serving engine, we walk the logic in pseudocode instead of pretending it is reproducible on a laptop.
中文译文 01
462 字这篇文章会帮助你弄清楚:输入 token 在哪些地方被重复计算,以及如何避免这些重复工作。我们会从基本原理出发,介绍四个层面的缓存、各自的取舍、它们相互作用时会发生什么,以及最常妨碍缓存复用的五类问题。
在大语言模型的技术栈里,有四样东西存着四种不同的对象,但它们都被称为缓存。
- KV 缓存保存单次请求中的注意力张量。
- 前缀缓存把同样的张量保存在服务器上,并通过基于 token ID 构建的哈希链来索引。
- 提示缓存是服务商对同一种查找与复用机制提供的计费服务:缓存读取按基础输入价格的 0.1 倍收费,写入则按 1.25 倍收费。
- 语义缓存保存已经生成的响应文本,并通过嵌入向量之间的余弦相似度进行查找。
前三种采用精确匹配,不影响结果的正确性,因此未命中时,损失主要体现在费用和延迟上。第四种采用模糊匹配,即使返回的是错误答案,HTTP 状态码也可能仍然是 200。
今天,我们就逐一看看这四种缓存:它们分别保存什么,又有哪些不易察觉的因素会让它们失效。
这里的示例使用一个 3.6 亿参数的模型,在一台机器上就能运行,只有 CPU 也可以。另外还有一个 Anthropic API 示例,以及一个用 sentence-transformers 构建的小型语义缓存。对于只有推理服务引擎内部才具备的机制,我们会用伪代码说明逻辑,而不会假装笔记本电脑就能完整复现。
上下游
本块首次出现的来源与延伸
区分当前查询、历史键值与下一步才会送入模型的 token。
已核对缓存与逐 token 生成流程按原文声明的 v5 版本核对接口,避免拿不同版本的例子直接拼接。
已核对动态、静态、量化及迭代生成缓存键包括前缀信息及必要的额外标识;空闲且仍有缓存内容的块可以被回收。
已核对哈希链、引用计数和 LRU文中的 Sonnet 4.6 示例适用 5 分钟写入与读取规则;其他型号或 TTL 要单独核对。
已核对断点、回溯窗口、门槛和计费在语义相似度之外,还需要控制条目有效期和适用范围。
已核对阈值、TTL 与过滤字段对应示例的 3.6 亿参数模型;教程中的具体生成结果不等于可复现的性能评测。
已核对官方模型卡本块新增 6 项
判断
对本块内容的判断
这段建立了一个有用的排查框架:缓存的是中间状态,还是最终回答。作者把前三类概括为精确复用,需要同时保留输入一致、配置兼容与数值精度这些前提。 模型、框架版本和运行设备都会影响示例能否直接执行。本页保留作者的代码与输出,按官方文档核对逻辑,但没有把这些输出当作已经复现的性能测试。
前三种缓存不是三种完全不同的数据对象
作者的分层对工程排查很有帮助,但它主要区分复用范围、生命周期和计费接口。前缀与提示缓存通常继续复用 KV 状态。所谓“不影响正确性”,也以正确的键、兼容配置和精确复用为前提,不包含量化误差或后文 CacheBlend 的近似处理,更不保证模型本身答对。Hugging Face · KV 缓存原理 ↗ · 定位原文 ↑
核验与延伸:Hugging Face · KV 缓存原理 ↗ · Transformers v5.0 · 缓存策略 ↗ · vLLM · Automatic Prefix Caching ↗ · Anthropic · 提示缓存文档 ↗
解释
本块首次出现的知识点
四种缓存与两种“命中”
KV、前缀、提示缓存都围绕模型中间状态工作:一次生成里保存状态,是 KV 缓存;让后续请求继续找这些状态,是前缀复用;通过托管 API 控制和计费,是提示缓存。语义缓存则保存已经完成的回答。
精确匹配问的是“这段输入和配置是否允许复用同一状态”;语义匹配问的是“两个问题是否足够相似”。后一个判断并不能自动保证回答通用。Hugging Face · KV 缓存原理 ↗ · RedisVL · SemanticCache API ↗
预填充、解码与首 token 延迟
预填充先处理整个提示,建立模型状态,并预测第一个输出 token。解码接着反复处理新 token,直到满足停止条件。首 token 延迟(TTFT)是从请求发出到看到第一个输出的等待时间;它还可能包含排队、传输和调度。
前缀复用减少预填充,并不直接删去后续输出步骤。一个请求整体快了多少,还要看输出有多长、排队是否变化。Hugging Face · KV 缓存原理 ↗
Q、K、V 与因果注意力
查询 Q 表示当前位置要找什么;键 K 用来计算匹配程度;值 V 提供被聚合的信息。简化的单头计算是:
这里 d 是注意力头的维度,softmax 把分数归一化为和为 1 的权重。因果掩码禁止当前位置读取未来内容。生成新 token 时,新的 Q 会读取历史 K、V,所以历史键值值得保存。缓存并没有取消 QKᵀ、softmax 或加权求和,只是避免重新计算已经处理过的历史状态。Hugging Face · KV 缓存原理 ↗
DynamicCache、StaticCache 和量化缓存
动态缓存按生成进度增长;静态缓存预先准备固定容量,有利于编译,但可能留出未使用空间。量化缓存用较少位数保存部分 KV 值,需要额外编码、还原以及辅助数据。
“省空间”和“更快”是两个目标,可能互相冲突。缓存可跨调用复用与否,取决于对象和输入是否兼容,不由 Dynamic 或 Static 这个名字单独决定。Transformers v5.0 · 缓存策略 ↗
本块新增 4 项
英文原文 02
266 词 · 3 张图Also, the cache API changed shape in transformers v5, so the snippets below assume v5 or later. On v4, the equivalents are DynamicCache() with no config argument and torch_dtype= instead of dtype=.
pip install "transformers>=5.0" torch

# only for the quantized cache example
pip install optimum-quanto

# only for the semantic cache example
pip install sentence-transformers

# only for the prompt caching example
pip install anthropic
1) The KV cache
During prefill, the model computes a key and value vector for every prompt token at every layer and stores them.
Decoding then attends over those stored vectors and appends one new pair per generated token, instead of recomputing the whole sequence each step.
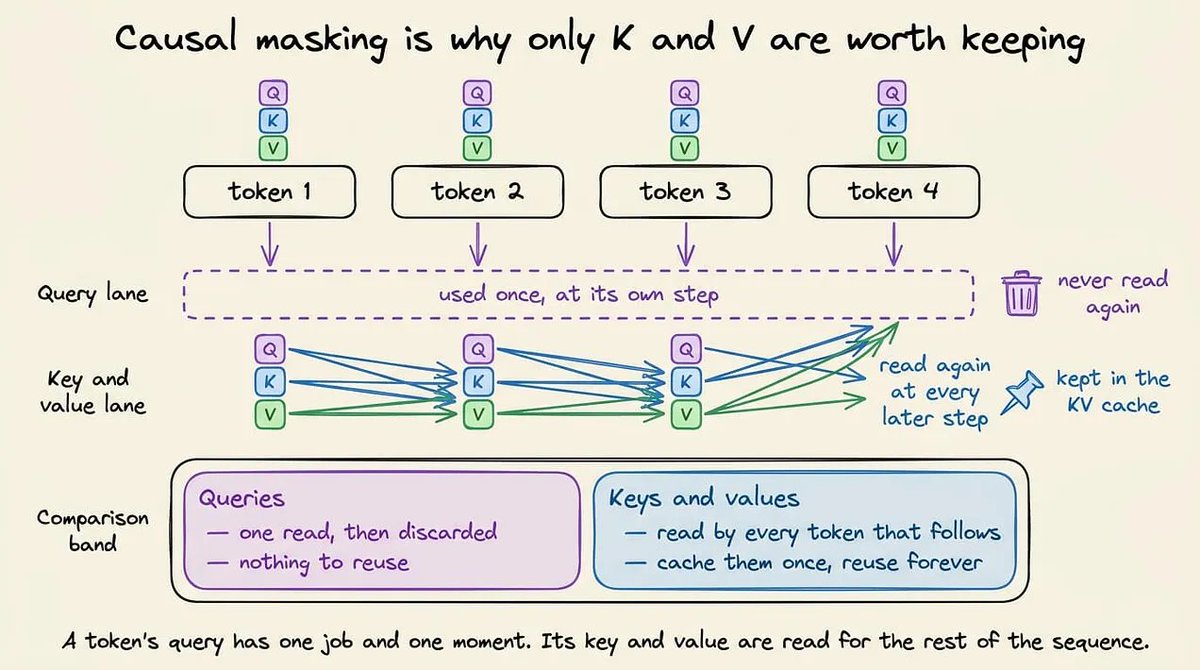
Queries don’t get cached, and the reason is causal masking. A token’s query vector is used once, at the step that token is processed, and never read again. Its key and value are read by every token that comes after it, so those are the two most important vectors to save.
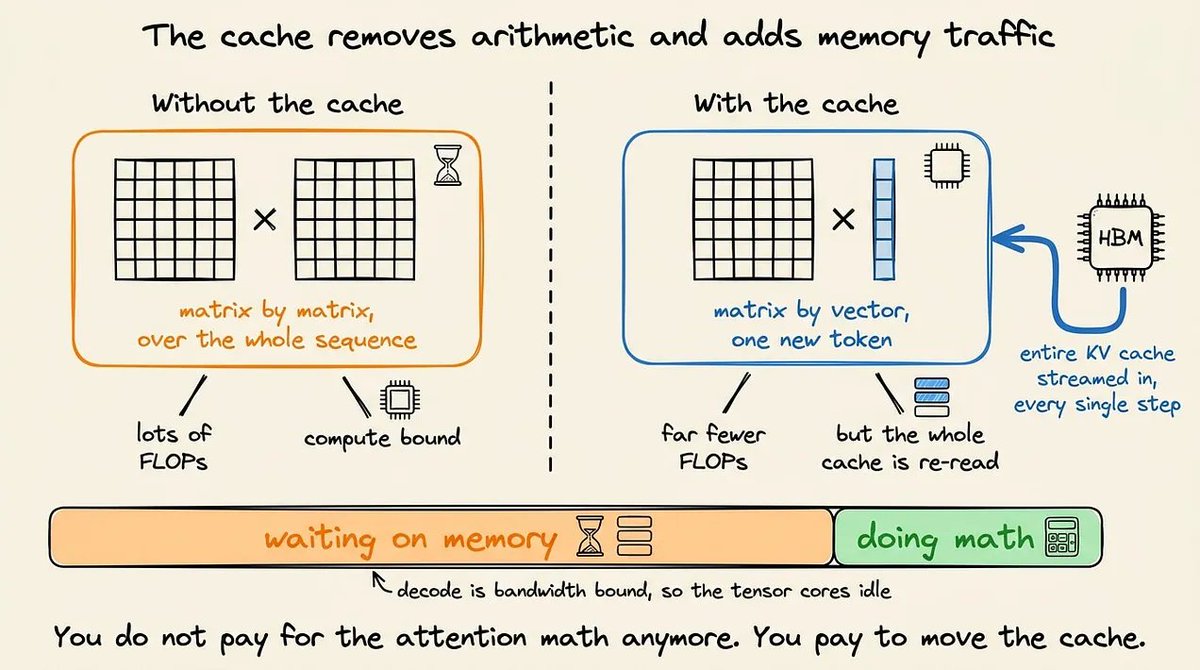
- Without storing them, each decode step requires a matrix-matrix multiply over the full sequence that has been generated so far.
- With it, the step becomes a matrix-vector multiply over one new token, which is far fewer FLOPs.
The video below depicts LLM inference with and without KV caching:
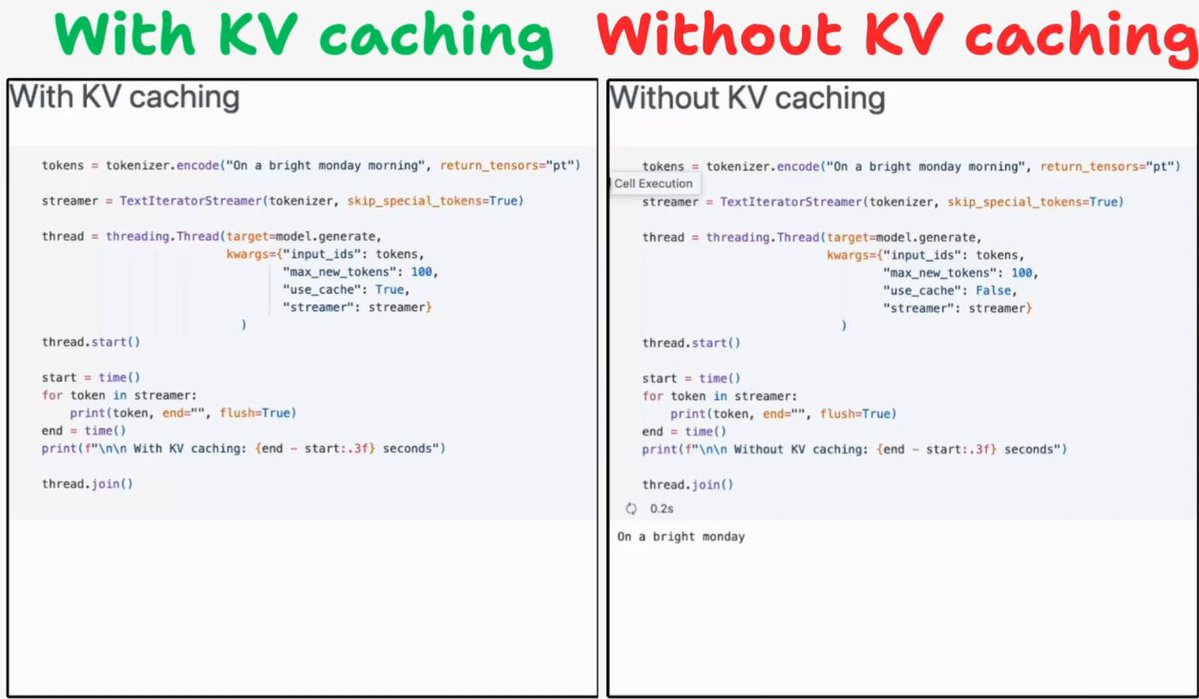
While this reduces the computation on each token, you have to load the entire cache from HBM on every single step, so decode is no longer compute-bound but rather becomes memory bandwidth-bound.
Attention kernels finish faster than the cache can be streamed in, and the GPU spends most of a decode step waiting on memory.
中文译文 02
470 字还要注意,transformers v5 调整了缓存 API,因此下面的代码假定使用 v5 或更新版本。在 v4 中,对应写法是不给 DynamicCache() 传入 config 参数,并用 torch_dtype= 代替 dtype=。
pip install "transformers>=5.0" torch

# only for the quantized cache example
pip install optimum-quanto

# only for the semantic cache example
pip install sentence-transformers

# only for the prompt caching example
pip install anthropic1)KV 缓存
在预填充(prefill)阶段,模型会在每一层为提示中的每个 token 计算一个键向量和一个值向量,并把它们保存下来。
随后,解码阶段会利用这些已保存的向量计算注意力,每生成一个 token 就追加一组新的键和值,而不必在每一步都重新计算整个序列。
查询向量不会被缓存,原因在于因果掩码。某个 token 的查询向量只在处理这个 token 的那一步使用一次,之后不会再被读取。它的键和值则会被后续所有 token 读取,因此最值得保存的是这两种向量。
- 如果不保存它们,每一步解码都需要对已经生成的整个序列进行矩阵与矩阵的乘法运算。
- 使用缓存后,每一步只需围绕一个新 token 做矩阵与向量的乘法,浮点运算量会少得多。
下面的视频展示了使用和不使用 KV 缓存时,大语言模型推理过程的区别:
虽然这样减少了每个 token 所需的计算,但每一步仍然要从高带宽显存(HBM)中读入整个缓存。因此,解码阶段不再主要受计算能力限制,而是转而受内存带宽限制。
注意力计算内核的处理速度比缓存数据读入的速度更快,GPU 在解码的大部分时间里都在等待内存数据。
上下游
本块首次出现的来源与延伸
本块相关内容已在前文介绍
判断
对本块内容的判断
模型、框架版本和运行设备都会影响示例能否直接执行。本页保留作者的代码与输出,按官方文档核对逻辑,但没有把这些输出当作已经复现的性能测试。 缓存历史 K、V 的理由基本成立。需要避免把“少做重复计算”进一步说成“注意力计算不再发生”,也不能只凭一张视频预览判断实际加速或硬件瓶颈。
使用缓存后,注意力计算并没有消失
图 5 底部“无需再为注意力运算付出代价”的说法过强。新查询仍要与历史键匹配,并对值加权;省去的是重复处理历史位置的工作。长上下文、小批量解码常受带宽限制,但是否成为瓶颈取决于批量、硬件、模型和实现,不能断言 GPU 大部分时间都在等缓存。Hugging Face · KV 缓存原理 ↗ · 定位原文 ↑
核验与延伸:Transformers v5.0 · 缓存策略 ↗ · SmolLM2-360M-Instruct · 模型卡 ↗ · Hugging Face · KV 缓存原理 ↗
解释
本块首次出现的知识点
KV 显存怎么估算,带宽又是什么
2 代表键和值两份数据。BF16 通常每个数占 2 字节。层数相同的模型,只要 KV 头数或批量不同,缓存占用就可能相差很多。GiB 使用 2³⁰ 字节,GB 使用 10⁹ 字节。
显存容量决定放得下多少,带宽决定每秒能搬运多少。缓存减少运算,却仍需读取历史状态;瓶颈要结合具体工作负载测量。
本块新增 1 项 · 另有 3 项已在前文介绍
英文原文 03
260 词 · 1 张图KV cache growth with each token
The `transformers` library exposes the cache as a first-class object, so you can hold it, inspect it, and pass it back in.
Here is a minimal code demo of it:
import torch
from transformers import AutoTokenizer, AutoModelForCausalLM, DynamicCache

model_id = "HuggingFaceTB/SmolLM2-360M-Instruct"
tokenizer = AutoTokenizer.from_pretrained(model_id)
model = AutoModelForCausalLM.from_pretrained(
    model_id, dtype=torch.bfloat16, device_map="auto"
)

inputs = tokenizer("The capital of France is", return_tensors="pt")
inputs = inputs.to(model.device)

past_key_values = DynamicCache(config=model.config)

out = model.generate(
    **inputs,
    do_sample=False,
    max_new_tokens=20,
    past_key_values=past_key_values,
)

>>> print(tokenizer.decode(out[0], skip_special_tokens=True))
"""The capital of France is Paris. It is the largest city in
France and the second-largest city in the European Union."""

>>> print("prompt tokens: ", inputs["input_ids"].shape[1])
"prompt tokens: 5"

>>> print("total tokens: ", out.shape[1])
"total tokens:  25"

>>> print("cache length: ", past_key_values.get_seq_length())
"cache length:  24"
Normally, you invoke the `generate` method and the cache is created and destroyed internally, invisible to you. Here we construct a DynamicCache ourselves and hand it in, which means we still hold a reference to it after generation finishes.
`get_seq_length()` then reports how many token positions the cache holds. When you run this, the output contains the prompt length plus the tokens generated, minus one.
The final token's key and value are computed but never attended over by anything.
This code shows the cache holds one entry per token seen, and it grows by exactly one entry per decode step.
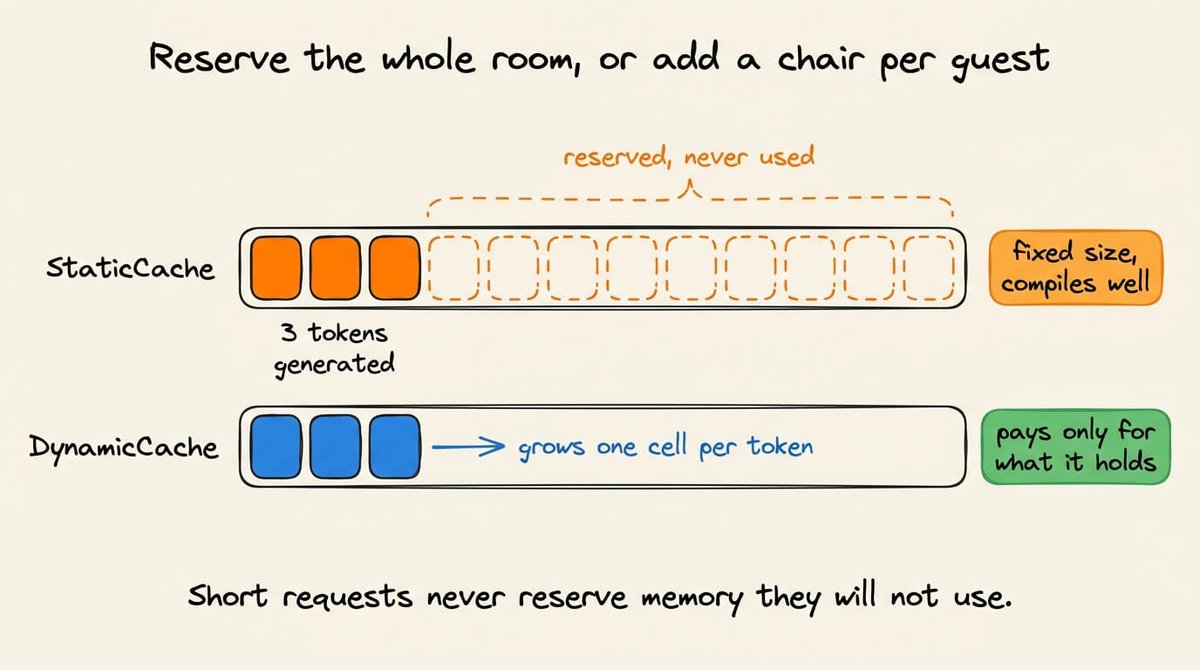
DynamicCache is used as the default because it grows as generation proceeds rather than pre-allocating, so short requests don't reserve memory they will never use.
中文译文 03
403 字KV 缓存如何随 token 增长
transformers 库把缓存作为可以直接操作的对象提供出来,因此你可以持有它、检查它,再把它传回模型。
下面是一个最小代码示例:
import torch
from transformers import AutoTokenizer, AutoModelForCausalLM, DynamicCache

model_id = "HuggingFaceTB/SmolLM2-360M-Instruct"
tokenizer = AutoTokenizer.from_pretrained(model_id)
model = AutoModelForCausalLM.from_pretrained(
    model_id, dtype=torch.bfloat16, device_map="auto"
)

inputs = tokenizer("The capital of France is", return_tensors="pt")
inputs = inputs.to(model.device)

past_key_values = DynamicCache(config=model.config)

out = model.generate(
    **inputs,
    do_sample=False,
    max_new_tokens=20,
    past_key_values=past_key_values,
)

>>> print(tokenizer.decode(out[0], skip_special_tokens=True))
"""The capital of France is Paris. It is the largest city in
France and the second-largest city in the European Union."""

>>> print("prompt tokens: ", inputs["input_ids"].shape[1])
"prompt tokens: 5"

>>> print("total tokens: ", out.shape[1])
"total tokens:  25"

>>> print("cache length: ", past_key_values.get_seq_length())
"cache length: 24"通常调用 generate 方法时,缓存会在内部创建和销毁,你看不到这个过程。这里我们自己创建一个 DynamicCache 并传入模型,因此生成结束后,仍然持有这个缓存对象的引用。
get_seq_length() 会返回缓存中保存了多少个 token 位置。运行这段代码时,你会看到,这个数量等于提示长度加上已生成的 token 数,再减去 1。
最后一个 token 的键和值已经计算出来了,但之后不会再有任何 token 对它们进行注意力计算。
这段代码说明,缓存会为每个已经处理过的 token 保存一个条目,而且每一步解码都会恰好增加一个条目。
DynamicCache 之所以被用作默认缓存,是因为它随着生成过程逐渐增长,而不是预先分配全部空间。这样,短请求就不会占用自己永远用不到的内存。
上下游
本块首次出现的来源与延伸
用于检查前向传播、采样新 token、追加序列与结束循环的先后关系。
已核对生成循环本块新增 1 项 · 另有 3 项已在前文介绍
判断
对本块内容的判断
显式持有 DynamicCache 有助于观察生成状态,示例的输入、输出和缓存长度值得分别比较。代码中的具体回答与 token 数属于作者展示的运行结果,并非每次运行都必须得到的常量。 这里有两个不同问题:最后一个生成位置是否已经写入缓存,以及某种架构的缓存占用是多少。应分别看生成循环的执行顺序和显存公式,不能把模型参数量当作唯一依据。
少一个缓存位置,是因为最后采样的 token 尚未再次进入模型
普通自回归 generate 循环先做前向传播,再选出下一 token;达到停止条件后,这个最新 token 通常不会再被送入模型。因此示例的 25 个输出位置对应 24 个缓存位置是合理的,但“最后 token 的 K、V 已经计算出来”解释相反。这里的判断针对文中的常规生成循环,不外推到所有特殊解码策略。Transformers v5.0 · generate 源码 ↗ · 定位原文 ↑
核验与延伸:Transformers v5.0 · 缓存策略 ↗ · Transformers v5.0 · generate 源码 ↗ · SmolLM2-360M-Instruct · 模型卡 ↗ · Hugging Face · KV 缓存原理 ↗
解释
本块首次出现的知识点
为什么生成 25 个位置,缓存却只有 24 个
把生成想成“读入已有 token → 做前向计算 → 选出下一个 token”。新选出的 token 要在下一轮被读入,才会建立自己的 KV。
例如提示长 5,第一次前向建立 5 个位置的缓存并选出第 6 个 token。再做 19 轮前向,缓存达到 24 个位置,同时选出第 25 个 token。若此时停止,第 25 个 token 尚未再次前向,所以缓存长度仍为 24。Transformers v5.0 · generate 源码 ↗
本块新增 1 项 · 另有 2 项已在前文介绍
英文原文 04
229 词 · 1 张图The cache decides how many requests can fit on a GPU. Its size is fixed by the model shape and grows linearly with token count, since every layer holds a key and value tensor for every KV head.
For a 70B model at BF16, a single 128K context holds around 40 GB of cache, comparable to the entire model at 4-bit weights.
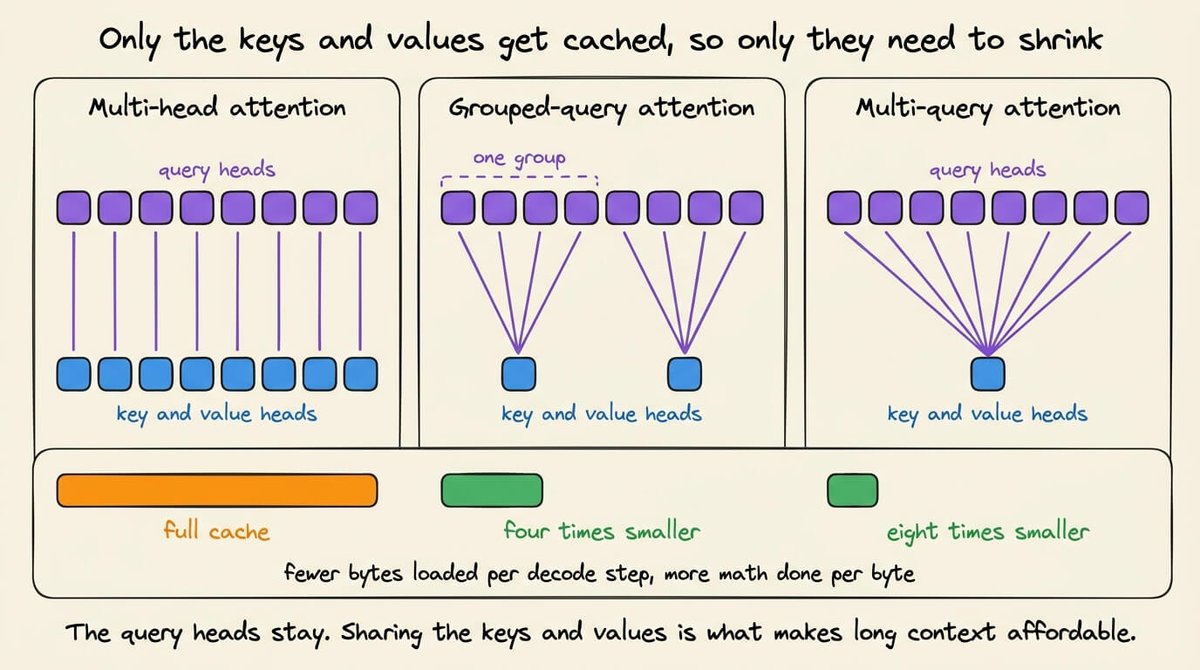
These are some ways to reduce this. For instance, Grouped-query attention shares one key and value head across a group of query heads, which shrinks the cache and raises FLOPs per byte of data loaded.
Multi-head latent attention in the DeepSeek line compresses the whole thing into a latent vector.
Cache quantization trades a little numerical accuracy for roughly double the capacity, and transformers implements it:
# requires: pip install optimum-quanto
out = model.generate(
    **inputs,
    do_sample=False,
    max_new_tokens=20,
    cache_implementation="quantized",
    cache_config={"nbits": 4, "backend": "quanto"},
)
print(tokenizer.decode(out[0], skip_special_tokens=True))
Two arguments replace the default cache with a quantized one.
The KV values are stored at reduced precision, which reduces memory at the cost of quantizing and dequantizing on every access.
The backend also requires the group size to divide the model's head dimension evenly, so an unusual architecture can reject the config outright.
On short contexts, that overhead can make things slower rather than faster, so it is best used when running low on memory.
中文译文 04
407 字缓存会影响一块 GPU 能同时容纳多少个请求。每个位置所需的缓存大小由模型结构决定;由于每一层都要为每个 KV 头保存键和值张量,缓存总量会随 token 数线性增长。
对于一个使用 BF16 的 700 亿参数模型,单个 128K 上下文大约需要 40 GB 的缓存,已经接近整个模型采用 4 位权重时所占的空间。
有几种办法可以减小缓存。例如,分组查询注意力(GQA)让一组查询头共享一个键头和值头,从而缩小缓存,并提高每读取一个字节的数据所能完成的浮点运算量。
DeepSeek 系列使用的多头潜在注意力(MLA),则把这些信息压缩进一个潜在向量。
缓存量化以少量数值精度损失,换取大约两倍的容量;transformers 也实现了这一功能:
# requires: pip install optimum-quanto
out = model.generate(
    **inputs,
    do_sample=False,
    max_new_tokens=20,
    cache_implementation="quantized",
    cache_config={"nbits": 4, "backend": "quanto"},
)
print(tokenizer.decode(out[0], skip_special_tokens=True))只需两个参数,就能把默认缓存换成量化缓存。
KV 值以更低的精度保存,因而占用更少内存,代价是在每次访问时都要进行量化和反量化处理。
后端还要求分组大小能够整除模型的注意力头维度,因此某些不常见的架构可能会直接拒绝这组配置。
上下文较短时,这些额外操作可能让推理变慢,而不是变快。因此,量化缓存更适合内存紧张的情况。
上下游
本块首次出现的来源与延伸
解释 GQA 如何在多头与单 KV 头之间选择共享粒度。
已核对论文摘要查看压缩注意力状态的模型设计背景。
已核对论文入口与架构主题提供低比特 KV 量化及精度、存储取舍的研究背景。
已核对论文摘要本块新增 3 项 · 另有 3 项已在前文介绍
判断
对本块内容的判断
这里有两个不同问题:最后一个生成位置是否已经写入缓存,以及某种架构的缓存占用是多少。应分别看生成循环的执行顺序和显存公式,不能把模型参数量当作唯一依据。 共享 KV 头、压缩注意力表示和降低存储精度是不同的机制。它们都可能减小占用,但不具有相同的数值性质;收益应由具体结构和配置决定。
700 亿参数本身不能确定缓存需要多少 GB
KV 大小取决于层数、KV 头数、头维度、序列长度、批量和精度。若取 80 层、8 个 KV 头、头维度 128、批量 1、BF16 和 131072 个位置,计算为 2×80×8×128×131072×2 字节,即 40 GiB,约 42.95 GB。这能解释“约 40 GB”的量级,但不能推广给所有 70B 架构。Hugging Face · KV 缓存原理 ↗ · 定位原文 ↑
4 位缓存不能直接概括成“容量翻倍”
从 16 位到 4 位,量化主体的理论位宽变为四分之一;实际节省还受比例参数、未量化残差区和其他开销影响。原文“约两倍容量”不是由 nbits=4 就能推出的固定结论。短上下文可能变慢的提醒则与官方文档一致。Transformers v5.0 · 缓存策略 ↗ · 定位原文 ↑
核验与延伸:Transformers v5.0 · generate 源码 ↗ · Hugging Face · KV 缓存原理 ↗ · GQA · 原始研究论文 ↗ · DeepSeek-V2 · MLA 研究来源 ↗
解释
本块首次出现的知识点
MHA、GQA、MQA 与 MLA 的区别
多头注意力(MHA)通常让每个查询头各有自己的键和值。分组查询注意力(GQA)让一组查询头共享 KV;多查询注意力(MQA)让所有查询头共享一组 KV。查询头不必减少,但缓存的 KV 头数变少。
MLA 采用压缩表示来保存注意力所需的信息,它是另一种模型架构设计。不能把减少 KV 头数、量化数值、压缩表示当成同一个开关;各自的正确实现依赖模型结构。
本块新增 1 项 · 另有 3 项已在前文介绍
英文原文 05
292 词 · 1 张图The cache is freed with the request
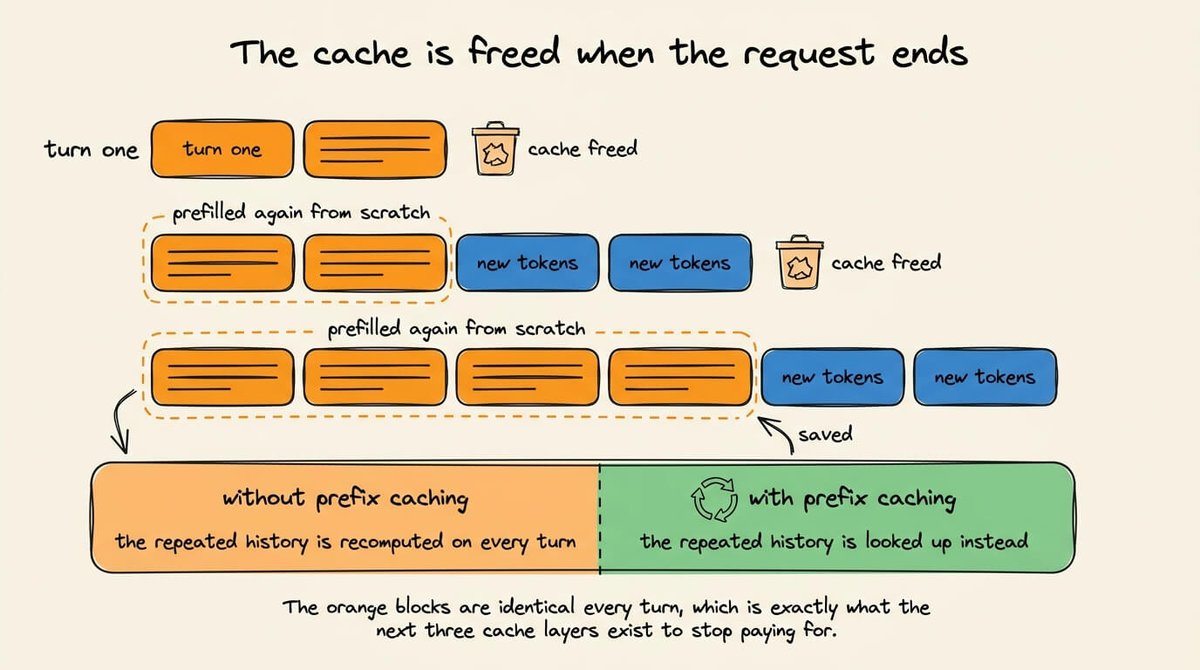
Everything above happens inside one call. The engine frees those blocks when the request finishes, so a 20-turn chat prefills turns 1 through 19 again on turn 20, at full cost.
You can see the alternative by keeping the cache alive yourself across turns.
import torch
from transformers import AutoTokenizer, AutoModelForCausalLM, DynamicCache

model_id = "HuggingFaceTB/SmolLM2-360M-Instruct"
tokenizer = AutoTokenizer.from_pretrained(model_id)
model = AutoModelForCausalLM.from_pretrained(
    model_id, dtype=torch.bfloat16, device_map="auto"
)

past_key_values = DynamicCache(config=model.config)
messages = []

questions = ["What is the capital of France?", "And its population?"]

for prompt in questions:
    # Add to the history
    messages.append({"role": "user", "content": prompt})

   # Tokenize
    inputs = tokenizer.apply_chat_template(
        messages,
        add_generation_prompt=True,
        return_tensors="pt", return_dict=True
    ).to(model.device)

    # Generate
    input_length = inputs["input_ids"].shape[1]
    outputs = model.generate(
         **inputs, do_sample=False,
         max_new_tokens=64,
         past_key_values=past_key_values
    )

    # decode
    completion = tokenizer.decode(outputs[0, input_length:], skip_special_tokens=True)

    # Append to message history
    messages.append({"role": "assistant", "content": completion})
    print(f"turn tokens in: {input_length} | cache now: {past_key_values.get_seq_length()}")

# Output:
"turn tokens in: 42 | cache now: 55"
"turn tokens in: 71 | cache now: 92"- The `past_key_values` object is created once, outside the loop, and passed into every generate call. That way, the cache is not freed at the end of turn one and is still populated when turn two begins.
- On each turn, we rebuild the full message list and re-render it through apply_chat_template. The prompt sent on turn two contains everything from turn one plus the new question.
- Because the cache already holds the tokens from turn one, the model only prefills the new suffix. The printed input_length grows every turn while the actual prefill work does not.
- The completion is sliced off the generated IDs and appended back into messages. That is what makes the next turn's prompt a strict extension of the last one.
中文译文 05
427 字请求结束后,缓存就会释放
上面的过程都发生在一次调用之内。请求完成后,引擎会释放对应的缓存块。因此,在一段 20 轮的对话中,第 20 轮还会重新预填充第 1 到第 19 轮的内容,并支付全部计算成本。
另一种做法是由你自己让缓存跨轮次存活,下面就能看到这种方式。
import torch
from transformers import AutoTokenizer, AutoModelForCausalLM, DynamicCache

model_id = "HuggingFaceTB/SmolLM2-360M-Instruct"
tokenizer = AutoTokenizer.from_pretrained(model_id)
model = AutoModelForCausalLM.from_pretrained(
    model_id, dtype=torch.bfloat16, device_map="auto"
)

past_key_values = DynamicCache(config=model.config)
messages = []

questions = ["What is the capital of France?", "And its population?"]

for prompt in questions:
    # Add to the history
    messages.append({"role": "user", "content": prompt})

   # Tokenize
    inputs = tokenizer.apply_chat_template(
        messages,
        add_generation_prompt=True,
        return_tensors="pt", return_dict=True
    ).to(model.device)

    # Generate
    input_length = inputs["input_ids"].shape[1]
    outputs = model.generate(
         **inputs, do_sample=False,
         max_new_tokens=64,
         past_key_values=past_key_values
    )

    # decode
    completion = tokenizer.decode(outputs[0, input_length:], skip_special_tokens=True)

    # Append to message history
    messages.append({"role": "assistant", "content": completion})
    print(f"turn tokens in: {input_length} | cache now: {past_key_values.get_seq_length()}")

# Output:
"turn tokens in: 42 | cache now: 55"
"turn tokens in: 71 | cache now: 92"- past_key_values 对象只在循环外创建一次,之后每次调用 generate 都传入它。这样,第一轮结束时缓存不会被释放,第二轮开始时里面仍保留着已有内容。
- 每一轮都会重新构建完整的消息列表,再通过 apply_chat_template 生成模型输入。第二轮发送的提示包含第一轮的全部内容,以及新问题。
- 由于缓存已经保存了第一轮的 token,模型只需要预填充新增的后缀。打印出的 input_length 每轮都会增长,但实际的预填充工作量不会随之增长。
- 代码从生成的 token ID 中截取新生成的回答,再把它追加到 messages 中。这就让下一轮提示严格延续上一轮的内容。
上下游
本块首次出现的来源与延伸
消息列表需转换为带角色边界的 token 序列,文本看起来相同仍不一定拥有相同前缀。
已核对角色与控制 token标题为 Why RAG Latency Is a Prefill Problem, Not a Retrieval Problem;是作者的扩展教程。
已核对页面标题与可见内容本块新增 2 项 · 另有 1 项已在前文介绍
判断
对本块内容的判断
在一次请求结束时释放缓存,是作者为说明问题选择的基线。示例转为显式持有对象后,能否复用还取决于下一轮输入与已有缓存是否对应,而不是只看变量是否仍存在。 消息历史追加与 token 序列严格追加并非天然等价。去除特殊标记、重新套模板或改变空白,都可能打破缓存对应关系;需要比较真实 token ID。
请求结束是否丢弃缓存,取决于持有者与服务策略
这一节描述的是不保留跨请求缓存的基线。调用者若继续持有缓存对象,或服务开启前缀缓存,历史状态可以继续存在。应把“释放请求的引用”和“清除可复用内容”区分开;后文共享池正是另一种生命周期。Transformers v5.0 · 缓存策略 ↗ · vLLM · Automatic Prefix Caching ↗ · 定位原文 ↑
重新拼装消息,不自动保证 token 前缀相同
沿用缓存时,必须核对已缓存部分的 token ID。解码时去掉特殊 token,再套聊天模板重新编码,可能改变角色边界或控制 token;官方文档也提示这种差异。模型仍需处理新增后缀,并对历史状态计算注意力,不能把“只计算新增部分”理解为预填充成本始终不随历史增长。Transformers v5.0 · 聊天模板 ↗ · Transformers v5.0 · 缓存策略 ↗ · 定位原文 ↑
核验与延伸:Transformers v5.0 · 缓存策略 ↗ · Transformers v5.0 · 聊天模板 ↗ · 作者的 RAG 系列 · 第 12 篇 ↗
解释
本块首次出现的知识点
真正匹配的是 token 前缀和相容配置
请求会先经过模板和分词器,成为 token ID 序列。角色标记、BOS(序列起始标记)、换行、空格或特殊结束符都可能进入序列。字符串在日志里相似,不等于模型看到的前缀相同。
已有缓存覆盖 k 个位置时,复用前应确认新请求的前 k 个 ID 与缓存来源一致,同时保持模型和相关配置兼容。聊天模板会处理角色边界,所以解码后再编码尤其需要检查。Transformers v5.0 · 聊天模板 ↗
本块新增 1 项 · 另有 2 项已在前文介绍
英文原文 06
238 词 · 1 张图Reuse only works because turn two's token sequence starts with turn one's token sequence, absolutely identical, bit by bit. If you edit anything earlier in the history, the cache becomes invalid.
In this code demo, the cache belongs to one Python variable in one process. In a serving engine, it belongs to a shared pool that thousands of requests look up against. Let's learn about that next.
2) Prefix caching
The shared pool discussed above comes from one change in behavior.
When a request finishes, the engine keeps its KV blocks in memory instead of freeing them, and leaves them indexed so a later request can find them. That is prefix caching.
The index has to enforce the same rule covered in the chat loop, where reuse is only valid if the earlier tokens are identical.
vLLM does that by storing the cache of 16 tokens by default and identifying each block by a hash over the parent block's hash plus the token IDs inside it.
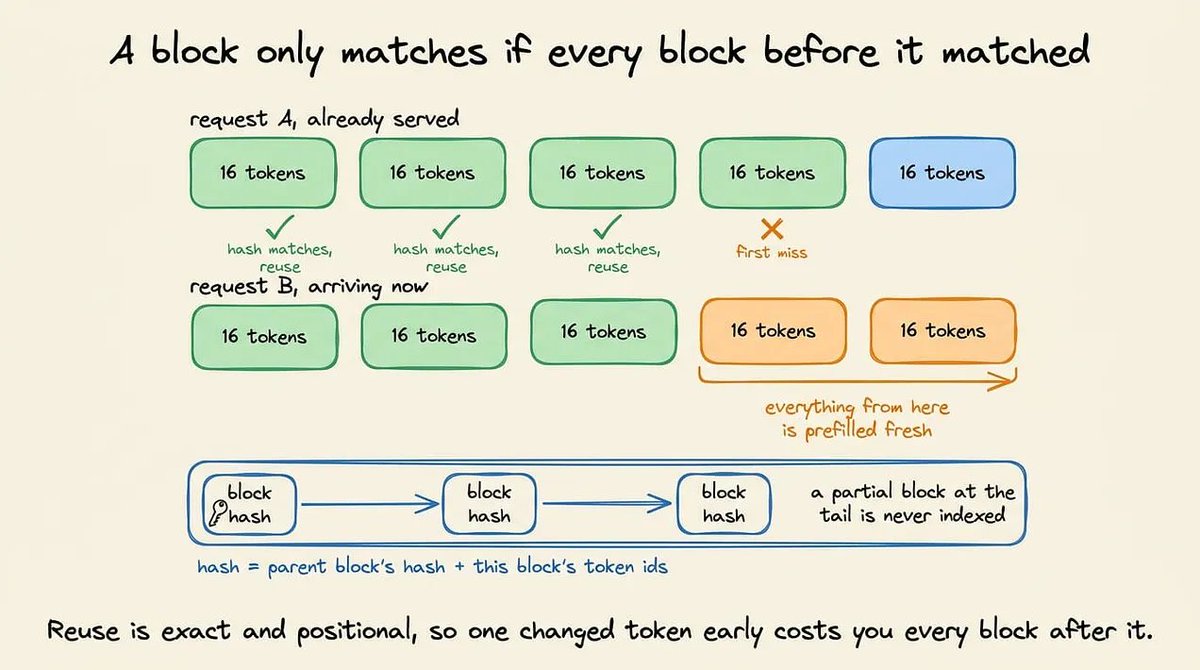
Chaining the parent hash into the child turns a block lookup into a prefix lookup, since a block only matches if everything before it matched too.
The scheduler iterates over the incoming blocks in order and stops at the first miss. A hit increments that block’s reference count, which also pins it against eviction while a request is using it.
Everything from the miss onward gets fresh allocation and a fresh prefill.
中文译文 06
421 字能够复用缓存,完全是因为第二轮的 token 序列以第一轮的 token 序列开头,而且两者逐位完全一致。如果修改了历史记录中较早的任何内容,缓存就会失效。 [1]
在这段示例里,缓存属于一个进程中的一个 Python 变量。到了推理服务引擎中,缓存则属于一个共享池,会被成千上万个请求查找和复用。接下来我们就讨论这个共享池。
2)前缀缓存
只需改变一项行为,就能得到前面提到的共享池。
请求完成后,引擎不会释放其中的 KV 块,而是继续把它们留在内存里,并保留索引,让后续请求能够找到。这就是前缀缓存。
索引必须遵守前面对话循环中的同一条规则:只有前面的 token 完全一致,缓存才可以复用。
vLLM 的做法是默认按每 16 个 token 保存一个缓存块,再把前一个块的哈希值与当前块中的 token ID 一起计算哈希,用它来标识这个块。
把父块的哈希值纳入子块的哈希计算,就能把单块查找变成前缀查找:只有前面的所有块都匹配,当前块才会匹配。
调度器会依次检查传入的各个块,在第一次未命中时停止。每次命中都会增加对应块的引用计数,使它在被请求使用期间不会遭到淘汰。
从未命中的位置开始,后面所有内容都会重新分配空间并进行预填充。
上下游
本块首次出现的来源与延伸
本块相关内容已在前文介绍
判断
对本块内容的判断
消息历史追加与 token 序列严格追加并非天然等价。去除特殊标记、重新套模板或改变空白,都可能打破缓存对应关系;需要比较真实 token ID。 作者用分块哈希解释跨请求复用,基本机制清楚。这里的键必须包含足以区分计算状态的信息,且块大小、可回收规则与具体实现有关。
哈希链展示了原理,但还不是生产缓存键
固定 16-token 分块用于理解算法是合适的,但块大小应以实际后端配置为准。Python 内置 hash 也不提供密码学级别的防碰撞保证。当前 vLLM 文档采用更完整的键:父哈希、token 及 LoRA(低秩适配器)、多模态输入、隔离 salt 等额外信息;这些条件不能省略。vLLM · Automatic Prefix Caching ↗ · 定位原文 ↑
核验与延伸:作者的 RAG 系列 · 第 12 篇 ↗ · Transformers v5.0 · 聊天模板 ↗ · Transformers v5.0 · 缓存策略 ↗ · vLLM · Automatic Prefix Caching ↗
解释
本块首次出现的知识点
哈希链为什么只能复用连续前缀
每个键都带着前面的信息,因此中途改一个 token,后面的键也会改变。查找从头开始,一旦遇到没有缓存的完整块,剩下的部分就需要重新处理。16 是文中示例的块大小,并非所有实现固定如此。
hash 是索引,不是语义相似度,也不自动证明不存在碰撞。实际系统还需选择合适的哈希算法和完整的缓存键。
引用计数、LRU 与缓存的“释放”
引用计数表示多少个活跃请求正在使用某块缓存。计数不为零时不能直接回收。计数归零后,块可以进入空闲队列,但其中的数据和索引未必立即清空。
当新请求需要空间时,LRU(最近最少使用)帮助选择淘汰对象。因此空闲可回收、保留可复用内容、仍被请求使用,是三个不同状态。命中率下降也可能来自流量变化,需结合日志判断。vLLM · Automatic Prefix Caching ↗
本块新增 2 项 · 另有 2 项已在前文介绍
英文原文 07
233 词 · 1 张图The lookup code
vLLM runs this inside its scheduler, wrapped in the memory management that owns the actual tensors.
The code below keeps only the two parts that decide reuse, i.e., the function that turns a token sequence into block keys and the function that walks those keys to work out how much of the prefix it can skip prefilling.
BLOCK_SIZE = 16

def block_hashes(token_ids, salt=None):
    """Chain-hash a token sequence into per-block keys."""

    hashes, parent = [], hash(salt)

    # Only complete blocks are hashed. A partial tail block is skipped.
    for start in range(0, len(token_ids) - BLOCK_SIZE + 1, BLOCK_SIZE):
        block = tuple(token_ids[start : start + BLOCK_SIZE])
        parent = hash((parent, block))
        hashes.append(parent)

    return hashes

def schedule(token_ids, cache):

    """Return how many tokens are reusable, and allocate the rest."""

    matched_blocks = 0

    for h in block_hashes(token_ids):
        if h not in cache:
            break                      # first miss ends all reuse
        cache[h].ref_count += 1        # pin it against eviction
        matched_blocks += 1

    reused_tokens = matched_blocks * BLOCK_SIZE
    to_prefill = token_ids[reused_tokens:]

return reused_tokens, to_prefill- The `block_hashes` method slices the token sequence into fixed 16-token blocks. Each block's key folds in the previous block's key through hash((parent, block)), so key number five encodes blocks one through five rather than block five alone.
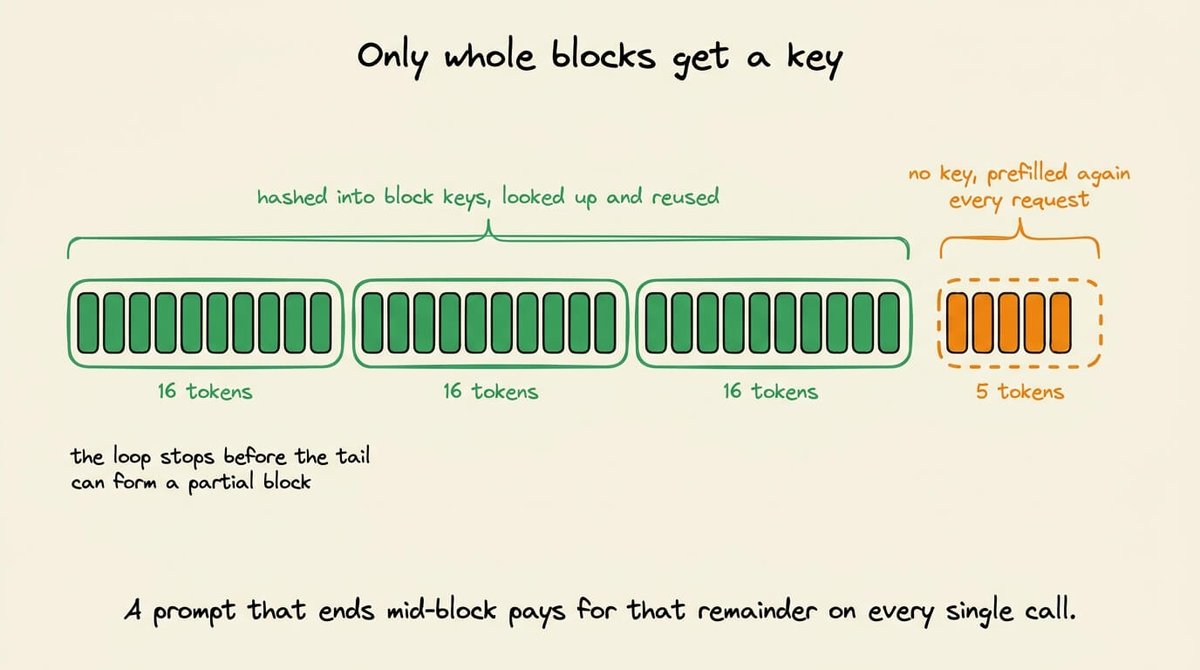
- The range stops at len(token_ids) - BLOCK_SIZE + 1, which drops any partial block at the tail. Those tokens are never indexed and get recomputed on every request that ends there.
中文译文 07
335 字查找逻辑的代码
vLLM 在调度器内部执行这套逻辑,而外层的内存管理负责持有真正的张量。
下面的代码只保留决定能否复用的两个核心部分:一个函数把 token 序列转换为缓存块的键,另一个函数依次检查这些键,确定前缀中有多少内容可以跳过预填充。
BLOCK_SIZE = 16

def block_hashes(token_ids, salt=None):
    """Chain-hash a token sequence into per-block keys."""

    hashes, parent = [], hash(salt)

    # Only complete blocks are hashed. A partial tail block is skipped.
    for start in range(0, len(token_ids) - BLOCK_SIZE + 1, BLOCK_SIZE):
        block = tuple(token_ids[start : start + BLOCK_SIZE])
        parent = hash((parent, block))
        hashes.append(parent)

    return hashes

def schedule(token_ids, cache):

    """Return how many tokens are reusable, and allocate the rest."""

    matched_blocks = 0

    for h in block_hashes(token_ids):
        if h not in cache:
            break                      # first miss ends all reuse
        cache[h].ref_count += 1        # pin it against eviction
        matched_blocks += 1

    reused_tokens = matched_blocks * BLOCK_SIZE
    to_prefill = token_ids[reused_tokens:]

return reused_tokens, to_prefill- block_hashes 方法把 token 序列切成固定大小的块,每块 16 个 token。通过 hash((parent, block)),每个块的键都包含前一个块的键。因此,第五个键编码的是第一到第五个块的整体信息,而不只是第五个块本身。
- 循环范围在 len(token_ids) - BLOCK_SIZE + 1 之前结束,因此尾部不足一整块的 token 会被跳过。它们不会建立索引;只要请求在这里结束,这部分内容就要重新计算。
上下游
本块首次出现的来源与延伸
本块相关内容已在前文介绍
判断
对本块内容的判断
这段代码刻意省略了真实张量管理,适合用来理解连续前缀命中。生产实现还需要更完整的键、分配、引用释放和冲突处理,不能直接把这个字典示例当作服务引擎。 完整块索引、遇到第一次未命中就停止,是本例的核心规则。增加引用计数只是生命周期的一半;真实请求结束后还需要正确减少引用并管理可回收块。
解释
本块首次出现的知识点
本块相关内容已在前文介绍
英文原文 08
270 词- The `schedule` method iterates over the keys in order and stops on the first missing one. There is no attempt to resume matching later in the sequence, because a later block's key already depends on the earlier one that failed.
- ref_count += 1 marks the block as in use. Eviction only touches blocks whose count is zero, which is what stops a running request from having its own cache pulled out from under it.
- Whatever gets matched becomes reused_tokens, and everything after it is prefilled fresh.
There's one more important thing in the code we just discussed:
BLOCK_SIZE = 16

def block_hashes(token_ids, salt=None):
    """Chain-hash a token sequence into per-block keys."""

    hashes, parent = [], hash(salt)

    # Only complete blocks are hashed. A partial tail block is skipped.
    for start in range(0, len(token_ids) - BLOCK_SIZE + 1, BLOCK_SIZE):
        block = tuple(token_ids[start : start + BLOCK_SIZE])
        parent = hash((parent, block))
        hashes.append(parent)

    return hashes
Notice the `salt` argument in the function above.
When two requests send identical text, they produce identical block keys, so they end up pointing at the same physical KV blocks in GPU memory. There is one copy of those tensors, and both requests read it.
That is the behavior you want when both requests come from the same application.
But it may need a decision when they come from different customers. So passing a per-tenant value as the salt changes the first parent hash, so identical text now produces different keys for each tenant and their requests never land on the same blocks.
This way, every tenant gets its own copy, which costs memory and hit rate but provides separation.
中文译文 08
405 字- schedule 方法按顺序遍历各个键,并在第一个缺失的键处停止。它不会尝试从后面继续匹配,因为后续块的键已经依赖于前面未命中的那个块。
- ref_count += 1 表示这个块正在被使用。淘汰操作只会处理引用计数为零的块,这样就能避免一个请求还在运行,它自己的缓存却被收走。
- 匹配到的部分计入 reused_tokens,剩下的所有内容则重新预填充。
刚才的代码中,还有一个重要的细节:
BLOCK_SIZE = 16

def block_hashes(token_ids, salt=None):
    """Chain-hash a token sequence into per-block keys."""

    hashes, parent = [], hash(salt)

    # Only complete blocks are hashed. A partial tail block is skipped.
    for start in range(0, len(token_ids) - BLOCK_SIZE + 1, BLOCK_SIZE):
        block = tuple(token_ids[start : start + BLOCK_SIZE])
        parent = hash((parent, block))
        hashes.append(parent)

return hashes注意上面函数里的 salt 参数。
两个请求发送相同的文本时,会生成相同的块键,因此最终会指向 GPU 内存中的同一组物理 KV 块。这些张量只保存一份,两个请求共同读取它们。
如果两个请求来自同一个应用,这通常就是我们想要的行为。
但如果它们来自不同客户,就需要作出取舍。为每个租户传入不同的 salt,会改变最初的父哈希值。这样,即使文本相同,不同租户也会生成不同的键,请求便不会落到同一组缓存块上。
如此一来,每个租户都有自己的一份缓存。虽然这会增加内存占用、降低命中率,但也实现了隔离。
上下游
本块首次出现的来源与延伸
本块相关内容已在前文介绍
判断
对本块内容的判断
完整块索引、遇到第一次未命中就停止,是本例的核心规则。增加引用计数只是生命周期的一半;真实请求结束后还需要正确减少引用并管理可回收块。 salt 改变哈希链,可以划定共享范围。需要留意的是,示例函数定义了这个参数,但调度函数的调用没有传入它;隔离必须落实到完整调用路径。 深拷贝让不同续写互不修改同一份示例缓存,但会产生随前缀长度增长的复制成本。它演示的是状态复用,不代表生产引擎的共享方式和开销。
示例的 schedule 没有传入租户 salt
block_hashes 的确接收 salt,但前一段 schedule 调用的是 block_hashes(token_ids),没有将租户值向下传递。因此这两段代码能说明隔离思路,却不能直接提供租户隔离。实际系统必须将经过验证的隔离标识贯穿写入和查找路径,并使用一致的模型与输入配置。此结论来自对原文代码的静态检查。vLLM · Automatic Prefix Caching ↗ · 定位原文 ↑
核验与延伸:vLLM · Automatic Prefix Caching ↗ · Transformers v5.0 · 缓存策略 ↗ · Transformers v5.0 · 聊天模板 ↗
解释
本块首次出现的知识点
salt 与缓存共享范围
salt 是参与索引计算的隔离标识。把租户标识加入键,可以让不同租户即使提交相同文本,也不会查到同一组缓存。
隔离会牺牲一部分共享机会;它还必须贯穿写入、读取和模型配置。示例函数有 salt 参数,不等于调用方已经正确传递。应用应在可信边界确定共享范围,不能只依靠用户随意提供的值。
本块新增 2 项 · 另有 3 项已在前文介绍
英文原文 09
281 词Implementation in transformers
transformers lets you prefill a prompt once and reuse the resulting cache across several different continuations.
import copy
import torch
from transformers import AutoModelForCausalLM, AutoTokenizer, StaticCache

model_id = "HuggingFaceTB/SmolLM2-360M-Instruct"
tokenizer = AutoTokenizer.from_pretrained(model_id)
model = AutoModelForCausalLM.from_pretrained(
    model_id, dtype=torch.bfloat16, device_map="auto"
)

SHARED_PREFIX = """You are a careful assistant.
                   Answer in one short sentence."""

prompt_cache = StaticCache(config=model.config, max_cache_len=1024)

prefix_inputs = tokenizer(SHARED_PREFIX, return_tensors="pt")
prefix_inputs = prefix_inputs.to(model.device)

# Prefill the shared prefix exactly once. No token is sampled here.
with torch.no_grad():
    prompt_cache = model(**prefix_inputs, past_key_values=prompt_cache)
    prompt_cache = prompt_cache.past_key_values

questions = ["What is the capital of France?", "Name one ocean."]

for question in questions:
    inputs = tokenizer(SHARED_PREFIX + question, return_tensors="pt")
    inputs = inputs.to(model.device)

    # each request gets its own copy
    past_key_values = copy.deepcopy(prompt_cache)

    outputs = model.generate(
        **inputs, past_key_values=past_key_values, do_sample=False
    )
print(tokenizer.decode(outputs[0], skip_special_tokens=True))- `StaticCache` is used instead of DynamicCache because we need a fixed allocation we can copy around.
- The model(...) call is a prefill. No token is sampled here. We run the shared prefix through the model purely to populate the cache, then keep the returned past_key_values.
- Inside the loop, each question is concatenated onto the same prefix. The full string is tokenized, so the token IDs for the prefix portion are identical every time, which is exactly the condition the engine's hash chain checks for.
- copy.deepcopy gives each request its own copy of the prefilled cache. Generation mutates the cache in place by appending, so without the copy, the first question would corrupt the prefix for the second. A production engine does not copy the tensors. Instead, it shares the physical blocks and tracks reference counts, which is what makes reuse nearly free instead of proportional to prefix length.
中文译文 09
406 字在 transformers 中实现
transformers 允许先对一段提示进行一次预填充,再把得到的缓存用于多个不同的后续生成任务。
import copy
import torch
from transformers import AutoModelForCausalLM, AutoTokenizer, StaticCache

model_id = "HuggingFaceTB/SmolLM2-360M-Instruct"
tokenizer = AutoTokenizer.from_pretrained(model_id)
model = AutoModelForCausalLM.from_pretrained(
    model_id, dtype=torch.bfloat16, device_map="auto"
)

SHARED_PREFIX = """You are a careful assistant.
                   Answer in one short sentence."""

prompt_cache = StaticCache(config=model.config, max_cache_len=1024)

prefix_inputs = tokenizer(SHARED_PREFIX, return_tensors="pt")
prefix_inputs = prefix_inputs.to(model.device)

# Prefill the shared prefix exactly once. No token is sampled here.
with torch.no_grad():
    prompt_cache = model(**prefix_inputs, past_key_values=prompt_cache)
    prompt_cache = prompt_cache.past_key_values

questions = ["What is the capital of France?", "Name one ocean."]

for question in questions:
    inputs = tokenizer(SHARED_PREFIX + question, return_tensors="pt")
    inputs = inputs.to(model.device)

    # each request gets its own copy
    past_key_values = copy.deepcopy(prompt_cache)

    outputs = model.generate(
        **inputs, past_key_values=past_key_values, do_sample=False
    )
print(tokenizer.decode(outputs[0], skip_special_tokens=True))- 这里使用 StaticCache 而不是 DynamicCache,是因为我们需要一块固定分配、可以复制的缓存。
- model(...) 这次调用执行的是预填充,不会采样任何 token。我们让共享前缀通过模型,只为填充缓存,然后保留返回的 past_key_values。
- 循环内部,每个问题都追加在同一个前缀后面,再对完整字符串进行分词。这样,前缀部分的 token ID 每次都相同,正好符合引擎用哈希链检查的条件。
- copy.deepcopy 会为每个请求复制一份已经完成预填充的缓存。生成过程会原地追加内容、修改缓存;如果不复制,第一个问题就会改变缓存,导致第二个问题无法正确复用前缀。生产环境中的引擎不会复制这些张量,而是共享物理块并跟踪引用计数。因此,复用的开销可以很低,不必随前缀长度一起增长。
上下游
本块首次出现的来源与延伸
本块相关内容已在前文介绍
判断
对本块内容的判断
深拷贝让不同续写互不修改同一份示例缓存,但会产生随前缀长度增长的复制成本。它演示的是状态复用,不代表生产引擎的共享方式和开销。 StaticCache 的固定容量有自己的用途,但不是复制或复用的唯一前提。缓存是否可用仍应检查完整 token 前缀,尤其是字符串拼接后的分词边界。
StaticCache 不是跨请求复用的唯一选择
固定分配有利于编译和预先规划空间,但不是“能复制缓存”的必要条件,DynamicCache 也可以用于迭代复用。完整字符串重新分词时,也应检查拼接边界处的前缀 ID,而不是仅凭字符串相同就作保证。文中的深拷贝示例用于演示分支,不能等同于共享物理块的真实服务成本。Transformers v5.0 · 缓存策略 ↗ · Transformers v5.0 · 聊天模板 ↗ · 定位原文 ↑
核验与延伸:Transformers v5.0 · 缓存策略 ↗ · Transformers v5.0 · 聊天模板 ↗
解释
本块首次出现的知识点
本块相关内容已在前文介绍
英文原文 10
225 词 · 3 张图The impact of eviction on hit rate
As discussed above, only complete blocks get indexed, so a trailing partial block is recomputed every time.
This means the block size should be tuned appropriately
- Larger blocks imply fewer table lookups and better memory locality
- Smaller blocks imply finer-grained sharing and less waste at the tail.
Eviction reduces hit rates, as expected.
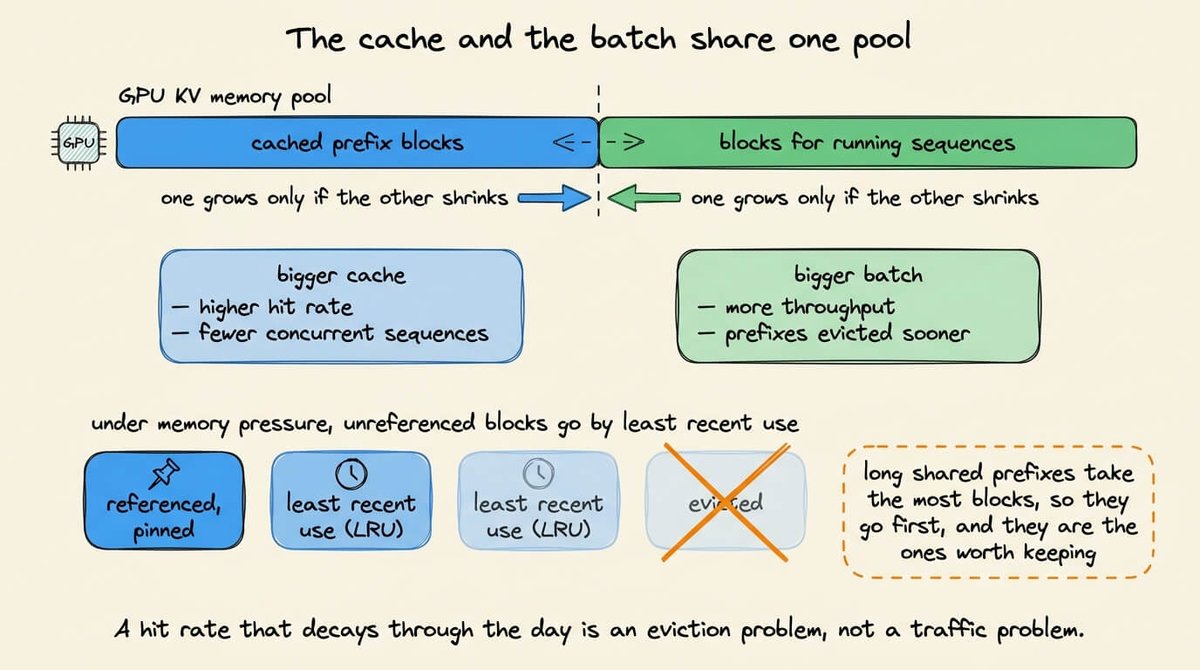
The cache and the running batch draw from the same GPU memory pool, so a larger cache leads to fewer concurrent sequences, and under pressure vLLM drops unreferenced blocks by least recent use.
Mixed traffic makes this worse, because long shared prefixes occupy the most blocks and are the ones whose loss actually hurts.
Before you turn this on, you should know two things
- It saves prefill only, so decode time is unchanged and crediting a whole speedup to the cache will overstate it.
- And the hashing itself costs something, so on traffic with genuinely unique prompts, benchmarks have measured a throughput regression rather than a gain.
There’s a third problem, which is workload dependent, and it impacts RAG the most.
 GIF
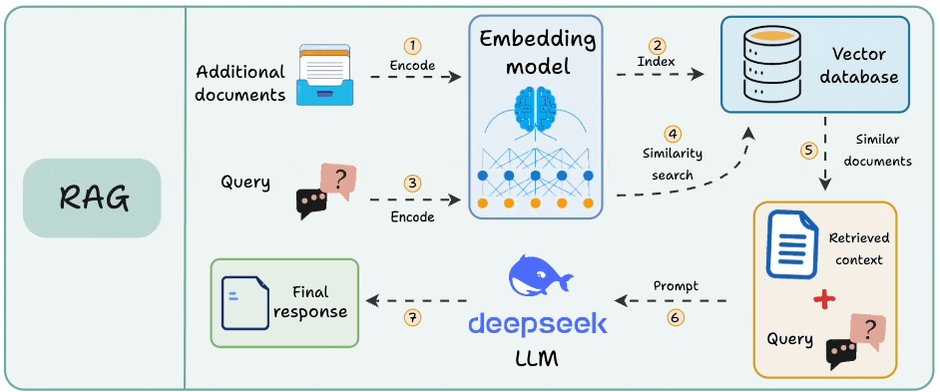
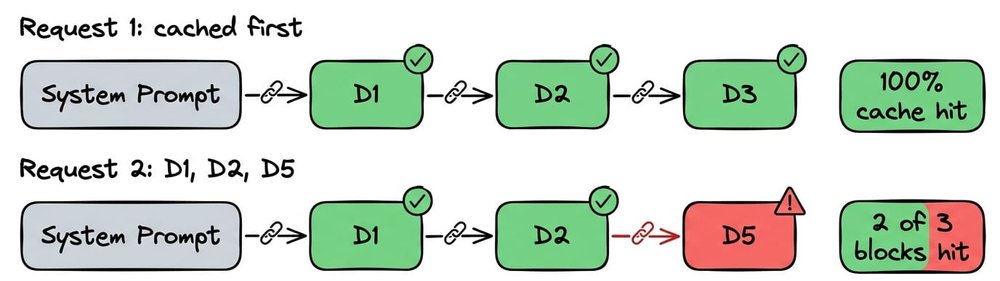
A RAG prompt includes a system instruction, then retrieved chunks, then the query, and the chunks change per request and change order between requests. Two requests that retrieve the same documents in a different order share nothing at all under the chain hash.
中文译文 10
428 字缓存淘汰如何影响命中率
前面说过,只有完整块会建立索引,因此尾部不足一块的内容每次都要重新计算。
这意味着,块大小需要根据实际情况调整。
- 较大的块意味着更少的索引查找,以及更好的内存局部性。
- 较小的块意味着可以更细致地共享缓存,尾部浪费也更少。
不难理解,淘汰缓存会降低命中率。
缓存和正在运行的批次使用同一个 GPU 内存池,因此缓存越大,能并发运行的序列就越少。内存紧张时,vLLM 会按照最近最少使用原则,淘汰没有被引用的块。
混合流量会让问题更加明显,因为较长的共享前缀占用最多的块,而失去它们的缓存,代价也最大。
启用前缀缓存之前,有两点需要了解。
- 它只节省预填充,解码时间并不会改变。如果把全部加速都归功于缓存,就会高估它的收益。
- 哈希计算本身也有开销。因此,当请求中的提示几乎都不重复时,有些基准测试测到的是吞吐量下降,而不是提升。
还有第三个问题,它取决于工作负载,对 RAG 的影响尤其明显。
GIFRAG 提示通常由系统指令、检索出的文本块和查询依次组成。检索块会随请求变化,块的顺序也会改变。在这种链式哈希机制下,即使两个请求检索到了相同文档,只要顺序不同,也无法共享任何缓存。
上下游
本块首次出现的来源与延伸
本块相关内容已在前文介绍
判断
对本块内容的判断
StaticCache 的固定容量有自己的用途,但不是复制或复用的唯一前提。缓存是否可用仍应检查完整 token 前缀,尤其是字符串拼接后的分词边界。 前缀命中率受容量、复用间隔和流量结构共同影响。RAG 文档顺序变化会缩短公共前缀,但不会自动抹掉差异点之前仍然相同的系统内容。
LRU 不等于优先淘汰最长前缀
图 11 把“长前缀占块多”进一步画成“因此最先被淘汰”,又把命中率下降排除为流量问题,这两点都不充分。LRU 依据使用顺序和可回收状态;vLLM 的空闲队列也可包含仍有缓存内容的块。判断命中率变化,需要同时检查请求分布、复用间隔、容量和淘汰记录。vLLM · Automatic Prefix Caching ↗ · 定位原文 ↑
文档重排不会抹掉它前面的公共系统前缀
若两个请求都以相同系统指令开头,即使后面的文档顺序不同,差异点之前的完整前缀仍可能复用。真正失去复用的是首次不匹配位置及其后的部分。图 13 对公共部分的示意比“完全没有共享”这句话更准确。vLLM · Automatic Prefix Caching ↗ · 定位原文 ↑
核验与延伸:Transformers v5.0 · 缓存策略 ↗ · Transformers v5.0 · 聊天模板 ↗ · vLLM · Automatic Prefix Caching ↗
解释
本块首次出现的知识点
RAG 的分块缓存为什么不能直接拼接
RAG 把检索出的资料加入提示。某份资料单独处理时没有读过其他资料,位置编号也可能从头开始。文中的注意力汇聚点(attention sink),指注意力容易集中到的少数位置,这里主要是各段开头。把各自 KV 首尾拼接,不会自动补上跨资料的影响。
CacheBlend 通过复用大部分状态、选择性重算一部分 token 来修复差异,并将重算与缓存读取重叠。这是一种需要评测质量的近似优化。前面的公共系统前缀仍可使用普通精确复用。CacheBlend · 研究论文 ↗ · LMCache · Blending 实现说明 ↗
本块新增 1 项 · 另有 5 项已在前文介绍
英文原文 11
200 词 · 3 张图Prefilling each chunk on its own and stitching the caches together does not work.
The stitched tensors carry the wrong positional encoding. No chunk ever attended to any other chunk. And every chunk contributes its own attention sink at what the model thinks is position zero. Making it work needs partial recomputation at the boundaries rather than plain concatenation.
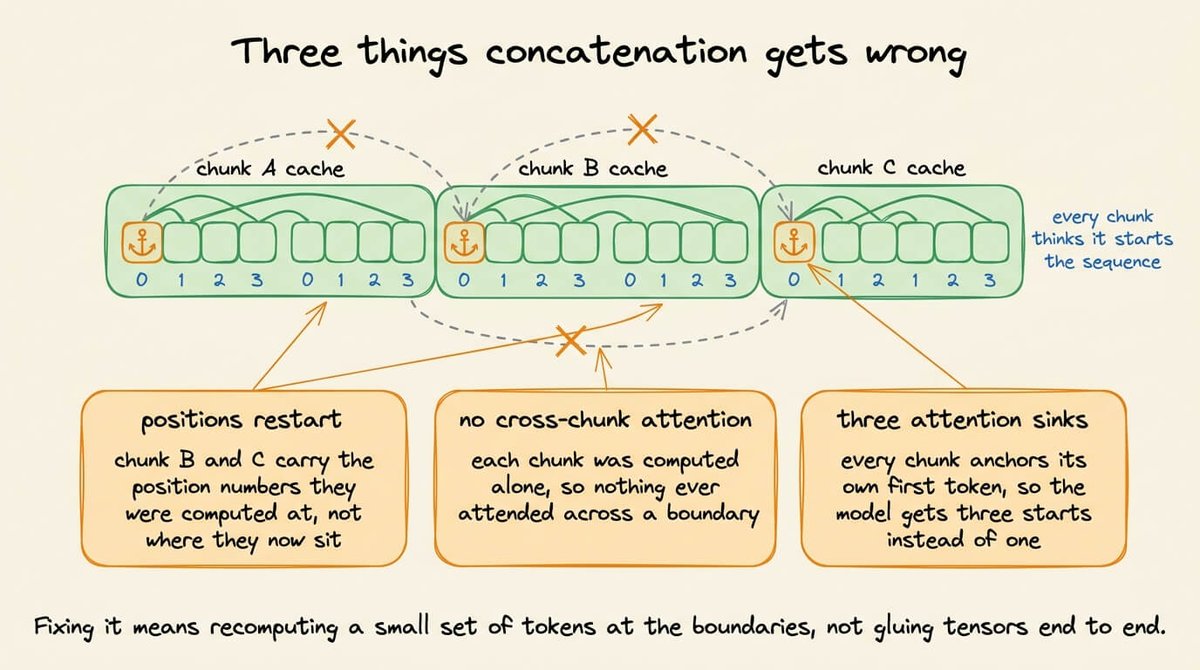
Btw, the solution already exists in open source.
LMCache (open-source) implements CacheBlend, wherein, instead of gluing the chunk caches end to end, it reuses them at any position and recomputes only a small subset of tokens, chosen by where the precomputed values deviate most from what full attention would have produced.
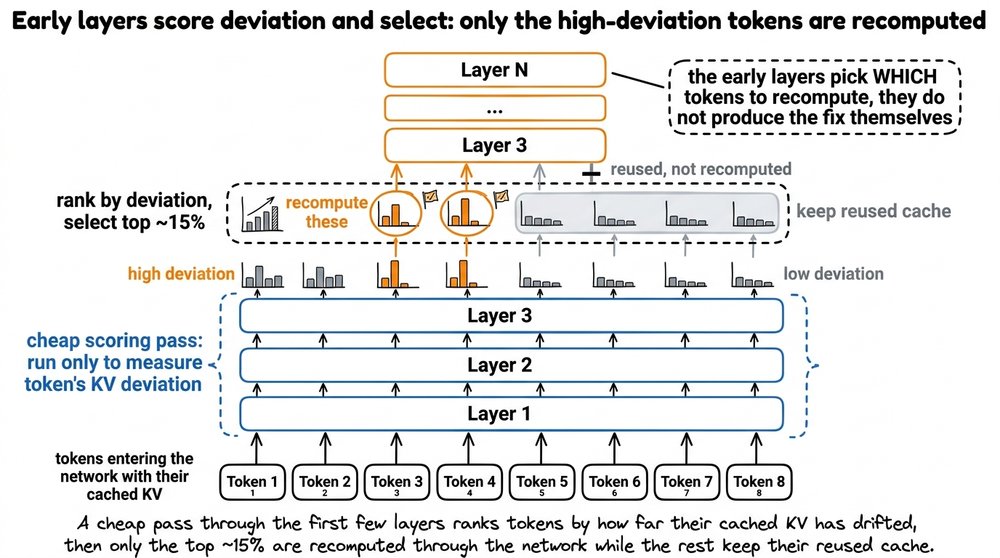
That subset restores the cross-chunk attention and fixes up the positional encoding, so the output holds at full-prefill quality.
This leads to an improvement in the time to first token by roughly two to three times compared to recomputing everything, with the recompute cost pipelined against fetching the cached chunks from slower storage.
It plugs into vLLM and reads the chunk boundaries out of your prompt, so retrieval traffic gets reused even when the retrieved documents arrive in a different order each time.
Here's the repo: https://github.com/LMCache/LMCache
中文译文 11
383 字先分别预填充每个文本块,再把各自的缓存拼在一起,并不能解决问题。
拼接后的张量携带着错误的位置编码,各个文本块也从未对其他块计算过注意力。而且,每个块都会在模型认为是位置零的地方,产生自己的注意力汇聚点。要让这种复用真正生效,需要在边界处进行部分重算,而不是简单拼接。
顺便说一句,开源社区已经有解决方案了。
开源项目 LMCache 实现了 CacheBlend。它不会简单地把各块缓存首尾相接,而是允许在不同位置复用缓存,并只重新计算一小部分 token。这些 token 的选择依据是:预先计算的值,与完整注意力计算本应得到的值,在哪些位置偏差最大。 [1]
重新计算这部分 token,可以恢复跨块注意力并修正位置编码,使输出达到完整预填充的质量。
与全部重新计算相比,这种做法能把首 token 延迟缩短到原来的约二分之一至三分之一。同时,重算可以与从较慢存储中读取缓存块的过程流水线并行。
它可以接入 vLLM,并从提示中读取文本块的边界。因此,即使每次检索得到的文档顺序不同,也能复用检索内容对应的缓存。
项目仓库在这里:https://github.com/LMCache/LMCache [1]
上下游
本块首次出现的来源与延伸
连接 KV 缓存管理、跨请求复用与推理服务集成。
已读项目说明论文报告特定实验中的首 token 延迟和吞吐收益;质量保持是实验结果。
已核对论文摘要与实验范围查看文本块边界、重算设置与集成条件,不能把示意图直接当作通用配置。
已核对实现文档新模型的写入、读取倍率与旧模型规则不同,不能凭历史经验判定原文错误。
已核对 GPT-5.6 及以后与旧模型的差异本块新增 4 项 · 另有 1 项已在前文介绍
判断
对本块内容的判断
原文从精确前缀复用转向了允许部分重算的研究方法。质量与速度的说法要回到论文所测模型和任务,不应把近似质量保持误解为与完整预填充逐位相同。 这段把工程缓存连接到服务商的计费接口。示例中稳定系统指令与变化用户消息分开,是合理的结构;图中写入与读取的回本时点需按实际算式判断。
CacheBlend 的质量和加速要放在实验条件下理解
CacheBlend 不是简单拼接,也不保证与完整预填充逐 token 完全等价。论文在三种开源模型、四个数据集上报告首 token 延迟改善 2.2–3.3 倍,支持原文“约两到三倍”的量级,但不证明所有模型和请求都保持同样质量。重算位置也不应被简化为只发生在文本块边界。CacheBlend · 研究论文 ↗ · LMCache · Blending 实现说明 ↗ · 定位原文 ↑
核验与延伸:LMCache · 官方仓库 ↗ · CacheBlend · 研究论文 ↗ · LMCache · Blending 实现说明 ↗ · Anthropic · 提示缓存文档 ↗
解释
本块首次出现的知识点
断点、TTL、最小长度和回溯窗口
断点标记希望保存的前缀终点;TTL 决定条目在多长时间内可能继续有效;最小长度是服务商允许缓存的门槛;回溯窗口限制本次查找能检查哪些旧写入位置。它们不是同一个限制。
以 Anthropic 当前规则为例,回溯找的是过去真正写入过的条目,不能替你缓存从未标记过的静态内容。追加式对话和每次替换末尾消息的独立请求,需要不同的断点安排。Anthropic · 提示缓存文档 ↗
缓存计费与回本条件
设同一段前缀的普通输入成本为 C,写入倍率为 w,读取倍率为 r,共调用 n 次;若第一次写入、之后全部完整命中:
无缓存:Cn
代入 w=1.25、r=0.1,n=2 时是 1.35C 对 2C,即第一次完整读取就回本。实际还有冷写、未命中、未缓存后缀和输出费用,不能只盯着折扣倍率。型号和保存时长变化时需要重新计算。OpenAI · 提示缓存文档 ↗
本块新增 2 项 · 另有 2 项已在前文介绍
英文原文 12
231 词 · 1 张图3) Prompt caching
On a hosted model, you don’t get any block table or the eviction policy. Instead, you get a price sheet over the provider’s own prefix reuse, plus two knobs for control.
The cached object is still KV tensors, not your prompt text, and it still requires an exact prefix match on the fully rendered context.
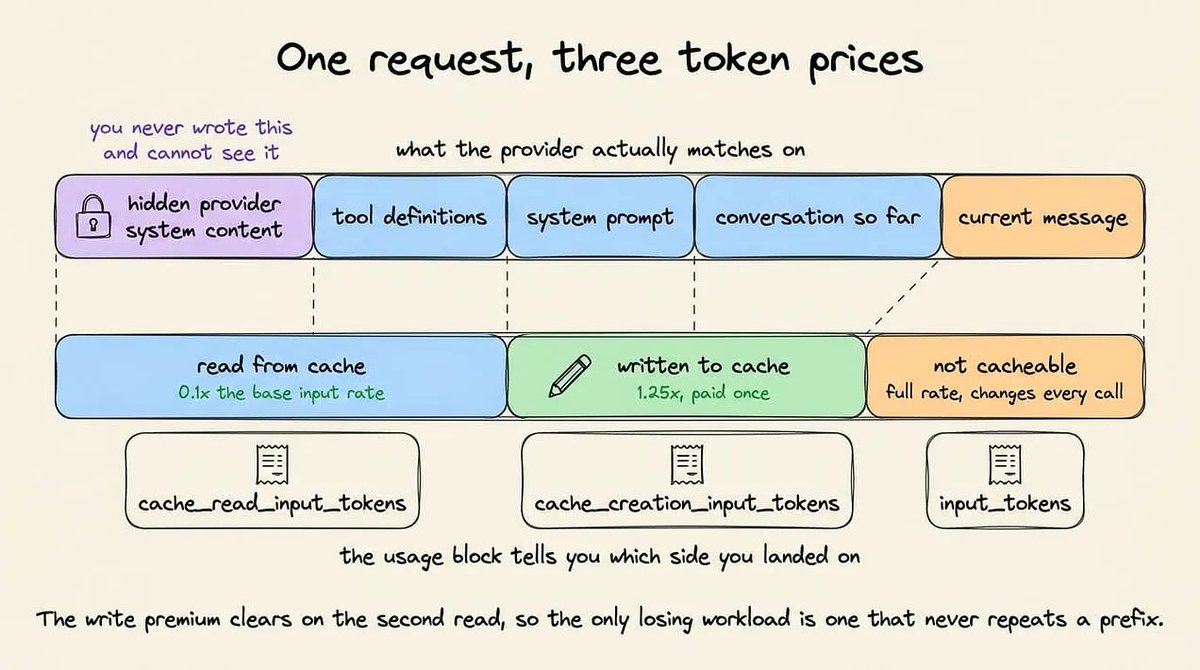
The rendered context includes provider-side system content you never wrote, which is part of why the minimum lengths and the invalidation rules look arbitrary from the outside.
Here's a version of prompt caching demonstrated with code:
import anthropic

client = anthropic.Anthropic()   # reads ANTHROPIC_API_KEY from the environment

# Must clear the model's minimum cacheable length or nothing is cached at all.
LONG_INSTRUCTIONS = "You are a precise technical editor. " * 400

def ask(question: str):
    return client.messages.create(
        model="claude-sonnet-4-6",
        max_tokens=512,
        system=[
            {
                "type": "text",
                "text": LONG_INSTRUCTIONS,
                "cache_control": {"type": "ephemeral"},   # everything above is cacheable
            }
        ],
        messages=[{"role": "user", "content": question}],
    )

for question in ["Summarize section 3.", "Now rewrite it for a beginner."]:
    resp = ask(question)
    u = resp.usage
    print(
        f"write={u.cache_creation_input_tokens} "
        f"read={u.cache_read_input_tokens} "
        f"uncached={u.input_tokens}"
    )

# Output:
"write=2823  read=0     uncached=14"
"write=0     read=2823  uncached=17"
Only one line in that snippet touches the cache.
Where you specify `cache_control` decides which part of the request gets an entry written for it, and the usage counters tell you whether a later call read that entry back.
中文译文 12
334 字3)提示缓存
使用托管模型时,你无法直接操作缓存块表或淘汰策略。服务商提供的是一套前缀复用的价格规则,以及两个可供调整的控制项。
缓存的对象仍然是 KV 张量,而不是提示文本;匹配条件也仍然是:完整渲染后的上下文必须具有完全一致的前缀。
渲染后的上下文还包含服务商添加、并非由你编写的系统内容。这也是为什么从外部看来,最小长度和失效规则似乎有些难以理解。
下面用代码演示一种提示缓存的用法:
import anthropic

client = anthropic.Anthropic()   # reads ANTHROPIC_API_KEY from the environment

# Must clear the model's minimum cacheable length or nothing is cached at all.
LONG_INSTRUCTIONS = "You are a precise technical editor. " * 400

def ask(question: str):
    return client.messages.create(
        model="claude-sonnet-4-6",
        max_tokens=512,
        system=[
            {
                "type": "text",
                "text": LONG_INSTRUCTIONS,
                "cache_control": {"type": "ephemeral"},   # everything above is cacheable
            }
        ],
        messages=[{"role": "user", "content": question}],
    )

for question in ["Summarize section 3.", "Now rewrite it for a beginner."]:
    resp = ask(question)
    u = resp.usage
    print(
        f"write={u.cache_creation_input_tokens} "
        f"read={u.cache_read_input_tokens} "
        f"uncached={u.input_tokens}"
    )

# Output:
"write=2823  read=0     uncached=14"
"write=0 read=2823 uncached=17"这段代码里,只有一行直接设置了缓存。
cache_control 放在哪里,就决定为请求中的哪一部分写入缓存条目;用量计数器则会告诉你,后续调用是否读取了这个条目。
上下游
本块首次出现的来源与延伸
本块相关内容已在前文介绍
判断
对本块内容的判断
这段把工程缓存连接到服务商的计费接口。示例中稳定系统指令与变化用户消息分开,是合理的结构;图中写入与读取的回本时点需按实际算式判断。 查看 API 返回的缓存用量字段,比只看响应变快更可靠。未缓存原因仍需结合请求设置判断;示例中的最小长度条件与具体模型绑定。
一写一读就能回本,不需要等到第二次读取
图 17 的“second read”容易混淆第二次请求和第二次缓存读取。按其给定倍率,一次写入加一次完整读取为 1.25+0.1=1.35,已经低于两次普通输入的 2。这里假定同一前缀在有效期内完整命中,不包括额外冷写、未缓存后缀和输出费用。OpenAI · 提示缓存文档 ↗ · 定位原文 ↑
核验与延伸:LMCache · 官方仓库 ↗ · Anthropic · 提示缓存文档 ↗ · OpenAI · 提示缓存文档 ↗
解释
本块首次出现的知识点
本块相关内容已在前文介绍
英文原文 13
264 词 · 1 张图- The marker is attached to the last block you want covered, not to a range. It writes one cache entry spanning everything from the start of the request up to and including that block.
- The user message sits below the marker, so it stays outside the cached region since it changes every call, so it must not be inside.
- The usage counters tell you what's happening under the hood. The first call reports a non-zero cache_creation_input_tokens and a zero read. The second reports the reverse, and the instructions are billed at a tenth of the input rate.
- If both counters come back as zero, the prefix was below the model's minimum cacheable length, and the request was processed with no caching at all. No error is raised for this.
Intuitively (and as discussed above), if we move cache_control down onto the user message, the read counter will always be zero, because the marked block changes on every call.
The economics of prompt caching
Anthropic charges 1.25x the base input rate to write an entry and 0.1x to read it, with a higher write multiplier if you want it for a longer time. OpenAI applies the same two multipliers on its current models.
The premium cost is recovered in subsequent requests since anything reused inside the TTL will avoid any recomputation.
A read can only find an entry that some earlier request wrote, and writes happen only at a breakpoint you placed.
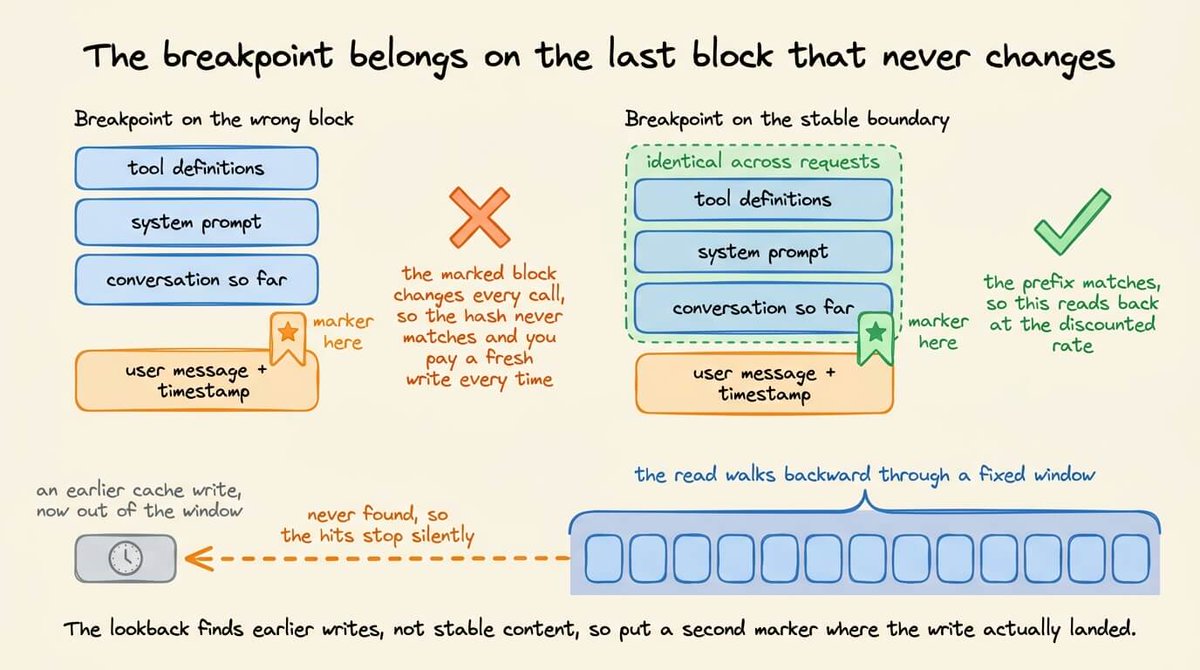
Each call checks your breakpoint, and on a miss it walks backward through a limited number of blocks looking for an older write.
中文译文 13
456 字- 标记应加在希望缓存的最后一个内容块上,而不是标记一个区间。它会写入一个缓存条目,覆盖从请求开头到该块为止、并且包含该块的全部内容。
- 用户消息放在标记之后,因此不属于缓存区域。因为它每次调用都会变化,所以不应该包含在这个区域里。
- 用量计数器能显示实际发生了什么:第一次调用的 cache_creation_input_tokens 不为零,读取量为零;第二次则相反,此时指令部分按输入价格的十分之一计费。
- 如果两个计数器都是零,说明前缀没有达到该模型允许缓存的最小长度,请求完全没有使用缓存。遇到这种情况,API 不会报错。
直观地说,如果把 cache_control 下移到用户消息上,由于被标记的块每次调用都在变化,读取计数就会一直是零,这与前面讨论的情况一致。
提示缓存的成本如何计算
Anthropic 按基础输入价格的 1.25 倍收取缓存写入费,读取则按 0.1 倍收费;如果希望缓存保留更久,写入倍率还会更高。OpenAI 当前的模型也采用相同的这两个倍率。
后续请求可以抵消首次写入增加的成本,因为只要在存活时间(TTL)内成功复用,对应内容就不必重新计算。
读取只能找到某个先前请求已经写入的条目,而写入只会发生在你设置的缓存断点处。
每次调用都会先检查当前断点;如果没有命中,就在有限数量的内容块内向前回溯,寻找更早的缓存写入位置。
上下游
本块首次出现的来源与延伸
说明余弦相似度、向量点积、分块搜索与规模取舍。
已核对归一化与精确检索它面向句子和短段落;默认超过 256 个 word piece 会截断,长上下文不能直接照搬。
已核对用途与输入长度本块新增 2 项 · 另有 3 项已在前文介绍
判断
对本块内容的判断
查看 API 返回的缓存用量字段,比只看响应变快更可靠。未缓存原因仍需结合请求设置判断;示例中的最小长度条件与具体模型绑定。 独立请求每次替换变量后缀,与对话不断向后追加,命中机制不同。倍率也需按模型和 TTL 核对;不能把旧版 API 规则套到文中提到的新模型上。 这里跨越了两类查找:回溯已有的精确前缀写入,以及搜索相似问题。它们的命中含义不同,不能共用同一套正确性或成本判断。
变化的末尾断点不代表任何场景都无法命中
替换唯一的变量用户消息、又没有在静态前缀处留下旧写入时,确实会一直未命中。但在只向尾部追加消息的对话中,新的断点可以回溯并找到上一轮写入,读取量不必为零。当前 Anthropic 也提供自动断点方式,不能把手工逐块标记当成唯一入口。Anthropic · 提示缓存文档 ↗ · 定位原文 ↑
1.25 倍写入、0.1 倍读取有明确适用范围
截至核验日,Sonnet 4.6 的 5 分钟缓存符合这组倍率,1 小时写入为 2 倍;Anthropic 的部分新型号有不同读取倍率。OpenAI 官方文档确认 GPT-5.6 及以后采用 1.25 倍写入、0.1 倍读取,旧型号保留不同规则。因此原文对新款 OpenAI 模型的说法有依据,但不能概括所有型号与所有缓存时长。Anthropic · 提示缓存文档 ↗ · OpenAI · 提示缓存文档 ↗ · 定位原文 ↑
核验与延伸:Anthropic · 提示缓存文档 ↗ · OpenAI · 提示缓存文档 ↗ · Sentence Transformers · 语义检索 ↗ · all-MiniLM-L6-v2 · 模型卡 ↗
解释
本块首次出现的知识点
嵌入、归一化与余弦相似度
嵌入模型把文本转换为向量。余弦相似度比较向量方向:
两个向量都归一化为单位长度后,点积就等于余弦相似度。这衡量的是编码器学习到的相近程度,不是逻辑等价或回答正确的概率。文中的 MiniLM 默认会截断超过 256 个 word piece 的输入,不能不加处理地拿来编码任意长对话。all-MiniLM-L6-v2 · 模型卡 ↗
语义缓存要评测“错用旧答案”的比例
缓存命中率高,不代表答案可靠。需要用真实业务样例标注哪些问题可以共用回答,分别测量正确命中、错误命中、未命中以及整体延迟和成本。
缓存键或过滤条件还应包含影响答案的租户、语言、权限、知识库版本和上下文,并配合 TTL。相似度高也不能省掉这些判断。精确响应缓存没有模糊匹配问题,但同样可能返回陈旧答案。RedisVL · SemanticCache API ↗
本块新增 2 项 · 另有 2 项已在前文介绍
英文原文 14
339 词 · 1 张图Anthropic caps that at 20 blocks, so adding more than 20 blocks of conversation between two calls pushes the last write out of range and the hits stop.
4) Semantic caching
The three techniques above save prefill work and still run the model.
A semantic cache embeds the incoming prompt, runs a nearest-neighbor search over stored prompts, and returns a stored response outright when the similarity exceeds a threshold.
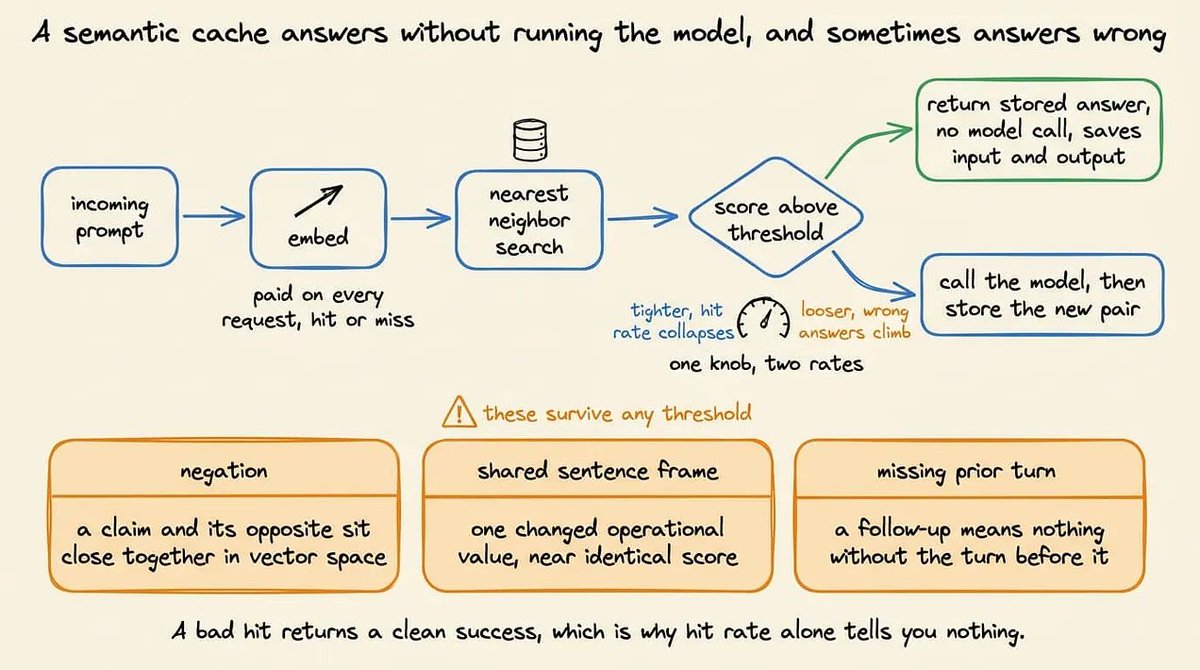
That’s why it saves output tokens as well as input. It’s also why every request must bear an embedding round trip, including every miss.
Here's a working semantic cache demo in a few lines of code:
# requires: pip install sentence-transformers
import numpy as np
from sentence_transformers import SentenceTransformer

encoder = SentenceTransformer("all-MiniLM-L6-v2")

class SemanticCache:
    def __init__(self, threshold=0.95):
        self.threshold = threshold
        self.vectors = np.empty((0, encoder.get_sentence_embedding_dimension()))
        self.prompts, self.responses = [], []

    def _embed(self, text):
        return encoder.encode([text], normalize_embeddings=True)[0]

    def lookup(self, prompt):
        vec = self._embed(prompt)
        if len(self.prompts) == 0:
            return None, 0.0, vec
        scores = self.vectors @ vec           # cosine sim, vectors are unit length
        best = int(np.argmax(scores))
        if scores[best] >= self.threshold:
            return self.responses[best], float(scores[best]), vec
        return None, float(scores[best]), vec

    def store(self, prompt, response, vec):
        self.vectors = np.vstack([self.vectors, vec])
        self.prompts.append(prompt)
        self.responses.append(response)

cache = SemanticCache(threshold=0.95)

def answer(prompt, call_model):
    hit, score, vec = cache.lookup(prompt)
    if hit is not None:
        return hit, f"HIT  (score {score:.3f})"
    response = call_model(prompt)             # the expensive path
    cache.store(prompt, response, vec)
    return response, f"MISS (best {score:.3f})"

# Stand in for the model so this runs without an API key.
fake_model = lambda p: f"<answer for {p!r}>"

for q in ["How do I reset my password?",
          "How can I reset my password?",
          "Is the API rate limited?"]:
    _, status = answer(q, fake_model)
    print(f"{status}  {q}")


# Output:
"MISS (best 0.000)  How do I reset my password?"
"HIT  (score 0.961)  How can I reset my password?"
"MISS (best 0.112)  Is the API rate limited?"
Every method in the class above maps onto a decision you have to make in production:
中文译文 14
453 字Anthropic 把这个查找范围限制为 20 个块。因此,如果两次调用之间追加了超过 20 个对话块,上一次写入的位置就会落到范围之外,缓存便不再命中。 [1]
4)语义缓存
前面的三种技术都能节省预填充工作,但仍然需要运行模型。
语义缓存会为输入提示生成嵌入向量,在已保存的提示中做最近邻搜索;如果相似度超过阈值,就直接返回已保存的回答。
因此,它不仅能节省输入 token,也能节省输出 token。但这也意味着,每个请求都要经历一次嵌入处理,包括所有未命中的请求。
下面用几行代码实现一个可以运行的语义缓存示例:
# requires: pip install sentence-transformers
import numpy as np
from sentence_transformers import SentenceTransformer

encoder = SentenceTransformer("all-MiniLM-L6-v2")

class SemanticCache:
    def __init__(self, threshold=0.95):
        self.threshold = threshold
        self.vectors = np.empty((0, encoder.get_sentence_embedding_dimension()))
        self.prompts, self.responses = [], []

    def _embed(self, text):
        return encoder.encode([text], normalize_embeddings=True)[0]

    def lookup(self, prompt):
        vec = self._embed(prompt)
        if len(self.prompts) == 0:
            return None, 0.0, vec
        scores = self.vectors @ vec           # cosine sim, vectors are unit length
        best = int(np.argmax(scores))
        if scores[best] >= self.threshold:
            return self.responses[best], float(scores[best]), vec
        return None, float(scores[best]), vec

    def store(self, prompt, response, vec):
        self.vectors = np.vstack([self.vectors, vec])
        self.prompts.append(prompt)
        self.responses.append(response)

cache = SemanticCache(threshold=0.95)

def answer(prompt, call_model):
    hit, score, vec = cache.lookup(prompt)
    if hit is not None:
        return hit, f"HIT  (score {score:.3f})"
    response = call_model(prompt)             # the expensive path
    cache.store(prompt, response, vec)
    return response, f"MISS (best {score:.3f})"

# Stand in for the model so this runs without an API key.
fake_model = lambda p: f"<answer for {p!r}>"

for q in ["How do I reset my password?",
          "How can I reset my password?",
          "Is the API rate limited?"]:
    _, status = answer(q, fake_model)
    print(f"{status}  {q}")


# Output:
"MISS (best 0.000)  How do I reset my password?"
"HIT  (score 0.961)  How can I reset my password?"
"MISS (best 0.112) Is the API rate limited?"上面这个类的每个方法,都对应着生产环境中需要作出的一项决定:
上下游
本块首次出现的来源与延伸
标题为 Preloading Knowledge Into a Model Instead of Retrieving It (Part A)。
已核对页面标题与可见内容本块新增 1 项 · 另有 4 项已在前文介绍
判断
对本块内容的判断
这里跨越了两类查找:回溯已有的精确前缀写入,以及搜索相似问题。它们的命中含义不同,不能共用同一套正确性或成本判断。 这段完整代码示例按原样保留。它使用占位模型,展示查找、未命中调用和入库的控制流;尚未包含回答审核、条目有效期、租户过滤或并发控制。 归一化与向量范数有关,检索索引的选择则取决于实际规模和延迟。入库答案没有经过验证,是比单纯提高命中率更值得关注的问题。
回溯窗口包含当前断点,不是额外向前找 20 个
当前 Anthropic 文档说明,每个断点最多检查 20 个位置,当前断点算第一个。旧写入若落在当前断点之前第 20 个位置,就已经在窗口之外,而不必等到“超过 20”。连续的 tool_use 或 tool_result 还有合并计数规则,不能把工具调用数、消息数和查找位置数混为一谈。Anthropic · 提示缓存文档 ↗ · 定位原文 ↑
KV 缓存不只是节省跨请求预填充
KV 缓存还避免了解码时重复计算历史位置;前缀和托管提示缓存则主要减少后续请求的预填充。语义缓存会直接绕过生成模型,但示例的嵌入可以在本地计算,并不必然产生一次远程 API 往返或按次收费。Hugging Face · KV 缓存原理 ↗ · Sentence Transformers · 语义检索 ↗ · 定位原文 ↑
核验与延伸:作者的 RAG 系列 · 第 13 篇 ↗ · Anthropic · 提示缓存文档 ↗ · Sentence Transformers · 语义检索 ↗ · all-MiniLM-L6-v2 · 模型卡 ↗
解释
本块首次出现的知识点
精确检索、ANN 和阈值不是同一件事
精确检索逐一比较候选;近似最近邻(ANN)用索引减少搜索范围,在速度、内存与召回之间取舍。阈值负责决定是否接受找到的候选,索引召回则决定是否找到合适候选。
先测自己的规模与延迟,再选择算法。“几千条就必须改用 ANN”没有通用依据。还要分清相似度与距离:相似度阈值越高通常越严格,而距离阈值越低通常越严格。
本块新增 1 项 · 另有 3 项已在前文介绍
英文原文 15
322 词- normalize_embeddings=True makes every vector unit length, which lets self.vectors @ vec compute cosine similarity as a plain dot product. If you skip the normalization, the scores cannot be compared across prompts of different lengths.
- lookup returns the embedding alongside the result, so answer can store it later without re-embedding. That matters because the embedding is paid on every request, hit or miss, and computing it twice doubles the standing cost of having a cache at all.
- The brute-force argmax is fine for a demo and wrong at scale. Once you are past a few thousand entries, this becomes an approximate nearest neighbor index, which introduces its own recall setting on top of the threshold.
- store is called only on the miss path, after the model has answered. Nothing validates that answer before it becomes the response for every future prompt that scores above the threshold. This highlights the biggest risk with this technique. The cache has no notion of whether the stored response was correct, only of whether the new prompt looks similar to the old one.
The code below depicts the last point:
pairs = [
    ("How do I reset my password?", "How can I reset my password?"),
    ("Is the API rate limited?",     "Is the API not rate limited?"),
    ("Refund policy for annual plans", "Refund policy for monthly plans"),
]

for a, b in pairs:
    va, vb = encoder.encode([a, b], normalize_embeddings=True)
    print(f"{float(va @ vb):.3f}   {a!r}  vs  {b!r}")
This is the output we get:
0.961   'How do I reset my password?'  vs  'How can I reset my password?'
0.952   'Is the API rate limited?'  vs  'Is the API not rate limited?'
0.887 'Refund policy for annual plans' vs 'Refund policy for monthly plans'- The first pair is a genuine paraphrase and should share an answer.
- The second pair differs by one negation and needs opposite answers.
- The third differs by one operational value and needs different answers.
中文译文 15
485 字- normalize_embeddings=True 会把每个向量归一化为单位长度。这样,self.vectors @ vec 计算出的普通点积,就等于余弦相似度。如果跳过归一化,不同长度提示的分数就无法相互比较。
- lookup 会把嵌入向量和查找结果一起返回,让 answer 后面可以直接保存,不必重新生成向量。这一点很重要,因为无论命中与否,每个请求都要承担嵌入开销。如果重复计算两次,就会把维持缓存的这项固定成本翻倍。
- 暴力计算 argmax 用于演示没有问题,但不适合大规模应用。当条目达到几千条以上时,就应该换成近似最近邻索引;除了相似度阈值,它还会引入独立的召回率设置。
- 只有未命中时,模型给出回答之后,才会调用 store。回答在入库前没有经过任何校验,却可能被返回给之后所有相似度高于阈值的提示。这暴露了语义缓存最大的风险:它不知道存下来的回答是否正确,只知道新提示看起来是否像旧提示。
下面的代码演示了最后这一点:
pairs = [
    ("How do I reset my password?", "How can I reset my password?"),
    ("Is the API rate limited?",     "Is the API not rate limited?"),
    ("Refund policy for annual plans", "Refund policy for monthly plans"),
]

for a, b in pairs:
    va, vb = encoder.encode([a, b], normalize_embeddings=True)
print(f"{float(va @ vb):.3f} {a!r} vs {b!r}")运行后得到的输出如下:
0.961   'How do I reset my password?'  vs  'How can I reset my password?'
0.952   'Is the API rate limited?'  vs  'Is the API not rate limited?'
0.887 'Refund policy for annual plans' vs 'Refund policy for monthly plans'- 第一对是真正的同义改写,应该可以共用一个回答。
- 第二对只差一个否定词,却需要相反的回答。
- 第三对改变了一个业务条件,因此需要不同的回答。
上下游
本块首次出现的来源与延伸
本块相关内容已在前文介绍
判断
对本块内容的判断
归一化与向量范数有关,检索索引的选择则取决于实际规模和延迟。入库答案没有经过验证,是比单纯提高命中率更值得关注的问题。 这组样例说明词面接近不等于业务条件一致。对于否定问句,是否能共用完整回答还取决于回答形式;不能把相似度数值直接当作正确性的概率。
归一化处理的是向量范数,ANN 也没有“几千条”硬门槛
单位化后点积等于余弦相似度,是因为去除了向量范数的影响,而不专门是“修正提示长度”。检索方式也应看延迟、维度、批量与内存:Sentence Transformers 文档给出了面向约百万条以内语料的分块精确检索,不能把几千条直接当作必须改用 ANN 的门槛。Sentence Transformers · 语义检索 ↗ · 定位原文 ↑
相似度不是“回答可以通用”的证明
否定、业务参数与多轮指代都可能让相似问题需要不同回答,原文的风险提示成立。但分数是模型与样例的结果,不能当成通用阈值;“任意阈值都必然失效”也过强,拒绝所有复用当然可以避免错误命中,只是失去收益。更有用的评测是在保留命中量的同时测量错误复用率,并加入版本、租户、上下文与有效期限制。all-MiniLM-L6-v2 · 模型卡 ↗ · RedisVL · SemanticCache API ↗ · 定位原文 ↑
核验与延伸:Sentence Transformers · 语义检索 ↗ · all-MiniLM-L6-v2 · 模型卡 ↗ · RedisVL · SemanticCache API ↗
解释
本块首次出现的知识点
本块相关内容已在前文介绍
英文原文 16
260 词 · 1 张图Despite some mismatches, the scores for all three are close together. The paraphrase and the negation are separated by less than a hundredth of a point, which is far too thin a margin to hold across real traffic.
- If you increase it, the hit rate collapses while you keep paying for embeddings on every call.
- If you decrease it, the hit rate climbs alongside the rate of confidently wrong answers.
- Published defaults range from 0.75 to 0.97 depending on who you ask, which tells you it’s a property of your traffic rather than a value to copy.
This is not a fully reliable technique per se since some failures (as demonstrated above) can bypass any threshold value, because they come from what embeddings represent.
Recap of all four techniques
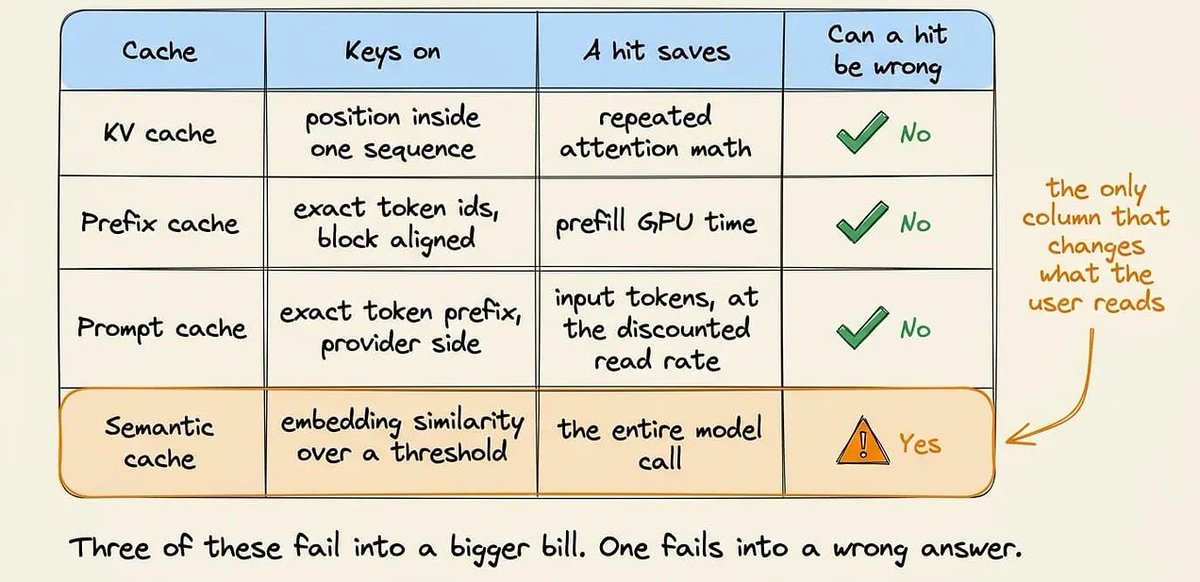
Three of the four techniques discussed above are correctness-neutral, so their misses show up in cost and latency and nowhere else.
The semantic cache works in a different way, so hit rate is not the right metric to report here.
There is a fifth, lesser-used layer as well. It's exact-match response cache that returns a stored answer when the request is byte identical. It saves input and output like a semantic cache and carries no false positive risk, because it does no similarity matching at all. You just measure your byte-identical repeat rate before reaching for embeddings. There are problems, of course, as you can probably identify by now. Post them in replies.
Takeaways for production
Every technique has some failure point that you should note before using them in production:
中文译文 16
470 字尽管有些问题并不等价,这三组相似度分数却很接近。同义改写与否定改写的分数相差不到 0.01,这样的间隔太小,难以在真实流量中稳定地区分两者。
- 如果提高阈值,命中率会大幅下降,但每次调用仍然需要承担嵌入开销。
- 如果降低阈值,命中率会上升,返回看似可信、实际错误答案的比例也会增加。
- 不同资料给出的默认值从 0.75 到 0.97 不等。这说明,合适的阈值取决于你自己的流量,不能直接照搬别人的数值。
这项技术本身并不完全可靠。正如上面的例子所示,一些错误可能绕过任何阈值,因为问题出在嵌入向量所表达的信息本身。
四种技术回顾
前面讨论的四种技术中,有三种不影响结果的正确性。因此,它们未命中时,影响只会体现在成本和延迟上。
语义缓存的工作方式不同,所以不能只用命中率来衡量它。
其实还有一个较少被使用的第五层:精确匹配的响应缓存。只有请求的字节完全一致时,它才返回已经保存的回答。与语义缓存一样,它能同时节省输入和输出,但因为完全不进行相似度匹配,所以不存在误匹配风险。在引入嵌入之前,可以先测量一下请求完全重复的比例。当然,它也有问题;读到这里,你应该已经能想到一些了,欢迎在回复中讨论。
生产环境中的实践要点
每种技术都有可能失效的地方,在用于生产环境之前,需要留意以下几点:
上下游
本块首次出现的来源与延伸
本块相关内容已在前文介绍
判断
对本块内容的判断
阈值需要在真实问题和答案上评估,既看正确命中,也看错误命中。作者对风险的提醒有价值,但提高阈值必然崩溃或所有阈值都失效,均不宜视作无条件结论。 完全重复的请求可以优先考虑精确响应缓存,但还要检查答案是否过期、权限和知识状态是否变化。稳定前缀优化与响应有效性是两项不同工作。
字节完全相同,也可能命中已经过期的回答
精确响应缓存确实避免了模糊相似度造成的误匹配,但相同请求的正确答案仍可能随时间、知识库、权限或模型版本改变。缓存键和失效策略必须覆盖这些条件;没有相似度假阳性,不等于没有陈旧结果或上下文不完整的风险。RedisVL · SemanticCache API ↗ · 定位原文 ↑
核验与延伸:RedisVL · SemanticCache API ↗ · all-MiniLM-L6-v2 · 模型卡 ↗ · Sentence Transformers · 语义检索 ↗ · vLLM · Automatic Prefix Caching ↗
解释
本块首次出现的知识点
前缀失效、响应过期和输入压缩
修改历史中的一个位置,会影响该位置及之后的精确前缀。把摘要替换到前面、改动已发送的工具输出、切换模型,都会改变复用条件。稳定序列化能减少意外差异,但不能掩盖真实内容变更。
应当比较最终 token ID,定位首次不同的位置。输入压缩也要计算长期收益:一次冷预填充可能换来后续更短的输入,缓存命中率并不是唯一目标。
本块新增 1 项 · 另有 2 项已在前文介绍
英文原文 17
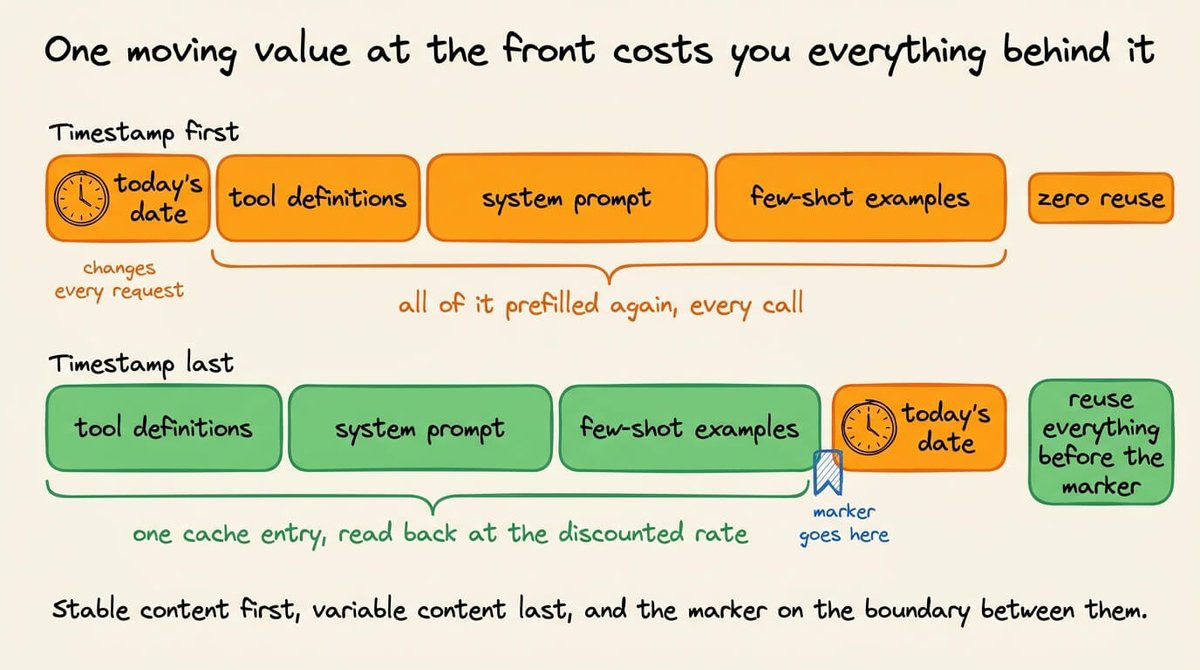
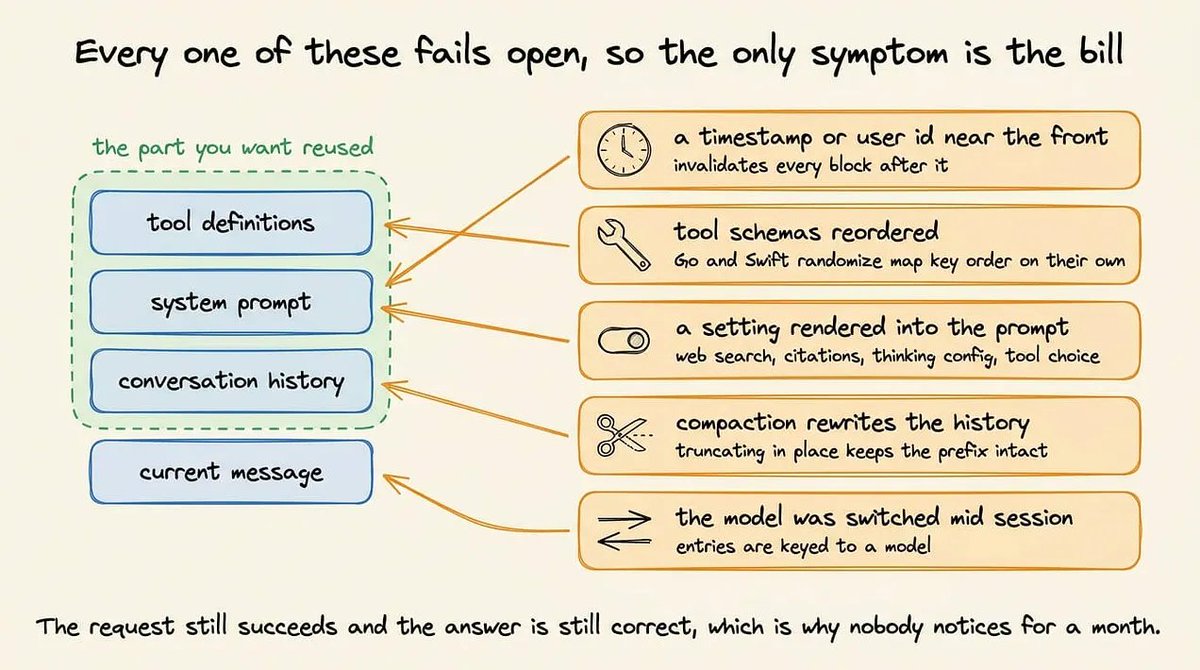
299 词 · 3 张图- If you have any variable in the front of the prompt, like A timestamp, request id or user name in the system prompt, this invalidates every block after it. Always put stable content first, variable content last, and a marker on the boundary.
- Tool schemas are usually placed ahead of the system prompt, so a reorder can invalidate the whole cache.
- Check the settings that get rendered into the prompt. On Anthropic, toggling web search, citations, thinking config, or tool_choice rewrites the prompt text and invalidates downstream blocks. A/B testing two reasoning efforts splits your cache in two.
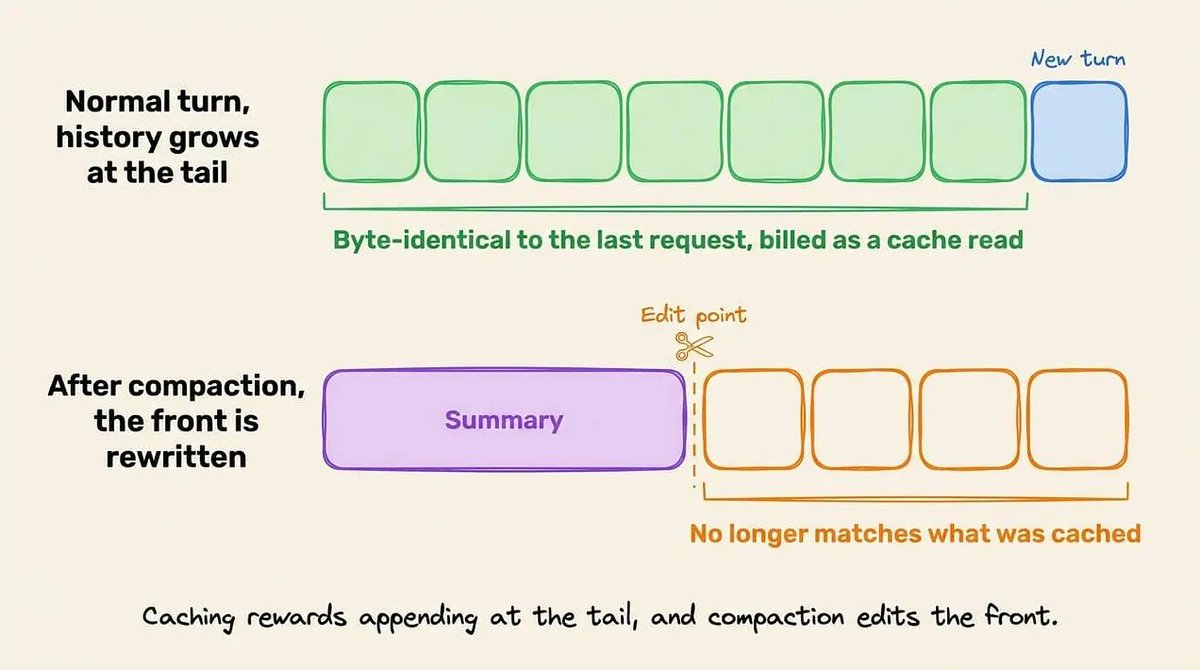
- Summarizing history rewrites the prefix, so the next call pays full price on cold tokens. Truncating tool outputs in place keeps the prefix byte-identical and the cache alive.
- Cache entries are keyed to a model, so routing to a cheaper one still prefills the whole accumulated history at cold rates.
To determine exactly where two prompts stop matching, compare their token IDs directly rather than the text you logged. Here's a demonstration:
messages_turn_1 = [{"role": "user", "content": "What is the capital of France?"}]
messages_turn_2 = [{"role": "system", "content": "Today is Tuesday."},
                   {"role": "user", "content": "What is the capital of France?"}]

# tokenize=True is the default and returns a plain list of token ids
a = tokenizer.apply_chat_template(messages_turn_1)
b = tokenizer.apply_chat_template(messages_turn_2)

shared = 0
for x, y in zip(a, b):
    if x != y:
        break
    shared += 1

print(f"shared prefix: {shared} tokens of {len(a)} and {len(b)}")
print(f"first divergence at index {shared}: {a[shared:shared+8]} vs {b[shared:shared+8]}")

# Output:
"""
shared prefix: 3 tokens of 35 and 26
diverges at index 3
  turn 1: [2683, 418, 253, 11173, 9042, 14260] You are a helpful AI assistant
  turn 2: [11814, 314, 27758, 30, 2, 198] Today is Tuesday.<|im_end|>
"""
中文译文 17
462 字- 如果把时间戳、请求 ID、用户名等变量放在提示开头,例如放进系统提示中,它后面的所有块都会失效。应始终把稳定内容放在前面,变化内容放在后面,并在两者边界处设置标记。
- 工具定义通常放在系统提示之前,因此只要调整工具定义的顺序,就可能让整个缓存失效。
- 检查那些会进入最终提示的设置。在 Anthropic 上,切换网页搜索、引用、思考配置或 tool_choice,都会改写提示文本,使后面的缓存块失效。对两种推理强度做 A/B 测试,也会把缓存分成两份。
- 对历史记录做摘要会改写前缀,因此下一次调用要为未缓存的 token 支付全价。在原位置截断工具输出,则能让前缀在字节层面保持一致,使缓存继续有效。
- 缓存条目与模型绑定。因此,即使把请求路由到一个更便宜的模型,它仍然需要按未缓存的价格,对全部累积历史进行预填充。
要精确定位两段提示从哪里开始不再匹配,应直接比较 token ID,而不是只看日志里的文本。下面是一段演示:
messages_turn_1 = [{"role": "user", "content": "What is the capital of France?"}]
messages_turn_2 = [{"role": "system", "content": "Today is Tuesday."},
                   {"role": "user", "content": "What is the capital of France?"}]

# tokenize=True is the default and returns a plain list of token ids
a = tokenizer.apply_chat_template(messages_turn_1)
b = tokenizer.apply_chat_template(messages_turn_2)

shared = 0
for x, y in zip(a, b):
    if x != y:
        break
    shared += 1

print(f"shared prefix: {shared} tokens of {len(a)} and {len(b)}")
print(f"first divergence at index {shared}: {a[shared:shared+8]} vs {b[shared:shared+8]}")

# Output:
"""
shared prefix: 3 tokens of 35 and 26
diverges at index 3
  turn 1: [2683, 418, 253, 11173, 9042, 14260] You are a helpful AI assistant
  turn 2: [11814, 314, 27758, 30, 2, 198] Today is Tuesday.<|im_end|>
"""上下游
本块首次出现的来源与延伸
Go 的标准 JSON 编码会对 map 键排序,不能把 map 遍历顺序直接等同于请求 JSON 顺序。
已核对 map 键的序列化规则本块新增 1 项 · 另有 5 项已在前文介绍
判断
对本块内容的判断
完全重复的请求可以优先考虑精确响应缓存,但还要检查答案是否过期、权限和知识状态是否变化。稳定前缀优化与响应有效性是两项不同工作。 应检查实际发出的内容及最终 token 序列,而不是从语言或数据结构名称推断顺序。修改旧工具输出本身就会改变前缀,这一点不能被“原地”二字掩盖。 逐个比较 token ID 能帮助定位真实差异。示例里系统角色和模板默认值发生变化,因此只比较用户消息文本会漏掉关键上下文。
原地截断历史工具输出,并不会保持旧前缀不变
如果某段工具输出已经进入上一次请求,再把它截短,就改变了该位置及之后的 token,旧缓存只能复用到修改点之前。只有从第一次发送起就一致地做截断,并保持此前历史不变,才可能继续获得稳定前缀。图 23 中把“原地截断”直接等同于“前缀不变”的说法不成立。Transformers v5.0 · 聊天模板 ↗ · 定位原文 ↑
map 的遍历顺序与 JSON 的输出顺序是两回事
图 23 将 Go、Swift 的 map 顺序笼统画成缓存失效原因,但 Go 标准 encoding/json.Marshal 明确会对 map 键排序。真正应检查的是最终工具数组、序列化结果和模板产生的 token,而不能单凭使用哪种语言下结论。Go · encoding/json.Marshal ↗ · 定位原文 ↑
核验与延伸:RedisVL · SemanticCache API ↗ · vLLM · Automatic Prefix Caching ↗ · Go · encoding/json.Marshal ↗ · Transformers v5.0 · 聊天模板 ↗
解释
本块首次出现的知识点
本块相关内容已在前文介绍
英文原文 18
236 词Two prompts that look identical in your logs can differ by a beginning-of-sequence (BOS) token, a trailing newline, or a re-serialized tool schema.
Comparing token IDs instead of rendered text finds the exact index where reuse stops, and decoding the few IDs on either side usually finds the exact text.
The run above shows a common one.
Turn one specified no system message, so the chat template filled in the model's default, and the two prompts looked different at index 3, so no reuse was possible.
The first three layers cover one idea, applied at three scopes.
- The KV cache holds attention state for the duration of a single request.
- Prefix caching keeps that state after the request ends so a later request can look it up.
- Prompt caching is a provider running prefix caching on their own hardware and charging a separate rate for the part you reuse.
The semantic cache works differently. It stores response text keyed by embedding similarity, so if there's a hit, it skips the model entirely and saves output tokens along with input tokens. A hit can also be wrong, and it returns with a normal success status when it is.
Over to you: which of these four layers has cost you the most debugging time?
That's a wrap!
If you enjoyed this tutorial:
Find me → @_avichawla
Every day, I share tutorials and insights on DS, ML, LLMs, and RAGs.
中文译文 18
426 字两段在日志里看起来相同的提示,可能在序列起始(BOS)token、末尾换行,或重新序列化后的工具定义上存在差异。
比较 token ID,而不是渲染后的文本,能够找到复用终止的准确位置。再把这个位置前后的几个 ID 解码,通常就能定位是哪段文本发生了变化。
上面的运行结果展示了一种常见情况。
第一轮没有指定系统消息,因此聊天模板填入了模型的默认系统消息。两段提示在索引 3 处开始不同,所以无法复用缓存。
前三个层面,其实是把同一个思路应用在三个不同的范围里。
- KV 缓存在单次请求期间保存注意力状态。
- 前缀缓存在请求结束后继续保留这些状态,让后续请求可以查找和复用。
- 提示缓存则是由服务商在自己的硬件上运行前缀缓存,并为被复用的部分单独定价。
语义缓存的机制不同。它以嵌入相似度为依据保存和查找响应文本,命中时直接跳过模型,从而同时节省输入和输出 token。但命中也可能是错误的,即使如此,系统返回的依然是正常的成功状态。
轮到你了:这四个缓存层面中,哪一个让你花了最多时间调试?
这次就讲到这里!
如果你喜欢这篇教程:
欢迎关注我 → @_avichawla [1]
我每天都会分享数据科学、机器学习、大语言模型和 RAG 的教程与见解。
上下游
本块首次出现的来源与延伸
对应文末继续关注作者的入口。
地址来自所供网页的作者署名本块新增 1 项 · 另有 5 项已在前文介绍
判断
对本块内容的判断
逐个比较 token ID 能帮助定位真实差异。示例里系统角色和模板默认值发生变化,因此只比较用户消息文本会漏掉关键上下文。 结尾正确强调了状态复用与答案复用的差别。实际排查时,分别记录输入结构、命中 token、延迟、成本与错误答案,才能知道哪个层面的缓存真正产生了收益。
核验与延伸:Transformers v5.0 · 聊天模板 ↗ · SmolLM2-360M-Instruct · 模型卡 ↗ · Hugging Face · KV 缓存原理 ↗ · vLLM · Automatic Prefix Caching ↗
解释
本块首次出现的知识点
本块相关内容已在前文介绍
来源与阅读说明
正文来自你提供的浏览器保存资料:同名 HTML 与 _files 资源文件夹。已提取文章正文和作者资料,保留文字、链接、代码、图片的顺序;未运行保存网页附带的脚本。按中文译文约 400 字分块,常规范围为 300–500 字;优先保持章节、段落及代码完整,中英文同步分块。
译文覆盖正文、列表、引用和文末介绍。12 段代码及其示例字符串保持原样,并附中文说明;代码与原文中的问题不在原文或译文里悄悄改写,而是在“判断”中说明。辅助资料和知识解释只在首次涉及的块里展开,右栏可查看全部,并随正文滚动更新关联标注。
23 张保存图片全部内嵌,其中两张是视频预览,文件夹未包含对应视频文件。第一处原视频地址为不可移植的浏览器临时地址,可在原帖播放;第二处保留了原始在线视频地址。图片和文字离线可读,外部资料与视频需联网。
技术核验日期:2026 年 9 月 11 日。已检查官方文档、模型卡、研究论文及原文代码逻辑;未执行模型推理,也未调用付费 API。缓存价格、门槛和接口规则应以具体版本与官方最新文档为准。